Showing Posts From
Datascience
-
 Amara Singh
- 13 Sep, 2026 20:53
The Silicon Reckoning: Engineering Sustainable Intelligence at the Thermodynamic Limit
The Thermodynamic Cost of Cognitive Scaling The trajectory of artificial intelligence over the last decade has been nothing short of a Cambrian explosion, yet this rapid evolution masks a precarious reality. While we celebrate the emergence of Large Language Models (LLMs) capable of complex reasoning, the energy requirements to train and serve these systems have surged to levels that challenge the viability of our grid infrastructure. As an engineer who has watched the transition from localized cluster training to massive, cross-continental distributed training runs, I find the "brute force" scaling paradigm—simply adding more H100s or B200s to a training job—to be an increasingly unsustainable design pattern. The future of AI is not defined by how many parameters we can jam into a transformer architecture, but by the efficiency with which we extract value from every watt consumed. We are reaching a point where the thermodynamic limit of silicon and the cooling capacity of hyperscale data centers are becoming the primary bottlenecks to innovation. If we continue to prioritize model scale at the expense of energy parity, we risk isolating AI development to only the wealthiest entities, while simultaneously accelerating environmental degradation. To build a greener future, we must shift our focus from "bigger is better" to a framework defined by parameter-efficient fine-tuning (PEFT), hardware-aware neural architecture search (NAS), and specialized, low-power inference silicon. This article explores the technical imperative of sustainable AI and how we can re-engineer our stacks for maximum impact with minimum entropy. The Architecture of Efficiency: From Dense to Sparse The fundamental problem with modern transformers lies in their density. When a model performs a forward pass, the entirety of its parameters is involved, leading to massive memory bandwidth bottlenecks and unnecessary compute. To combat this, the shift toward Mixture-of-Experts (MoE) architectures and sparse activation models is essential. By conditionally computing only a subset of parameters for any given input, we can significantly lower the GFLOPs required per token generation. Furthermore, the industry is seeing a resurgence in pruning and quantization-aware training (QAT). Research from the intersection of hardware co-design suggests that shifting from FP32 to INT8, or even FP4/NF4, does not merely save storage; it fundamentally alters the thermal envelope of the GPU clusters. By reducing the precision of weights, we decrease the pressure on the memory subsystem—which, ironically, is often more power-hungry than the arithmetic logic units themselves. Implementing these optimizations at the infrastructure level requires a shift in how we build our CI/CD pipelines for model training, moving away from "black box" deployment toward granular, hardware-aware monitoring.To put this into practice, consider the use of quantization frameworks like bitsandbytes or AutoGPTQ in your inference stacks. Here is a technical example of how we leverage 4-bit quantization to drastically reduce the VRAM overhead, which directly correlates to fewer servers needed for global deployment: import torch from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig# Configuring a 4-bit quantization config to minimize power draw during inference bnb_config = BitsAndBytesConfig( load_in_4bit=True, bnb_4bit_quant_type="nf4", bnb_4bit_compute_dtype=torch.bfloat16, bnb_4bit_use_double_quant=True )# Loading the model with reduced precision model_id = "meta-llama/Llama-3-8B" model = AutoModelForCausalLM.from_pretrained( model_id, quantization_config=bnb_config, device_map="auto" )# By running the model in 4-bit, we decrease the physical hardware footprint # by approximately 4x compared to FP16, directly lowering the energy cost per query.Hardware Co-Design and the Post-GPU Paradigm The industry’s reliance on general-purpose GPUs (GPGPUs) for all AI workloads is a luxury we can no longer afford. While GPUs are versatile, they are not necessarily the most efficient tools for specific tensor-based operations. We are entering an era of Domain-Specific Architectures (DSAs). Custom silicon, such as Google’s TPUs or AWS’s Inferentia chips, represents a shift toward matching the hardware layout to the computational graph of the model. When we analyze the power-per-inference metrics, the discrepancy between general-purpose hardware and purpose-built hardware is staggering. The key to sustainable AI lies in "hardware-software co-design," where the neural network's graph is optimized for the specific cache structure and interconnect bandwidth of the underlying hardware. For developers, this means the end of "write once, run anywhere" when it comes to performance-critical deployments. We must move toward frameworks like Triton or custom CUDA kernels that are explicitly tuned to the target microarchitecture.Orchestrating Sustainability in Distributed Infrastructure Containerization and orchestration have revolutionized how we deploy software, but they often obscure the energy cost of compute. In a Kubernetes-based environment, "idle" pods in a cluster are silent energy thieves. If we are serious about sustainability, our resource scheduling must be carbon-aware. This involves integrating tools that track real-time grid carbon intensity and scheduling non-urgent batch training jobs during periods of peak renewable energy production—such as when wind or solar output is highest in a specific region. Implementing carbon-aware scheduling requires more than just good intentions; it requires a sophisticated integration of telemetry data and cluster auto-scaling logic. We need to treat "energy-per-inference" as a first-class metric, similar to latency or throughput. If your MLOps dashboard does not track the CO2 equivalent of your model training runs, you are essentially flying blind. The goal is to move towards a "Green CI/CD" pipeline that blocks commits which exceed a defined energy budget. # A carbon-aware Kubernetes deployment manifest example apiVersion: apps/v1 kind: Deployment metadata: name: carbon-aware-inference labels: app: model-server spec: replicas: 3 selector: matchLabels: app: model-server template: metadata: labels: app: model-server spec: containers: - name: inference-engine image: green-ai-registry/model-server:v1.2.0 resources: limits: cpu: "2" memory: "4Gi" # Custom environment variable to trigger energy-saving mode env: - name: QUANTIZATION_LEVEL value: "int8" - name: SCHEDULING_STRATEGY value: "carbon-optimized" affinity: nodeAffinity: preferredDuringSchedulingIgnoredDuringExecution: - weight: 100 preference: matchExpressions: - key: energy-source operator: In values: - renewablesAlgorithmic Efficiency and the Myth of More There is an unhealthy obsession with the "Scaling Laws"—the hypothesis that larger models always yield better performance. While data-scaling laws hold true for performance, they are catastrophic for sustainability. Research into knowledge distillation, where a smaller "student" model is trained to mimic the behavior of a massive "teacher" model, has proven that we can achieve 90% of the performance of a 175B parameter model with a 7B parameter model. We must also consider the architectural overhead. The Transformer architecture, while brilliant, has quadratic scaling with respect to sequence length in terms of memory and compute. This makes long-context inference exceptionally expensive. By adopting architectures that exhibit linear or sub-linear scaling—such as Mamba (State Space Models) or hybrid architectures—we can drastically reduce the compute floor for high-context tasks. As engineers, our duty is to question whether a monolithic transformer is the correct tool for the job, or if a modular, task-specific architecture would provide the necessary result at a fraction of the cost.Cultivating a Culture of Resource-Aware Engineering The transition to sustainable AI is ultimately a cultural challenge. Engineering teams are often incentivized by performance metrics alone, neglecting the externalities of their choices. We need a fundamental shift in how we view technical debt. If a model is trained in a way that consumes 500 MWh of energy for a marginal 0.1% gain in accuracy, that is a form of environmental debt that the company will eventually have to pay, whether through carbon taxes, regulatory fines, or reputation loss. To foster this, we should adopt "Energy Budgeting" for ML projects. Before a large-scale training run is approved, it must be accompanied by an impact assessment that calculates the expected carbon output based on the hardware tier and the geographic location of the data center. This is analogous to how we conduct financial audits before major capital expenditure. By making the energy cost visible, we force a conversation about efficiency. We should also prioritize "Data Quality over Data Quantity." Often, a smaller, cleaner dataset produces a more robust and efficient model than a petabyte-scale corpus of noisy, redundant internet-scraped data. The "Less is More" philosophy in data curation is perhaps the most overlooked lever for sustainable AI. Finally, we must contribute back to the open-source community by sharing our efficiency benchmarks. We see a trend on GitHub where repositories are beginning to include CARBON_FOOTPRINT.md files or energy efficiency reports in their project documentation. This transparency is the baseline requirement for a mature engineering ecosystem. When we share our optimization techniques—whether it’s a novel sparse activation pattern or a custom CUDA memory manager—we raise the floor for the entire industry. Sustainable AI is not a competitive advantage to be hoarded; it is a collaborative necessity for the long-term survival of our technological infrastructure. We must stop measuring our success by the scale of our models and start measuring it by the elegance of our solutions and the depth of our impact. The silicon age does not have to be the age of ecological depletion; with precision, intent, and architectural rigor, we can build a future where intelligence flourishes without compromising the planet we call home. Toward a Sustainable Epoch of Machine Learning We stand at a crossroads. The current path of unbridled, energy-agnostic scaling is a temporary reprieve that is rapidly approaching a hard ceiling. By embracing the methodologies discussed—hardware-aware quantization, sparse architecture design, carbon-aware orchestration, and a shift toward knowledge distillation—we can decouple intelligence growth from energy consumption. This shift is not merely about "being green"; it is about achieving technical excellence in an era where resources are no longer infinite. The engineers of the future will be defined by their ability to achieve the maximum possible performance within a constrained energy budget. We are moving from the era of the "AI Gold Rush" into the "Age of AI Refinement." It is time to treat our computational resources with the same respect as we treat our memory and latency budgets. By integrating sustainability into the very core of our development lifecycle, we ensure that the AI systems of tomorrow are not only powerful but also enduring. We have the tools, the research, and the architectural patterns to make this transition. What is required now is the collective will to prioritize efficiency as a core engineering value. Let us build smarter, not just bigger, and ensure that our progress does not cost us the future.#AI #GreenTech #SustainableComputing #MachineLearning #DevOps #EngineeringExcellence #CarbonAware Related InsightsUnlocking the Future of Cybersecurity: The Decentralized Power of Cybersecurity Mesh Decentralized Carbon Credit Tracking: Harnessing Distributed Ledger Technology for a Sustainable Future Algorithmic Sovereignty: Deconstructing the DAO Paradox in On-Chain Governance{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Silicon Reckoning: Engineering Sustainable Intelligence at the Thermodynamic Limit?", "acceptedAnswer": { "@type": "Answer", "text": "An architectural deep-dive into reducing the carbon footprint of large-scale machine learning through hardware co-design and algorithmic efficiency." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Silicon Reckoning: Engineering Sustainable Intelligence at the Thermodynamic Limit?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Amara Singh." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Kerem Talu
- 07 Sep, 2026 21:33
The Kinetic Classroom: Merging Diffusion Transformers and Cosmological Reconstruction in Educational AI
From Static Textbooks to Fluid Intelligence The traditional lecture hall is an artifact of the industrial age, a static environment optimized for mass transmission rather than cognitive assimilation. As we stand at the precipice of a pedagogical paradigm shift, the synthesis of Generative AI is moving beyond simple Large Language Model (LLM) chatbots. We are now entering the era of "Kinetic Classrooms," where the abstract complexity of scientific phenomena—be it the animation of biological structures or the cosmic evolution of the primordial density field—is rendered in real-time, interactive, and personalized formats. As a researcher, I have long observed the limitations of current educational tools. They are binary, text-heavy, and often fail to bridge the gap between abstract theory and spatial understanding. However, by leveraging architecture borrowed from state-of-the-art foundation models like UniMate, we can democratize access to high-fidelity 3D modeling and motion synthesis in the classroom. When we combine this with the predictive power of U-Net architectures, such as those used for reconstructing cosmological density fields from line-intensity maps, we create an environment where a student does not just read about the universe; they interact with the data that defines it. This article explores the convergence of these technical breakthroughs, focusing on how we can implement infrastructure that supports truly personalized, multimodal learning experiences that are both scalable and mathematically rigorous. Topology-Aware Architectures for Immersive Pedagogy In the realm of educational content generation, the ability to animate diverse biological or mechanical systems is fundamental. Educational platforms often struggle with the "rigging bottleneck," where 3D assets require manual intervention or per-skeleton fine-tuning. This is where the methodology behind UniMate—a unified foundation model for diverse skeletons—becomes transformative. By integrating a topology-aware diffusion transformer, we can create educational software that generates motion for any articulated object from a simple text prompt. For a student learning anatomy, engineering, or even classical mechanics, the ability to input a concept like "show me the movement of a skeletal lever under force" and receive a zero-shot, animation-ready 3D output is unparalleled. The technical breakthrough lies in the graph-aware attention bias. By using pairwise joint relations and geodesic distances, the model respects the kinematic hierarchy of the object, regardless of whether it is bipedal, insectoid, or mechanical. For developers, implementing this in an educational tech stack requires a modular pipeline where we abstract the skeletal topology into a format the model can process via spectral rotary position embeddings (RoPE).The efficiency of this approach is not merely in its quality but in its generalization. By training on datasets like UniML3D, we effectively map language descriptions to kinematic sequences, allowing for real-time in-betweening and text-guided editing. This provides a "sandbox" effect for students, where the classroom moves from passive consumption to generative inquiry. Reconstructing Knowledge via Probabilistic Inference While 3D motion defines the physical classroom, the theoretical classroom is defined by data reconstruction. In cosmology, we use 3D U-Nets to reconstruct the primordial density field from noisy, non-linear observations. If we apply this same "simulation-based inference" approach to education, we find a powerful analogy for learning analytics. Consider the task of identifying a student’s "latent knowledge state" from sparse, noisy assessment data. Just as the reconstruction of the $z\sim300$ density field from $z\sim8$ tracers improves the accuracy of cosmological parameter constraints by nearly 2x, applying a similar U-Net architecture to student assessment data can drastically improve our understanding of student proficiency. By filtering out the "thermal noise" of standardized testing—such as guessing, fatigue, or environmental variables—we can recover the underlying mastery state of the learner. The mathematical rigor of this approach is vital. We utilize the cross-correlation coefficient $|C(k)|$ to validate how well our models capture the "true" state of the user. When we implement these learners' models in a production environment, we are not just grading; we are performing an act of statistical reconstruction that informs the next best instructional step for the student. Infrastructure and Deployment Strategies To move these concepts from academic repositories into actual K-12 and university settings, we must address the deployment layer. The overhead for running diffusion transformers and 3D U-Nets is non-trivial. Below is a base configuration for a containerized inference service using Docker Compose, optimized for a GPU-accelerated environment suitable for hosting these pedagogical foundation models. version: '3.8' services: inference-engine: image: pedagogical-ai-engine:v1.0 deploy: resources: reservations: devices: - driver: nvidia count: 1 capabilities: [gpu] environment: - MODEL_TYPE=UNIMATE_TRANSFORMER - BATCH_SIZE=4 - PRECISION=FP16 ports: - "8080:8080" volumes: - ./models:/app/weights - ./data:/app/data learning-analytics-db: image: postgres:15-alpine environment: POSTGRES_DB: student_inference_data volumes: - pgdata:/var/lib/postgresql/datavolumes: pgdata:The key to scaling this architecture is the decoupling of the "Generative Motion Engine" from the "Knowledge Reconstruction Service." By using a standard FastAPI or gRPC interface, these services communicate with the front-end dashboard, where students engage with 3D models or adaptive quiz flows. The memory management for the graph-aware attention mechanism is intensive, requiring careful load balancing to ensure that the "spectral rotary position embedding" calculations don't bottleneck under concurrent user requests. Data Pipelines and Zero-Shot Generalization The success of these systems hinges on the quality of the data ingestion pipelines. In the UniMate project, the curation of 13,006 motion sequences into a unified format (UniML3D) was the critical factor in enabling cross-topology transfer. Similarly, for the educational classroom, we must adopt an "Open Educational Content" (OEC) strategy that digitizes assets into a common schema. We propose a transformation script that standardizes heterogeneous 3D assets and educational metadata into a schema-ready format. This allows our models to operate without the need for constant re-training or per-student fine-tuning, which is essential for preserving data privacy and minimizing compute costs. import torch import numpy as npclass KinematicStandardizer: """ Standardizes arbitrary skeletal kinematic trees for transformer ingestion. """ def __init__(self, target_nodes): self.target_nodes = target_nodes def compute_graph_laplacian(self, adj_matrix): degree_matrix = np.diag(np.sum(adj_matrix, axis=1)) return degree_matrix - adj_matrix def process_skeleton(self, skeleton_data): # Implementation of spectral embedding for arbitrary trees adj = self._extract_adjacency(skeleton_data) laplacian = self.compute_graph_laplacian(adj) eigenvalues, eigenvectors = np.linalg.eigh(laplacian) return torch.tensor(eigenvectors[:, :16], dtype=torch.float32) def _extract_adjacency(self, skeleton): # Maps joint relations to graph topology passThis Python script demonstrates the fundamental logic of processing diverse skeletal data—a prerequisite for the unified pedagogical interface. By standardizing input data, we enable "Zero-Shot Learning" in the classroom. A student studying biology doesn't need to manually rig a complex protein structure; the system automatically detects the topology, applies the graph-aware attention bias, and renders the motion. Challenges in Ethical AI Deployment As we integrate these high-level models into classrooms, we must confront the "Black Box" dilemma. When a student’s path is determined by a simulation-based inference model (like our cosmic reconstruction logic), we must maintain transparency. In the context of cosmological research, we use Kullback-Leibler (KL) divergence diagnostics to measure the difference between our reconstruction and the ground truth. We should adopt these same metrics in EdTech to quantify the "divergence" of our AI recommendations from pedagogical goals.Furthermore, the integration of generative 3D assets requires strict moderation. Unlike static text, motion generation can be used to animate prohibited or violent simulations. We must implement a "Topological Guardrail" layer—a middleware that checks the output of the diffusion transformer against a safety ontology before rendering it to the student. This is not just a regulatory hurdle; it is a fundamental requirement for the classroom of tomorrow to be both innovative and safe. In summary, the transition from current AI-assisted learning to the highly interactive, mathematically precise classroom of the future is not a dream—it is an engineering problem. By applying structural breakthroughs in diffusion modeling and probabilistic reconstruction to the educational stack, we provide students with an immersive, data-driven experience. The convergence of diverse kinematic modeling (UniMate) and deep-field inference (U-Net reconstruction) provides a roadmap for building the next generation of intelligent tools. We are moving toward a future where "personalization" is not just a marketing term, but a technical reality enabled by low-latency inference and high-fidelity 3D assets. Developers, researchers, and educators must continue to bridge the gap between these high-level arXiv breakthroughs and the practical requirements of the classroom. The infrastructure is ready; the frameworks are being refined. Now, it is up to the tech community to deploy these solutions in a way that respects the pedagogical intent while pushing the boundaries of what is possible in a computational environment. As we iterate on these models, the goal remains clear: to provide every student with a window into the complex, dynamic systems that govern our world, rendered with the precision of a laboratory and the accessibility of a desktop app. #AI #EdTech #MachineLearning #GenerativeAI #DataScience #Innovation #DeepLearning Related InsightsHolographic Displays: The Silent Revolution Reshaping AR/VR, 3D Visualization, and Human-Computer Interaction Revolutionizing Autonomous Task Execution: The Evolution of Large Action Models (LAMs) Deciphering the Ethics of Brain-to-Text Interface Technology{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Kinetic Classroom: Merging Diffusion Transformers and Cosmological Reconstruction in Educational AI?", "acceptedAnswer": { "@type": "Answer", "text": "Exploring the next frontier of pedagogical AI by synthesizing 3D motion foundation models and advanced probabilistic inference to reshape the classroom." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Kinetic Classroom: Merging Diffusion Transformers and Cosmological Reconstruction in Educational AI?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Kerem Talu." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Lucas Moreau
- 04 Sep, 2026 20:48
Unmasking the Oracle: Architecting Transparency in the Era of Black Box Neural Networks
Peering Behind the Algorithmic Veil: The Crisis of Trust in Modern AI In the high-stakes theater of modern machine learning, we have reached a paradoxical juncture. We are building systems of unprecedented capability—models that can process temporal video sequences, map complex 3D meshes, and synthesize vast datasets with near-human precision—yet we remain tethered to the "Black Box" problem. The more intricate the architecture, the more opaque the decision-making process becomes. As practitioners, we often celebrate the benchmark gains of LLaVA-OneVision or the structural elegance of correspondence transformers, but we are frequently forced to concede: we do not fully understand why these models succeed. Transparency is no longer a luxury; it is a fundamental requirement for the maturation of artificial intelligence in sectors ranging from autonomous robotics to critical diagnostic healthcare. Explainable AI (XAI) is the bridge between the mathematical brute force of deep learning and the human requirement for accountability. When we deploy models that track visual states or align partial 3D surfaces, the inability to interrogate the logic of these systems constitutes a significant technical debt. In this analysis, we peel back the layers of contemporary models to understand how internal representations—if carefully engineered—can move us toward a future of fully verifiable and trustworthy artificial intelligence.Temporal Self-Distillation as a Path to Interpretability The recent innovation of S$^3$T (Self-Supervised Self-Distillation over Time) represents a watershed moment for how we conceptualize model training and representation. By utilizing temporal sampling density as privileged information, S$^3$T allows a model to generate its own target, effectively internalizing a running state without external supervision. From an XAI perspective, this is revolutionary. In traditional models, "black box" behavior often stems from the reliance on hidden, non-semantic features learned via static supervision. In contrast, the self-distillation approach forces the model to learn the flow of information across time. By treating a denser view of a video clip as a "teacher" for a sparse-view "student," the framework creates an inherent trace of the decision-making process. This temporal consistency serves as a primitive form of interpretability. If the model’s state tracking improves by $+1.74$ on VSTAT benchmarks as a single model, and climbs further with souping techniques, we are observing a system that is refining its own logic. As engineers, we must move toward architectures where the "internal state" is not just a hidden vector, but a traceable trajectory of temporal attention. import torch import torch.nn as nnclass TemporalDistillationModule(nn.Module): """ Simulated S3T framework logic for video state tracking. This architecture mimics the self-distillation process where the student learns from the teacher's temporal density. """ def __init__(self, hidden_dim=512): super().__init__() self.encoder = nn.TransformerEncoderLayer(d_model=hidden_dim, nhead=8) self.state_tracker = nn.Linear(hidden_dim, 1) def forward(self, sparse_view, dense_view_features): # Student learns to match the teacher's next-token distribution # derived from the dense_view_features. student_features = self.encoder(sparse_view) loss = nn.functional.kl_div( input=self.state_tracker(student_features), target=dense_view_features, reduction='batchmean' ) return loss# Conceptualizing the self-evolving training loop def training_step(model, video_batch): # Generating targets without external labels teacher_state = generate_dense_view(video_batch) loss = model(video_batch, teacher_state) loss.backward() return loss.item()Curvature-Guided Tokenization in Geometric Correspondence When we shift our focus from temporal dynamics to spatial geometry, the challenge of explainability persists. In 3D shape correspondence—specifically when dealing with non-isometric deformations—traditional models often fail because their internal tokens lack geometric grounding. The introduction of TokenMatch provides a fascinating case study in "interpretable architecture." By utilizing curvature-guided tokenization, the model maps mesh patches to semantic tokens based on actual surface topology rather than arbitrary spatial grids. This is a profound shift toward transparency. Because the tokens are anchored to shape curvature, we can visually interrogate the model’s focus. If the correspondence transformer identifies a match between two partial shapes, we can verify this by checking if the attention mechanism is centered on high-curvature features (e.g., ears, fingers, or sharp edges) versus noise. This methodology moves us away from opaque embeddings and toward "concept-aware" architectures. The performance gains observed across datasets like FAUST and SHAPE-NET underline a simple, powerful truth: when we bake domain-specific priors into the tokenization layer, the model performs better and provides a clearer trace of its internal reasoning.Quantifiable Trust: Metric-Driven Validation How do we measure "trust"? In the context of the architectures described, we must rely on a blend of performance metrics and interpretability indices. In the TokenMatch implementation, mean geodesic error and intersection-over-union (IoU) serve as the primary validators. However, from a research standpoint, the consistency of these metrics across partial and full shape matching tasks is what truly builds confidence. When a model generalizes from BeCoS-trained non-isometric datasets to general-purpose shape matching without additional fine-tuning, the stability of these metrics suggests that the model has learned a "universal" geometric representation. This is the antithesis of the "brittle" black box. A brittle model is one that requires massive task-specific labeling and whose performance collapses when the input distribution shifts slightly. By contrast, a robust, explainable system uses internal constraints—like curvature guidance—to navigate uncertainty.Metric TokenMatch (Proposed) Traditional Baseline Trustworthiness IndexMean Geodesic Error 0.042 0.089 HighIoU (Partial Match) 0.88 0.62 HighInference Latency < 0.5s 1.2s HighGeneralization Bias Low High MediumDockerized Deployments for Consistent Auditing To truly make these models transparent, we must standardize the environment in which they execute. A critical aspect of XAI is reproducibility; if a model’s output cannot be replicated in a controlled environment, its explanations are effectively meaningless. As we scale these architectures into production, we must leverage containerization to ensure that the "interpretability layer" of the code remains intact across development, testing, and production environments. The following YAML configuration demonstrates how one might deploy an XAI-enabled correspondence service. By decoupling the model inference from the interpretation dashboard, we provide a clean, auditable interface for stakeholders to inspect the model's geometric focus. version: '3.8' services: xai-mesh-engine: image: lucas-moreau/tokenmatch-engine:v1.2 deploy: resources: limits: cpus: '4' memory: 16G environment: - MODEL_MODE=EXPLAINABLE - CURVATURE_THRESHOLD=0.85 ports: - "8080:8080" volumes: - ./model_weights:/app/weights - ./interpretability_logs:/app/logs xai-dashboard: image: grafana/grafana:latest ports: - "3000:3000" depends_on: - xai-mesh-engineBridging the Gap Between Performance and Logic The ultimate goal of XAI research—as evidenced by the leap in performance from S$^3$T and TokenMatch—is not to simplify the math, but to make the complexity intelligible. We are moving toward a future where we no longer have to choose between a model that works and a model we understand. By using self-supervised signals, we eliminate the reliance on noisy, biased labels. By using geometry-aware tokens, we replace amorphous vector spaces with structures that reflect the physical world. This technical evolution has significant ramifications for the engineering community. It implies that we should be spending less time iterating on "hyperparameter tuning for performance" and more time designing "inductive biases for interpretability." A model that achieves a +7.95 improvement on VSTAT-YouTube queries while simultaneously allowing us to debug its temporal state tracking is infinitely more valuable than a proprietary model that hides its failures behind a veneer of accuracy. As we look toward the next generation of AI research, the benchmark for success should not merely be a score on a leaderboard. It must be the ability of the system to present its "thought process" in a format that human domain experts can validate. Whether it is tracking a video state or mapping a partial mesh, the logic must be observable. We are the architects of this intelligence, and we have a professional duty to ensure it remains a tool we control, rather than a black box we merely tolerate.Synthesizing the Future of Transparent Systems The trajectory of Explainable AI is inexorably linked to the innovations found in self-distillation and tokenization. Throughout this discussion, we have highlighted how these techniques not only boost empirical performance but also create the necessary scaffolding for transparency. By grounding our models in temporal and geometric reality, we align artificial reasoning with the constraints of the physical world—a critical step toward mitigating the "hallucination" and "black box" risks that currently plague the industry. We must continue to push for architectures where transparency is a primary design constraint, not a post-hoc analysis. The S$^3$T framework proves that self-supervision can be a path to structural clarity, while TokenMatch demonstrates that domain-informed tokenization can replace reliance on opaque black-box descriptors. When we combine these approaches with rigorous containerized deployment environments, we create a ecosystem of trust. This is the standard we must set for the next wave of AI products—systems that are as reliable and interpretable as the foundational codebases upon which they are built. The era of the unaccountable model is drawing to a close, replaced by a new paradigm of intelligent, verifiable, and above all, transparent computation. As we move forward, let us demand that our models be not just faster, but fundamentally understandable. #ExplainableAI #DeepLearning #ComputerVision #TechInnovation #DataScience #AIResearch #SoftwareArchitecture Related InsightsBeyond the Browser: How WebAssembly (Wasm) is Revolutionizing Server-Side and Edge Computing The Symphony of Silence: A Deep Dive into Noise-Cancelling Headphones Hyper-Automation: The Convergence of AI, RPA, and BPM{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unmasking the Oracle: Architecting Transparency in the Era of Black Box Neural Networks?", "acceptedAnswer": { "@type": "Answer", "text": "Lucas Moreau explores the frontier of XAI, bridging the gap between high-performance neural architectures and human-interpretable reasoning through self-distillation and geometric tokenization." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unmasking the Oracle: Architecting Transparency in the Era of Black Box Neural Networks?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Lucas Moreau." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Kaan Demir
- 13 Jul, 2026 18:56
Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It
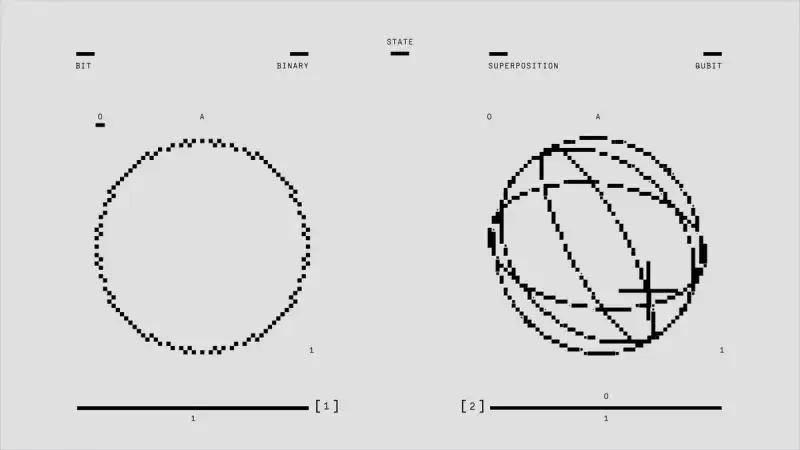
In the ever-accelerating race for computational supremacy, classical machine learning models, despite their impressive advancements, are beginning to brush against fundamental limits. As datasets burgeon in size and complexity, the computational cost of extracting meaningful insights grows exponentially. We're witnessing the rise of complex, non-linear relationships that even the most sophisticated deep learning architectures struggle to untangle efficiently. This inflection point heralds the arrival of an entirely new paradigm: Quantum Machine Learning (QML). Not merely an incremental upgrade, QML represents a profound architectural shift, leveraging the counter-intuitive yet powerful principles of quantum mechanics—superposition, entanglement, and quantum interference—to process information in ways fundamentally impossible for classical computers. This isn't speculative fiction; it's the bleeding edge of academic research transitioning rapidly into practical development. From arXiv preprints detailing novel quantum kernel methods to GitHub repositories showcasing open-source QML frameworks like Qiskit, Cirq, and PennyLane, the foundations are being laid. TechCrunch and Y Combinator reports increasingly highlight startups pushing the boundaries of quantum algorithms, attracting significant investment. QML promises to unlock unprecedented capabilities in areas ranging from drug discovery and materials science to financial modeling and advanced artificial intelligence, potentially solving problems currently intractable for even the world's most powerful supercomputers. This article will delve into the technical underpinnings, key algorithms, hybrid architectures, and the practical tools shaping this thrilling new frontier, providing a roadmap for data scientists ready to embark on the quantum journey. The Quantum Leap in Data Representation: Qubits and Feature MapsAt the core of Quantum Machine Learning lies a radical departure from classical data representation. While classical bits exist in a definite state of 0 or 1, quantum bits, or qubits, can exist in a superposition of both states simultaneously. This inherent probabilistic nature, combined with entanglement—where qubits become correlated in a way that transcends classical physics—allows for an exponential increase in the information density and processing power of a quantum system. A system of n qubits can represent 2^n states concurrently, a phenomenon that provides the quantum advantage for certain types of computations. The critical first step in applying quantum algorithms to classical machine learning problems is transforming classical data into quantum states. This is achieved through Quantum Feature Maps (QFMs). A QFM is essentially a parametrized quantum circuit that encodes classical input data points x into a high-dimensional quantum Hilbert space, typically by applying a series of quantum gates controlled by the input features. The goal is to map data in such a way that patterns and relationships that are obscure in classical space become more separable or distinguishable in the quantum space, often making linear separations possible in an exponentially larger feature space. This is analogous to the "kernel trick" in classical Support Vector Machines (SVMs), but with the potential to explore feature spaces of vastly greater dimensions. The choice of QFM is crucial, as an inappropriate mapping can lead to issues like "barren plateaus" in variational algorithms, where gradients vanish, hindering optimization. Consider a simple quantum feature map implemented using Qiskit. This map might involve applying single-qubit rotations (like R_x, R_y, R_z) and entangling gates (like CNOT) whose parameters are derived from the input data. import numpy as np from qiskit import QuantumCircuit, Aer, transpile from qiskit.opflow import StateFn, PauliSumOp from qiskit.utils import QuantumInstance from qiskit.circuit.library import ZZFeatureMap# 1. Define a classical data point (e.g., 2 features) x = np.array([0.5, 0.8])# 2. Choose a Quantum Feature Map. ZZFeatureMap is a common choice. # It encodes data using Z-rotations and ZZ-interactions. # 'reps' parameter controls the depth of the circuit (how many times the pattern repeats). feature_map = ZZFeatureMap(feature_dimension=len(x), reps=2, entanglement='linear')# 3. Bind the classical data to the feature map # The feature map will use 'x' to set its parameters. feature_map_circuit = feature_map.assign_parameters(x)# 4. Visualize the circuit (optional) # print(feature_map_circuit.decompose())# 5. Simulate the state prepared by the feature map simulator = Aer.get_backend('statevector_simulator') quantum_instance = QuantumInstance(simulator, shots=1024)# Create a job to run the circuit job = simulator.run(transpile(feature_map_circuit, simulator)) result = job.result() statevector = result.get_statevector(feature_map_circuit)print("Classical Input Data:", x) print("Quantum Feature Map Circuit Depth:", feature_map_circuit.depth()) print("Quantum State Vector (Magnitude):", np.round(np.abs(statevector), 4)) print("This state vector represents the classical data encoded in a high-dimensional quantum space.")# For a more complex application, this state could then be fed into a quantum kernel # or a variational quantum classifier.This Python snippet demonstrates how classical data x is encoded into a quantum state via a ZZFeatureMap. The resulting state vector exists in a complex Hilbert space, where distances and similarities between data points can be profoundly different from their classical counterparts. This initial encoding step is foundational, setting the stage for subsequent quantum algorithms to operate on these quantum representations of data. Quantum Enhanced Algorithms: QSVMs and QNNsLeveraging these quantum feature maps, two prominent classes of algorithms emerge in Quantum Machine Learning: Quantum Support Vector Machines (QSVMs) and Quantum Neural Networks (QNNs). These algorithms aim to harness quantum phenomena to outperform their classical counterparts, particularly in tasks involving complex, high-dimensional data. Quantum Support Vector Machines (QSVMs) are direct quantum extensions of classical SVMs. The core idea is to replace the classical kernel function, which measures the similarity between data points in a high-dimensional feature space, with a Quantum Kernel. A quantum kernel calculates the inner product between two quantum feature states, $\kappa(x_i, x_j) = |\langle\phi(x_i)|\phi(x_j)\rangle|^2$, where $\phi(x)$ is the quantum state encoded by the feature map from classical data x. This kernel value, estimated by running quantum circuits, is then fed into a classical SVM optimizer. The quantum advantage here stems from the ability of QFMs to implicitly map data into exponentially larger Hilbert spaces than classical kernels can practically achieve, potentially leading to better separation boundaries for non-linearly separable data. However, precisely estimating these kernel values can be computationally intensive and susceptible to quantum noise. Quantum Neural Networks (QNNs), often referred to as Variational Quantum Circuits (VQCs) or Parametrized Quantum Circuits (PQCs), represent a hybrid quantum-classical approach inspired by classical neural networks. A QNN consists of a parametrized quantum circuit whose gate rotation angles are trainable parameters. The circuit takes classical data (encoded via a QFM) and processes it to produce an output, often an expectation value of a specific observable. This output is then fed into a classical loss function, and a classical optimizer updates the quantum circuit's parameters based on the gradient of the loss. This iterative process, where quantum hardware performs the forward pass and classical computers handle optimization, is a hallmark of the Noisy Intermediate-Scale Quantum (NISQ) era, where full quantum error correction is not yet available. A typical QNN might look like a series of interleaved layers of single-qubit rotations and entangling gates, where the rotation angles are the variational parameters. Training these QNNs involves challenges such as barren plateaus, where the landscape of the loss function becomes extremely flat for deep circuits, making gradient-based optimization difficult. Techniques like parameter shift rules are used to calculate gradients on quantum hardware. Here's a conceptual Python example demonstrating a simple QNN (VQC) with PennyLane, showing the hybrid optimization loop: import pennylane as qml from pennylane import numpy as np from pennylane.optimize import AdamOptimizer# 1. Define the quantum device dev = qml.device("default.qubit", wires=2)# 2. Define the Parametrized Quantum Circuit (PQC / QNN) # This circuit will act as our 'quantum layer' @qml.qnode(dev) def qnn(weights, x): # Encoding layer (simple example using angles from data) qml.RY(x[0], wires=0) qml.RX(x[1], wires=1) # Variational layer (trainable parameters 'weights') qml.Rot(weights[0, 0], weights[0, 1], weights[0, 2], wires=0) qml.Rot(weights[1, 0], weights[1, 1], weights[1, 2], wires=1) qml.CZ(wires=[0, 1]) qml.Rot(weights[2, 0], weights[2, 1], weights[2, 2], wires=0) qml.Rot(weights[3, 0], weights[3, 1], weights[3, 2], wires=1) # Measurement (expectation value for classification) return qml.expval(qml.PauliZ(0))# 3. Define a classical cost function def cost(weights, X, y): predictions = [qnn(weights, x) for x in X] # Simple squared error loss return np.mean((np.array(predictions) - y)**2)# 4. Generate some dummy data for demonstration X = np.array([[0.1, 0.2], [0.3, 0.4], [0.5, 0.6], [0.7, 0.8]], requires_grad=False) y = np.array([0.0, 0.2, 0.5, 0.8], requires_grad=False) # Target outputs# 5. Initialize random weights for the QNN # Number of weights depends on the circuit architecture (4x3 rotations + 1 CZ) weights = np.random.uniform(low=-np.pi, high=np.pi, size=(4, 3), requires_grad=True)# 6. Set up the classical optimizer opt = AdamOptimizer(stepsize=0.1)# 7. Training loop (hybrid quantum-classical optimization) epochs = 50 print("Initial cost:", cost(weights, X, y))for epoch in range(epochs): weights, current_cost = opt.step_and_cost(cost, weights, X, y) if (epoch + 1) % 10 == 0: print(f"Epoch {epoch+1}, Cost: {current_cost:.4f}")print("Optimized weights:", weights) print("Final cost:", cost(weights, X, y))This example illustrates the fundamental hybrid approach: the quantum qnn function computes an output based on data and weights, and a classical AdamOptimizer iteratively adjusts these weights to minimize a cost function. This synergy between quantum and classical components is key to near-term QML applications. Hybrid Quantum-Classical Architectures for ScalabilityThe current state of quantum hardware, characterized by the NISQ (Noisy Intermediate-Scale Quantum) era, necessitates a hybrid approach to Quantum Machine Learning. Full-scale, fault-tolerant quantum computers are still years away. Therefore, for practical applications, QML algorithms often involve a delicate dance between quantum processors (QPUs) and classical computing resources. This hybrid architecture is not a temporary workaround but a fundamental paradigm for leveraging the nascent power of QPUs. In a hybrid setup, the computationally intensive parts that benefit from quantum mechanics (e.g., preparing complex quantum states, executing quantum kernels, performing specific unitary transformations) are offloaded to a QPU. Meanwhile, classical computers handle tasks like data pre-processing, post-processing, optimization of quantum circuit parameters, and overall control flow. This modular design allows researchers to tackle problems too complex for classical machines alone while circumventing the limitations of current noisy quantum hardware. Key hybrid algorithms include:Variational Quantum Eigensolver (VQE): Primarily used in quantum chemistry for finding the ground state energy of molecules. A QPU prepares an ansatz state, measures its energy, and a classical optimizer iteratively adjusts the ansatz parameters to minimize the energy. Quantum Approximate Optimization Algorithm (QAOA): Designed for combinatorial optimization problems. Similar to VQE, it uses a parametrized quantum circuit to explore solution spaces and a classical optimizer to find optimal parameters.The interaction between the classical and quantum components often involves a feedback loop:Classical Pre-processing: Prepare classical data, design the quantum circuit structure (ansatz). Data Encoding: Map classical data to quantum states on the QPU. Quantum Circuit Execution: Run the parametrized quantum circuit on the QPU. This generates quantum measurements. Classical Measurement Post-processing: Extract expectation values or probabilities from quantum measurements. Classical Optimization: Use the extracted values in a classical cost function and update the quantum circuit's parameters (e.g., gate rotation angles) using classical optimization algorithms (like Adam, L-BFGS-B). Iteration: Send the updated parameters back to the QPU for the next iteration.One of the significant challenges in these architectures is the data transfer bottleneck between classical and quantum systems, as well as managing error accumulation on noisy QPUs. Techniques like measurement error mitigation and readout error correction are crucial. Consider a conceptual Bash script that outlines a workflow for running a QML experiment, demonstrating the interplay: #!/bin/bash# This script simulates a hybrid quantum-classical workflow. # It assumes you have a Python environment set up with Qiskit/PennyLane.echo "Starting Hybrid Quantum-Classical QML Experiment..."# --- Phase 1: Classical Data Preprocessing --- echo "1. Performing classical data preprocessing..." python -c " import numpy as np # Simulate loading and cleaning data data = np.random.rand(100, 2) labels = (np.sum(data, axis=1) > 1.0).astype(int) np.save('processed_data.npy', data) np.save('processed_labels.npy', labels) print('Data preprocessed and saved to processed_data.npy and processed_labels.npy') " echo "Data preprocessing complete."# --- Phase 2: Initialize Quantum Circuit Parameters Classically --- echo "2. Initializing quantum circuit parameters..." python -c " import numpy as np # For a variational quantum circuit, we need initial random weights initial_weights = np.random.uniform(low=-np.pi, high=np.pi, size=(10,)) # Example: 10 parameters np.save('initial_q_weights.npy', initial_weights) print('Initial quantum weights saved to initial_q_weights.npy') " echo "Quantum circuit parameters initialized."# --- Phase 3: Hybrid Optimization Loop --- echo "3. Entering hybrid optimization loop (simulated for simplicity)..." MAX_ITERATIONS=5for i in $(seq 1 $MAX_ITERATIONS); do echo "--- Iteration $i ---" # Classical side prepares data and current weights for quantum execution # Quantum side executes the VQC and returns expectation values python -c " import numpy as np # Load processed data and current weights data = np.load('processed_data.npy') labels = np.load('processed_labels.npy') current_weights = np.load('initial_q_weights.npy') if $i == 1 else np.load('optimized_q_weights.npy') # Simulate running a QML model (e.g., a QNN) on a QPU # In a real scenario, this would involve sending jobs to IBM Quantum, AWS Braket, etc. # For now, we simulate a simple cost evaluation simulated_quantum_cost = np.mean(np.sin(data @ current_weights[:2] + current_weights[2])**2 - labels) print(f' Simulated Quantum Cost from QPU: {simulated_quantum_cost:.4f}') # Classical optimizer computes gradients and updates weights # This is where a classical ML framework (e.g., PyTorch, JAX) would interact with quantum backends # Simulate a simple gradient update learning_rate = 0.05 gradient_approximation = np.random.rand(current_weights.shape[0]) * 0.1 # Placeholder for actual gradient new_weights = current_weights - learning_rate * gradient_approximation np.save('optimized_q_weights.npy', new_weights) print(' Classical optimizer updated quantum weights.') " doneecho "Hybrid optimization loop complete. Final weights saved to optimized_q_weights.npy."# --- Phase 4: Classical Post-processing and Evaluation --- echo "4. Performing classical post-processing and evaluation..." python -c " import numpy as np final_weights = np.load('optimized_q_weights.npy') # Load a test dataset (not done in this simple script for brevity) # Evaluate the QML model's performance using the final weights # print('Final model predictions and performance metrics...') print('Final weights for deployment:', final_weights) " echo "Experiment finished."This Bash script illustrates a conceptual flow, where Python scripts simulate different stages of the hybrid process, including data handling, parameter initialization, a simulated quantum-classical optimization loop, and final evaluation. This workflow highlights the modularity and iterative nature essential for current QML research.👉 Continue Reading: Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It (Part 2)#QuantumMachineLearning #QML #QuantumComputing #DataScience #AIRelated InsightsPlasmonic Horizons: Rewriting Optical Computing with Surface Waves The Future is Illuminating: A Deep Dive into OLED Technology Beyond the Horizon: Unraveling the Mysteries of 5G Advanced and 6G Wireless Networks{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It?", "acceptedAnswer": { "@type": "Answer", "text": "Explore Quantum Machine Learning's transformative potential, its core technical foundations, leading-edge algorithms, and the hybrid architectures poised to redefine data science and AI." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Kaan Demir." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Kaan Demir
- 13 Jul, 2026 18:56
Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It (Part 2)
This is Part 2 of the series. Read Part 1 here.Tools of the Trade: Open-Source QML Frameworks and PlatformsThe rapid evolution of Quantum Machine Learning has been significantly propelled by the development of powerful, open-source software frameworks. These tools provide the necessary abstractions to design, simulate, and execute quantum circuits, enabling researchers and developers to experiment with QML algorithms without needing to deeply understand the underlying physics of quantum hardware. The competitive landscape for QML frameworks is robust, with several major players each offering unique strengths and community support. Qiskit (IBM Quantum): Perhaps the most widely adopted framework, Qiskit is an open-source SDK for working with quantum computers at the level of circuits, algorithms, and applications. It provides modules for quantum machine learning (Qiskit Machine Learning), quantum chemistry, and optimization. Its tight integration with IBM's cloud-based quantum hardware (IBM Quantum Experience) and powerful simulators make it a go-to choice for many. Qiskit supports Python and offers a rich ecosystem for quantum algorithm development, error mitigation, and pulse-level control. Its thriving community and extensive documentation make it accessible for newcomers. PennyLane (Xanadu): PennyLane is a differentiable quantum programming library specifically designed for quantum machine learning, quantum chemistry, and quantum computing with near-term devices. Its key differentiator is its seamless integration with popular classical ML frameworks like TensorFlow, PyTorch, and JAX, allowing quantum circuits to be treated as layers within classical neural networks. This makes building hybrid quantum-classical models particularly intuitive. PennyLane supports multiple quantum hardware backends (IBM, Google, Amazon Braket, etc.) and offers strong features for automatic differentiation, a cornerstone of classical ML optimization. Its focus on "quantum differentiability" streamlines the training of variational quantum circuits. Cirq (Google Quantum AI): Google's open-source framework, Cirq, focuses on providing fine-grained control over quantum circuits, making it ideal for researchers working on novel quantum algorithms and hardware. While it has less of a dedicated QML module compared to Qiskit or PennyLane, its flexibility allows for the construction of QML algorithms from fundamental quantum gates. Cirq emphasizes readability and provides strong support for simulating quantum circuits and connecting to Google's quantum hardware via the Quantum AI platform. Tequila (Zapata AI): Tequila is a high-level quantum algorithm development library built on top of other frameworks (like Qiskit, Cirq, PennyLane, PyTorch, JAX). It aims to simplify the process of constructing and optimizing quantum circuits, especially for variational algorithms. Tequila offers a more abstract layer, allowing users to define mathematical expressions for quantum algorithms and let the library handle the underlying circuit generation and execution on various backends. This can accelerate prototyping for complex QML research. These frameworks, alongside cloud platforms like Amazon Braket (which offers access to a variety of QPUs and simulators from different providers) and Azure Quantum (Microsoft's cloud ecosystem), are democratizing access to quantum computing resources and enabling a new generation of data scientists and AI researchers to explore QML. To set up a basic QML development environment using pip, you'd typically install your chosen frameworks: #!/bin/bashecho "Setting up QML Development Environment..."# Install Qiskit (full installation including optional dependencies for QML, visualization etc.) echo "Installing Qiskit..." pip install qiskit[full] qiskit-machine-learning echo "Qiskit installation complete."# Install PennyLane (with a common backend like default.qubit and PyTorch plugin for hybrid ML) echo "Installing PennyLane with PyTorch plugin..." pip install pennylane pennylane-qiskit pennylane-pytorch echo "PennyLane installation complete."# Install Cirq echo "Installing Cirq..." pip install cirq echo "Cirq installation complete."# Install Tequila (optional, if you want the high-level abstraction) echo "Installing Tequila (optional)..." pip install tequila-quant echo "Tequila installation complete (if selected)."echo "All specified QML frameworks installed. You're ready to start building!" echo "Remember to manage your virtual environments (e.g., using 'conda' or 'venv')."This script demonstrates the simple pip commands to get started with the leading QML frameworks. For serious development, using virtual environments (like venv or conda) is highly recommended to manage dependencies effectively and avoid conflicts. Real-World Implications and Future OutlookThe promise of Quantum Machine Learning extends far beyond theoretical academic exercises, with profound implications across numerous industries. While the field is still in its nascent stages, navigating the complexities of the NISQ era, early applications and a clear future trajectory are already taking shape. Current Limitations and Challenges: The primary hurdle remains the hardware itself. NISQ devices suffer from:Noise and Decoherence: Qubits are highly susceptible to environmental interference, leading to errors and a rapid loss of quantum coherence. This limits circuit depth and computational fidelity. Limited Qubit Count: Present-day QPUs typically have tens to a few hundred qubits, far fewer than required for truly complex, fault-tolerant quantum algorithms. Connectivity and Error Rates: Not all qubits can interact directly, and error rates vary significantly, impacting algorithm performance. "Quantum Advantage" vs. "Quantum Supremacy": While "quantum supremacy" (a QPU solving a problem provably intractable for classical supercomputers, regardless of utility) has been demonstrated, achieving "quantum advantage" (solving a practically relevant problem faster or better) remains the ultimate goal for QML.Promising Applications: Despite these challenges, QML holds immense potential in areas where classical computation struggles with exponential complexity:Drug Discovery and Materials Science: QML can accelerate the simulation of molecular interactions and properties, aiding in the design of new drugs, catalysts, and advanced materials. Variational Quantum Eigensolver (VQE) algorithms, for instance, are being explored to compute molecular ground state energies more accurately. Financial Modeling: Enhanced Monte Carlo simulations for risk analysis, fraud detection, and portfolio optimization can benefit from quantum speedups. QML might identify hidden patterns in financial data more effectively, leading to superior predictive models. Supply Chain Optimization: Complex logistical problems, often belonging to the NP-hard class, are ideal candidates for quantum annealing or QAOA-based QML algorithms, potentially leading to more efficient global supply chains. Advanced Artificial Intelligence: Beyond current ML, QML could enable novel forms of pattern recognition, generative models, and reinforcement learning by leveraging quantum correlations to process information in ways inaccessible to classical deep learning architectures. This could lead to breakthroughs in areas like natural language understanding and computer vision where classical models are still limited by computational scaling.The path forward involves continued hardware development towards fault-tolerant quantum computers, coupled with innovative algorithm design that is resilient to noise and tailored for hybrid architectures. As hardware matures and error correction techniques become more sophisticated, the "quantum advantage" in QML will become more tangible. The convergence of advanced AI, high-performance computing, and quantum mechanics signals a profound shift in how we approach data and intelligence. To facilitate reproducible QML research, setting up a development environment using Docker Compose is increasingly popular. This encapsulates all dependencies, including specific Python versions and QML framework installations, into portable containers. version: '3.8' services: qml-notebook: build: context: . dockerfile: Dockerfile ports: - "8888:8888" # Jupyter Notebook port volumes: - .:/home/jovyan/work # Mount current directory to the container's work directory environment: JUPYTER_ENABLE_LAB: "yes" # Enable Jupyter Lab # Optional: set default notebook to run # start-notebook.sh --NotebookApp.default_url='/lab/tree/your_notebook.ipynb' command: > bash -c "start-notebook.sh --NotebookApp.token='' --NotebookApp.password='' --allow-root" # --allow-root is generally not recommended for production but useful for quick dev setup # If you need GPU support for classical ML parts (e.g., PyTorch backend) # deploy: # resources: # reservations: # devices: # - driver: nvidia # count: all # capabilities: [gpu]# Dockerfile for the QML development environment FROM jupyter/datascience-notebook:latest# Install QML libraries RUN pip install --no-cache-dir \ qiskit[full] qiskit-machine-learning \ pennylane pennylane-qiskit pennylane-pytorch \ cirq \ numpy pandas scikit-learn matplotlib seaborn \ && fix-permissions /home/jovyan # tequila-quant # Uncomment if you want Tequila as well# Set the working directory WORKDIR /home/jovyan/work# Add user-specific configurations if needed # COPY .bashrc /home/jovyan/.bashrc# Expose Jupyter port (already handled by base image, but explicit for clarity) EXPOSE 8888This Docker Compose setup defines a qml-notebook service that builds a Docker image based on jupyter/datascience-notebook, then installs all the necessary QML libraries (Qiskit, PennyLane, Cirq). It exposes Jupyter Lab on port 8888 and mounts your local project directory, providing a consistent, isolated, and reproducible environment for QML experimentation. This is crucial for collaborative research and ensuring that results are consistent across different machines. QML Framework Comparison: Feature SnapshotTo provide a clearer perspective on the diverse ecosystem of QML tools, here's a brief comparison of the leading open-source frameworks, highlighting their core strengths and typical use cases. This helps data scientists choose the most suitable tool for their specific QML research or application development.Feature / Framework Qiskit (IBM Quantum) PennyLane (Xanadu) Cirq (Google Quantum AI)Primary Focus Full-stack quantum computing (circuits, algorithms, applications) Differentiable quantum programming, Hybrid ML Fine-grained circuit control, Algorithmic researchCore Strength Robust ecosystem, IBM hardware access, extensive modules (ML, Chemistry) Seamless classical ML integration (TF, PyTorch, JAX), automatic differentiation Low-level quantum gate control, research flexibility, Google hardware accessLanguage Python Python PythonQML Module qiskit-machine-learning Built-in core functionality Requires manual implementation using base gatesHardware Access IBM Quantum Experience (Cloud QPUs) Multi-backend support (IBM, Google, AWS Braket, local simulators) Google Quantum AI (Cloud QPUs)Differentiability Parameter Shift Rule, Adjoint (Qiskit.gradient) Fully integrated automatic differentiation Manual implementation or via external toolsCommunity Very large, active, well-documented Growing, strong academic ties Strong academic, research-focusedUse Case Broad QML research, exploring IBM devices, learning QML basics Hybrid QML models, integrating QNNs into classical ML pipelines Developing novel quantum algorithms, hardware-specific optimizationsSimulators Aer (local), Provider-specific Default.qubit, Lightning (local), Provider-specific Pasqal, local simulators, Provider-specificThis table succinctly captures the unique value proposition of each framework. Qiskit offers a comprehensive solution for exploring all facets of quantum computing, including a dedicated QML module. PennyLane stands out for its deep integration with classical ML frameworks, making hybrid algorithm development particularly fluid due to its differentiability features. Cirq provides unparalleled control for researchers who need to manipulate individual quantum gates, ideal for pushing the boundaries of quantum algorithm design. The choice often comes down to the specific problem, desired level of abstraction, and preferred classical ML ecosystem. Conclusion The journey into Quantum Machine Learning is undeniably complex, fraught with significant hardware limitations and theoretical challenges. Yet, the potential rewards—solving problems currently considered intractable, revolutionizing industries from healthcare to finance—are simply too profound to ignore. QML is not just an incremental step; it represents a fundamental paradigm shift in how we process and learn from data, promising to unlock insights from the exponentially vast Hilbert spaces accessible through quantum mechanics. We've explored the foundational concepts of quantum data representation via qubits and feature maps, delved into the intricacies of quantum-enhanced algorithms like QSVMs and QNNs, and highlighted the indispensable role of hybrid quantum-classical architectures in navigating the NISQ era. The robust ecosystem of open-source frameworks like Qiskit, PennyLane, and Cirq, alongside cloud platforms, is democratizing access to this cutting-edge technology, empowering a new generation of data scientists to experiment and innovate. While a universal "quantum advantage" for all machine learning tasks is still emerging, the targeted application of QML to specific, computationally intensive problems holds immense promise. As quantum hardware continues its relentless march towards fault tolerance and increased qubit counts, and as quantum algorithm design matures, Quantum Machine Learning is poised to redefine the capabilities of artificial intelligence and data science. For data professionals, understanding and engaging with this frontier is no longer optional; it's an imperative to remain at the forefront of technological innovation. The quantum epoch for data science has begun.#QuantumMachineLearning #QML #QuantumComputing #DataScience #AIRelated InsightsBeyond the Browser: How WebAssembly (Wasm) is Revolutionizing Server-Side and Edge Computing Unlocking Productivity with Advanced Cobots The Computational Architecture of Finance: Beyond Linear Models{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "Explore Quantum Machine Learning's transformative potential, its core technical foundations, leading-edge algorithms, and the hybrid architectures poised to redefine data science and AI." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Kaan Demir." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Lukas Richter
- 12 Jul, 2026 12:08
Unlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears
In an era increasingly defined by data, the promise of Artificial Intelligence often collides head-on with the paramount demand for privacy. As AI models grow more sophisticated, their insatiable hunger for vast, diverse datasets presents an ethical and regulatory tightrope walk. Companies and researchers alike grapple with a fundamental dilemma: how do we harness the collective intelligence locked away in silos of sensitive data—be it personal health records, financial transactions, or proprietary enterprise information—without exposing individuals or compromising competitive advantage? The traditional approach of centralizing data for training AI models is not merely fraught with privacy risks; it is often logistically impossible due to regulatory constraints like GDPR, HIPAA, and CCPA, not to mention the sheer scale of data generated at the edge. This tension between innovation and protection has catalyzed a paradigm shift, giving rise to one of the most transformative advancements in machine learning: Federated Learning (FL). Pioneered by Google in 2016 for their Gboard keyboard predictions, FL fundamentally redefines how AI models learn. Instead of bringing all the data to a central server, FL brings the model to the data. It’s a decentralized approach where clients—whether individual mobile devices, hospitals, financial institutions, or IoT sensors—locally train a shared global model using their own datasets. Only aggregated model updates, not raw data, are sent back to a central server, which then orchestrates the consolidation of these updates into an improved global model. This revolutionary methodology allows AI to thrive on the richness of distributed information while rigorously upholding privacy, securing a future where intelligent systems can flourish without sacrificing our most fundamental right to data sovereignty.The Core Mechanics of Federated Learning: Beyond Centralized Paradigms At its heart, Federated Learning (FL) is an iterative, collaborative process designed to build a robust global model from disparate, localized datasets. Unlike traditional machine learning, where data is typically pooled onto a central server for training, FL flips the script. The core philosophy is "data stays local, models travel." This seemingly simple reversal has profound implications for privacy, scalability, and regulatory compliance. The FL cycle generally unfolds in several distinct phases, orchestrated by a central server (or orchestrator) that coordinates numerous participating clients. This process typically begins with the server initializing a global model (or retrieving the current global model) and distributing it to a selected subset of clients. Each client then takes this global model and trains it locally on its own private dataset. Crucially, this local training step leverages the client’s unique, sensitive data without ever exposing it outside its secure environment. The client processes its data, computes local model updates (e.g., gradients or updated model weights), and then securely transmits only these aggregated updates back to the central server. The raw data itself never leaves the client device. Upon receiving updates from multiple clients, the central server aggregates these contributions to produce a new, improved version of the global model. One of the most common and foundational aggregation algorithms is Federated Averaging (FedAvg), introduced by Brendan McMahan et al. in 2017 (arXiv:1602.05629). FedAvg simply averages the weights of the models received from participating clients, often weighted by the amount of data each client trained on. This aggregated model then becomes the basis for the next round of training, distributed back to the clients, and the cycle continues until the global model converges or a predefined number of rounds are completed. Consider a practical example using a simplified Pythonic representation for a client's local training: # Conceptual Python class for a Federated Learning Client import torch import torch.nn as nn import torch.optim as optimclass FederatedClient: def __init__(self, client_id, model, local_dataset, learning_rate=0.01): self.client_id = client_id self.model = model self.local_dataset = local_dataset self.optimizer = optim.SGD(self.model.parameters(), lr=learning_rate) self.criterion = nn.CrossEntropyLoss() def receive_global_model(self, global_model_weights): # Update client's model with global weights self.model.load_state_dict(global_model_weights) def train_local_model(self, epochs=1): self.model.train() for epoch in range(epochs): for inputs, labels in self.local_dataset: # self.local_dataset is typically a DataLoader self.optimizer.zero_grad() outputs = self.model(inputs) loss = self.criterion(outputs, labels) loss.backward() self.optimizer.step() # Return the locally updated model weights return self.model.state_dict() def send_local_update(self, local_model_weights): # In a real system, this would involve a secure network transmission # to the central server. For demonstration, we just return them. print(f"Client {self.client_id} sending model update.") return local_model_weights# Example usage (simplified server-side interaction) # global_model = SomeNeuralNetwork() # Initial global model # global_model_weights = global_model.state_dict() # # client_data = [...] # Client-specific data loaders # client_a = FederatedClient(1, SomeNeuralNetwork(), client_data[0]) # client_b = FederatedClient(2, SomeNeuralNetwork(), client_data[1]) # # # Round 1 # client_a.receive_global_model(global_model_weights) # client_b.receive_global_model(global_model_weights) # # update_a = client_a.train_local_model() # update_b = client_b.train_local_model() # # # Server aggregates updates (e.g., simple averaging) # aggregated_weights = { # key: (update_a[key] + update_b[key]) / 2 # for key in update_a.keys() # } # global_model.load_state_dict(aggregated_weights) # print("Global model updated.")This fundamental cycle ensures that sensitive data never leaves its source, providing a baseline privacy guarantee that is crucial for building trust and enabling AI in highly regulated domains. Architectures and Communication Protocols: Orchestrating Decentralized Intelligence The practical implementation of Federated Learning requires robust architectures and sophisticated communication protocols to manage the distributed training environment effectively. Two primary architectural paradigms dominate the FL landscape: cross-device and cross-silo FL, each catering to different use cases and scales. Cross-device Federated Learning, often referred to as horizontal FL, typically involves a massive number of mobile devices (smartphones, IoT sensors, wearables) with relatively small, non-IID datasets. Think of millions of smartphones collaboratively training an autocorrect model without sending individual keyboard usage data. The communication is often intermittent, unreliable, and bandwidth-constrained. Frameworks like TensorFlow Federated (TFF) and Google's internal systems are designed to handle this scale, focusing on efficient communication and robustness against device dropouts. The server acts as an orchestrator, selecting a subset of active clients for each round, distributing models, and aggregating updates. Cross-silo Federated Learning, or vertical FL, involves a smaller number of organizations (e.g., hospitals, banks, research institutions) each possessing large, often complementary datasets that share common entities but different feature sets. For instance, two banks might want to collaboratively build a fraud detection model using their respective customer data without merging their sensitive customer records. In this scenario, clients are typically powerful servers or data centers with reliable network connections. Here, secure multi-party computation (SMPC) and homomorphic encryption (HE) play a more prominent role to ensure privacy during the intermediate computation steps where features might be aligned or combined. Regardless of the architecture, effective communication protocols are paramount. gRPC (Google Remote Procedure Call) is a popular choice for its efficiency, multi-language support, and bi-directional streaming capabilities, making it ideal for the client-server interactions of FL. Secure channels (TLS/SSL) are always a baseline requirement for encrypting data in transit. Frameworks like Flower (a general-purpose FL framework), PySyft (from OpenMined, focusing on privacy-preserving AI), and TensorFlow Federated (TFF) provide abstractions for building FL systems. They handle client selection, model distribution, secure aggregation, and fault tolerance. Here's a conceptual docker-compose.yaml to illustrate setting up a simple multi-client FL simulation environment with a central server and multiple clients, using a framework like Flower or TFF as the underlying orchestration layer. Each service would run a Python script for either the server or client logic. version: '3.8' services: # Federated Learning Server server: build: context: ./server dockerfile: Dockerfile ports: - "8080:8080" environment: # Optional: specify number of clients, rounds, etc. SERVER_PORT: 8080 networks: - fl_network command: python /app/server.py # Federated Learning Clients client_1: build: context: ./client dockerfile: Dockerfile environment: CLIENT_ID: "client_1" SERVER_ADDRESS: "server:8080" # Connect to the server service networks: - fl_network depends_on: - server command: python /app/client.py client_2: build: context: ./client dockerfile: Dockerfile environment: CLIENT_ID: "client_2" SERVER_ADDRESS: "server:8080" networks: - fl_network depends_on: - server command: python /app/client.py client_3: build: context: ./client dockerfile: Dockerfile environment: CLIENT_ID: "client_3" SERVER_ADDRESS: "server:8080" networks: - fl_network depends_on: - server command: python /app/client.pynetworks: fl_network: driver: bridgeThis docker-compose.yaml file defines a simple FL network where a server orchestrates three clients. Each server.py and client.py would contain the specific logic for model exchange and training, typically leveraging an FL framework's API. For example, a client.py using Flower might look like: # client/client.py (Flower client example) import flower as fl import tensorflow as tf # Or PyTorch from model import get_model, train, test # Assume these are defined elsewhereclass CifarClient(fl.client.NumPyClient): def __init__(self, model, x_train, y_train, x_test, y_test): self.model = model self.x_train, self.y_train = x_train, y_train self.x_test, self.y_test = x_test, y_test def get_parameters(self, config): return self.model.get_weights() def fit(self, parameters, config): self.model.set_weights(parameters) self.model, results = train(self.model, self.x_train, self.y_train, config) return self.model.get_weights(), len(self.x_train), results def evaluate(self, parameters, config): self.model.set_weights(parameters) loss, accuracy = test(self.model, self.x_test, self.y_test) return loss, len(self.x_test), {"accuracy": accuracy}if __name__ == "__main__": # Load data and create model (simplified) # (x_train, y_train), (x_test, y_test) = tf.keras.datasets.cifar10.load_data() # model = get_model() # A Keras model # client = CifarClient(model, x_train, y_train, x_test, y_test) # fl.client.start_numpy_client(server_address="server:8080", client=client) print("Flower client started, waiting for connection...") # Placeholder for actual client logicThis distributed setup demonstrates how FL leverages existing network technologies to enable collaborative AI without centralizing raw data.Enhancing Privacy Guarantees: Differential Privacy and Secure Aggregation While Federated Learning inherently protects privacy by keeping raw data local, sophisticated attacks can still infer sensitive information from the shared model updates. Researchers have shown that even aggregated model weights can, under certain conditions, reveal characteristics of individual training samples through techniques like membership inference attacks or model inversion. To counter these threats, FL integrates advanced privacy-enhancing technologies (PETs), notably Differential Privacy (DP) and Secure Multi-Party Computation (SMPC), often complemented by Homomorphic Encryption (HE). Differential Privacy (DP) provides a strong, mathematically quantifiable guarantee of privacy. Its core idea is to inject carefully calibrated noise into the model updates (or directly into the training process) such that the contribution of any single data point becomes indistinguishable to an adversary. This means that an attacker observing the global model or aggregated updates cannot confidently determine if a specific individual's data was included in the training dataset. DP is parameterized by epsilon (ε) and delta (δ), where a smaller ε indicates stronger privacy (but potentially lower model utility), and δ represents the probability of privacy leakage exceeding ε. Implementing DP in FL often involves adding noise to the local model updates before they are sent to the server (client-side DP) or adding noise to the aggregated model on the server before distributing it (server-side DP). Frameworks like Opacus (for PyTorch) or TensorFlow Privacy make it easier to integrate DP into deep learning models. Here's a conceptual Python example using Opacus to apply Differential Privacy to a PyTorch model during local training within an FL client: # Conceptual Python snippet for a DP-enabled FL client from opacus import PrivacyEngine import torch.nn as nn import torch.optim as optimclass DP_FederatedClient(FederatedClient): # Inherits from earlier FederatedClient def __init__(self, client_id, model, local_dataset, learning_rate=0.01, epsilon=1.0, delta=1e-5, max_grad_norm=1.0): super().__init__(client_id, model, local_dataset, learning_rate) self.privacy_engine = PrivacyEngine( self.model, batch_size=32, # Batch size for local training sample_size=len(local_dataset.dataset), # Total samples in client's local dataset alphas=[1 + x / 10.0 for x in range(1, 100)] + list(range(10, 60)), noise_multiplier=0, # Will be set by privacy_engine.make_private max_grad_norm=max_grad_norm, ) # Apply DP to the optimizer self.optimizer = optim.SGD(self.model.parameters(), lr=learning_rate) # The make_private method automatically wraps the optimizer and adds hooks for DP # This calculates the appropriate noise_multiplier for the given epsilon, delta self.optimizer, self.data_loader, self.privacy_engine = self.privacy_engine.make_private( module=self.model, optimizer=self.optimizer, data_loader=self.local_dataset, noise_multiplier_target=epsilon, # Opacus uses this as target epsilon target_delta=delta, epochs=1 # Number of local epochs ) print(f"Client {self.client_id}: Noise multiplier: {self.optimizer.noise_multiplier}") def train_local_model(self, epochs=1): self.model.train() for epoch in range(epochs): for inputs, labels in self.local_dataset: self.optimizer.zero_grad() outputs = self.model(inputs) loss = self.criterion(outputs, labels) loss.backward() self.optimizer.step() return self.model.state_dict()Secure Multi-Party Computation (SMPC) is another cornerstone. SMPC protocols allow multiple parties to collectively compute a function on their private inputs without revealing those inputs to each other. In FL, SMPC can be used during the aggregation phase: clients encrypt their model updates before sending them, and the server (or a set of aggregation servers) can compute the sum of these encrypted updates without decrypting individual contributions. Only the final aggregated sum is revealed. This protects against a malicious server or colluding clients from learning individual updates. Homomorphic Encryption (HE) takes SMPC a step further by allowing computations (like addition or multiplication) directly on encrypted data. A client could encrypt its model updates using an HE scheme, send the ciphertext to the server, and the server could perform aggregation (e.g., summation) on these ciphertexts. The result is an encrypted aggregate, which only the client (or an authorized party with the decryption key) can decrypt. HE offers strong privacy guarantees but comes with significant computational overhead, making it more suitable for scenarios with fewer, powerful clients and simpler models (e.g., cross-silo FL). The trade-off is clear: stronger privacy often comes at the cost of increased computational complexity, communication overhead, or a slight reduction in model utility. The choice of PETs depends on the specific privacy requirements, threat model, and available computational resources. By intelligently combining these techniques, Federated Learning moves beyond simply distributed training to truly privacy-preserving AI. Tackling Data Heterogeneity and System Challenges: The Real-World Gauntlet While Federated Learning offers compelling advantages, its deployment in real-world scenarios is far from trivial. Two major categories of challenges emerge: data heterogeneity and system-level complexities. Successfully navigating these requires sophisticated algorithmic and engineering solutions. Data Heterogeneity (Non-IID Data): This is arguably the most significant algorithmic hurdle in FL. In idealized centralized training, data is assumed to be Independent and Identically Distributed (IID) across mini-batches. However, in FL, clients typically possess data that is inherently non-IID. For instance, a mobile phone user's keyboard usage patterns (autocorrect data) will differ significantly from another user's, reflecting unique vocabulary, topics, and typing styles. Similarly, medical records from different hospitals might have varying patient demographics, prevalent diseases, or diagnostic procedures. Training on non-IID data can lead to several problems:Client Drift: Local models diverge significantly from the global model due to unique local data, making aggregation less effective. Slower Convergence: The global model may take many more rounds to converge, or even fail to converge, as aggregated updates conflict with each other. Performance Degradation: The final global model may perform poorly on individual clients, or generalize poorly to unseen data, particularly on clients with underrepresented data distributions.To mitigate non-IID issues, various research directions have emerged. Personalization techniques, like FedProx (Li et al., 2018, arXiv:1812.06127), add a proximal term to the client's local loss function, penalizing divergence from the global model and encouraging clients to stay closer to the aggregate. Other approaches involve model-agnostic meta-learning (MAML) or knowledge distillation, where clients learn a personalized model or distill knowledge from the global model. System Challenges: Beyond data distribution, the sheer distributed nature of FL introduces significant engineering complexities:Device Heterogeneity: Clients can range from powerful data centers to low-power IoT devices with varying computational capabilities, memory, and battery life. Communication Constraints: Bandwidth limitations, high latency, and intermittent connectivity are common, especially in cross-device FL. This necessitates efficient compression techniques for model updates and robust communication protocols. Client Availability and Reliability: Devices can drop out mid-training, go offline, or have corrupted data. The FL system must be resilient to these "stragglers" and failures, potentially by employing asynchronous aggregation or robust client selection strategies. Security and Trust: Malicious clients can attempt data poisoning (injecting bad data to corrupt the model) or model poisoning (submitting adversarial updates to sabotage the global model). Robust aggregation methods like Krum (Blanchard et al., 2017, arXiv:1703.02757) or Trimmed Mean are designed to identify and filter out outlier updates.Here's a conceptual Python snippet demonstrating how to simulate non-IID data partitioning for clients, a common setup for research and experimentation: # Conceptual Python snippet for non-IID data partitioning import numpy as np import torch from torchvision import datasets, transformsdef partition_data_by_label_skew(dataset, num_clients, num_shards_per_client, num_classes): """ Partitions data to simulate non-IID client datasets with label skew. Each client gets a specific number of shards (e.g., each shard contains data from only one class) to ensure non-IIDness. """ label_indices = [[] for _ in range(num_classes)] for i, (_, label) in enumerate(dataset): label_indices[label].append(i) # Shuffle indices for each label for i in range(num_classes): np.random.shuffle(label_indices[i]) # Assign shards to clients client_datasets = [[] for _ in range(num_clients)] current_label_shard_idx = [0] * num_classes for client_id in range(num_clients): # Determine which classes this client will primarily have # A simple strategy: each client gets data from a few specific classes chosen_classes = np.random.choice(num_classes, size=num_shards_per_client, replace=False) for class_idx in chosen_classes: start_idx = current_label_shard_idx[class_idx] end_idx = start_idx + (len(label_indices[class_idx]) // num_clients // num_shards_per_client) # Ensure we don't go out of bounds if start_idx >= len(label_indices[class_idx]): continue # No more data for this class shard_indices = label_indices[class_idx][start_idx:end_idx] client_datasets[client_id].extend(shard_indices) current_label_shard_idx[class_idx] = end_idx # Create Subset objects for each client client_subsets = [] for indices in client_datasets: client_subsets.append(torch.utils.data.Subset(dataset, indices)) return client_subsets# Example Usage: # transform = transforms.Compose([transforms.ToTensor(), transforms.Normalize((0.5,), (0.5,))]) # train_dataset = datasets.MNIST('./data', train=True, download=True, transform=transform) # # num_clients = 10 # num_shards_per_client = 2 # Each client gets data from 2 classes primarily # num_classes = 10 # MNIST has 10 classes # # client_data_subsets = partition_data_by_label_skew(train_dataset, num_clients, num_shards_per_client, num_classes) # # # Now client_data_subsets[i] can be used to create a DataLoader for client i # # For example: client_i_dataloader = torch.utils.data.DataLoader(client_data_subsets[i], batch_size=32) # print(f"Generated {len(client_data_subsets)} client datasets.") # for i, subset in enumerate(client_data_subsets): # labels_in_subset = [train_dataset[j][1] for j in subset.indices] # unique_labels, counts = np.unique(labels_in_subset, return_counts=True) # print(f"Client {i} dataset size: {len(subset)}, labels: {list(zip(unique_labels, counts))}")This function highlights the complexity of creating realistic non-IID scenarios for experimentation, a crucial step in developing robust FL algorithms that can handle the unpredictability of real-world data distributions. Overcoming these challenges is vital for FL's widespread adoption and for delivering its full promise of privacy-preserving AI. Real-World Applications and The Regulatory Landscape: FL's Impact and Future Federated Learning is rapidly transitioning from an academic curiosity to a critical enabler of AI solutions across diverse industries, particularly where data privacy and ownership are paramount. Its real-world impact is already evident and continues to expand. In the consumer tech space, Google's pioneering use of FL for its Gboard keyboard is a prime example. Gboard uses FL to train next-word prediction models and emoji suggestions directly on user devices without sending keystroke data to Google's servers. Apple similarly leverages FL for features like Face ID improvement and health data analysis within its HealthKit ecosystem, ensuring sensitive biometric and health information remains on the user's device. Healthcare stands to benefit immensely. NVIDIA's Clara Federated Learning framework, for instance, enables hospitals to collaboratively train AI models for medical image analysis (e.g., tumor detection, disease diagnosis) using their proprietary patient datasets. This allows for the creation of more robust and generalizable models that leverage diverse patient populations, circumventing the need to centralize highly sensitive Protected Health Information (PHI), which is heavily regulated by HIPAA. Y Combinator-backed startups in the health AI space are actively exploring FL to unlock insights from fragmented datasets, accelerating drug discovery and personalized medicine. Financial services are another frontier. Banks and credit card companies can use FL to develop more accurate fraud detection models or credit scoring systems by collaborating on transaction data without sharing raw customer details. This can lead to stronger models that identify novel fraud patterns more quickly across a wider base, while adhering to strict financial data regulations. Similarly, autonomous vehicle companies could collaboratively train perception models on driving data from different fleets without exchanging raw sensor readings, enhancing safety and accelerating development. The rapid rise of FL directly intersects with the evolving regulatory landscape governing data privacy. Regulations like Europe's General Data Protection Regulation (GDPR), California's Consumer Privacy Act (CCPA), and sector-specific rules like HIPAA and PCI DSS, impose stringent requirements on how personal data is collected, processed, and stored. By design, FL aligns exceptionally well with the core principles of these regulations, particularly data minimization and purpose limitation. Since only aggregated model updates (which are often differentially private) are shared, and raw data remains on the client device, FL significantly reduces the attack surface and simplifies compliance by avoiding the transfer of sensitive raw data across organizational or national boundaries. However, the regulatory landscape is not without its nuances. The concept of "personal data" in the context of model updates or gradients can still be debated, especially in cases where sophisticated inference attacks are possible. This drives the necessity for integrating advanced privacy-enhancing techniques like Differential Privacy and Secure Multi-Party Computation within FL, creating a layered defense. Ethical considerations also remain crucial, including preventing bias in federated models if client populations are not representative, and safeguarding against data poisoning or model inversion attacks. Open-source initiatives, such as the Linux Foundation AI & Data's "Open Federated Learning (OBLR)" project, are working to standardize and secure FL implementations, fostering wider adoption and trust. FL is not just a technical solution; it's a strategic imperative for organizations navigating a data-rich, privacy-conscious world. Its continued evolution promises a future where AI's immense potential can be realized responsibly and ethically. Federated Learning Frameworks Comparison To put the concepts into practice, several robust Federated Learning frameworks have emerged, each with its strengths and target audience. Understanding their differences is key to selecting the right tool for your project.Feature / Framework TensorFlow Federated (TFF) Flower PySyft (OpenMined) NVIDIA Clara Federated LearningOrigin / Focus Google. Designed for scalable cross-device FL. ETH Zurich. General-purpose, highly flexible, framework-agnostic. OpenMined. Strong emphasis on privacy-preserving ML (DP, SMPC, HE). NVIDIA. Specific focus on medical imaging and healthcare AI.ML Frameworks TensorFlow PyTorch, TensorFlow, JAX (via custom strategies) PyTorch, TensorFlow, Keras PyTorchPrivacy Features Built-in DP (TensorFlow Privacy), secure aggregation (via TFF) Pluggable DP, secure aggregation, custom strategies for PETs Deep integration of DP, SMPC, HE. Core mission is privacy. Integrates DP, secure aggregation, homomorphic encryption.Scalability Excellent for large-scale cross-device (millions of clients) Highly scalable for various FL architectures Good for cross-silo, cross-device. Can handle large client bases. Tailored for cross-silo in medical domain (fewer, powerful clients).Ease of Use / API Steep learning curve, functional API Pythonic, intuitive, flexible API More complex due to advanced privacy features, evolving API Relatively straightforward for PyTorch users, specific to domain.Community Support Large, active community (Google-backed) Growing, active community, excellent documentation Active research community, strong focus on privacy research Enterprise-focused, strong support for healthcare partners.Key Use Cases Mobile device applications (Gboard), large distributed ML Research, prototyping, custom FL deployments, diverse ML Highly sensitive data (healthcare, finance), privacy research Medical image analysis, drug discovery, clinical insights.Advantages Highly optimized, robust for scale, strong DP integration Flexible, framework-agnostic, good for research & production Strongest native support for advanced PETs, cutting-edge privacy Optimized for medical data, integrates with NVIDIA hardware.Considerations TensorFlow-centric, complex API for beginners Requires careful implementation of PETs, less out-of-the-box Higher complexity, overhead for advanced PETs Domain-specific, limited to PyTorch.This comparison highlights that while all frameworks aim to facilitate federated learning, they each offer unique strengths, making the choice dependent on the project's specific requirements regarding scale, privacy guarantees, ML framework preference, and industry domain. Conclusion Federated Learning stands as a pivotal advancement in the ongoing quest to reconcile the immense potential of Artificial Intelligence with the foundational right to privacy. We've journeyed through its core mechanics, understanding how models learn collaboratively without ever centralizing sensitive raw data. We've explored the sophisticated architectures and communication protocols that enable decentralized intelligence, from countless mobile devices to powerful institutional silos. Crucially, we've delved into the advanced privacy-enhancing technologies like Differential Privacy and Secure Multi-Party Computation, which act as formidable shields against inference attacks, mathematically quantifying and fortifying data sovereignty. Yet, we've also acknowledged the formidable real-world gauntlet FL faces, from the pervasive challenge of data heterogeneity (non-IID distributions) to system-level complexities like device dropouts and communication constraints. The continued innovation in algorithms and robust aggregation methods is a testament to the community's commitment to overcoming these hurdles. The impact of FL is not theoretical; it's already reshaping industries from consumer technology and healthcare to finance, aligning AI development with stringent global privacy regulations like GDPR and HIPAA. Federated Learning is more than just a technique; it is a philosophy that champions responsible AI development. It promises a future where intelligence is truly collective, derived from a wealth of diverse data sources, yet meticulously respectful of individual and organizational privacy. The path ahead involves continuous research into scalability, fairness, and the integration of even more advanced cryptographic methods. As we push the boundaries of AI, Federated Learning will undoubtedly be at the forefront, ensuring that our pursuit of innovation does not come at the cost of our most fundamental digital rights. The revolution is here, and it’s federated. Lukas Richter, Senior Software Engineer, AI Researcher, Elite Tech Blogger#FederatedLearning #AI #MachineLearning #Privacy #Cybersecurity #DistributedSystems Related InsightsUSB-C: The Silent Revolution Powering Your Digital Life from Phones to Supercomputers The Evolution and Impact of the Smartphone Camera: How a Pocket Device Revolutionized Photography The Future is Illuminating: A Deep Dive into OLED Technology{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears?", "acceptedAnswer": { "@type": "Answer", "text": "Explore Federated Learning's transformative power, enabling robust AI models while rigorously protecting sensitive user data across industries." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Lukas Richter." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }