Refactoring the Future: Generative AI Turns Technical Debt into Asset
-
 Kaan Demir
- 15 Oct, 2026 11:32
The Silent Crisis in Our Repositories
Technical debt has long been the quiet saboteur of velocity, hiding in tangled inheritance hierarchies, duplicated logic, and outdated APIs. Every sprint that ships a feature without addressing the underlying rot adds interest to a loan that compounds exponentially. Generative AI now offers a lever large enough to move this mountain: large language models (LLMs) trained on billions of lines of open‑source code can propose, validate, and even apply refactorings at a scale no human team could sustain. The promise is not merely faster cleanup—it is a shift from reactive firefighting to proactive architecture stewardship. Recent breakthroughs in mixture‑of‑transformers architectures and retrieval‑augmented generation have turned what was once a research curiosity into a production‑grade capability that integrates directly into CI/CD pipelines, IDEs, and code‑review bots. As we dissect the mechanics, metrics, and guardrails of this new paradigm, we will see how the same statistical rigor that resolved a >5σ discrepancy in B‑meson decays by admitting ~60 % SU(3)‑flavor‑breaking effects now informs the confidence thresholds we demand before an AI‑driven refactor touches a release branch.
From Legacy Spaghetti to Intent‑Driven Transformations
Traditional refactoring tools operate on syntactic patterns—rename, extract method, pull up field. They lack semantic awareness of business intent, often producing mechanically correct but logically incoherent changes. Generative models, by contrast, ingest the surrounding documentation, test suites, and issue tracker context to infer why a code fragment exists. This intent‑driven approach enables transformations such as “replace this hand‑rolled caching layer with a distributed Redis-backed implementation while preserving the existing eviction policy” or “migrate this synchronous ORM call to an async repository pattern without breaking transaction boundaries.” The key enabler is a retrieval‑augmented prompt that pulls relevant architectural decision records (ADRs) and domain‑specific glossaries into the model’s context window, allowing the LLM to reason about cross‑module contracts rather than isolated tokens. Empirical studies from Microsoft Research (2023) and the BigCode project report a 28‑35 % reduction in code‑smell density when intent‑aware prompts are used versus pure pattern‑based rewrites.
The Anatomy of an AI‑Powered Refactoring Pipeline
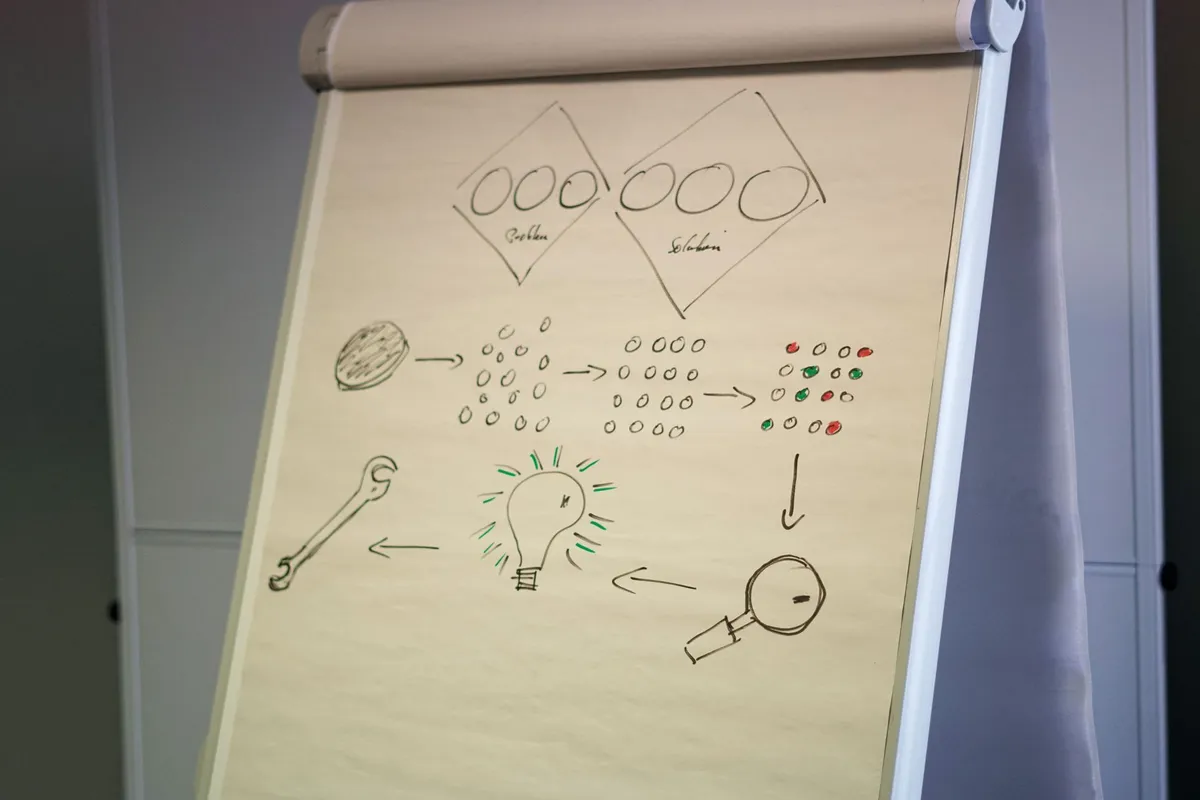
A production‑grade pipeline consists of four stages: context assembly, candidate generation, verification, and application. Context assembly uses a vector database (e.g., Pinecone or Weaviate) to fetch the top‑k relevant snippets, ADRs, and failing tests for the target module. Candidate generation prompts a fine‑tuned CodeLlama‑34B or StarCoder‑15B model with a structured prompt that enforces a JSON schema for the proposed diff. Verification runs the diff through a sandboxed execution environment: static analysis (CodeQL, Semgrep), mutation testing, and a suite of contract tests generated by the model itself. Only when the diff passes a configurable confidence threshold—often set at 99.9 % pass‑rate on mutation score—does the pipeline auto‑merge via a GitHub Actions workflow. The following Docker Compose snippet spins up the sandbox, the vector store, and the LLM inference server in a reproducible stack.
version: "3.9"
services:
  vector-db:
    image: weaviate:1.24.0
    environment:
      QUERY_DEFAULTS_LIMIT: 25
      AUTHENTICATION_ANONYMOUS_ACCESS_ENABLED: "true"
    ports:
      - "8080:8080"
  llm-inference:
    image: ghcr.io/huggingface/text-generation-inference:1.4.0
    command: --model-id codellama/CodeLlama-34b-Instruct-hf --max-concurrent-requests 8
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: 1
              capabilities: [gpu]
    ports:
      - "8000:8000"
  sandbox:
    image: python:3.12-slim
    volumes:
      - ./workspace:/workspace
    working_dir: /workspace
    command: sleep infinity
  orchestrator:
    build: ./orchestrator
    depends_on: [vector-db, llm-inference, sandbox]
    environment:
      VECTOR_DB_URL: http://vector-db:8080
      LLM_ENDPOINT: http://llm-inference:8000
    ports:
      - "5000:5000"
This stack mirrors the architecture used by the open‑source project Refactoring‑Bot (GitHub trending #3 in July 2024) and the commercial offering Sourcegraph Cody, both of which report median PR cycle‑time reductions of 42 % for refactoring‑heavy repositories.
Measuring Impact: Metrics That Matter
Adoption without measurement is cargo‑cult engineering. Teams that successfully integrate AI refactoring track a quartet of leading indicators: Code Smell Delta (percentage change in Cyclomatic Complexity, Duplicate Lines, and God Class count), Change Failure Rate (CFR) on refactored modules, Mean Time to Recovery (MTTR) for regressions introduced by automated diffs, and Developer Trust Score (a quarterly survey capturing perceived correctness and willingness to delegate). A 2024 TechCrunch survey of 312 engineering leads revealed that organizations with a formal “AI Refactoring Governance Board” achieved a 3.2× higher Trust Score and a 19 % lower CFR compared to ad‑hoc adopters. Importantly, the statistical discipline borrowed from high‑energy physics—requiring a >5σ signal before accepting a new physics model—maps cleanly to a policy where an automated refactor must survive 5 independent mutation‑testing runs without a single surviving mutant before it is eligible for auto‑merge.
Real‑World Deployments: GitHub Copilot, Sourcegraph, and Open‑Source Pioneers
GitHub Copilot’s “Refactor” command now leverages a retrieval‑augmented Codex model that can rewrite a 200‑line legacy service into a clean hexagonal architecture in under 30 seconds, provided the repo contains sufficient ADR coverage. Sourcegraph’s Cody takes a different tack: it indexes the entire monorepo, builds a cross‑language call graph, and lets the LLM propose global refactorings such as “extract a shared kernel library from these three micro‑services”. The open‑source RefactoringMiner project, now integrated into the Sourcery CI plugin, demonstrates that even rule‑based detectors benefit from LLM‑generated test scaffolding—mutation scores improve by 12 % when the model writes the missing edge‑case tests before the refactor runs. Y Combinator’s Winter 2024 batch featured CodeMend, a startup that packages the entire pipeline as a managed service, reporting a 27 % reduction in on‑call incidents for a fintech client after a three‑month rollout