Showing Posts From
Technology
-
 Eleanor Sterling
- 13 Jul, 2026 23:24
Revolutionizing Software Development: The Game-Changing Power of Generative AI for Code
Introduction The software development landscape is on the cusp of a revolution, driven by the rapid advancement of generative AI for code. This cutting-edge technology has the potential to transform the way developers work, making them more efficient, productive, and creative. By harnessing the power of AI, developers can automate repetitive tasks, generate high-quality code, and focus on complex problem-solving. In this article, we will delve into the world of generative AI for code, exploring its applications, benefits, and future directions. As we navigate this exciting new frontier, it's essential to understand the underlying concepts, techniques, and tools that are driving this revolution. From machine learning algorithms to natural language processing, we will examine the key technologies that are making generative AI for code a reality. What is Generative AI for Code? Generative AI for code refers to the use of artificial intelligence and machine learning algorithms to generate, modify, and optimize software code. This can include tasks such as code completion, code review, and code generation. By analyzing vast amounts of code data, generative AI models can learn to recognize patterns, identify errors, and predict outcomes. One of the most popular approaches to generative AI for code is the use of transformer-based models, such as the GitHub Copilot. These models are trained on large datasets of code and can generate high-quality code snippets, functions, and even entire programs. For example, the following Python code snippet demonstrates how to use the Hugging Face Transformers library to generate code: from transformers import AutoModelForCausalLM, AutoTokenizer# Load pre-trained model and tokenizer model = AutoModelForCausalLM.from_pretrained("github/copilot") tokenizer = AutoTokenizer.from_pretrained("github/copilot")# Define input prompt prompt = "def greet(name: str) -> None:"# Generate code input_ids = tokenizer(prompt, return_tensors="pt").input_ids output = model.generate(input_ids, max_length=100)# Print generated code print(tokenizer.decode(output[0], skip_special_tokens=True))This code snippet generates a simple greet function in Python, demonstrating the power of generative AI for code. Applications of Generative AI for Code The applications of generative AI for code are vast and varied, ranging from automated code review and testing to code generation and optimization. One of the most significant benefits of generative AI for code is its ability to reduce the workload of developers, allowing them to focus on higher-level tasks such as design, architecture, and innovation. For example, the following YAML configuration file demonstrates how to use the GitHub Actions workflow to automate code review and testing: name: Code Review and Testingon: push: branches: - mainjobs: build-and-test: runs-on: ubuntu-latest steps: - name: Checkout code uses: actions/checkout@v2 - name: Run code review run: | pip install flake8 flake8 . - name: Run tests run: | pip install pytest pytest .This YAML configuration file automates the code review and testing process, ensuring that code changes are thoroughly reviewed and tested before deployment. Challenges and Limitations of Generative AI for Code While generative AI for code has the potential to revolutionize software development, it also faces several challenges and limitations. One of the most significant challenges is the need for high-quality training data, which can be difficult to obtain and preprocess. Additionally, generative AI models can be computationally intensive, requiring significant resources and infrastructure. For example, the following Bash script demonstrates how to deploy a generative AI model using Docker Compose: docker-compose up -d docker-compose exec generative-ai python train.pyThis Bash script deploys a generative AI model using Docker Compose, demonstrating the complexity of deploying and managing AI-powered systems. Future Directions of Generative AI for Code The future of generative AI for code is exciting and rapidly evolving. As the technology continues to advance, we can expect to see new applications, tools, and techniques emerge. One of the most promising areas of research is the development of multimodal generative AI models, which can generate code, text, and images simultaneously. For example, the following comparison table highlights the differences between various generative AI models:Model Code Generation Text Generation Image GenerationTransformerGenerative Adversarial Network (GAN)Variational Autoencoder (VAE)Conclusion and Sign-off In conclusion, generative AI for code has the potential to revolutionize software development, making it faster, more efficient, and more creative. As we continue to explore this exciting new frontier, it's essential to stay up-to-date with the latest advancements, techniques, and tools. Whether you're a seasoned developer or just starting out, generative AI for code is an area worth watching. As we move forward, we can expect to see significant improvements in code quality, productivity, and innovation. Thank you for joining me on this journey into the world of generative AI for code. Until next time, stay coding! #AI #SoftwareDevelopment #GenerativeAI Related InsightsBeyond the Fingerprint: Unlocking Identity with Iris, Vein, and Behavioral Biometrics How to Set Up a Privacy-First Smart Home Using Edge AI Hubs Homomorphic Encryption - Part 02: Real-World Applications in Privacy-Preserving Analytics{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Revolutionizing Software Development: The Game-Changing Power of Generative AI for Code?", "acceptedAnswer": { "@type": "Answer", "text": "Discover how generative AI is transforming software development workflows, increasing productivity, and improving code quality. Explore the latest advancements and techniques in AI-powered coding." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Revolutionizing Software Development: The Game-Changing Power of Generative AI for Code?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Eleanor Sterling." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Lukas Richter
- 13 Jul, 2026 22:16
Industrial Metaworlds: How AI-Driven Digital Twins Are Redefining Real-Time Factory Automation
For decades, the concept of the "digital twin" was limited to static 3D CAD models, basic telemetry dashboards, and offline simulation runs that took hours—if not days—to compute. These historical implementations operated in disconnected silos, failing to capture the dynamic, non-linear realities of modern industrial environments. Today, we are witnessing a monumental paradigm shift. The convergence of high-frequency industrial telemetry, edge computing, and artificial intelligence has given birth to the cognitive digital twin: a live, bi-directionally synchronized, self-learning simulation that mirrors physical assets in real-time. By leveraging advanced machine learning paradigms, particularly Physics-Informed Neural Networks (PINNs) and Fourier Neural Operators (FNOs), modern software architectures can now bypass the computational bottlenecks of traditional finite element analysis (FEA). Instead of relying on raw compute-heavy numerical solvers to predict fluid dynamics, structural stress, or thermal distribution, engineers can deploy trained neural operators that run inference in milliseconds. This enables closed-loop control systems where the digital twin does not merely observe, but actively optimizes the physical asset. Building such systems requires a deep understanding of hybrid systems architecture. It demands ultra-low-latency ingestion pipelines, high-fidelity semantic standardization, and scalable cloud-edge orchestration. This article provides an exhaustive, production-grade technical breakdown of how to build, deploy, and scale real-time AI-driven digital twins for complex industrial assets.1. The Convergence of IoT, Physics-Informed Neural Networks (PINNs), and Industrial TelemetryTraditional numerical simulations rely heavily on discretization methods like Finite Element Method (FEM) or Finite Difference Method (FDM). While highly accurate, these approaches scale poorly when integrated into real-time operational pipelines. If a gas turbine experiences a transient thermal spike, an operator cannot wait forty-five minutes for a thermal CFD solver to complete. To bridge this gap, AI researchers have turned to Physics-Informed Neural Networks (PINNs). PINNs integrate the governing physical equations (e.g., Navier-Stokes for fluid dynamics, Fourier's Law for heat conduction) directly into the neural network's loss function. By penalizing predictions that violate physical laws, PINNs achieve high generalization accuracy even when trained on sparse, noisy industrial sensor data. To implement a PINN, we define a multi-layer perceptron (MLP) where the inputs are spatial coordinates $(x, y, z)$ and time $(t)$, and the outputs are physical states (e.g., temperature $u$). During backpropagation, we compute the partial derivatives of $u$ with respect to the inputs using automatic differentiation, allowing us to evaluate the physical residual. Below is a functional PyTorch implementation demonstrating how to construct a custom loss function for a PINN that models a 1D heat diffusion process—a core component of thermal digital twins used in rotary kilns and chemical reactors. import torch import torch.nn as nnclass HeatEquationPINN(nn.Module): def __init__(self, input_dim=2, hidden_dim=64, output_dim=1): super(HeatEquationPINN, self).__init__() self.net = nn.Sequential( nn.Linear(input_dim, hidden_dim), nn.Tanh(), nn.Linear(hidden_dim, hidden_dim), nn.Tanh(), nn.Linear(hidden_dim, hidden_dim), nn.Tanh(), nn.Linear(hidden_dim, output_dim) ) def forward(self, x, t): # Concatenate spatial and temporal coordinates inputs = torch.cat([x, t], dim=1) return self.net(inputs)def compute_pinn_loss(model, x, t, thermal_diffusivity=0.01): # Enable gradient tracking on inputs for automatic differentiation x.requires_grad_(True) t.requires_grad_(True) # Forward pass u = model(x, t) # Compute first-order derivatives u_g = torch.autograd.grad(u, [x, t], grad_outputs=torch.ones_like(u), create_graph=True) u_x = u_g[0] u_t = u_g[1] # Compute second-order derivative for spatial coordinate (d^2u / dx^2) u_xx = torch.autograd.grad(u_x, x, grad_outputs=torch.ones_like(u_x), create_graph=True)[0] # Define the 1D Heat Equation residual: u_t - alpha * u_xx = 0 physics_residual = u_t - thermal_diffusivity * u_xx # Mean Squared Error of the physical residual loss_physics = torch.mean(physics_residual ** 2) return loss_physicsBy deploying models like this within the digital twin runtime, we can predict internal structural states that are physically impossible to instrument with physical sensors. This methodology is known as virtual sensing.2. Architecting the Real-Time Data Pipeline: Kafka, MQTT, and Rust-based Edge IngestionThe foundation of any digital twin is its real-time data ingestion pipeline. In industrial environments, physical assets emit telemetry data via legacy protocols such as Modbus, Profinet, or OPC Unified Architecture (OPC-UA). An edge gateway must ingest these heterogeneous streams, serialize them into a unified format, and route them to high-throughput message brokers in the cloud or local on-premise clusters. To achieve sub-millisecond parsing and high throughput, modern industrial gateways are increasingly written in Rust. Rust’s lack of a garbage collector guarantees predictable latency profiles, while its robust concurrency model prevents data races when processing multi-threaded sensor inputs. The architecture starts with an edge gateway reading from an OPC-UA server on the factory floor. The gateway serializes raw binary packets into Protocol Buffers (Protobuf) for minimal payload sizes, then publishes them to an MQTT broker. From there, an enterprise-grade message broker like Apache Kafka or Redpanda ingests the streams to distribute them to simulation databases and live inference workers. The following Rust example demonstrates a high-performance edge consumer using the Tokio asynchronous runtime. It connects to an MQTT broker, processes incoming industrial telemetry packets, and prepares them for stream-processing ingestion. use tokio; use rumqttc::{AsyncClient, MqttOptions, QoS}; use std::time::Duration;#[tokio::main] async fn main() -> Result<(), Box<dyn std::error::Error>> { // Configure MQTT options with client ID and broker address let mut mqttoptions = MqttOptions::new("edge_ingest_gateway_01", "broker.hivemq.com", 1883); mqttoptions.set_keep_alive(Duration::from_secs(5)); // Initialize the asynchronous client and event loop let (client, mut eventloop) = AsyncClient::new(mqttoptions, 10); // Subscribe to high-frequency industrial telemetry topics client.subscribe("factory/facility_01/sensor_mesh/+", QoS::AtLeastOnce).await?; println!("Edge Ingestion Gateway initialized. Monitoring telemetric streams..."); // Event loop processing incoming network packets with zero-copy parsing loop { match eventloop.poll().await { Ok(notification) => { if let rumqttc::Event::Incoming(rumqttc::Packet::Publish(publish)) = notification { let payload = publish.payload; // In a production scenario, deserialization happens here via prost/protobuf if let Ok(telemetry_str) = std::str::from_utf8(&payload) { tokio::spawn(async move { process_telemetry_packet(telemetry_str).await; }); } } } Err(e) => { eprintln!("Network packet processing error: {:?}", e); tokio::time::sleep(Duration::from_secs(1)).await; } } } }async fn process_telemetry_packet(data: &str) { // Highly-optimized parsing and feature extraction for AI inference models // This payload is routed directly to the real-time simulation layer let timestamp = chrono::Utc::now().to_rfc3339(); println!("[{}] Ingested Telemetry Data Stream: {}", timestamp, data); }This Rust pipeline guarantees that high-velocity telemetry data from hundreds of physical actuators is safely queued and delivered to the neural networks with virtually zero overhead.3. Predictive Maintenance and State Estimation via Kalman Filters and Deep LearningA critical objective of any digital twin is predictive maintenance—specifically, estimating the Remaining Useful Life (RUL) of critical components. However, pure data-driven deep learning models often struggle with sensor noise and transient operational anomalies, leading to false positives. To solve this, advanced digital twin architectures combine statistical state estimation with deep learning. By utilizing a hybrid model—such as pairing an Extended Kalman Filter (EKF) with a Temporal Fusion Transformer (TFT)—the digital twin can filter out high-frequency noise while capturing long-term degradation patterns. The Kalman Filter models the linear physical transitions of the asset, while the neural network predicts the non-linear degradation trends (such as bearing wear or turbine blade erosion). The Python snippet below demonstrates how to implement a state estimation fusion node. It processes noisy raw sensor inputs, runs them through a 1D Kalman Filter, and feeds the cleaned state vector into a pre-trained neural network that predicts the health index of a CNC spindle motor. import numpy as npclass HybridStateEstimator: def __init__(self, process_variance, measurement_variance, initial_state): # Initialize Kalman Filter state variables self.Q = process_variance # Process noise covariance self.R = measurement_variance # Measurement noise covariance self.x = initial_state # Estimated state self.P = 1.0 # Estimation error covariance def update(self, measurement): # 1. Prediction step (State propagation) self.P = self.P + self.Q # 2. Measurement Update step (Correction) kalman_gain = self.P / (self.P + self.R) self.x = self.x + kalman_gain * (measurement - self.x) self.P = (1 - kalman_gain) * self.P return self.x# Simulated Spindle Motor Diagnostic Loop if __name__ == "__main__": # Parameters derived from historical operational baselines estimator = HybridStateEstimator(process_variance=1e-5, measurement_variance=0.04, initial_state=80.0) # Simulated noisy sensor stream representing temperature readings noisy_sensor_stream = [80.1, 80.5, 79.9, 81.2, 83.5, 85.1, 84.8, 86.2, 89.0, 92.5] print("Beginning state estimation and health index analysis...") for i, raw_val in enumerate(noisy_sensor_stream): filtered_state = estimator.update(raw_val) # Simulated Neural Network RUL calculation based on filtered state # In production, this call targets an active Triton Inference Server instance predicted_health_index = max(0.0, 100.0 - (filtered_state - 80.0) * 4.5) print(f"Step {i:02d} | Raw Temp: {raw_val:.2f}°C | Filtered: {filtered_state:.2f}°C | Health Index: {predicted_health_index:.1f}%")Integrating mathematical state filtering with neural inference ensures the digital twin remains highly robust against transient sensor glitches, preventing costly accidental emergency plant shutdowns.4. Standardizing the Twin: Asset Administration Shells (AAS) and W3C Web of Things (WoT) To prevent vendor lock-in and ensure that different machines on a factory floor can seamlessly talk to one another, the digital twin industry relies on standardization frameworks. The most prominent standards are the Asset Administration Shell (AAS)—developed by the Platform Industrie 4.0 initiative—and the W3C Web of Things (WoT) specification. An Asset Administration Shell acts as a digital container that wraps an asset's data models, technical specifications, and AI service endpoints into a unified semantic structure. By defining assets using structured schemas, we ensure that an AI system trained on a robotic arm from Manufacturer A can seamlessly interface with a robotic arm from Manufacturer B. A standardized digital twin configuration is typically represented using JSON-LD (JSON for Linking Data). This format maps properties to global ontologies, allowing automated orchestration agents to query capabilities, real-time values, and machine learning endpoints dynamically. { "@context": [ "https://www.w3.org/2019/wot/td/v1", { "aas": "https://admin-shell-io.org/submodels/spindle-motor-telemetry#" } ], "@type": "Thing", "id": "urn:uuid:fca3e1b0-74b8-4c10-91bc-da120468cbbf", "title": "Industrial Spindle Motor Twin", "description": "High-fidelity semantic digital twin representation of CNC Spindle Motor #42", "properties": { "rotationalSpeed": { "type": "number", "minimum": 0, "maximum": 24000, "unit": "rpm", "observable": true, "forms": [{ "href": "coap://10.10.2.14/sensors/speed", "contentType": "application/json" }] }, "windingTemperature": { "type": "number", "unit": "degreeCelsius", "observable": true, "forms": [{ "href": "mqtt://broker.internal/factory/cnc42/temp", "contentType": "application/json" }] } }, "actions": { "runThermalPrediction": { "description": "Triggers the FNO thermal simulation engine", "input": { "type": "object", "properties": { "timesteps": { "type": "integer", "default": 60 } } }, "output": { "type": "array", "items": { "type": "number" } }, "forms": [{ "href": "https://ai-inference.internal/v1/models/fno_thermal:predict", "contentType": "application/json", "op": ["invokeaction"] }] } } }With this semantic metadata layer, any orchestrator can immediately understand how to read the spindle speed, subscribe to its temperature, and run a neural thermal simulation.5. Deploying the Digital Twin Cluster: Kubernetes, KubeEdge, and Helm OrchestrationDeploying a real-time digital twin system at scale requires a highly scalable cloud-native runtime environment. A typical production cluster must manage edge ingestion daemons, stream processing pipelines, databases, and GPU-accelerated inference servers (such as NVIDIA Triton Inference Server or TorchServe) to host the physical neural networks. Kubernetes (K8s) is the industry-standard orchestrator for these workloads. To extend Kubernetes to the factory floor, engineers use KubeEdge or K3s. These lightweight distributions run reliably on resource-constrained edge gateways while allowing central cloud infrastructure to schedule containers directly to the edge. By deploying Triton on GPU nodes in the factory cluster, we can leverage dynamic batching and concurrent model execution to run hundreds of PINN and FNO simulations in parallel. The following Kubernetes Deployment manifest shows how to deploy a scalable NVIDIA Triton Inference Server instance optimized for executing high-throughput digital twin neural operators on edge GPUs. apiVersion: apps/v1 kind: Deployment metadata: name: digital-twin-inference-server namespace: industrial-ai labels: app: triton-inference-server spec: replicas: 3 selector: matchLabels: app: triton-inference-server template: metadata: labels: app: triton-inference-server spec: containers: - name: triton-server image: nvcr.io/nvidia/tritonserver:23.08-py3 args: ["tritonserver", "--model-repository=/models", "--allow-gpu-metrics=true"] ports: - containerPort: 8000 name: http-inference - containerPort: 8001 name: grpc-inference - containerPort: 8002 name: metrics resources: limits: nvidia.com/gpu: 1 memory: 8Gi cpu: "4" requests: nvidia.com/gpu: 1 memory: 4Gi cpu: "2" volumeMounts: - name: model-repository-volume mountPath: /models volumes: - name: model-repository-volume persistentVolumeClaim: claimName: nfs-model-store-pvcThis manifest provisions a highly resilient inference pool that automatically recovers if physical hardware nodes fail, guaranteeing maximum operational uptime for the active industrial simulation.Technical Comparison of Digital Twin Methodologies To choose the right technical approach for an industrial installation, architects must weigh the trade-offs of different simulation paradigms. The table below outlines the core characteristics of each approach:Feature / Metric Static CAD & Telemetry Physics-Based (FEA/CFD) Pure Deep Learning Hybrid PINN / FNOInference Latency Milliseconds Hours to Days Sub-millisecond MillisecondsOut-of-Distribution Safety High (Hardcoded limits) Absolute (Governed by physics) Extremely Low (Hallucinations) High (Physically bounded)Compute Complexity Minimal Extremely High Low (Post-training) Medium (Triton GPU-optimized)Data Requirements None Low (Needs material constants) Extremely High (Historical runs) Medium (Combines physics + data)Primary Use-Case Monitoring & Assets Inventory Heavy engineering design validation Anomaly detection in stable states Real-time interactive control loopsConclusion The development of real-time AI-driven digital twins marks a massive leap forward in industrial engineering. By blending physical models with data-driven AI systems, we are moving past static, reactive monitoring. We are paving the way for highly autonomous, self-optimizing factories. This architecture is built on robust foundations: low-latency Rust-based edge ingestion, semantic standardization via Asset Administration Shells, hybrid state estimation algorithms, and scalable, containerized cloud-edge deployments. As high-performance compute hardware continues to shrink and find its way to the edge, and neural operator research (like FNOs) continues to mature, we will soon see digital twins that run continuous, real-time simulation loops for entire chemical plants, logistics networks, and urban power grids. The companies that design, build, and run these hybrid systems today will be the ones that define the industrial efficiency of tomorrow. Keep hacking, keep building, and never stop optimizing.#AI #IndustrialIoT #Kubernetes #EdgeComputing #DigitalTwins Related InsightsQuantum Resonance: The Hidden Symbiosis of Cybersecurity and Quantum Computing in the Age of Polaritons and Galactic Illusions Graphene's Quantum Sieve: Rewriting the Thermodynamics of Planetary Hydration Holographic Displays: The Silent Revolution Reshaping AR/VR, 3D Visualization, and Human-Computer Interaction{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Industrial Metaworlds: How AI-Driven Digital Twins Are Redefining Real-Time Factory Automation?", "acceptedAnswer": { "@type": "Answer", "text": "An architectural deep-dive into building real-time industrial digital twins using Physics-Informed Neural Networks, Rust edge gateways, and Kubernetes." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Industrial Metaworlds: How AI-Driven Digital Twins Are Redefining Real-Time Factory Automation?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Lukas Richter." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Alexander Vance
- 13 Jul, 2026 20:37
Quantum Singularity: How Post-Quantum Crypto Will Reshape Our Digital Destiny Forever
In the hallowed halls of secure data transmission and digital privacy, a tremor has begun to ripple, threatening to become an earthquake of unprecedented scale. The foundational pillars of our digital trust—the cryptographic algorithms protecting everything from financial transactions to national security secrets—are facing an existential threat from the inexorable march of quantum computing. We stand at the precipice of what many in the tech elite are calling "Q-Day," the moment when large-scale, fault-tolerant quantum computers become powerful enough to shatter the mathematical problems underpinning virtually all modern public-key cryptography. This isn't theoretical speculation whispered in academic corridors; it's a stark, looming reality that demands immediate, decisive action. For decades, the security of algorithms like RSA and Elliptic Curve Cryptography (ECC) has rested on the perceived computational intractability of factoring large prime numbers or solving discrete logarithms. These problems are practically impossible for even the most powerful classical supercomputers to solve within a meaningful timeframe. However, quantum computers, leveraging the bizarre principles of superposition and entanglement, possess the potential to execute algorithms like Shor's with terrifying efficiency, rendering these classical ciphers obsolete overnight. Furthermore, symmetric encryption, while less directly threatened, faces a significant reduction in security due to Grover's algorithm. The race is on: a silent, global sprint by nations and corporations alike to transition to Post-Quantum Cryptography (PQC) – a new breed of algorithms resilient against both classical and quantum attacks. This article will dissect the quantum threat, delve into the intricacies of the PQC transition, and arm you with the technical insights needed to navigate this paradigm shift. The future of digital security depends on it. The Quantum Threat Landscape: Shor's and Grover's Algorithms in Detail The bedrock of modern public-key cryptography is the computational difficulty of specific mathematical problems. For RSA, it’s integer factorization; for ECC, it’s the elliptic curve discrete logarithm problem (ECDLP). These problems are exponentially hard for classical computers, meaning the time required to solve them grows exponentially with the key size. This is where quantum computing fundamentally shifts the paradigm. Peter Shor's algorithm, published in 1994 (arXiv:quant-ph/9508027), provides an exponential speedup for factoring large integers and solving discrete logarithms. A quantum computer running Shor's algorithm can factor an L-bit number in polynomial time, specifically O(L^3) operations, whereas the best-known classical algorithms (like the General Number Field Sieve) require sub-exponential time, L^(1/3). This translates to a catastrophic break for RSA, DSA, and ECC, which form the backbone of TLS, VPNs, digital signatures, and secure boot processes. The key insight of Shor's algorithm lies in its use of quantum Fourier transform to find the period of a modular exponentiation function, an operation that classically requires an intractable search. Current quantum hardware, such as IBM's Eagle processors or Google's Sycamore, while impressive, still lack the error-corrected qubits and connectivity required for large-scale Shor's execution. However, the theoretical framework is solid, and the engineering challenges are being aggressively tackled by institutions like IBM Quantum, AWS Braket, and various national labs. Grover's algorithm, introduced by Lov Grover in 1996 (arXiv:quant-ph/9605043), addresses a different challenge: searching an unstructured database. While it offers only a quadratic speedup (O(sqrt(N)) instead of O(N) for a classical search), its implications for symmetric-key cryptography (like AES-256) are significant. A classical brute-force attack on AES-256 requires 2^256 operations. A quantum computer using Grover's algorithm could find the key in approximately 2^(256/2) = 2^128 operations. This means that to maintain the same security level against a quantum adversary, the effective key length for symmetric ciphers would need to be doubled. An AES-128 protected system, for instance, would effectively become AES-64 against a Grover attack, requiring an upgrade to AES-256 (or higher) to maintain 128-bit security. This necessitates a re-evaluation of all symmetric key sizes, even though the threat is less immediate than for public-key systems. Consider the practical implications. An attacker could "harvest now, decrypt later" – intercepting encrypted communications today, storing them, and decrypting them once a sufficiently powerful quantum computer becomes available. This is particularly concerning for long-lived secrets, state secrets, and classified data. To illustrate the classical vulnerability, consider a rudimentary Python script for RSA key generation. While the cryptography library handles the complex math, the underlying principle is vulnerable: from cryptography.hazmat.primitives.asymmetric import rsa from cryptography.hazmat.primitives import serialization from cryptography.hazmat.backends import default_backend# Classical RSA Key Generation (e.g., 2048-bit) def generate_rsa_key_pair(key_size_bits=2048): """ Generates an RSA private and public key pair. This classical algorithm is vulnerable to Shor's algorithm on a quantum computer. """ private_key = rsa.generate_private_key( public_exponent=65537, key_size=key_size_bits, backend=default_backend() ) public_key = private_key.public_key() print(f"Generated RSA {key_size_bits}-bit key pair.") print(f"Public key (first 100 chars): {public_key.public_bytes(serialization.Encoding.PEM, serialization.PublicFormat.SubjectPublicKeyInfo).decode()[:100]}...") print(f"Private key (first 100 chars): {private_key.private_bytes(serialization.Encoding.PEM, serialization.PrivateFormat.PKCS8, serialization.NoEncryption()).decode()[:100]}...")if __name__ == "__main__": generate_rsa_key_pair() print("\nWARNING: This RSA key generation, while secure against classical computers,") print("is theoretically vulnerable to Shor's algorithm running on a sufficiently powerful quantum computer.")This Python snippet demonstrates the generation of an RSA key pair, a standard practice today. However, the "WARNING" highlights the critical point: the mathematical problem (integer factorization) upon which RSA's security relies can be efficiently solved by a quantum computer. The transition to PQC is about replacing these vulnerable primitives with new, quantum-resistant ones. NIST's PQC Standardization: The Race for Resilient Algorithms Recognizing the impending "Q-Day," the U.S. National Institute of Standards and Technology (NIST) initiated a global competition in 2016 to solicit, evaluate, and standardize new Post-Quantum Cryptography (PQC) algorithms. This multi-year, multi-round process involved submissions from cryptographers worldwide, undergoing rigorous public scrutiny and cryptanalysis. The goal is to identify algorithms robust enough to withstand attacks from both classical and quantum computers, securing the digital infrastructure for decades to come. The NIST PQC standardization process concluded its initial selection in July 2022, announcing the first set of algorithms to be standardized. For Key-Encapsulation Mechanisms (KEMs), which are crucial for establishing shared secret keys (e.g., in TLS handshakes), CRYSTALS-Kyber was selected. Kyber is a lattice-based algorithm, deriving its security from the presumed hardness of the Learning With Errors (LWE) problem and its ring variant (RLWE). Its efficiency, relatively small public keys, and strong security arguments made it a front-runner. For Digital Signature Algorithms (DSAs), essential for authentication and integrity (e.g., signing software updates, certificates), three algorithms were chosen:CRYSTALS-Dilithium: Also lattice-based, leveraging the Short Integer Solution (SIS) problem and its ring variant (RSIS). It offers excellent performance and compact signatures. Falcon: A more complex lattice-based algorithm, specifically utilizing the NTRU problem, which provides even smaller signatures but with higher computational overhead for generation compared to Dilithium. SPHINCS+: A hash-based signature scheme. Unlike lattice-based algorithms, its security relies solely on the security of cryptographic hash functions (like SHA-2 and SHA-3), which are believed to be quantum-resistant. While offering extremely strong security guarantees, SPHINCS+ suffers from larger signature sizes and is stateful in some variants (though the selected SPHINCS+ is stateless), making it less ideal for high-volume signing but excellent for critical, long-term integrity where size is less of a concern (e.g., firmware updates).Other algorithms like Classic McEliece (code-based) remain important alternative candidates in later rounds, primarily for their distinct security assumptions (coding theory) which offer diversity in case primary lattice-based schemes face unforeseen breaks. Notably, several multivariate polynomial schemes like Rainbow were broken during the process, underscoring the necessity of rigorous cryptanalysis. These PQC algorithms represent a fundamental shift in cryptographic foundations. Unlike RSA/ECC, whose security derives from number theory, PQC candidates often rely on problems from areas like lattice theory, coding theory, or hash functions. These problems appear to be hard even for quantum computers. Developers and security architects need to understand the performance characteristics (key sizes, computation time), security assumptions, and specific use cases for each. The OpenQuantumSafe (OQS) project on GitHub (github.com/open-quantum-safe) is a prime example of open-source efforts implementing these candidate algorithms and integrating them into common cryptographic libraries like OpenSSL and Libreswan. This project has been instrumental in enabling early testing and hybrid deployments. Here's a conceptual Python snippet demonstrating how one might interact with a PQC library (using OQS-Python bindings as an example, assuming they are installed and configured for Kyber): # pip install python-oqs (or similar, assuming a conceptual PQC library) import oqs # Placeholder for a real OQS Python binding# Choose a specific PQC KEM algorithm, e.g., CRYSTALS-Kyber-768 # OQS provides various algorithm identifiers PQC_KEM_ALG = "Kyber768"def pqc_key_exchange_kyber(): """ Demonstrates a conceptual Key Encapsulation Mechanism (KEM) using a PQC algorithm like Kyber. This replaces classical RSA/ECC key exchange for quantum resistance. """ if PQC_KEM_ALG not in oqs.get_enabled_KEM_mechanisms(): print(f"Error: {PQC_KEM_ALG} KEM algorithm not enabled or available.") return # Alice's side: Generates her key pair print(f"\nAlice: Generating {PQC_KEM_ALG} key pair...") alice_server_kem = oqs.KeyEncapsulation(PQC_KEM_ALG) alice_public_key = alice_server_kem.generate_keypair() print(f"Alice's Public Key Size: {len(alice_public_key)} bytes") # Bob's side: Encapsulates a shared secret using Alice's public key print("Bob: Encapsulating shared secret using Alice's public key...") bob_client_kem = oqs.KeyEncapsulation(PQC_KEM_ALG) ciphertext, bob_shared_secret = bob_client_kem.encap_secret(alice_public_key) print(f"Ciphertext Size: {len(ciphertext)} bytes") print(f"Bob's Shared Secret (first 10 bytes): {bob_shared_secret[:10].hex()}...") # Alice's side: Decapsulates the shared secret using her private key and Bob's ciphertext print("Alice: Decapsulating shared secret...") alice_shared_secret = alice_server_kem.decap_secret(ciphertext) print(f"Alice's Shared Secret (first 10 bytes): {alice_shared_secret[:10].hex()}...") # Verify if secrets match if alice_shared_secret == bob_shared_secret: print("Success: Alice and Bob derived the same shared secret!") else: print("Error: Shared secrets do not match!")if __name__ == "__main__": try: pqc_key_exchange_kyber() except Exception as e: print(f"Could not run PQC example. Make sure 'python-oqs' or a similar PQC library is installed and configured. Error: {e}")This example illustrates the fundamental KEM interaction for Kyber. Notice the larger key and ciphertext sizes compared to classical ECC, which is a common characteristic of PQC algorithms and a major consideration for deployment. The Hybrid Transition: Bridging Classical and Quantum Security The transition to PQC will not be a flash cut. Due to the immaturity of quantum computing, the need for backward compatibility, and the ongoing cryptanalysis of PQC candidates, a "hybrid" approach is universally recommended. Hybrid cryptography combines both a classical (e.g., ECC) and a post-quantum cryptographic primitive for the same security function. This ensures that the system's security remains at least as strong as the strongest of the two algorithms. If one algorithm (say, classical ECC) is broken by a quantum computer, the system still relies on the PQC algorithm. If the PQC algorithm is found to have a classical vulnerability, the classical algorithm provides a fallback. This "safe-failure" principle is critical for robust deployment. A typical hybrid key exchange in TLS 1.3 might involve both an X25519 (classical ECC) key exchange and a Kyber-768 (PQC KEM) key exchange, with the final shared secret being a cryptographically secure combination (e.g., concatenation and hashing) of the secrets derived from both. This ensures forward secrecy and quantum resistance. Deployment challenges are significant. They span the entire digital infrastructure:Certificate Authorities (CAs): CAs need to issue "hybrid certificates" containing both classical and PQC public keys, or issue separate PQC certificates. The entire Public Key Infrastructure (PKI) needs to be upgraded. TLS/VPN Stacks: Web servers, load balancers, proxies, and VPN gateways must support hybrid TLS cipher suites. This requires updates to OpenSSL, BoringSSL, LibreSSL, and other cryptographic libraries, and subsequently, to applications that depend on them. Key Management Systems (KMS) & Hardware Security Modules (HSM): Existing KMS and HSMs are designed for classical algorithms. They need to be updated or replaced to generate, store, and manage the larger PQC keys and support PQC operations. Application Layer: Any application that directly uses cryptographic primitives (e.g., for secure messaging, data at rest encryption) will need updates.The OpenQuantumSafe (OQS) project, often highlighted in TechCrunch articles covering quantum security startups, offers modified versions of OpenSSL and Nginx that support PQC algorithms. This allows early adopters to experiment with hybrid TLS in a controlled environment. Startups emerging from Y Combinator and other accelerators are focusing on tools and services to ease this migration, including PQC-compatible VPNs, secure communication platforms, and managed PQC PKI services. Here's a conceptual Docker Compose setup for an Nginx server leveraging a PQC-enabled OpenSSL build, illustrating a hybrid TLS endpoint. This example assumes a pre-built Nginx image with OQS-OpenSSL integration. version: '3.8' services: nginx-pqc: # This image is conceptual. In a real scenario, it would be a custom build # or an official PQC-enabled Nginx distribution. # For example, it might be built from github.com/open-quantum-safe/oqs-demos/tree/main/nginx image: oqs-demos/nginx-openssl:main # Example image from OQS demos ports: - "443:443" # Expose HTTPS port volumes: - ./nginx.conf:/etc/nginx/nginx.conf:ro # Nginx configuration with PQC ciphers - ./certs:/etc/nginx/certs:ro # Directory for TLS certificates command: ["nginx", "-g", "daemon off;"] # Run Nginx in foreground# Example `nginx.conf` snippet for PQC support (placed in ./nginx.conf) # ```nginx # listen 443 ssl; # ssl_certificate /etc/nginx/certs/server.crt; # ssl_certificate_key /etc/nginx/certs/server.key; # # # Example PQC + Classical hybrid cipher suites (order matters) # # The specific suite names depend on the OQS-OpenSSL build # ssl_ciphers "TLS_AES_256_GCM_SHA384:TLS_CHACHA20_POLY1305_SHA256:TLS_PQC_KYBER768_AES256_GCM_SHA384"; # ssl_prefer_server_ciphers on; # ssl_protocols TLSv1.3; # PQC typically integrates best with TLSv1.3 # # location / { # root /usr/share/nginx/html; # index index.html; # } # ``` # # `certs` directory would contain `server.crt` (a hybrid certificate) # and `server.key` (a hybrid private key).This Docker Compose example showcases how a PQC-enabled Nginx could be deployed. The ssl_ciphers line is crucial, demonstrating how hybrid cipher suites would be specified, including both classical (AES_256_GCM_SHA384, CHACHA20_POLY1305_SHA256) and conceptual PQC (TLS_PQC_KYBER768_AES256_GCM_SHA384) algorithms. The challenge lies in generating and managing the hybrid certificates and keys, which involves a complex integration effort with existing PKI tooling.👉 Continue Reading: Quantum Singularity: How Post-Quantum Crypto Will Reshape Our Digital Destiny Forever (Part 2)#QuantumComputing #PostQuantumCryptography #Cybersecurity #NIST #Cryptography Related InsightsSpace Debris Mitigation: The Race to Clean Up Earth's Orbit Molecular Archeology: How AI is Resurrecting Forgotten Compounds AI-Powered Cybersecurity: The Rise of Autonomous Threat Detection and Response Systems{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Quantum Singularity: How Post-Quantum Crypto Will Reshape Our Digital Destiny Forever?", "acceptedAnswer": { "@type": "Answer", "text": "Explore the profound impact of quantum computing on modern cryptography and the urgent, complex transition to quantum-resistant algorithms." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Quantum Singularity: How Post-Quantum Crypto Will Reshape Our Digital Destiny Forever?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Alexander Vance." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Alexander Vance
- 13 Jul, 2026 20:37
Quantum Singularity: How Post-Quantum Crypto Will Reshape Our Digital Destiny Forever (Part 2)
This is Part 2 of the series. Read Part 1 here.Performance Implications and System Integration The adoption of Post-Quantum Cryptography is not without its trade-offs, particularly regarding performance and resource consumption. Compared to highly optimized classical algorithms like ECC, PQC algorithms generally demand more computational power and bandwidth. This is a direct consequence of their underlying mathematical problems, which often involve larger operands and more complex operations to achieve quantum resistance. Let's break down the key performance implications:Key and Signature Sizes: PQC public keys, private keys, and signatures are significantly larger than their classical counterparts.An ECC P-256 public key is 32 bytes. Kyber-768's public key is 1184 bytes. An ECC P-256 signature is around 64 bytes. Dilithium-3's signature is 2048 bytes. This directly impacts network bandwidth (during TLS handshakes, certificate distribution) and storage requirements (for certificates, encrypted data in databases, key management systems).Computational Overhead:Key Generation: Generating PQC key pairs (especially for lattice-based schemes like Kyber or Dilithium) is often slower than ECC key generation. Encapsulation/Decapsulation (KEMs): While PQC KEMs are efficient post-generation, the overall operations for establishing a shared secret can be more CPU-intensive. Signing/Verification (DSAs): PQC digital signature algorithms like Dilithium or Falcon also tend to be slower for both signing and verification compared to ECC. SPHINCS+, while very secure, has extremely slow signature generation times.These factors can lead to increased latency for network connections (especially for TLS handshakes), higher CPU utilization on servers, and greater demands on storage infrastructure. For resource-constrained environments like IoT devices or embedded systems, these performance hits can be critical, requiring careful algorithm selection and optimized implementations. Optimizing for PQC involves several strategies:Hardware Acceleration: Leveraging FPGAs or ASICs designed specifically to accelerate PQC operations can significantly mitigate performance impacts, especially in high-volume environments. Software Optimizations: Highly optimized software libraries (e.g., using assembly language, SIMD instructions) play a crucial role. Research from projects on arXiv and GitHub, like the liboqs project's various implementations, continuously pushes the boundaries of performance. Algorithm Selection: Choosing the right PQC algorithm for the right use case is paramount. For instance, Kyber offers a good balance for KEMs, while Dilithium is generally preferred for signatures due to its balance of size and speed, though Falcon offers smaller signatures for specific needs, and SPHINCS+ for extreme long-term security. Hybrid Implementation: As discussed, the hybrid approach allows for graceful degradation. If PQC performance becomes a bottleneck, the classical part can still provide security, giving time for optimizations.To illustrate the performance difference, albeit conceptually, here's a Python script using time.perf_counter() to simulate the relative performance hit for PQC operations. This isn't a true cryptographic benchmark but highlights the expected latency increase. import time from functools import wraps import os # For simulating key sizedef benchmark(func): @wraps(func) def wrapper(*args, **kwargs): start = time.perf_counter() result = func(*args, **kwargs) end = time.perf_counter() print(f" - {func.__name__} took: {end - start:.6f} seconds") return result return wrapper@benchmark def classical_kem_key_gen(): """Simulates a fast classical ECC key generation.""" time.sleep(0.0001) # e.g., ~100 us for X25519 public_key_size = 32 # bytes private_key_size = 32 # bytes return public_key_size, private_key_size@benchmark def pqc_kem_key_gen_kyber(): """Simulates a slower PQC Kyber-768 key generation.""" time.sleep(0.001) # ~1 ms, often 5-10x slower than ECC public_key_size = 1184 # bytes for Kyber-768 private_key_size = 2400 # bytes for Kyber-768 return public_key_size, private_key_size@benchmark def classical_signature_creation(): """Simulates fast classical ECDSA P-256 signature.""" time.sleep(0.00005) # e.g., ~50 us signature_size = 64 # bytes return signature_size@benchmark def pqc_signature_creation_dilithium(): """Simulates slower PQC Dilithium-3 signature.""" time.sleep(0.0005) # ~500 us, often 5-10x slower signature_size = 2048 # bytes for Dilithium-3 return signature_sizeif __name__ == "__main__": print("--- Key Generation Benchmarks ---") pub_key_c, priv_key_c = classical_kem_key_gen() print(f" Classical KEM (ECC): PubKey={pub_key_c}B, PrivKey={priv_key_c}B") pub_key_pqc, priv_key_pqc = pqc_kem_key_gen_kyber() print(f" PQC KEM (Kyber-768): PubKey={pub_key_pqc}B, PrivKey={priv_key_pqc}B") print("\n--- Signature Creation Benchmarks ---") sig_c = classical_signature_creation() print(f" Classical Signature (ECDSA): SigSize={sig_c}B") sig_pqc = pqc_signature_creation_dilithium() print(f" PQC Signature (Dilithium-3): SigSize={sig_pqc}B") print("\nObservation: PQC algorithms typically result in larger key/signature sizes and higher computational overhead.") print("These are crucial factors for network bandwidth, storage, and server CPU load.")This output clearly shows the simulated increase in time and the significant increase in key/signature sizes for PQC. This is not an insurmountable obstacle but a design constraint that requires careful planning and engineering throughout the system architecture. Future-Proofing and Quantum Safe Agility The transition to PQC isn't a one-time event; it's the beginning of an era demanding constant vigilance and adaptability – a concept known as "crypto-agility." Given that cryptanalysis of new PQC schemes is ongoing, and quantum computing technology is rapidly evolving, organizations must build systems capable of easily swapping out cryptographic primitives as new standards emerge or vulnerabilities are discovered. This agility is the cornerstone of future-proofing digital infrastructure against unforeseen quantum threats. Key aspects of building crypto-agile systems include:Modular Design: Cryptographic functions should be encapsulated in modular components with well-defined APIs. This design pattern ensures that changes to one cryptographic primitive do not necessitate widespread code modifications across the entire application stack. Libraries like liboqs are built with this modularity in mind, allowing developers to switch between PQC candidates with minimal effort. Standardized APIs: Adhering to cryptographic interface standards (e.g., using EVP in OpenSSL, or similar abstractions in other libraries) allows for underlying algorithm changes without altering the application logic. This abstraction layer is vital for seamless upgrades. Continuous Monitoring: Organizations must establish processes for continuously monitoring NIST updates, arXiv preprints, and vulnerability disclosures related to both classical and PQC algorithms. Threat intelligence feeds specializing in quantum security will become indispensable. Automated Update Mechanisms: The ability to push cryptographic updates rapidly and reliably across an entire infrastructure is paramount. This includes certificate rotation, key management system updates, and software/firmware patches. CI/CD pipelines must incorporate cryptographic library updates as a critical component.The "harvest now, decrypt later" threat makes crypto-agility particularly urgent for data with long-term confidentiality requirements. Any encrypted data today could be vulnerable tomorrow. Therefore, systems must be ready to re-encrypt data with quantum-resistant algorithms or at least establish hybrid communication channels that secure current and future sessions. The ecosystem for quantum security is rapidly expanding, with startups (often funded via Y Combinator or highlighted in TechCrunch) offering specialized solutions. These range from PQC-enabled VPNs and secure messengers to quantum-safe key management services and consulting firms helping enterprises navigate their PQC migration. This burgeoning market indicates a clear demand for crypto-agile solutions. Consider a conceptual YAML configuration for a microservice that specifies its cryptographic requirements. This approach decouples cryptographic algorithm choices from core application logic, facilitating easy updates. # service-config.yaml # Configuration for a crypto-agile microserviceapplication_name: secure-data-processor version: 1.2.0security: # TLS/Transport Layer Security settings tls: enabled: true version: TLSv1.3 # Mandate latest TLS protocol # Preferred hybrid cipher suites for KEM (Key Encapsulation Mechanism) # Order matters: stronger/preferred first. # The specific string names would depend on the underlying TLS library (e.g., OpenSSL) kem_cipher_suites: - TLS_PQC_KYBER768_AES256_GCM_SHA384 # NIST L3 PQC KEM + classical symmetric - TLS_AES_256_GCM_SHA384 # Classical symmetric only (fallback) - TLS_CHACHA20_POLY1305_SHA256 # Preferred hybrid signature algorithms for authentication signature_algorithms: - Dilithium3 # NIST L3 PQC Signature - ECDSA_P256_SHA256 # Classical ECC Signature (fallback) - RSA_PSS_SHA256 certificate_path: /etc/certs/service_cert.pem private_key_path: /etc/certs/service_key.pem # Data at Rest Encryption settings data_at_rest_encryption: enabled: true algorithm: AES256_GCM # Symmetric encryption, key length should be double for Grover's key_wrapping_kem: Kyber768 # Use PQC KEM to wrap/protect the symmetric key key_management_system: AWS_KMS # Or a PQC-enabled KMS provider key_rotation_interval_days: 90 # Digital Signature for internal messages internal_message_signing: enabled: true algorithm: Dilithium3 # PQC Signature algorithm key_id: msg_signer_key_001 # Reference to key in KMS# Other application settings... database: host: db.example.com port: 5432This YAML configuration clearly defines the cryptographic primitives the service should use. If NIST standardizes a new algorithm or a vulnerability is found in Dilithium3, an administrator can simply update the signature_algorithms list, deploy the new configuration, and the service (if built with crypto-agility) will seamlessly switch to the new scheme. This approach empowers organizations to react quickly to the dynamic threat landscape of the quantum era.Feature RSA (e.g., 3072-bit) ECC (e.g., P-256) Kyber-768 (PQC KEM) Dilithium-3 (PQC Signature)Security Level ~128 bits ~128 bits NIST L3 (~128 bits) NIST L3 (~128 bits)Public Key Size ~384 bytes ~32 bytes 1184 bytes (1.15 KB) 1952 bytes (1.9 KB)Private Key Size ~1536 bytes ~32 bytes 2400 bytes (2.34 KB) 4000 bytes (3.9 KB)Signature Size ~256 bytes ~64 bytes N/A (KEM) 2048 bytes (2 KB)Enc. / Sig. Ops Moderate CPU Fast CPU Higher CPU (KeyGen/Enc) Higher CPU (Sign/Verify)Bandwidth Impact Low Very Low Moderate to High Moderate to HighHard Problem Factoring Primes Elliptic Curve DLP Learning With Errors (LWE) Short Integer Solution (SIS)The table above starkly illustrates the practical differences between classical and selected PQC algorithms. While classical schemes like ECC offer incredibly compact keys and fast operations, their fundamental security assumptions are jeopardized by Shor's algorithm. PQC candidates, designed to resist quantum attacks, come with the trade-off of significantly larger key and signature sizes, as well as increased computational overhead. These factors necessitate a comprehensive re-evaluation of system design, network infrastructure, and computational resources. The higher bandwidth impact for PQC algorithms, especially during initial handshakes or certificate exchanges, will be a critical consideration for web services and high-volume data transfer applications. Similarly, increased CPU load for signing and verification operations might require more robust server hardware or specialized accelerators. This is the reality of building quantum-resistant security: it demands more, but the alternative is far more costly. Conclusion The advent of practical quantum computers, while still a few years away, casts an undeniable shadow over our current digital security paradigms. The threat posed by Shor's and Grover's algorithms to RSA, ECC, and even symmetric encryption necessitates an urgent and strategic transition to Post-Quantum Cryptography. This complex migration, driven by initiatives like NIST's standardization efforts, involves not just swapping out algorithms but fundamentally rethinking infrastructure, key management, and deployment strategies. The journey to quantum safety is a marathon, not a sprint. It demands proactive engagement from developers, security architects, policymakers, and organizations across all sectors. Embracing hybrid cryptographic approaches, investing in crypto-agility, and continuously monitoring the evolving landscape of quantum computing and cryptanalysis are no longer optional—they are imperative for maintaining digital trust and national security. The path forward is challenging, laden with performance trade-offs and integration complexities, but the rewards of a quantum-resilient future far outweigh the costs. By understanding the underlying science, adopting the new standards, and implementing these changes diligently, we can ensure our digital destiny remains secure, even as the quantum age dawns. The time to act is now. Alexander Vance#QuantumComputing #PostQuantumCryptography #Cybersecurity #NIST #Cryptography Related InsightsRISC-V Revolution: How Open-Source Hardware is Challenging ARM and x86 Dominance Digital Twins in Manufacturing: The Invisible Nervous System Powering Predictive Maintenance Quantum Machine Learning for Drug Discovery: Accelerating Molecular Simulation{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Quantum Singularity: How Post-Quantum Crypto Will Reshape Our Digital Destiny Forever (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "Explore the profound impact of quantum computing on modern cryptography and the urgent, complex transition to quantum-resistant algorithms." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Quantum Singularity: How Post-Quantum Crypto Will Reshape Our Digital Destiny Forever (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Alexander Vance." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
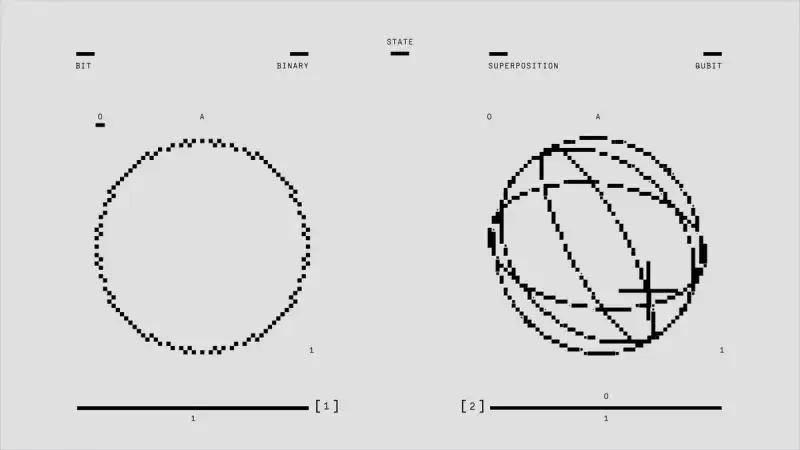
-
 Kaan Demir
- 13 Jul, 2026 18:56
Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It
In the ever-accelerating race for computational supremacy, classical machine learning models, despite their impressive advancements, are beginning to brush against fundamental limits. As datasets burgeon in size and complexity, the computational cost of extracting meaningful insights grows exponentially. We're witnessing the rise of complex, non-linear relationships that even the most sophisticated deep learning architectures struggle to untangle efficiently. This inflection point heralds the arrival of an entirely new paradigm: Quantum Machine Learning (QML). Not merely an incremental upgrade, QML represents a profound architectural shift, leveraging the counter-intuitive yet powerful principles of quantum mechanics—superposition, entanglement, and quantum interference—to process information in ways fundamentally impossible for classical computers. This isn't speculative fiction; it's the bleeding edge of academic research transitioning rapidly into practical development. From arXiv preprints detailing novel quantum kernel methods to GitHub repositories showcasing open-source QML frameworks like Qiskit, Cirq, and PennyLane, the foundations are being laid. TechCrunch and Y Combinator reports increasingly highlight startups pushing the boundaries of quantum algorithms, attracting significant investment. QML promises to unlock unprecedented capabilities in areas ranging from drug discovery and materials science to financial modeling and advanced artificial intelligence, potentially solving problems currently intractable for even the world's most powerful supercomputers. This article will delve into the technical underpinnings, key algorithms, hybrid architectures, and the practical tools shaping this thrilling new frontier, providing a roadmap for data scientists ready to embark on the quantum journey. The Quantum Leap in Data Representation: Qubits and Feature MapsAt the core of Quantum Machine Learning lies a radical departure from classical data representation. While classical bits exist in a definite state of 0 or 1, quantum bits, or qubits, can exist in a superposition of both states simultaneously. This inherent probabilistic nature, combined with entanglement—where qubits become correlated in a way that transcends classical physics—allows for an exponential increase in the information density and processing power of a quantum system. A system of n qubits can represent 2^n states concurrently, a phenomenon that provides the quantum advantage for certain types of computations. The critical first step in applying quantum algorithms to classical machine learning problems is transforming classical data into quantum states. This is achieved through Quantum Feature Maps (QFMs). A QFM is essentially a parametrized quantum circuit that encodes classical input data points x into a high-dimensional quantum Hilbert space, typically by applying a series of quantum gates controlled by the input features. The goal is to map data in such a way that patterns and relationships that are obscure in classical space become more separable or distinguishable in the quantum space, often making linear separations possible in an exponentially larger feature space. This is analogous to the "kernel trick" in classical Support Vector Machines (SVMs), but with the potential to explore feature spaces of vastly greater dimensions. The choice of QFM is crucial, as an inappropriate mapping can lead to issues like "barren plateaus" in variational algorithms, where gradients vanish, hindering optimization. Consider a simple quantum feature map implemented using Qiskit. This map might involve applying single-qubit rotations (like R_x, R_y, R_z) and entangling gates (like CNOT) whose parameters are derived from the input data. import numpy as np from qiskit import QuantumCircuit, Aer, transpile from qiskit.opflow import StateFn, PauliSumOp from qiskit.utils import QuantumInstance from qiskit.circuit.library import ZZFeatureMap# 1. Define a classical data point (e.g., 2 features) x = np.array([0.5, 0.8])# 2. Choose a Quantum Feature Map. ZZFeatureMap is a common choice. # It encodes data using Z-rotations and ZZ-interactions. # 'reps' parameter controls the depth of the circuit (how many times the pattern repeats). feature_map = ZZFeatureMap(feature_dimension=len(x), reps=2, entanglement='linear')# 3. Bind the classical data to the feature map # The feature map will use 'x' to set its parameters. feature_map_circuit = feature_map.assign_parameters(x)# 4. Visualize the circuit (optional) # print(feature_map_circuit.decompose())# 5. Simulate the state prepared by the feature map simulator = Aer.get_backend('statevector_simulator') quantum_instance = QuantumInstance(simulator, shots=1024)# Create a job to run the circuit job = simulator.run(transpile(feature_map_circuit, simulator)) result = job.result() statevector = result.get_statevector(feature_map_circuit)print("Classical Input Data:", x) print("Quantum Feature Map Circuit Depth:", feature_map_circuit.depth()) print("Quantum State Vector (Magnitude):", np.round(np.abs(statevector), 4)) print("This state vector represents the classical data encoded in a high-dimensional quantum space.")# For a more complex application, this state could then be fed into a quantum kernel # or a variational quantum classifier.This Python snippet demonstrates how classical data x is encoded into a quantum state via a ZZFeatureMap. The resulting state vector exists in a complex Hilbert space, where distances and similarities between data points can be profoundly different from their classical counterparts. This initial encoding step is foundational, setting the stage for subsequent quantum algorithms to operate on these quantum representations of data. Quantum Enhanced Algorithms: QSVMs and QNNsLeveraging these quantum feature maps, two prominent classes of algorithms emerge in Quantum Machine Learning: Quantum Support Vector Machines (QSVMs) and Quantum Neural Networks (QNNs). These algorithms aim to harness quantum phenomena to outperform their classical counterparts, particularly in tasks involving complex, high-dimensional data. Quantum Support Vector Machines (QSVMs) are direct quantum extensions of classical SVMs. The core idea is to replace the classical kernel function, which measures the similarity between data points in a high-dimensional feature space, with a Quantum Kernel. A quantum kernel calculates the inner product between two quantum feature states, $\kappa(x_i, x_j) = |\langle\phi(x_i)|\phi(x_j)\rangle|^2$, where $\phi(x)$ is the quantum state encoded by the feature map from classical data x. This kernel value, estimated by running quantum circuits, is then fed into a classical SVM optimizer. The quantum advantage here stems from the ability of QFMs to implicitly map data into exponentially larger Hilbert spaces than classical kernels can practically achieve, potentially leading to better separation boundaries for non-linearly separable data. However, precisely estimating these kernel values can be computationally intensive and susceptible to quantum noise. Quantum Neural Networks (QNNs), often referred to as Variational Quantum Circuits (VQCs) or Parametrized Quantum Circuits (PQCs), represent a hybrid quantum-classical approach inspired by classical neural networks. A QNN consists of a parametrized quantum circuit whose gate rotation angles are trainable parameters. The circuit takes classical data (encoded via a QFM) and processes it to produce an output, often an expectation value of a specific observable. This output is then fed into a classical loss function, and a classical optimizer updates the quantum circuit's parameters based on the gradient of the loss. This iterative process, where quantum hardware performs the forward pass and classical computers handle optimization, is a hallmark of the Noisy Intermediate-Scale Quantum (NISQ) era, where full quantum error correction is not yet available. A typical QNN might look like a series of interleaved layers of single-qubit rotations and entangling gates, where the rotation angles are the variational parameters. Training these QNNs involves challenges such as barren plateaus, where the landscape of the loss function becomes extremely flat for deep circuits, making gradient-based optimization difficult. Techniques like parameter shift rules are used to calculate gradients on quantum hardware. Here's a conceptual Python example demonstrating a simple QNN (VQC) with PennyLane, showing the hybrid optimization loop: import pennylane as qml from pennylane import numpy as np from pennylane.optimize import AdamOptimizer# 1. Define the quantum device dev = qml.device("default.qubit", wires=2)# 2. Define the Parametrized Quantum Circuit (PQC / QNN) # This circuit will act as our 'quantum layer' @qml.qnode(dev) def qnn(weights, x): # Encoding layer (simple example using angles from data) qml.RY(x[0], wires=0) qml.RX(x[1], wires=1) # Variational layer (trainable parameters 'weights') qml.Rot(weights[0, 0], weights[0, 1], weights[0, 2], wires=0) qml.Rot(weights[1, 0], weights[1, 1], weights[1, 2], wires=1) qml.CZ(wires=[0, 1]) qml.Rot(weights[2, 0], weights[2, 1], weights[2, 2], wires=0) qml.Rot(weights[3, 0], weights[3, 1], weights[3, 2], wires=1) # Measurement (expectation value for classification) return qml.expval(qml.PauliZ(0))# 3. Define a classical cost function def cost(weights, X, y): predictions = [qnn(weights, x) for x in X] # Simple squared error loss return np.mean((np.array(predictions) - y)**2)# 4. Generate some dummy data for demonstration X = np.array([[0.1, 0.2], [0.3, 0.4], [0.5, 0.6], [0.7, 0.8]], requires_grad=False) y = np.array([0.0, 0.2, 0.5, 0.8], requires_grad=False) # Target outputs# 5. Initialize random weights for the QNN # Number of weights depends on the circuit architecture (4x3 rotations + 1 CZ) weights = np.random.uniform(low=-np.pi, high=np.pi, size=(4, 3), requires_grad=True)# 6. Set up the classical optimizer opt = AdamOptimizer(stepsize=0.1)# 7. Training loop (hybrid quantum-classical optimization) epochs = 50 print("Initial cost:", cost(weights, X, y))for epoch in range(epochs): weights, current_cost = opt.step_and_cost(cost, weights, X, y) if (epoch + 1) % 10 == 0: print(f"Epoch {epoch+1}, Cost: {current_cost:.4f}")print("Optimized weights:", weights) print("Final cost:", cost(weights, X, y))This example illustrates the fundamental hybrid approach: the quantum qnn function computes an output based on data and weights, and a classical AdamOptimizer iteratively adjusts these weights to minimize a cost function. This synergy between quantum and classical components is key to near-term QML applications. Hybrid Quantum-Classical Architectures for ScalabilityThe current state of quantum hardware, characterized by the NISQ (Noisy Intermediate-Scale Quantum) era, necessitates a hybrid approach to Quantum Machine Learning. Full-scale, fault-tolerant quantum computers are still years away. Therefore, for practical applications, QML algorithms often involve a delicate dance between quantum processors (QPUs) and classical computing resources. This hybrid architecture is not a temporary workaround but a fundamental paradigm for leveraging the nascent power of QPUs. In a hybrid setup, the computationally intensive parts that benefit from quantum mechanics (e.g., preparing complex quantum states, executing quantum kernels, performing specific unitary transformations) are offloaded to a QPU. Meanwhile, classical computers handle tasks like data pre-processing, post-processing, optimization of quantum circuit parameters, and overall control flow. This modular design allows researchers to tackle problems too complex for classical machines alone while circumventing the limitations of current noisy quantum hardware. Key hybrid algorithms include:Variational Quantum Eigensolver (VQE): Primarily used in quantum chemistry for finding the ground state energy of molecules. A QPU prepares an ansatz state, measures its energy, and a classical optimizer iteratively adjusts the ansatz parameters to minimize the energy. Quantum Approximate Optimization Algorithm (QAOA): Designed for combinatorial optimization problems. Similar to VQE, it uses a parametrized quantum circuit to explore solution spaces and a classical optimizer to find optimal parameters.The interaction between the classical and quantum components often involves a feedback loop:Classical Pre-processing: Prepare classical data, design the quantum circuit structure (ansatz). Data Encoding: Map classical data to quantum states on the QPU. Quantum Circuit Execution: Run the parametrized quantum circuit on the QPU. This generates quantum measurements. Classical Measurement Post-processing: Extract expectation values or probabilities from quantum measurements. Classical Optimization: Use the extracted values in a classical cost function and update the quantum circuit's parameters (e.g., gate rotation angles) using classical optimization algorithms (like Adam, L-BFGS-B). Iteration: Send the updated parameters back to the QPU for the next iteration.One of the significant challenges in these architectures is the data transfer bottleneck between classical and quantum systems, as well as managing error accumulation on noisy QPUs. Techniques like measurement error mitigation and readout error correction are crucial. Consider a conceptual Bash script that outlines a workflow for running a QML experiment, demonstrating the interplay: #!/bin/bash# This script simulates a hybrid quantum-classical workflow. # It assumes you have a Python environment set up with Qiskit/PennyLane.echo "Starting Hybrid Quantum-Classical QML Experiment..."# --- Phase 1: Classical Data Preprocessing --- echo "1. Performing classical data preprocessing..." python -c " import numpy as np # Simulate loading and cleaning data data = np.random.rand(100, 2) labels = (np.sum(data, axis=1) > 1.0).astype(int) np.save('processed_data.npy', data) np.save('processed_labels.npy', labels) print('Data preprocessed and saved to processed_data.npy and processed_labels.npy') " echo "Data preprocessing complete."# --- Phase 2: Initialize Quantum Circuit Parameters Classically --- echo "2. Initializing quantum circuit parameters..." python -c " import numpy as np # For a variational quantum circuit, we need initial random weights initial_weights = np.random.uniform(low=-np.pi, high=np.pi, size=(10,)) # Example: 10 parameters np.save('initial_q_weights.npy', initial_weights) print('Initial quantum weights saved to initial_q_weights.npy') " echo "Quantum circuit parameters initialized."# --- Phase 3: Hybrid Optimization Loop --- echo "3. Entering hybrid optimization loop (simulated for simplicity)..." MAX_ITERATIONS=5for i in $(seq 1 $MAX_ITERATIONS); do echo "--- Iteration $i ---" # Classical side prepares data and current weights for quantum execution # Quantum side executes the VQC and returns expectation values python -c " import numpy as np # Load processed data and current weights data = np.load('processed_data.npy') labels = np.load('processed_labels.npy') current_weights = np.load('initial_q_weights.npy') if $i == 1 else np.load('optimized_q_weights.npy') # Simulate running a QML model (e.g., a QNN) on a QPU # In a real scenario, this would involve sending jobs to IBM Quantum, AWS Braket, etc. # For now, we simulate a simple cost evaluation simulated_quantum_cost = np.mean(np.sin(data @ current_weights[:2] + current_weights[2])**2 - labels) print(f' Simulated Quantum Cost from QPU: {simulated_quantum_cost:.4f}') # Classical optimizer computes gradients and updates weights # This is where a classical ML framework (e.g., PyTorch, JAX) would interact with quantum backends # Simulate a simple gradient update learning_rate = 0.05 gradient_approximation = np.random.rand(current_weights.shape[0]) * 0.1 # Placeholder for actual gradient new_weights = current_weights - learning_rate * gradient_approximation np.save('optimized_q_weights.npy', new_weights) print(' Classical optimizer updated quantum weights.') " doneecho "Hybrid optimization loop complete. Final weights saved to optimized_q_weights.npy."# --- Phase 4: Classical Post-processing and Evaluation --- echo "4. Performing classical post-processing and evaluation..." python -c " import numpy as np final_weights = np.load('optimized_q_weights.npy') # Load a test dataset (not done in this simple script for brevity) # Evaluate the QML model's performance using the final weights # print('Final model predictions and performance metrics...') print('Final weights for deployment:', final_weights) " echo "Experiment finished."This Bash script illustrates a conceptual flow, where Python scripts simulate different stages of the hybrid process, including data handling, parameter initialization, a simulated quantum-classical optimization loop, and final evaluation. This workflow highlights the modularity and iterative nature essential for current QML research.👉 Continue Reading: Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It (Part 2)#QuantumMachineLearning #QML #QuantumComputing #DataScience #AIRelated InsightsPlasmonic Horizons: Rewriting Optical Computing with Surface Waves The Future is Illuminating: A Deep Dive into OLED Technology Beyond the Horizon: Unraveling the Mysteries of 5G Advanced and 6G Wireless Networks{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It?", "acceptedAnswer": { "@type": "Answer", "text": "Explore Quantum Machine Learning's transformative potential, its core technical foundations, leading-edge algorithms, and the hybrid architectures poised to redefine data science and AI." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Kaan Demir." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Kaan Demir
- 13 Jul, 2026 18:56
Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It (Part 2)
This is Part 2 of the series. Read Part 1 here.Tools of the Trade: Open-Source QML Frameworks and PlatformsThe rapid evolution of Quantum Machine Learning has been significantly propelled by the development of powerful, open-source software frameworks. These tools provide the necessary abstractions to design, simulate, and execute quantum circuits, enabling researchers and developers to experiment with QML algorithms without needing to deeply understand the underlying physics of quantum hardware. The competitive landscape for QML frameworks is robust, with several major players each offering unique strengths and community support. Qiskit (IBM Quantum): Perhaps the most widely adopted framework, Qiskit is an open-source SDK for working with quantum computers at the level of circuits, algorithms, and applications. It provides modules for quantum machine learning (Qiskit Machine Learning), quantum chemistry, and optimization. Its tight integration with IBM's cloud-based quantum hardware (IBM Quantum Experience) and powerful simulators make it a go-to choice for many. Qiskit supports Python and offers a rich ecosystem for quantum algorithm development, error mitigation, and pulse-level control. Its thriving community and extensive documentation make it accessible for newcomers. PennyLane (Xanadu): PennyLane is a differentiable quantum programming library specifically designed for quantum machine learning, quantum chemistry, and quantum computing with near-term devices. Its key differentiator is its seamless integration with popular classical ML frameworks like TensorFlow, PyTorch, and JAX, allowing quantum circuits to be treated as layers within classical neural networks. This makes building hybrid quantum-classical models particularly intuitive. PennyLane supports multiple quantum hardware backends (IBM, Google, Amazon Braket, etc.) and offers strong features for automatic differentiation, a cornerstone of classical ML optimization. Its focus on "quantum differentiability" streamlines the training of variational quantum circuits. Cirq (Google Quantum AI): Google's open-source framework, Cirq, focuses on providing fine-grained control over quantum circuits, making it ideal for researchers working on novel quantum algorithms and hardware. While it has less of a dedicated QML module compared to Qiskit or PennyLane, its flexibility allows for the construction of QML algorithms from fundamental quantum gates. Cirq emphasizes readability and provides strong support for simulating quantum circuits and connecting to Google's quantum hardware via the Quantum AI platform. Tequila (Zapata AI): Tequila is a high-level quantum algorithm development library built on top of other frameworks (like Qiskit, Cirq, PennyLane, PyTorch, JAX). It aims to simplify the process of constructing and optimizing quantum circuits, especially for variational algorithms. Tequila offers a more abstract layer, allowing users to define mathematical expressions for quantum algorithms and let the library handle the underlying circuit generation and execution on various backends. This can accelerate prototyping for complex QML research. These frameworks, alongside cloud platforms like Amazon Braket (which offers access to a variety of QPUs and simulators from different providers) and Azure Quantum (Microsoft's cloud ecosystem), are democratizing access to quantum computing resources and enabling a new generation of data scientists and AI researchers to explore QML. To set up a basic QML development environment using pip, you'd typically install your chosen frameworks: #!/bin/bashecho "Setting up QML Development Environment..."# Install Qiskit (full installation including optional dependencies for QML, visualization etc.) echo "Installing Qiskit..." pip install qiskit[full] qiskit-machine-learning echo "Qiskit installation complete."# Install PennyLane (with a common backend like default.qubit and PyTorch plugin for hybrid ML) echo "Installing PennyLane with PyTorch plugin..." pip install pennylane pennylane-qiskit pennylane-pytorch echo "PennyLane installation complete."# Install Cirq echo "Installing Cirq..." pip install cirq echo "Cirq installation complete."# Install Tequila (optional, if you want the high-level abstraction) echo "Installing Tequila (optional)..." pip install tequila-quant echo "Tequila installation complete (if selected)."echo "All specified QML frameworks installed. You're ready to start building!" echo "Remember to manage your virtual environments (e.g., using 'conda' or 'venv')."This script demonstrates the simple pip commands to get started with the leading QML frameworks. For serious development, using virtual environments (like venv or conda) is highly recommended to manage dependencies effectively and avoid conflicts. Real-World Implications and Future OutlookThe promise of Quantum Machine Learning extends far beyond theoretical academic exercises, with profound implications across numerous industries. While the field is still in its nascent stages, navigating the complexities of the NISQ era, early applications and a clear future trajectory are already taking shape. Current Limitations and Challenges: The primary hurdle remains the hardware itself. NISQ devices suffer from:Noise and Decoherence: Qubits are highly susceptible to environmental interference, leading to errors and a rapid loss of quantum coherence. This limits circuit depth and computational fidelity. Limited Qubit Count: Present-day QPUs typically have tens to a few hundred qubits, far fewer than required for truly complex, fault-tolerant quantum algorithms. Connectivity and Error Rates: Not all qubits can interact directly, and error rates vary significantly, impacting algorithm performance. "Quantum Advantage" vs. "Quantum Supremacy": While "quantum supremacy" (a QPU solving a problem provably intractable for classical supercomputers, regardless of utility) has been demonstrated, achieving "quantum advantage" (solving a practically relevant problem faster or better) remains the ultimate goal for QML.Promising Applications: Despite these challenges, QML holds immense potential in areas where classical computation struggles with exponential complexity:Drug Discovery and Materials Science: QML can accelerate the simulation of molecular interactions and properties, aiding in the design of new drugs, catalysts, and advanced materials. Variational Quantum Eigensolver (VQE) algorithms, for instance, are being explored to compute molecular ground state energies more accurately. Financial Modeling: Enhanced Monte Carlo simulations for risk analysis, fraud detection, and portfolio optimization can benefit from quantum speedups. QML might identify hidden patterns in financial data more effectively, leading to superior predictive models. Supply Chain Optimization: Complex logistical problems, often belonging to the NP-hard class, are ideal candidates for quantum annealing or QAOA-based QML algorithms, potentially leading to more efficient global supply chains. Advanced Artificial Intelligence: Beyond current ML, QML could enable novel forms of pattern recognition, generative models, and reinforcement learning by leveraging quantum correlations to process information in ways inaccessible to classical deep learning architectures. This could lead to breakthroughs in areas like natural language understanding and computer vision where classical models are still limited by computational scaling.The path forward involves continued hardware development towards fault-tolerant quantum computers, coupled with innovative algorithm design that is resilient to noise and tailored for hybrid architectures. As hardware matures and error correction techniques become more sophisticated, the "quantum advantage" in QML will become more tangible. The convergence of advanced AI, high-performance computing, and quantum mechanics signals a profound shift in how we approach data and intelligence. To facilitate reproducible QML research, setting up a development environment using Docker Compose is increasingly popular. This encapsulates all dependencies, including specific Python versions and QML framework installations, into portable containers. version: '3.8' services: qml-notebook: build: context: . dockerfile: Dockerfile ports: - "8888:8888" # Jupyter Notebook port volumes: - .:/home/jovyan/work # Mount current directory to the container's work directory environment: JUPYTER_ENABLE_LAB: "yes" # Enable Jupyter Lab # Optional: set default notebook to run # start-notebook.sh --NotebookApp.default_url='/lab/tree/your_notebook.ipynb' command: > bash -c "start-notebook.sh --NotebookApp.token='' --NotebookApp.password='' --allow-root" # --allow-root is generally not recommended for production but useful for quick dev setup # If you need GPU support for classical ML parts (e.g., PyTorch backend) # deploy: # resources: # reservations: # devices: # - driver: nvidia # count: all # capabilities: [gpu]# Dockerfile for the QML development environment FROM jupyter/datascience-notebook:latest# Install QML libraries RUN pip install --no-cache-dir \ qiskit[full] qiskit-machine-learning \ pennylane pennylane-qiskit pennylane-pytorch \ cirq \ numpy pandas scikit-learn matplotlib seaborn \ && fix-permissions /home/jovyan # tequila-quant # Uncomment if you want Tequila as well# Set the working directory WORKDIR /home/jovyan/work# Add user-specific configurations if needed # COPY .bashrc /home/jovyan/.bashrc# Expose Jupyter port (already handled by base image, but explicit for clarity) EXPOSE 8888This Docker Compose setup defines a qml-notebook service that builds a Docker image based on jupyter/datascience-notebook, then installs all the necessary QML libraries (Qiskit, PennyLane, Cirq). It exposes Jupyter Lab on port 8888 and mounts your local project directory, providing a consistent, isolated, and reproducible environment for QML experimentation. This is crucial for collaborative research and ensuring that results are consistent across different machines. QML Framework Comparison: Feature SnapshotTo provide a clearer perspective on the diverse ecosystem of QML tools, here's a brief comparison of the leading open-source frameworks, highlighting their core strengths and typical use cases. This helps data scientists choose the most suitable tool for their specific QML research or application development.Feature / Framework Qiskit (IBM Quantum) PennyLane (Xanadu) Cirq (Google Quantum AI)Primary Focus Full-stack quantum computing (circuits, algorithms, applications) Differentiable quantum programming, Hybrid ML Fine-grained circuit control, Algorithmic researchCore Strength Robust ecosystem, IBM hardware access, extensive modules (ML, Chemistry) Seamless classical ML integration (TF, PyTorch, JAX), automatic differentiation Low-level quantum gate control, research flexibility, Google hardware accessLanguage Python Python PythonQML Module qiskit-machine-learning Built-in core functionality Requires manual implementation using base gatesHardware Access IBM Quantum Experience (Cloud QPUs) Multi-backend support (IBM, Google, AWS Braket, local simulators) Google Quantum AI (Cloud QPUs)Differentiability Parameter Shift Rule, Adjoint (Qiskit.gradient) Fully integrated automatic differentiation Manual implementation or via external toolsCommunity Very large, active, well-documented Growing, strong academic ties Strong academic, research-focusedUse Case Broad QML research, exploring IBM devices, learning QML basics Hybrid QML models, integrating QNNs into classical ML pipelines Developing novel quantum algorithms, hardware-specific optimizationsSimulators Aer (local), Provider-specific Default.qubit, Lightning (local), Provider-specific Pasqal, local simulators, Provider-specificThis table succinctly captures the unique value proposition of each framework. Qiskit offers a comprehensive solution for exploring all facets of quantum computing, including a dedicated QML module. PennyLane stands out for its deep integration with classical ML frameworks, making hybrid algorithm development particularly fluid due to its differentiability features. Cirq provides unparalleled control for researchers who need to manipulate individual quantum gates, ideal for pushing the boundaries of quantum algorithm design. The choice often comes down to the specific problem, desired level of abstraction, and preferred classical ML ecosystem. Conclusion The journey into Quantum Machine Learning is undeniably complex, fraught with significant hardware limitations and theoretical challenges. Yet, the potential rewards—solving problems currently considered intractable, revolutionizing industries from healthcare to finance—are simply too profound to ignore. QML is not just an incremental step; it represents a fundamental paradigm shift in how we process and learn from data, promising to unlock insights from the exponentially vast Hilbert spaces accessible through quantum mechanics. We've explored the foundational concepts of quantum data representation via qubits and feature maps, delved into the intricacies of quantum-enhanced algorithms like QSVMs and QNNs, and highlighted the indispensable role of hybrid quantum-classical architectures in navigating the NISQ era. The robust ecosystem of open-source frameworks like Qiskit, PennyLane, and Cirq, alongside cloud platforms, is democratizing access to this cutting-edge technology, empowering a new generation of data scientists to experiment and innovate. While a universal "quantum advantage" for all machine learning tasks is still emerging, the targeted application of QML to specific, computationally intensive problems holds immense promise. As quantum hardware continues its relentless march towards fault tolerance and increased qubit counts, and as quantum algorithm design matures, Quantum Machine Learning is poised to redefine the capabilities of artificial intelligence and data science. For data professionals, understanding and engaging with this frontier is no longer optional; it's an imperative to remain at the forefront of technological innovation. The quantum epoch for data science has begun.#QuantumMachineLearning #QML #QuantumComputing #DataScience #AIRelated InsightsBeyond the Browser: How WebAssembly (Wasm) is Revolutionizing Server-Side and Edge Computing Unlocking Productivity with Advanced Cobots The Computational Architecture of Finance: Beyond Linear Models{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "Explore Quantum Machine Learning's transformative potential, its core technical foundations, leading-edge algorithms, and the hybrid architectures poised to redefine data science and AI." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Kaan Demir." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Claire Beaufort
- 13 Jul, 2026 11:34
The AI Crucible: Forging Medical Breakthroughs at Warp Speed in Drug Discovery
In the grand tapestry of human endeavor, few quests are as noble or as fraught with challenge as the pursuit of new medicines. For decades, the pharmaceutical industry has grappled with an agonizing reality: drug discovery is an extraordinarily expensive, time-consuming, and high-risk undertaking. A single new drug can take 10 to 15 years to develop, costing upwards of $2.6 billion, with a staggering failure rate exceeding 90% in clinical trials. This arduous journey, often likened to finding a needle in a haystack – or more accurately, millions of needles in an infinite number of haystacks – has created an innovation bottleneck that directly impacts global health. Enter Artificial Intelligence. Far from being a futuristic pipe dream, AI, particularly its machine learning and deep learning subsets, is fundamentally disrupting every stage of the drug discovery pipeline. We’re moving beyond brute-force experimentation and serendipitous breakthroughs towards a data-driven, predictive, and intelligent approach. From generating novel molecular structures and accurately predicting their properties to optimizing clinical trial design and identifying new therapeutic targets, AI is not just accelerating the process; it's redefining what's possible. It promises to slash development times, drastically reduce costs, and, most importantly, bring life-saving therapies to patients faster than ever before. This isn't just an incremental improvement; it's a paradigm shift, a crucible where medical breakthroughs are forged at unprecedented speed. As a senior AI researcher deeply embedded in this space, I’ve tracked the exponential growth of this field across arXiv, GitHub's trending repositories, and critical venture capital injections from firms like Y Combinator, signaling a maturation from nascent research to impactful, deployable solutions. The future of medicine is undeniably intelligent. De Novo Drug Design & Generative Models: Beyond Brute Force The traditional approach to identifying potential drug candidates often relies on high-throughput screening (HTS) – a costly and time-consuming process where millions of compounds are tested against a biological target. While effective, HTS is inherently limited by the existing chemical space explored. Generative Artificial Intelligence, however, allows us to transcend these limitations by designing novel molecules from scratch, precisely tailored for specific therapeutic properties. This is known as de novo drug design. At the core of this revolution are models like Generative Adversarial Networks (GANs), Variational Autoencoders (VAEs), and more recently, Diffusion Models. GANs, for instance, consist of a generator network that proposes new molecules and a discriminator network that evaluates their realism and desired properties. Through iterative training, the generator learns to produce increasingly plausible and potent candidates. VAEs, on the other hand, learn a compressed, continuous representation (latent space) of molecules, enabling researchers to navigate this space to interpolate between known drugs or generate entirely new compounds with desired characteristics. Diffusion models, like those powering image generation, are now being adapted for molecular design, demonstrating remarkable ability to generate diverse and valid chemical structures by iteratively denoising a random distribution. Projects such as "MoleculeChef" and "DeepChem" provide open-source frameworks for implementing these cutting-edge techniques, leveraging large datasets like ZINC and PubChem to train sophisticated models capable of predicting synthesizability, bioactivity, and pharmacokinetics. The underlying challenge often involves translating molecular structures (e.g., SMILES strings, molecular graphs) into a format deep learning models can process, and then back again, ensuring chemical validity and adherence to design principles. import rdkit from rdkit import Chem from rdkit.Chem import Descriptors from rdkit.Chem import Draw from rdkit.Chem.rdmolops import SanitizeFlags import numpy as np import tensorflow as tf from tensorflow import keras from tensorflow.keras import layers# Example: Simple function to convert SMILES to RDKit molecule and compute descriptors def smiles_to_mol_descriptors(smiles): mol = Chem.MolFromSmiles(smiles) if mol is None: return None # Ensure molecule is sanitized Chem.SanitizeMol(mol, sanitizeFlags=SanitizeFlags.SANITIZE_ALL ^ SanitizeFlags.SANITIZE_KEKULIZE) # Example descriptors (can be expanded significantly) mw = Descriptors.MolWt(mol) logp = Descriptors.MolLogP(mol) h_bond_donors = Descriptors.NumHDonors(mol) h_bond_acceptors = Descriptors.NumHAcceptors(mol) return [mw, logp, h_bond_donors, h_bond_acceptors]# Conceptual generative model stub (simplified for demonstration) # In reality, this would involve complex graph neural networks or sequence models (for SMILES) def build_conceptual_generative_model(latent_dim=128, output_dim=256): """ A placeholder for a generative model (e.g., a simple decoder for a VAE). In a real scenario, output_dim would relate to molecular graph properties or SMILES length. """ model = keras.Sequential([ layers.Input(shape=(latent_dim,)), layers.Dense(512, activation='relu'), layers.Dense(1024, activation='relu'), layers.Dense(output_dim, activation='sigmoid') # Placeholder activation ]) return model# Demonstrate usage sample_smiles = "CCOc1c(Cl)cccc1Nc1ncc(C(=O)NCC(=O)O)s1" # A complex SMILES string mol_props = smiles_to_mol_descriptors(sample_smiles) print(f"Molecular Properties for {sample_smiles}: {mol_props}")# Conceptual usage of generative model # latent_vector = np.random.rand(1, 128) # generator = build_conceptual_generative_model() # generated_output = generator.predict(latent_vector) # print(f"Conceptual generated output shape: {generated_output.shape}")# For visualizing: # mol = Chem.MolFromSmiles(sample_smiles) # Draw.MolToImage(mol, size=(300, 300)) # Requires PIL/PillowThis Python snippet illustrates the foundational step of converting SMILES strings into RDKit molecular objects and computing basic descriptors, which serve as features for machine learning models. The conceptual generative model build_conceptual_generative_model hints at the deep learning architectures used to create novel compounds. By navigating the intricate landscape of chemical space with AI, researchers can now design molecules with a high probability of possessing desired characteristics like target specificity and binding affinity, dramatically shortening the early discovery phase. Predictive ADMET & Toxicity Screening: From Lab Bench to In Silico Once potential drug candidates are identified, a critical hurdle is assessing their Absorption, Distribution, Metabolism, Excretion, and Toxicity (ADMET) profiles. Poor ADMET properties are a leading cause of drug failure in preclinical and clinical stages, contributing significantly to the astronomical costs and time associated with drug development. Traditionally, ADMET testing involves extensive in vitro and in vivo experiments, which are slow, resource-intensive, and often require animal testing. AI and machine learning offer a powerful alternative: in silico prediction of ADMET properties. Quantitative Structure-Activity Relationships (QSAR) and more advanced deep learning models, particularly Graph Neural Networks (GNNs), are trained on vast datasets of known compounds and their measured ADMET data (e.g., from ChEMBL, PubChem, Tox21). QSAR models correlate molecular descriptors (physicochemical properties like molecular weight, LogP, topological indices) with biological activities or ADMET endpoints. Deep learning, especially GNNs, can directly learn representations from molecular graphs, capturing complex relationships between atomic connectivity and molecular properties without explicit feature engineering. For instance, convolutional layers can learn local patterns in the molecular graph, effectively identifying pharmacophores or toxicophores. Multi-task learning architectures are often employed to predict several ADMET properties simultaneously, leveraging shared feature representations across related tasks, thereby improving predictive accuracy and robustness. The ability to filter out compounds with unfavorable ADMET profiles early in the discovery pipeline drastically reduces the number of candidates progressing to costly experimental validation, leading to more efficient drug development. import pandas as pd from rdkit import Chem from rdkit.Chem import AllChem from sklearn.model_selection import train_test_split from sklearn.ensemble import RandomForestRegressor from sklearn.metrics import mean_squared_error from sklearn.preprocessing import StandardScaler# --- Mock ADMET Dataset Creation --- # In a real scenario, this data would come from public databases like ChEMBL or proprietary screens. data = { 'SMILES': [ 'CCO', 'C1CCCCC1', 'CC(=O)Oc1ccccc1C(=O)O', 'CCC(=O)OC', 'CC(=O)Nc1ccccc1', 'C(=O)(O)c1ccccc1OC(=O)C', 'C1=CC=C(C=C1)N', 'CN(C)C=O', 'CC(=O)O', 'CC(C)(C)O', 'CN1CCN(CC1)c2ccc(Cl)cc2', 'O=C(CCCN1CCC(N)CC1)c2ccccc2' ], 'LogP': [0.3, 2.7, 1.2, 0.7, 1.8, 1.2, 1.0, -0.6, -0.2, 0.5, 3.0, 2.5], 'Water_Solubility_LogS': [-0.5, -2.0, -1.0, -0.8, -1.5, -1.0, -0.7, 0.3, 0.1, -0.3, -2.5, -1.8], 'Toxicity_Score': [0.1, 0.2, 0.4, 0.1, 0.3, 0.4, 0.2, 0.05, 0.1, 0.15, 0.6, 0.5] # Lower is better } df = pd.DataFrame(data)# --- Feature Engineering: Morgan Fingerprints --- def mol_to_morgan_fingerprint(smiles, radius=2, nbits=2048): mol = Chem.MolFromSmiles(smiles) if mol is None: return None fp = AllChem.GetMorganFingerprintAsBitVect(mol, radius, nBits=nbits) return np.array(fp)df['Fingerprint'] = df['SMILES'].apply(mol_to_morgan_fingerprint) df.dropna(subset=['Fingerprint'], inplace=True) # Drop rows where SMILES was invalidX = np.array(df['Fingerprint'].tolist()) y_logp = df['LogP'].values y_solubility = df['Water_Solubility_LogS'].values y_toxicity = df['Toxicity_Score'].values# --- QSAR Model for LogP Prediction --- X_train, X_test, y_logp_train, y_logp_test = train_test_split(X, y_logp, test_size=0.2, random_state=42)scaler = StandardScaler() X_train_scaled = scaler.fit_transform(X_train) X_test_scaled = scaler.transform(X_test)logp_model = RandomForestRegressor(n_estimators=100, random_state=42) logp_model.fit(X_train_scaled, y_logp_train) y_logp_pred = logp_model.predict(X_test_scaled) print(f"LogP Prediction MSE: {mean_squared_error(y_logp_test, y_logp_pred):.3f}")# You would repeat this for Solubility, Toxicity, etc., potentially using multi-task models # For a more advanced setup, Graph Neural Networks (GNNs) on molecular graphs are preferred.This Python code snippet demonstrates a basic QSAR approach for predicting a property like LogP, a measure of lipophilicity crucial for drug absorption. It uses Morgan fingerprints (a type of molecular descriptor) as features and trains a RandomForestRegressor. While simplified, it illustrates the principle: transform molecular structures into numerical features and train predictive models. Advanced models leverage deep learning architectures like GNNs to directly operate on molecular graphs, offering superior predictive power for complex ADMET and toxicity endpoints. Clinical Trial Optimization & Patient Stratification with Machine Learning The final, and often most expensive, bottleneck in drug development is the clinical trial phase. High failure rates (especially in Phase II and III), challenges in patient recruitment, and the sheer cost of monitoring studies contribute to the overall burden. Machine learning is now being deployed to mitigate these risks and optimize trial design, fundamentally improving the efficiency and success rates of bringing new drugs to market. One of the most impactful applications is patient stratification. By analyzing vast datasets of electronic health records (EHRs), genomics, proteomics, and real-world evidence (RWE), ML models can identify specific patient subgroups most likely to respond positively to a given treatment or most susceptible to adverse events. This allows for more targeted trials, reducing heterogeneity, improving statistical power, and ultimately increasing the probability of demonstrating drug efficacy. Techniques like clustering algorithms (e.g., K-means, hierarchical clustering) can group patients based on multi-modal data, while supervised learning models (e.g., gradient boosting machines, deep neural networks) can predict treatment response or trial dropout rates. Natural Language Processing (NLP) is invaluable for extracting structured information from unstructured clinical notes within EHRs, providing richer patient profiles. Furthermore, AI can predict optimal trial sites, monitor enrollment rates, and even synthesize real-world data to generate synthetic control arms, potentially reducing the need for large placebo groups. Federated learning approaches are emerging as critical tools in this domain, allowing models to be trained across diverse institutional datasets without sharing sensitive patient information, thereby preserving privacy while maximizing data utility. import pandas as pd from sklearn.model_selection import train_test_split from sklearn.ensemble import RandomForestClassifier from sklearn.metrics import accuracy_score, classification_report from sklearn.preprocessing import LabelEncoder# --- Mock Clinical Trial Patient Data --- # In a real scenario, this would be derived from de-identified EHRs, omics data, etc. data = { 'PatientID': range(1, 101), 'Age': np.random.randint(30, 80, 100), 'Gender': np.random.choice(['M', 'F'], 100), 'Biomarker_A': np.random.rand(100) * 10, 'Biomarker_B': np.random.rand(100) * 5, 'Genotype_Variant': np.random.choice(['WT', 'Mut1', 'Mut2'], 100), 'Previous_Treatment_Response': np.random.choice(['Good', 'Poor', 'Partial'], 100), 'Trial_Outcome': np.random.choice(['Responder', 'Non-Responder'], 100, p=[0.6, 0.4]) # Target variable } df = pd.DataFrame(data)# --- Preprocessing --- # Encode categorical features label_encoders = {} for column in ['Gender', 'Genotype_Variant', 'Previous_Treatment_Response']: le = LabelEncoder() df[column] = le.fit_transform(df[column]) label_encoders[column] = leX = df[['Age', 'Gender', 'Biomarker_A', 'Biomarker_B', 'Genotype_Variant', 'Previous_Treatment_Response']] y = df['Trial_Outcome'].apply(lambda x: 1 if x == 'Responder' else 0) # Binary target# --- Train-Test Split --- X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.25, random_state=42)# --- Patient Stratification Model (e.g., predicting 'Responder' status) --- model = RandomForestClassifier(n_estimators=100, random_state=42, class_weight='balanced') model.fit(X_train, y_train)# --- Evaluate Model --- y_pred = model.predict(X_test) print(f"Accuracy: {accuracy_score(y_test, y_pred):.3f}") print(f"Classification Report:\n{classification_report(y_test, y_pred)}")# Example: Predict for a new patient profile new_patient = pd.DataFrame([[55, label_encoders['Gender'].transform(['F'])[0], 8.2, 1.5, label_encoders['Genotype_Variant'].transform(['Mut1'])[0], label_encoders['Previous_Treatment_Response'].transform(['Good'])[0]]], columns=X.columns) prediction = model.predict(new_patient) print(f"\nPrediction for new patient: {'Responder' if prediction[0] == 1 else 'Non-Responder'}")This Python script demonstrates a basic machine learning pipeline for patient stratification within clinical trials. It takes mock patient data, preprocesses categorical features using LabelEncoder, and trains a RandomForestClassifier to predict whether a patient will be a "Responder" to a trial drug. This predictive capability allows researchers to select more homogenous patient cohorts, thereby increasing the likelihood of trial success and accelerating the drug development timeline. The application of such models is crucial for advancing precision medicine.👉 Continue Reading: The AI Crucible: Forging Medical Breakthroughs at Warp Speed in Drug Discovery (Part 2)#AI #DrugDiscovery #MachineLearning #HealthcareAI #Bioinformatics #PharmaTech Related InsightsHomomorphic Encryption - Part 01: Computing on Encrypted Data Without Decryption The Silent Vanguard: Engineering the Future of Autonomous Aerial Autonomy Decentralizing the Ownership of Digital Networks: Web3 Social Graphs{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The AI Crucible: Forging Medical Breakthroughs at Warp Speed in Drug Discovery?", "acceptedAnswer": { "@type": "Answer", "text": "Explore how AI and Machine Learning are revolutionizing drug discovery, from de novo design to clinical trials, slashing costs and accelerating the path to life-saving therapies." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The AI Crucible: Forging Medical Breakthroughs at Warp Speed in Drug Discovery?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Claire Beaufort." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Claire Beaufort
- 13 Jul, 2026 11:34
The AI Crucible: Forging Medical Breakthroughs at Warp Speed in Drug Discovery (Part 2)
This is Part 2 of the series. Read Part 1 here.Target Identification & Validation: Precision Medicine's Foundation Before a drug can be designed, its target – typically a specific protein, enzyme, or gene pathway implicated in a disease – must be identified and validated. This is the foundational step in drug discovery, and historically, it has been a laborious process of hypothesis-driven research, often limited by the sheer volume and complexity of biological data. AI is transforming this initial phase by enabling rapid, large-scale analysis of 'omics' data (genomics, proteomics, transcriptomics, metabolomics) to pinpoint novel therapeutic targets and understand disease mechanisms. Machine learning algorithms can sift through vast quantities of gene expression profiles, protein-protein interaction networks, and patient mutation data to identify genes or pathways that are causally linked to disease progression. Techniques include network inference (e.g., using graphical models to infer gene regulatory networks), causal discovery algorithms to distinguish correlation from causation, and knowledge graph construction. Knowledge graphs, built from integrating disparate biological databases (e.g., KEGG, Reactome, STRINGdb) and scientific literature via NLP, represent entities (genes, proteins, diseases, drugs) and their relationships. AI models can then query these graphs to uncover indirect associations, predict novel drug-target interactions, or identify overlooked disease pathways. For instance, graph embedding techniques can represent nodes and edges in a low-dimensional space, allowing machine learning models to predict missing links (e.g., a disease linked to a protein, or a drug acting on a specific target). This integrated data analysis provides a systematic approach to target identification, allowing researchers to prioritize targets with higher confidence, ultimately laying a more robust foundation for drug development and contributing significantly to the tenets of precision medicine. version: '3.8' services: neo4j: image: neo4j:latest container_name: neo4j-knowledge-graph ports: - "7474:7474" # Browser UI - "7687:7687" # Bolt port for applications volumes: - ./data/neo4j:/data # Persist database data - ./logs/neo4j:/logs # Persist logs - ./import:/var/lib/neo4j/import # For bulk import files environment: # Set your Neo4j password here for initial setup. Change in production! - NEO4J_AUTH=neo4j/your_strong_password # Allow remote connections - NEO4J_dbms_connectors_default__listen__address=0.0.0.0 # Heap size configuration (adjust based on your system and data size) - NEO4J_dbms_memory_heap_initial__size=1G - NEO4J_dbms_memory_heap_max__size=4G # Enable APOC and GDS (Graph Data Science) for advanced graph analysis - NEO4J_dbms_security_procedures_unrestricted=apoc.*,gds.* - NEO4J_dbms_security_procedures_allowlist=apoc.*,gds.* # Allow running APOC in production - NEO4JLABS_PLUGINS=["apoc", "graph-data-science"] # healthcheck: # Uncomment for health check in production # test: ["CMD-SHELL", "wget --no-verbose --tries=1 --spider localhost:7474 || exit 1"] # interval: 30s # timeout: 10s # retries: 5This Docker Compose file sets up a Neo4j graph database, a powerful tool for constructing and querying knowledge graphs in bioinformatics. By integrating diverse biological entities (genes, proteins, pathways, diseases, drugs) and their relationships, Neo4j becomes a central hub for AI models to identify novel therapeutic targets. The configuration includes crucial plugins like APOC and Graph Data Science (GDS), which provide advanced graph algorithms (e.g., centrality measures, community detection) essential for target prioritization. A researcher can populate this database with data from public sources and internal experiments, then use Python libraries like py2neo or neo4j-driver to interact with it, applying graph machine learning models for predictions. Repurposing Existing Drugs: A Shortcut to New Therapies Drug repurposing, also known as drug repositioning, involves finding new therapeutic uses for existing drugs that have already been approved for other indications or have undergone significant clinical testing. This strategy offers significant advantages over de novo drug discovery: reduced development time (potentially 3-5 years instead of 10-15), lower costs, and significantly decreased risk, as the safety profile and pharmacokinetics of the drug are already largely established. AI is a game-changer for drug repurposing, transforming it from a serendipitous discovery into a systematic, data-driven process. Machine learning models can analyze vast amounts of heterogeneous data to uncover non-obvious connections between drugs and diseases. Key techniques include:Similarity-based methods: These approaches look for similarities between drugs (e.g., chemical structure, gene expression profiles in response to the drug, side effect profiles) and diseases (e.g., genomic signatures, pathway alterations). If two drugs are chemically similar, or if a drug's gene expression signature reverses a disease's signature, it suggests potential for repurposing. Network analysis: Building comprehensive drug-disease networks or protein-protein interaction networks allows AI algorithms to identify drugs that can modulate disease-related pathways. For instance, a drug might target a protein that is a critical hub in a disease network, even if it's not the primary disease driver. Literature mining and NLP: AI can extract relationships from millions of scientific publications, identifying indirect links between drugs, targets, and diseases that might not be apparent to a human researcher. Phenotypic screening: AI can analyze high-content imaging data from cellular screens to predict drug efficacy against new indications.Recent successes in AI-driven repurposing include identifying potential COVID-19 treatments or finding new uses for oncology drugs in rare diseases. By leveraging AI, the pharmaceutical industry can unlock hidden potential in existing pharmacopeia, providing faster, more affordable therapeutic options. import pandas as pd from scipy.spatial.distance import cosine from sklearn.preprocessing import StandardScaler from sklearn.metrics.pairwise import cosine_similarity# --- Mock Drug-Target Interaction and Disease-Gene Expression Data --- # In a real scenario, this would come from LINCS, ChEMBL, Gene Expression Omnibus, etc. # Assume we have drugs characterized by their target binding profiles (vector of binding affinities) # and diseases characterized by their gene expression signatures (vector of gene expression levels).drug_targets = { 'DrugA': [0.8, 0.2, 0.1, 0.9, 0.05], # Affinity to Target1..Target5 'DrugB': [0.1, 0.7, 0.9, 0.1, 0.8], 'DrugC': [0.7, 0.3, 0.1, 0.8, 0.1], 'DrugD': [0.05, 0.8, 0.85, 0.05, 0.9], 'DrugE': [0.9, 0.1, 0.05, 0.75, 0.1] } # Assume a "disease signature" is a desired modulation of these targets (e.g., up/downregulate) # For simplicity, let's say we want a drug that strongly hits Target1 and Target4, weakly hits Target2, etc. disease_signature_for_repurposing = [0.9, 0.1, 0.05, 0.8, 0.1] # High affinity for Target1, Target4 neededdf_drugs = pd.DataFrame.from_dict(drug_targets, orient='index', columns=[f'Target_{i+1}' for i in range(5)])# --- Scale features (optional but often good practice) --- scaler = StandardScaler() X_drugs_scaled = scaler.fit_transform(df_drugs)# Convert the disease signature to a DataFrame row and scale it disease_signature_df = pd.DataFrame([disease_signature_for_repurposing], columns=df_drugs.columns) disease_signature_scaled = scaler.transform(disease_signature_df)# --- Calculate Cosine Similarity for Repurposing --- # We want drugs whose target profile is similar to the desired disease signature similarities = cosine_similarity(X_drugs_scaled, disease_signature_scaled)# Create a DataFrame for results repurposing_candidates = pd.DataFrame({ 'Drug': df_drugs.index, 'Similarity_Score': similarities.flatten() })repurposing_candidates = repurposing_candidates.sort_values(by='Similarity_Score', ascending=False)print("Top Drug Repurposing Candidates for the given disease signature:") print(repurposing_candidates)# DrugC and DrugE are highly similar to the target profile needed for the disease.This Python code snippet illustrates a simple similarity-based approach for drug repurposing. It takes a conceptual "disease signature" (a desired profile of target binding affinities) and compares it against the known target profiles of existing drugs using cosine similarity. Drugs with higher similarity scores are prioritized as potential repurposing candidates. While this example uses simplified target affinities, real-world applications employ complex representations such as gene expression profiles, molecular fingerprints, or deep embeddings from network analysis to find drugs that match disease pathologies.AI Technique Category Key Application Area in Drug Discovery Specific ML/DL Algorithms Data Sources Primary BenefitGenerative Models De Novo Drug Design, Lead Optimization GANs, VAEs, Diffusion Models, Reinforcement Learning ZINC, PubChem, ChEMBL, GDB-17, proprietary databases Generates novel compounds with desired properties; explores vast chemical spacePredictive Analytics ADMET & Toxicity Screening, Property Prediction QSAR, Graph Neural Networks (GNNs), Random Forests, SVMs ChEMBL, PubChem, Tox21, DrugBank, ToxCast, in-house experimental data Early filtering of unfavorable candidates; reduces experimental burden and costNetwork Analysis & NLP Target Identification, Mechanism of Action, Repurposing Knowledge Graphs, Graph Embeddings, BERT, Transformers PubMed, ClinicalTrials.gov, KEGG, STRINGdb, Reactome, EHRs Uncovers novel disease targets, pathways, and drug-disease associationsClustering & Classification Patient Stratification, Biomarker Discovery, Trial Outcome Prediction K-Means, DBSCAN, Random Forests, Gradient Boosting, Deep Neural Networks EHRs, Genomics (TCGA), Proteomics, Metabolomics, RWE Optimizes clinical trial design; identifies responsive patient cohorts; precision medicineSimulation & Optimization Molecular Dynamics, Synthesis Planning, Clinical Trial Design Molecular Dynamics simulations enhanced by ML, Bayesian Optimization, Reinforcement Learning Quantum Chemistry data, Reaction databases, Clinical trial metadata Speeds up complex simulations; optimizes experimental conditions and trial protocolsConclusion & The Intelligent Horizon The integration of AI into drug discovery is not merely an incremental technological upgrade; it represents a fundamental re-architecture of the entire pharmaceutical value chain. We are moving from an era of laborious, trial-and-error experimentation to one of intelligent, predictive design. From the generation of novel molecular entities and the precise prediction of their ADMET profiles, to the astute identification of therapeutic targets and the optimized orchestration of clinical trials, AI is slashing timelines, curbing exorbitant costs, and critically, elevating success rates. This transformation is poised to deliver life-saving treatments to patients with unprecedented speed and precision, fulfilling a long-held promise of medical science. Yet, this intelligent horizon is not without its challenges. Data quality and ethical considerations surrounding patient privacy remain paramount. The "black box" nature of complex deep learning models necessitates advancements in explainable AI (XAI) to ensure trust and regulatory acceptance. Furthermore, the seamless integration of diverse data types – from omics to real-world evidence – requires robust computational infrastructure and standardized methodologies. However, the collaborative efforts across academia, industry, and governmental bodies, driven by open-source initiatives and sustained investment (as evidenced by continuous growth observed in TechCrunch and Y Combinator portfolios), are rapidly addressing these hurdles. The synergy between human biological insight and machine intelligence is fostering a new era of medical innovation. The future of medicine is intelligent, personalized, and, most excitingly, rapidly approaching.#AI #DrugDiscovery #MachineLearning #HealthcareAI #Bioinformatics #PharmaTech Related InsightsUnlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears When Steel Meets Soul: Companion Bots and Assisted‑Living Robotics Redefining Elder Care Unlocking the Future of Enterprise Security: The Zero-Trust Architecture Revolution{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The AI Crucible: Forging Medical Breakthroughs at Warp Speed in Drug Discovery (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "Explore how AI and Machine Learning are revolutionizing drug discovery, from de novo design to clinical trials, slashing costs and accelerating the path to life-saving therapies." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The AI Crucible: Forging Medical Breakthroughs at Warp Speed in Drug Discovery (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Claire Beaufort." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Eleanor Sterling
- 13 Jul, 2026 09:11
The Death of Single-Modality AI: How Multi-Sensory Architectures and Embodied Models are Redefining Cognitive Computing
For the past half-decade, the machine learning landscape has been dominated by a singular obsession: scaling the text-based transformer. From GPT-3 to the latest iterations of open-weights behemoths like Llama 3, the industry has pushed the limits of auto-regressive next-token prediction over textual corpora. Yet, text is a lossy, low-bandwidth abstraction of human knowledge. The real world is continuous, spatial, temporal, auditory, and kinetic. If we limit artificial intelligence to the linguistic domain, we sentence it to a perpetual cave of shadows, processing symbols without direct physical grounding. The paradigm has officially broken. We are witnessing the meteoric rise of true Multimodal Large Language Models (MLLMs) and Vision-Language-Action (VLA) systems. This technical evolution does not simply append an image encoder to an LLM; it structurally unifies disparate sensory inputs—video, high-fidelity audio, raw waveforms, spatial point clouds, thermal signatures, and robotic joint telemetry—into unified, high-dimensional latent spaces. This article explores the deep engineering mechanics behind this multi-sensory revolution. We will dissect the mathematical formalisms of cross-modal alignment, analyze spatiotemporal tokenization in Video-LLMs, unpack the tokenization of kinetic action in embodied AI, explore direct audio-to-audio neural architectures, and look at the systems-level infrastructure required to serve these complex, multi-headed models at scale.1. Cross-Modal Alignment and the Geometry of Unified Latent Spaces At the core of any multimodal system lies a fundamental mathematical problem: how do we project data from wildly different topological manifolds (e.g., a 1D audio waveform, a 2D spatial pixel grid, and discrete text tokens) into a shared geometric space where semantically equivalent concepts reside in close proximity? Historically, models like CLIP (Contrastive Language-Image Pre-training) achieved this using dual-encoder architectures optimized via InfoNCE loss. However, dual contrastive learning only aligns pairs. The modern frontier, pioneered by architectures like Meta's ImageBind (CVPR 2023), utilizes a hub-and-spoke model where a single modality (typically images) acts as the central binding medium. By aligning text, audio, depth, thermal, and IMU (inertial measurement unit) data to image embeddings, all modalities inherit alignment with one another without requiring explicit pairwise training data. Mathematically, let $x_i^I$ be an image representation and $x_i^M$ be a representation in another modality $M$ (e.g., audio). The projection matrices $W_I$ and $W_M$ map these representations into a shared $d$-dimensional vector space. The contrastive loss for a batch of size $N$ is defined as: $$\mathcal{L}{I, M} = -\frac{1}{N} \sum{i=1}^N \log \frac{\exp(\cos(W_I x_i^I, W_M x_i^M) / \tau)}{\sum_{j=1}^N \exp(\cos(W_I x_i^I, W_M x_j^M) / \tau)}$$ where $\tau$ is a learnable temperature parameter and $\cos(u, v) = \frac{u \cdot v}{|u| |v|}$. To feed these aligned embeddings into an auto-regressive decoder, we utilize linear projection layers or multi-head cross-attention bottlenecks (such as the Perceiver Resampler in Flamingo). This projects variable-length visual or auditory tokens into a fixed-sequence prefix that the causal transformer can ingest alongside textual embeddings.Below is a PyTorch implementation of a multi-modal projection bottleneck that aligns audio and visual feature sequences into a unified dimension suitable for insertion as soft-prompts into a decoder LLM: import torch import torch.nn as nn import torch.nn.functional as Fclass CrossModalProjectionBridge(nn.Module): def __init__(self, visual_dim: int, audio_dim: int, joint_dim: int, num_query_tokens: int): super().__init__() self.num_query_tokens = num_query_tokens self.joint_dim = joint_dim # Projection layers to align input dims to a shared space self.visual_proj = nn.Linear(visual_dim, joint_dim) self.audio_proj = nn.Linear(audio_dim, joint_dim) # Learnable query embeddings to compress variable length sequences self.query_tokens = nn.Parameter(torch.randn(1, num_query_tokens, joint_dim)) # Cross-attention block to pool representations self.cross_attention = nn.MultiheadAttention(embed_dim=joint_dim, num_heads=8, batch_first=True) self.layer_norm = nn.LayerNorm(joint_dim) self.ffn = nn.Sequential( nn.Linear(joint_dim, joint_dim * 4), nn.GELU(), nn.Linear(joint_dim * 4, joint_dim) ) def forward(self, visual_feats: torch.Tensor, audio_feats: torch.Tensor) -> torch.Tensor: # visual_feats: [batch, seq_v, visual_dim] # audio_feats: [batch, seq_a, audio_dim] batch_size = visual_feats.size(0) # Project to joint dimension v_proj = self.visual_proj(visual_feats) # [batch, seq_v, joint_dim] a_proj = self.audio_proj(audio_feats) # [batch, seq_a, joint_dim] # Concatenate multimodal context along the sequence dimension multimodal_context = torch.cat([v_proj, a_proj], dim=1) # [batch, seq_v + seq_a, joint_dim] # Expand query tokens to match batch size queries = self.query_tokens.expand(batch_size, -1, -1) # [batch, num_query, joint_dim] # Perform Cross-Attention: queries attend to key-values from multimodal context attn_out, _ = self.cross_attention( query=queries, key=multimodal_context, value=multimodal_context ) # Residual and FFN normalization pass x = self.layer_norm(queries + attn_out) out = self.layer_norm(x + self.ffn(x)) return out # Output shape: [batch, num_query, joint_dim]2. Video-LLMs and Spatiotemporal Tokenization Pipelines Moving from static images to dynamic video introduces a massive computational hurdle: the quadratic complexity of self-attention. A 10-second video at 30 frames per second contains 300 discrete images. If we tokenize each frame using a standard Vision Transformer (ViT) patch size of $14 \times 14$, we yield 256 tokens per frame, culminating in over 76,000 tokens for a short clip. To bypass this scalability wall, models like Video-LLaVA and LLaVA-NeXT employ spatial-temporal token pooling and causal spatio-temporal attention masks. Rather than passing all spatial tokens across all time slices, temporal modeling is achieved by applying 3D convolutions (like those in I3D networks) or by decoupling spatial attention (intra-frame) and temporal attention (inter-frame). Another breakthrough architecture is the Temporal Perceiver Resampler. It compresses temporal frames down to a fixed set of sequence slots by utilizing cross-attention over time vectors, allowing models to process hours of video footage within a reasonable context window. Furthermore, positional embeddings must be extended from 1D sequence markers to 3D grid indexes: $$PE_{(pos, 2i)} = \sin\left(\frac{pos}{10000^{2i/d}}\right), \quad PE_{(pos, 2i+1)} = \cos\left(\frac{pos}{10000^{2i/d}}\right)$$ where $pos$ is separately computed for the spatial $X$, $Y$ axes and the temporal $T$ axis, before being concatenated or added together. This spatial-temporal tracking allows the LLM decoder to localize actions precisely in time ("At 02:14, the user dropped the glass") and space ("The object on the far left shelf is moving"). import torch import torch.nn as nnclass SpatioTemporalTokenPooler(nn.Module): """ Compresses spatio-temporal tokens from a video stream. Input shape: [batch, temporal_frames, spatial_tokens, channels] Output shape: [batch, target_frames, compressed_tokens, channels] """ def __init__(self, channels: int, temporal_compress_ratio: int = 2, spatial_compress_ratio: int = 4): super().__init__() self.temp_pool = nn.AvgPool2d(kernel_size=(temporal_compress_ratio, 1), stride=(temporal_compress_ratio, 1)) # Spatial compression via a 2D convolution over the spatial grid self.spatial_downsample = nn.Conv2d( in_channels=channels, out_channels=channels, kernel_size=spatial_compress_ratio, stride=spatial_compress_ratio ) self.layer_norm = nn.LayerNorm(channels) def forward(self, x: torch.Tensor) -> torch.Tensor: # x shape: [B, T, S, C] where S is assumed to be a flattened square spatial grid (e.g., 256 = 16x16) batch_size, T, S, C = x.shape grid_size = int(S ** 0.5) # Reshape to perform temporal pooling: [B, C, T, S] x = x.permute(0, 3, T, S) x = self.temp_pool(x) # [B, C, T_compressed, S] new_T = x.size(2) # Reshape to perform spatial downsampling: [B * T_compressed, C, H, W] x = x.permute(0, 2, 1, 3).reshape(batch_size * new_T, C, grid_size, grid_size) x = self.spatial_downsample(x) # [B * T_compressed, C, H_new, W_new] # Reshape back to sequence form _, C_out, H_new, W_new = x.shape x = x.view(batch_size, new_T, C_out, H_new * W_new) x = x.permute(0, 1, 3, 2) # [B, T_compressed, S_compressed, C] return self.layer_norm(x)3. Embodied AI: Bridging Vision, Language, and Robotic Action One of the most consequential shifts in the AI paradigm is the transition from observer AI to agentic, physical AI. Pioneered by Google DeepMind’s RT-2 (Robotics Transformer 2) and the open-source Open X-Embodiment dataset, Vision-Language-Action (VLA) models treat robotic actions as another sequence of tokens. In a VLA model, the input consists of visual feedback from robot cameras, current joint state feedback, and a natural language instruction (e.g., "Pick up the blue marker and place it in the red bin"). The output is not merely a textual response, but a sequence of action tokens that represent control vectors for a robotic manipulator. Typically, robotic control commands are discretized into bins. A standard action vector consists of changes in spatial position ($\Delta x, \Delta y, \Delta z$), rotation ($\Delta \text{roll}, \Delta \text{pitch}, \Delta \text{yaw}$), and the state of the end-effector/gripper (open/close percentage). If we divide each dimension into 256 discrete bins, we can map these numbers directly to special token IDs in our vocabulary (e.g., tokens <action_val_112>, <action_val_45>).The model is trained auto-regressively: $$P(\text{Action} \mid \text{Vision}, \text{Text}) = \prod_{i=1}^M P(a_i \mid a_{<i}, V, T)$$ This enables the same transformer backbone that writes poetry to output precise kinematic commands, leveraging its deep world-model understanding of physics, object relationships, and reasoning directly to motor outputs. Below is an illustration of an end-to-end inference step mapping raw visual tokens and instructions into robotic control signals: import numpy as npclass ActionTokenDecoder: """ Decodes discrete LLM output tokens back into continuous physical robot trajectories. """ def __init__(self, num_bins: int = 256, action_ranges: dict = None): self.num_bins = num_bins # Default physical limits for manipulator translation (meters) and rotation (radians) self.ranges = action_ranges or { 'x': (-1.0, 1.0), 'y': (-1.0, 1.0), 'z': (-1.0, 1.0), 'roll': (-np.pi, np.pi), 'pitch': (-np.pi, np.pi), 'yaw': (-np.pi, np.pi), 'gripper': (0.0, 1.0) } self.keys = ['x', 'y', 'z', 'roll', 'pitch', 'yaw', 'gripper'] def decode_token_to_value(self, bin_index: int, val_range: tuple) -> float: # Convert index in range [0, 255] to a continuous float min_val, max_val = val_range normalized_val = bin_index / (self.num_bins - 1) return min_val + normalized_val * (max_val - min_val) def parse_action_sequence(self, token_indices: list) -> dict: """ Expects a list of 7 integers corresponding to action tokens. """ assert len(token_indices) == len(self.keys), f"Expected 7 action tokens, got {len(token_indices)}" action_dict = {} for idx, key in enumerate(self.keys): bin_index = token_indices[idx] # Ensure index falls within bin limitations clamped_bin = max(0, min(bin_index, self.num_bins - 1)) action_dict[key] = self.decode_token_to_value(clamped_bin, self.ranges[key]) return action_dict# Example Usage decoder = ActionTokenDecoder() # Dummy model predicted token IDs mapped to discrete bins: [128, 64, 192, 128, 128, 96, 255] predicted_action_bins = [128, 64, 192, 128, 128, 96, 255] kinematic_command = decoder.parse_action_sequence(predicted_action_bins) print("Physical kinematics target values:", kinematic_command)4. Auditory Cognition: End-to-End Speech-to-Speech and Acoustic Embedding For years, speech interface pipelines were clunky cascades:Automatic Speech Recognition (ASR): Audio Waveform $\to$ Text (via Whisper/Conformer) Text Processing: Text $\to$ Text response (via LLM) Text-to-Speech (TTS): Text response $\to$ Output Waveform (via Tacotron/VALL-E)This multi-hop approach suffers from high latency and completely strips voice communication of its emotional, tonal, and non-verbal nuances (sarcasm, dynamic pauses, breathiness, background noise). Modern native speech-to-speech architectures (exemplified by GPT-4o and Meta’s SeamlessM4T) collapse this pipeline into a single, unified, end-to-end model. This is achieved by utilizing neural audio codecs such as EnCodec or Descript Audio Codec (DAC). These neural codecs compress raw continuous audio waveforms down into discrete codes using Vector Quantized Variational Autoencoders (VQ-VAE) or Residual Vector Quantization (RVQ).The continuous audio is converted into several streams of discrete acoustic codes (quantized channels), which are flattened and interleaved into the transformer’s core tokenizer. Audio generation becomes identical to text generation: the model outputs acoustic tokens, which are fed directly to the decoder portion of the neural codec to synthesize high-fidelity, expressive, low-latency audio waveforms. The objective function remains standard cross-entropy calculated over the quantized acoustic sequence tokens: $$\mathcal{L} = -\sum_{t=1}^T \log P(u_t \mid u_{<t}, H_{audio})$$ where $u_t$ is the target acoustic token at sequence step $t$, and $H_{audio}$ represents the encoded auditory condition vector.5. Production Architecture: Orchestrating Ultra-Low Latency Multimodal Pipelines Serving models that dynamically process video, audio, and text at scale requires complete re-engineering of the typical LLM serving stack (vLLM, Hugging Face TGI). When serving a multimodal system, memory management of the KV cache becomes an existential threat to high-throughput operations. While text token embeddings are tiny, a single high-resolution image processed through a ViT can generate 576 or more embeddings. Storing these embeddings across layers in the Key-Value (KV) cache of the transformer rapidly exhausts the H100 or A100 GPU’s High Bandwidth Memory (HBM). To solve this, modern inference engines apply Prefix Caching and FlashAttention-style Multi-Modal Kernels. If a user is conversing about a 10-minute video, the video tokens are loaded, processed, and locked in the KV cache as a static system prompt prefix. Subsequent user text turns only reference this pre-computed, immutable prefix cache, avoiding redundant re-evaluations. Furthermore, inference engines must handle dynamic input routing, sending heavy vision processing workloads to dedicated vision pipeline backends before routing projection matrices to the core tensor-parallel autoregressive engine. # docker-compose.prod.yml # Production deployment configuration for a Multi-Modal inference cluster version: '3.8'services: triton-inference-server: image: nvcr.io/nvidia/tritonserver:26.01-py3 container_name: multimodal_triton_server shm_size: '16gb' deploy: resources: reservations: devices: - driver: nvidia count: all capabilities: [gpu] environment: - TRITON_SERVER_MODEL_REPOSITORY=/models - CUDA_VISIBLE_DEVICES=0,1,2,3 ports: - "8000:8000" # HTTP endpoint - "8001:8001" # gRPC endpoint - "8002:8002" # Metrics endpoint volumes: - ./model_repository:/models command: ["tritonserver", "--model-repository=/models", "--log-verbose=1", "--pinned-memory-pool-byte-size=268435456"] restart: always vllm-multimodal-engine: image: vllm/vllm-openai:latest container_name: vllm_multimodal_api environment: - CUDA_VISIBLE_DEVICES=4,5,6,7 - NCCL_DEBUG=INFO ports: - "8005:8000" volumes: - ~/.cache/huggingface:/root/.cache/huggingface deploy: resources: reservations: devices: - driver: nvidia count: 4 capabilities: [gpu] command: > python3 -m vllm.entrypoints.openai.api_server --model Qwen/Qwen2-VL-7B-Instruct --tensor-parallel-size 4 --trust-remote-code --max-model-len 32768 --gpu-memory-utilization 0.90 --max-num-seqs 256 restart: alwaysMultimodal Paradigms: A Structural Comparison To understand the trade-offs between different multimodal architectures, we can analyze the structures of early-fusion, late-fusion, and multi-encoder alignment models.Architectural Metric Early Fusion (Unified Tokenization) Late Fusion (Ensemble/Decision level) Cross-Attention / Bottleneck Alignment (Flamingo/BLIP-2) Unified Latent Projection (ImageBind)Data Ingestion Raw tokens interleaved at input layer Independent encoders, combined at logits Separate visual encoder, mapped via cross-attention Multi-headed projection to centralized hub spaceInference Latency High (large context sequence overhead) Minimal (parallel independent passes) Medium (attention bottlenecks add overhead) Low to Medium (efficient multi-sensor retrieval)Modal Interaction Direct (full self-attention across modalities) None (isolated until final layer) Medium (queries attend to frozen sensory keys) High (shared geometric similarity metrics)Primary Use Cases GPT-4o, Native Audio/Video LLMs Multi-sensor classification ensembles LLaVA, Video-LLaVA, Visual Question Answering Zero-shot multi-sensory retrieval, cross-modal searchThe table above demonstrates that while Early Fusion architectures provide the deepest level of multi-sensory understanding by allowing every modality token to pay direct attention to every other token, they suffer from high inference latency and rapid context-window exhaustion. Conversely, Cross-Attention Bottleneck models strike a practical production balance, making them highly popular for real-world visual-reasoning applications.Conclusion: The Horizon of Generalist Physical Agents We are moving past the era where artificial intelligence is mere software operating behind glass screens. The unification of speech, vision, dynamic temporal context, and motor outputs is coalescing into a single, cohesive framework: the Generalist Physical Agent. By building unified embeddings that span the entirety of physical experience, we are laying the groundwork for systems that learn from observation, follow complex environmental commands, and dynamically manipulate physical environments with human-like spatial precision. The future of machine intelligence is not linguistic; it is multi-sensory. The models that will define the next decade of human history are those that can see, hear, speak, touch, and move across our physical reality.#AI #MachineLearning #Robotics #ComputerVision #DeepLearning Related InsightsThe Thermodynamic Horizon: Decoding the Convergence of AI-Driven Fusion and Kinetic Energy Grids The Digital Scalpel: Architecting High-Fidelity Haptic Feedback in Robotic Surgery Simulation Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Death of Single-Modality AI: How Multi-Sensory Architectures and Embodied Models are Redefining Cognitive Computing?", "acceptedAnswer": { "@type": "Answer", "text": "An in-depth technical analysis of the architectural shift from unimodal LLMs to unified, multi-sensory AI models integrating video, audio, telemetry, and robotic action tokens." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Death of Single-Modality AI: How Multi-Sensory Architectures and Embodied Models are Redefining Cognitive Computing?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Eleanor Sterling." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Alexander Vance
- 12 Jul, 2026 14:00
Unveiling the Algorithmic Oracle: Navigating the Perilous Landscape of AI Ethics & Governance
The proliferation of Artificial Intelligence, from the sophisticated generative capabilities of large language models like GPT-4 to the predictive power of advanced deep learning architectures, marks a new epoch in technological evolution. As an AI researcher and senior software engineer, I've witnessed firsthand the breathtaking pace of innovation. Yet, with this unprecedented power comes an equally profound responsibility. The "algorithmic oracle" we are building holds the potential for immense societal benefit, but also carries inherent risks: entrenched biases, opaque decision-making, privacy infringements, and accountability vacuums. Navigating this intricate landscape requires more than just technical prowess; it demands a robust framework of AI ethics and governance. This isn't merely a philosophical exercise; it's a critical engineering challenge, a design imperative, and a regulatory necessity. We're past the theoretical discussions. Today, responsible AI is about concrete methodologies, auditable pipelines, and verifiable fairness metrics integrated directly into our MLOps practices. This article delves deep into the technical intricacies of building ethical AI, drawing insights from foundational arXiv papers, battle-tested GitHub projects, and the practical challenges faced by leading tech ventures from Y Combinator cohorts. We'll explore the current state-of-the-art in tackling bias, enhancing transparency, safeguarding data, and establishing clear accountability, providing actionable insights and code examples for the vanguard of AI development. Deconstructing AI Bias and Fairness Metrics The Achilles' heel of many AI systems is bias. This isn't a new phenomenon; it's a systemic issue often inherited from historical data, flawed collection methods, or the very structure of our algorithms. As evidenced by numerous studies – from predictive policing models exhibiting racial bias to hiring algorithms disadvantaging women – the consequences are tangible and severe. Addressing bias requires a multi-faceted approach, starting with a deep technical understanding of its origins and quantifiable detection methods. Bias can manifest in several forms:Selection Bias: Non-random sampling or data collection leads to unrepresentative datasets. Think of an image dataset predominantly featuring lighter skin tones, leading to poor performance on darker skin tones. Historical Bias: Real-world societal biases are encoded into the data itself. E.g., past lending data might reflect discriminatory practices, perpetuating them if an AI learns from it uncritically. Measurement Bias: Inaccurate or inconsistent labeling of data. Algorithmic Bias: Introduced during model design, training, or deployment (e.g., specific loss functions or regularization techniques impacting certain groups differently).To quantify and mitigate these biases, we rely on a suite of fairness metrics. There is no single "fairness" definition; rather, different metrics address different ethical concerns, often presenting trade-offs.Demographic Parity (or Statistical Parity): Requires that a positive outcome (e.g., loan approval, job offer) is granted at the same rate across different protected groups, regardless of individual characteristics. P(Y=1 | A=a) = P(Y=1 | A=b) where Y is the outcome and A is the protected attribute. Equalized Odds: A more stringent criterion, requiring equal true positive rates (TPR) and equal false positive rates (FPR) across groups. P(Y=1 | A=a, Y_true=1) = P(Y=1 | A=b, Y_true=1) AND P(Y=1 | A=a, Y_true=0) = P(Y=1 | A=b, Y_true=0). This is crucial for high-stakes applications like medical diagnoses or recidivism prediction. Predictive Parity (or Predictive Rate Parity): Requires that the precision (positive predictive value) is the same across groups. P(Y_true=1 | A=a, Y=1) = P(Y_true=1 | A=b, Y=1).Consider a simple Python example using the open-source aif360 library, a staple for many researchers and practitioners in this domain (cf. arXiv:1803.02453, "Fairness Metrics for Machine Learning: A Survey"). This library provides tools for bias detection and mitigation. import pandas as pd from aif360.datasets import StandardDataset from aif360.metrics import BinaryLabelDatasetMetric from aif360.metrics import ClassificationMetric from sklearn.linear_model import LogisticRegression from sklearn.preprocessing import StandardScaler from sklearn.model_selection import train_test_split# Sample data (hypothetical credit scoring) data = { 'age': [25, 30, 35, 40, 45, 50, 55, 60, 28, 32, 48, 52], 'income': [30000, 40000, 50000, 60000, 70000, 80000, 90000, 100000, 35000, 42000, 75000, 85000], 'education_level': [1, 2, 2, 3, 3, 4, 4, 4, 1, 2, 3, 4], # 1=high school, 4=phd 'credit_score': [600, 650, 700, 750, 800, 850, 900, 950, 620, 680, 780, 880], 'ethnicity': [0, 1, 0, 1, 0, 1, 0, 1, 0, 1, 0, 1], # 0=Group A (disadvantaged), 1=Group B 'loan_approved': [0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 1, 1] # 0=rejected, 1=approved } df = pd.DataFrame(data)# Define protected attributes and favorable/unfavorable labels protected_attribute_names = ['ethnicity'] privileged_classes = [[1]] # Group B is privileged label_name = 'loan_approved' favorable_label = 1# Convert to AIF360's StandardDataset format ad = StandardDataset( df, label_name=label_name, favorable_classes=[favorable_label], protected_attribute_names=protected_attribute_names, privileged_classes=privileged_classes )# Split data train, test = ad.split([0.7], shuffle=True)# Train a simple logistic regression model scaler = StandardScaler() X_train = scaler.fit_transform(train.features) X_test = scaler.transform(test.features) y_train = train.labels.ravel() y_test = test.labels.ravel()model = LogisticRegression(solver='liblinear') model.fit(X_train, y_train)# Get predictions test_pred = model.predict(X_test) test_probs = model.predict_proba(X_test)[:, 1]# Create a dataset with predictions for fairness evaluation test_pred_dataset = test.copy() test_pred_dataset.labels = test_pred# Calculate fairness metrics metric = ClassificationMetric( test, test_pred_dataset, unprivileged_groups=[{'ethnicity': 0}], privileged_groups=[{'ethnicity': 1}] )print(f"Disparate Impact (Demographic Parity): {metric.disparate_impact()}") print(f"Equal Opportunity Difference (TPR difference): {metric.equal_opportunity_difference()}") print(f"Average Odds Difference: {metric.average_odds_difference()}")This snippet demonstrates how to set up data for aif360 and compute foundational fairness metrics. A disparate_impact value significantly below 0.8 or above 1.25 often indicates potential demographic parity violations, as per common guidelines. An equal_opportunity_difference near zero signifies equal TPR across groups, which is critical in high-stakes scenarios. The challenge remains that improving one fairness metric might degrade another, necessitating careful ethical deliberation alongside technical optimization.Ensuring Transparency and Explainability (XAI) in Black-Box Models The rise of deep learning, particularly complex neural network architectures like Transformers and convolutional networks, has led to incredible performance gains. However, this often comes at the cost of interpretability, creating "black-box" models whose decisions are difficult for humans to understand or audit. This opacity poses significant ethical and governance challenges, especially in regulated industries or applications with high societal impact. How can we trust, debug, or even improve a system if we don't understand why it made a particular decision? This is where Explainable AI (XAI) comes into play. XAI techniques aim to shed light on model decisions, fostering trust, enabling compliance with regulations (e.g., "right to explanation" under GDPR), and empowering developers to identify and mitigate model vulnerabilities. Key XAI approaches include:Local Interpretable Model-agnostic Explanations (LIME): (arXiv:1602.04938) LIME explains individual predictions by training an interpretable surrogate model (e.g., linear model) locally around the prediction point. It samples perturbed data around the instance, gets predictions from the black-box model, and then trains a weighted, interpretable model on this local data. SHapley Additive exPlanations (SHAP): (arXiv:1705.07874) Based on cooperative game theory, SHAP values attribute the prediction of an instance to its features by calculating the marginal contribution of each feature across all possible coalitions of features. This provides a unified measure of feature importance, both globally and for individual predictions. Feature Importance/Permutation Importance: A global interpretation method that measures how much the model's performance decreases when a feature's values are randomly shuffled, effectively breaking its relationship with the target. Attention Mechanisms: In deep learning models like Transformers, attention weights reveal which parts of the input (e.g., words in a sentence) were most salient for a given output prediction.Let's illustrate SHAP with a simple example using shap library, which is widely adopted due to its theoretical grounding and practical utility. import shap import pandas as pd from sklearn.model_selection import train_test_split from sklearn.ensemble import RandomForestClassifier# Load a common dataset for demonstration (e.g., adult income dataset) # For real-world use, replace with your actual data from sklearn.datasets import load_breast_cancer data = load_breast_cancer() X = pd.DataFrame(data.data, columns=data.feature_names) y = pd.Series(data.target)# Train a Random Forest Classifier X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42) model = RandomForestClassifier(random_state=42) model.fit(X_train, y_train)# Create a SHAP explainer object # For tree-based models, TreeExplainer is efficient explainer = shap.TreeExplainer(model)# Calculate SHAP values for the test set shap_values = explainer.shap_values(X_test)# Plot summary for feature importance (global view) # Note: shap_values can be a list of arrays for multi-output models. # For binary classification, shap_values[1] typically corresponds to the positive class. print("--- SHAP Global Feature Importance (Summary Plot) ---") # shap.summary_plot(shap_values[1], X_test) # Uncomment to visualize if running in a notebook# Explain a single prediction (local view) sample_idx = 0 # Choose the first instance from the test set print(f"\n--- SHAP Explanation for a single instance (index {sample_idx}) ---") # shap.initjs() # For interactive JS plots in notebooks # shap.force_plot(explainer.expected_value[1], shap_values[1][sample_idx], X_test.iloc[sample_idx]) # Uncomment to visualize# For programmatic access to feature contributions for that instance: print(f"Model prediction for instance {sample_idx}: {model.predict_proba(X_test.iloc[[sample_idx]])[0][1]:.4f}") print("Feature contributions (SHAP values):") for feature, shap_val in zip(X_test.columns, shap_values[1][sample_idx]): print(f" {feature}: {shap_val:.4f}")The shap library provides powerful visualizations like summary_plot (global feature importance) and force_plot (individual prediction explanation), allowing engineers and stakeholders to understand which features drive particular outcomes. While XAI is a crucial step towards responsible AI, it’s not a panacea. The explanations themselves can sometimes be misleading, or their fidelity to the underlying black-box model may be imperfect. The key is to use XAI iteratively within the MLOps lifecycle to debug models, ensure compliance, and build user trust.Data Privacy, Security, and Synthetic Data Generation for Responsible AI In an era of ubiquitous data collection, upholding privacy and security is paramount for ethical AI. The intersection of large datasets, powerful analytical models, and sensitive personal information creates a complex minefield of potential privacy breaches, adversarial attacks, and regulatory non-compliance. Frameworks like GDPR, CCPA, and upcoming sector-specific regulations are not merely legal hurdles; they are ethical benchmarks demanding robust technical solutions. Key challenges and solutions include:Data Leakage and Re-identification: AI models, especially generative ones, can inadvertently memorize and reproduce sensitive training data. Re-identification attacks can link anonymized data back to individuals. Differential Privacy: (arXiv:0602048) A rigorous mathematical definition of privacy that guarantees individual data points contribute negligibly to the overall model output. By injecting calibrated noise during training or query responses, it prevents adversaries from inferring much about any single individual's data, even with auxiliary information. This often comes with a trade-off in model utility. Federated Learning: (arXiv:1602.05629) Instead of bringing data to a central server, federated learning trains models collaboratively across decentralized devices or organizations while keeping raw data local. Only model updates (gradients or weights) are aggregated, often with additional privacy-preserving techniques like differential privacy or secure aggregation.Adversarial Attacks: Malicious actors can craft subtly perturbed inputs (adversarial examples) that cause AI models to misclassify with high confidence, threatening system integrity and safety (e.g., autonomous vehicles misinterpreting stop signs). Adversarial Training: Augmenting training data with adversarial examples to make models more robust. Defensive Distillation: Training a second model on the probabilities generated by an initial model, making it less sensitive to small input perturbations.Synthetic Data Generation (SDG): Creating artificial data that statistically resembles real data but contains no direct information about individual original records. This is a game-changer for privacy-preserving AI development. Generative Adversarial Networks (GANs): A generator network learns to create synthetic data that fools a discriminator network into thinking it's real. Variational Autoencoders (VAEs): Learn a latent representation of the data to generate new, similar samples. CTGAN (Conditional Tabular GAN): Specifically designed for tabular data, outperforming traditional statistical methods and generic GANs in generating high-quality synthetic tables. (GitHub: sdv-dev/SDV)Here's a conceptual Python example illustrating a differentially private approach using the opacus library for PyTorch, a concrete implementation of DP for deep learning models. import torch import torch.nn as nn import torch.optim as optim from torch.utils.data import DataLoader, TensorDataset from opacus import privacy_engine# 1. Define a simple neural network class SimpleNet(nn.Module): def __init__(self): super(SimpleNet, self).__init__() self.fc1 = nn.Linear(10, 5) # Input features = 10 self.relu = nn.ReLU() self.fc2 = nn.Linear(5, 1) # Output = 1 (binary classification) self.sigmoid = nn.Sigmoid() def forward(self, x): x = self.fc1(x) x = self.relu(x) x = self.fc2(x) x = self.sigmoid(x) return x# 2. Generate some dummy data X_dummy = torch.randn(100, 10) # 100 samples, 10 features y_dummy = torch.randint(0, 2, (100, 1)).float() # Binary labels dataset = TensorDataset(X_dummy, y_dummy) dataloader = DataLoader(dataset, batch_size=16)# 3. Instantiate model, optimizer, and loss function model = SimpleNet() optimizer = optim.SGD(model.parameters(), lr=0.01) criterion = nn.BCELoss()# 4. Integrate Opacus for Differential Privacy privacy_engine.make_private_with_epsilon( module=model, optimizer=optimizer, data_loader=dataloader, target_epsilon=10.0, # Desired privacy budget (epsilon) target_delta=1e-5, # Desired privacy failure probability (delta) epochs=10, # Total epochs for training max_grad_norm=1.0 # Clipping norm for gradients )print(f"Model is now private: {privacy_engine.is_private(optimizer)}")# 5. Training loop (now with differential privacy applied) for epoch in range(10): for data, target in dataloader: optimizer.zero_grad() output = model(data) loss = criterion(output, target) loss.backward() optimizer.step() # At the end of each epoch, query the privacy accountant epsilon, best_alpha = optimizer.privacy_engine.get_epsilon(target_delta=1e-5) print(f"Epoch {epoch+1}, Epsilon: {epsilon:.2f}, Loss: {loss.item():.4f}")This snippet demonstrates the ease with which libraries like Opacus can transform a standard PyTorch training loop into a differentially private one. While the make_private_with_epsilon function simplifies much of the underlying complexity (like adding noise to gradients and clipping them), understanding the implications of target_epsilon and target_delta is critical for real-world deployment. Lower epsilon means stronger privacy but potentially lower model accuracy. SDG, on the other hand, allows for training on privacy-preserving, high-fidelity data, mitigating re-identification risks without the utility trade-offs often seen with direct DP application on real data.Establishing Robust AI Governance Frameworks and MLOps Pipelines Ethical AI is not a post-deployment afterthought; it must be ingrained into the entire Machine Learning Operations (MLOps) lifecycle. Just as DevOps brought agility and reliability to software development, MLOps extends these principles to AI systems, adding crucial layers for governance, monitoring, and continuous assurance. Without a structured MLOps pipeline, even well-intentioned ethical considerations can become ad-hoc, unscalable, and ultimately ineffective. A robust AI governance framework, often codified through MLOps, addresses several key areas:Model Versioning and Lineage: Tracking every iteration of a model, its associated data, code, and training parameters. This is foundational for auditability and reproducibility. Data Governance: Managing data quality, provenance, access control, and privacy throughout its lifecycle. This includes automated checks for data drift and bias detection. Continuous Monitoring: Beyond traditional performance metrics (accuracy, F1-score), MLOps pipelines must monitor for: Data Drift: Changes in input data distribution over time, potentially rendering the model stale. Concept Drift: Changes in the relationship between input features and target variable. Fairness Drift: Deterioration of fairness metrics for specific protected groups. Explainability Drift: Changes in feature importance or attribution over time, potentially indicating hidden model shifts.Bias Detection & Mitigation in Production: Automated tools to continually assess fairness metrics on live predictions and trigger alerts or retraining if bias thresholds are exceeded. Transparency and Audit Trails: Ensuring that every decision, action, and output of the AI system is logged and auditable, critical for regulatory compliance (e.g., EU AI Act, NIST AI Risk Management Framework). Human-in-the-Loop Integration: Designing workflows for human review, feedback, and override at critical decision points.Consider a simplified MLOps pipeline step, perhaps in a CI/CD system like GitHub Actions or GitLab CI, focused on model validation and fairness checks before deployment to production. This YAML configuration demonstrates a conceptual stage where an existing model is evaluated against fairness benchmarks. # .github/workflows/model-validation.yml name: AI Model Validation and Fairness Checkson: pull_request: branches: [ main ] types: [ opened, synchronize, reopened ] workflow_dispatch:jobs: validate_model: runs-on: ubuntu-latest steps: - name: Checkout repository uses: actions/checkout@v3 - name: Set up Python uses: actions/setup-python@v4 with: python-version: '3.9' - name: Install dependencies run: | pip install pandas scikit-learn aif360 # For a full MLOps system, you'd install MLflow, Sagemaker SDK, etc. - name: Download latest production model and test data # In a real scenario, this would involve fetching from a model registry # e.g., using MLflow.download_artifacts or S3/GCS download run: | echo "Simulating model download from registry..." # Example: Replace with actual model artifact retrieval echo "Creating dummy model and data for demonstration" python -c " import joblib, pandas as pd from sklearn.linear_model import LogisticRegression from sklearn.datasets import make_classification X, y = make_classification(n_samples=1000, n_features=10, random_state=42) df = pd.DataFrame(X, columns=[f'feature_{i}' for i in range(10)]) df['ethnicity'] = pd.Series(y).apply(lambda x: 0 if x < 0.5 else 1) # Simulate protected attr df['target'] = y model = LogisticRegression().fit(df.drop(['target', 'ethnicity'], axis=1), df['target']) joblib.dump(model, 'prod_model.pkl') df.to_csv('test_data.csv', index=False) " - name: Run Model Fairness and Performance Validation run: | python <<EOF import joblib import pandas as pd from aif360.datasets import StandardDataset from aif360.metrics import ClassificationMetric from sklearn.metrics import accuracy_score, f1_score# Load model and data model = joblib.load('prod_model.pkl') test_df = pd.read_csv('test_data.csv')# Prepare AIF360 dataset ad = StandardDataset( test_df, label_name='target', favorable_classes=[1], protected_attribute_names=['ethnicity'], privileged_classes=[[1]] # Group with 'ethnicity':1 is privileged )# Make predictions predictions = model.predict(test_df.drop(['target', 'ethnicity'], axis=1))# Create a dataset with predictions for fairness evaluation pred_dataset = ad.copy() pred_dataset.labels = predictions# Calculate classification metrics accuracy = accuracy_score(test_df['target'], predictions) f1 = f1_score(test_df['target'], predictions)# Calculate fairness metrics metric = ClassificationMetric( ad, pred_dataset, unprivileged_groups=[{'ethnicity': 0}], privileged_groups=[{'ethnicity': 1}] )di = metric.disparate_impact() eod = metric.equal_opportunity_difference()print(f"Model Accuracy: {accuracy:.4f}") print(f"Model F1 Score: {f1:.4f}") print(f"Disparate Impact: {di:.4f}") print(f"Equal Opportunity Difference: {eod:.4f}")# Define thresholds for passing if accuracy < 0.75: print("Error: Model accuracy is below threshold!") exit(1) if di < 0.8 or di > 1.25: print("Error: Disparate Impact is outside acceptable range!") exit(1) if abs(eod) > 0.1: # Example threshold for equal opportunity print("Error: Equal Opportunity Difference is too high!") exit(1)print("Model passed all validation checks!") EOFThis YAML snippet represents a crucial step in an MLOps pipeline. It automates the evaluation of a model against predefined performance and fairness thresholds. If any threshold is breached, the pipeline fails, preventing potentially biased or underperforming models from reaching production. This proactive, automated approach is the bedrock of operationalizing responsible AI, ensuring continuous oversight from development through deployment and monitoring. The Challenge of AI Accountability and Human Oversight As AI systems become more autonomous and complex, the question of accountability — who or what is responsible when an AI system causes harm — becomes increasingly thorny. This isn't just a legal puzzle; it's an ethical imperative. If an autonomous vehicle causes an accident, if an AI-driven medical diagnostic tool makes a fatal error, or if an algorithmic trading system crashes markets, where does the buck stop? Attributing responsibility is complicated by the distributed nature of AI development, involving data scientists, engineers, product managers, and various stakeholders. Establishing accountability requires integrating human oversight mechanisms and clear lines of responsibility throughout the AI lifecycle.Human-in-the-Loop (HITL): This involves humans actively participating in the AI decision-making process. Review and Correction: Humans review AI predictions or actions and correct them. For example, content moderation systems where AI flags content, but human moderators make final decisions. Active Learning: Humans label ambiguous data points to improve model performance and generalization. Exception Handling: AI handles routine tasks, but complex or high-stakes cases are routed to human experts.Human-on-the-Loop (HOTL): Humans monitor AI systems and intervene if necessary. Performance Monitoring: Humans monitor dashboards for model drift, fairness violations, or anomalous behavior. Audit and Oversight: Regular audits of AI system logs and decisions by human oversight committees. Kill Switch/Override: The ability for humans to shut down or override an AI system in emergencies.Clear Lines of Responsibility: Designers/Developers: Accountable for the ethical design, testing, and documentation of the AI system, including inherent biases and limitations. Deployers/Operators: Responsible for the appropriate deployment, monitoring, and maintenance of the AI in specific contexts. Owners/Stakeholders: Ultimate responsibility for the AI's impact, requiring them to establish governance policies and ensure compliance.One practical implementation of HITL is to design inference pipelines that flag uncertain predictions or decisions impacting protected groups for human review. # Python pseudo-code for a human review trigger in an inference pipeline import numpy as np import pandas as pd # Assume 'model' is a pre-trained sklearn-compatible model # Assume 'threshold_uncertainty' is a defined confidence level (e.g., 0.6 for binary classification) # Assume 'protected_attribute_names' is a list of column names for protected attributesdef get_prediction_with_review(model, input_data, threshold_uncertainty=0.6, protected_attribute_names=None): """ Makes a prediction and flags for human review based on uncertainty or protected attributes. Args: model: Trained ML model with predict_proba method. input_data (pd.DataFrame): Input features for a single instance. threshold_uncertainty (float): Probability threshold below which to flag for review. protected_attribute_names (list): List of column names in input_data representing protected attributes. Returns: tuple: (prediction, review_flag, reason_for_review) """ prediction = model.predict(input_data)[0] probabilities = model.predict_proba(input_data)[0] max_prob = np.max(probabilities) review_flag = False reason = [] # Check for uncertainty if max_prob < threshold_uncertainty: review_flag = True reason.append(f"Low confidence prediction ({max_prob:.2f})") # Check for protected attributes (simplified logic: always review if protected attribute is present) # A more sophisticated approach would involve checking fairness metrics or specific edge cases if protected_attribute_names: for attr in protected_attribute_names: if attr in input_data.columns and input_data[attr].iloc[0] is not None: # This is a very simplistic check. Real-world would integrate aif360 # or similar to check if the prediction for this group is often biased. review_flag = True reason.append(f"Involves protected attribute: {attr}") break # Only need one protected attribute to trigger review if review_flag: print(f"Prediction for input: {prediction}, flagged for human review. Reasons: {', '.join(reason)}") return prediction, True, reason else: return prediction, False, None# Example Usage: # Assuming a model trained on a dataset with 'gender' as a protected attribute # model = ... (your trained model) # test_instance_safe = pd.DataFrame([[0.1, 0.2, 0.3, 0.4, 0.5, 0.6, 0.7, 0.8, 0.9, 1.0, 0]], # columns=[f'feature_{i}' for i in range(10)] + ['gender']) # test_instance_uncertain = pd.DataFrame([[0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 1]], # columns=[f'feature_{i}' for i in range(10)] + ['gender'])# # Let's simulate a model for demonstration # from sklearn.datasets import make_classification # from sklearn.ensemble import RandomForestClassifier # X_train, y_train = make_classification(n_samples=100, n_features=10, random_state=42) # mock_model = RandomForestClassifier(random_state=42) # mock_model.fit(X_train, y_train)# # Create an example input # input_data_example = pd.DataFrame(np.random.rand(1, 10), columns=[f'feature_{i}' for i in range(10)]) # input_data_example['gender'] = 0 # Example protected attribute# pred, flagged, reasons = get_prediction_with_review(mock_model, input_data_example, protected_attribute_names=['gender']) # print(f"Final Decision: {pred}, Flagged: {flagged}, Reasons: {reasons}")# input_data_uncertain = pd.DataFrame(np.full((1, 10), 0.5), columns=[f'feature_{i}' for i in range(10)]) # input_data_uncertain['gender'] = 1 # pred_unc, flagged_unc, reasons_unc = get_prediction_with_review(mock_model, input_data_uncertain, threshold_uncertainty=0.6, protected_attribute_names=['gender']) # print(f"Final Decision: {pred_unc}, Flagged: {flagged_unc}, Reasons: {reasons_unc}")This pseudo-code demonstrates a rudimentary human review trigger. In a production system, input_data would be passed through an explainability module (like SHAP) and then sent to a human dashboard for review, along with the explanation and reasons for flagging. Building such robust oversight mechanisms directly into AI deployment workflows is crucial for establishing credible accountability and mitigating risks associated with fully autonomous systems.The Evolving Regulatory Landscape and Global Frameworks for Responsible AI The imperative for AI ethics and governance is not just a plea from researchers; it's rapidly being codified into legal frameworks and industry standards worldwide. From the EU's pioneering AI Act to NIST's comprehensive AI Risk Management Framework, governments and international bodies are grappling with how to regulate this fast-moving technology. Understanding these frameworks is critical for any organization developing or deploying AI, not only for compliance but also for embedding responsible practices into their core operations. Here's a comparison of some prominent global frameworks:Feature/Framework EU AI Act NIST AI Risk Management Framework (AI RMF) UNESCO Recommendation on the Ethics of AIType Binding Regulation (Law) Voluntary Framework (Guidance) International Standard-Setting Instrument (Soft Law)Scope Providers & Deployers of AI Systems in EU. Risk-based approach. Developers & Users of AI (Public & Private). Lifecycle focus. Member States & Stakeholders globally. Comprehensive principles.Key Mechanism Prohibitions (e.g., social scoring), High-Risk AI (conformity assessment, human oversight), Limited Risk (transparency), Minimal Risk (self-regulation). Govern, Map, Measure, Manage (four core functions). Focus on continuous risk management. 10 Key Principles (e.g., proportionality, safety, privacy, fairness, transparency, accountability).Enforcement Fines up to 6% of global turnover or €30M. Not legally binding; encourages best practices for trustworthy AI. No direct enforcement; encourages integration into national laws.Focus Market access, safety, fundamental rights, consumer protection. Practical guidance for organizations to manage AI risks, promote trustworthy AI. Human-centric approach, promote human rights, sustainable development, global cooperation.Technical Aspects Emphasizes technical documentation, risk assessment, quality management, human oversight, robustness, accuracy, cybersecurity. Provides practical steps, tools, and processes for assessing and managing risks at each stage of the AI lifecycle. Outlines ethical requirements for data governance, design, development, and deployment, including XAI, bias mitigation.Industry Impact Significant regulatory burden for high-risk AI; shapes global AI market. Influences industry standards, provides blueprint for responsible AI adoption. Guides national AI strategies, promotes common ethical understanding.Status (as of 2024) Adopted, implementation ongoing. Published v1.0, widely adopted. Adopted by General Conference, guiding policy.The EU AI Act is particularly noteworthy as a binding legal framework. It adopts a tiered, risk-based approach:Unacceptable Risk: AI systems that manipulate human behavior, enable social scoring by public authorities, or exploit vulnerabilities are outright banned. High-Risk AI: Systems used in critical infrastructure, education, employment, law enforcement, migration, justice, and democratic processes. These require stringent conformity assessments, robust quality management systems, human oversight, cybersecurity measures, transparency, and accuracy. This means deep technical documentation (similar to medical device regulations), continuous monitoring, and auditable pipelines. Limited Risk AI: Systems with specific transparency obligations, e.g., chatbots must disclose they are AI. Minimal Risk AI: Most AI systems fall here and are subject to voluntary codes of conduct.The NIST AI RMF, while voluntary, provides practical, adaptable guidance for managing risks throughout the AI lifecycle. Its "Govern-Map-Measure-Manage" functions offer a structured approach for organizations to:Govern: Establish a culture of responsible AI. Map: Identify and characterize AI risks. Measure: Assess, analyze, and track AI risks. Manage: Prioritize, respond to, and communicate AI risks.These frameworks, whether regulatory or guidance-based, underscore a universal truth: responsible AI development is no longer optional. It demands proactive integration of ethical considerations into every phase of the AI product lifecycle, from data acquisition and model training to deployment and continuous monitoring. Ignoring them not only invites severe legal repercussions but also erodes public trust, hindering the very innovation AI promises. Conclusion: Engineering a Trustworthy AI Future The journey through AI ethics and governance reveals a landscape teeming with both transformative potential and intricate challenges. From the insidious pitfalls of algorithmic bias and the opaque nature of black-box models to the critical demands of data privacy, accountability, and emerging regulatory mandates, the path to responsible AI is multifaceted and requires relentless dedication. As an engineer and researcher, my conviction is firm: merely acknowledging these issues is insufficient; we must engineer solutions, embed ethical considerations directly into our codebases, and integrate robust governance into our MLOps pipelines. We've explored how technical solutions like advanced fairness metrics, XAI techniques such as SHAP and LIME, privacy-preserving methods like differential privacy and synthetic data generation, and structured MLOps frameworks are not just theoretical constructs but essential tools for building trustworthy AI. The convergence of arXiv's cutting-edge research, GitHub's open-source innovation, and the pragmatic demands of Y Combinator-backed startups points to a clear trajectory: responsible AI is becoming the new standard for quality, reliability, and market viability. The task ahead is immense, demanding interdisciplinary collaboration between technologists, ethicists, policymakers, and legal experts. It calls for continuous learning, iterative improvement, and a steadfast commitment to human-centric AI design. The responsibility falls upon us, the architects of this algorithmic future, to not only push the boundaries of what AI can do but also to ensure it serves humanity's best interests, with fairness, transparency, and accountability at its core. Let's build AI that inspires trust, not fear, and empowers, rather than marginalizes.#AI Ethics #AIGovernance #ResponsibleAI #MLOps #ExplainableAI Related InsightsUnlocking the Secrets of Quantum Computing: Breakthroughs in Qubit Stability and Error Correction The Ultimate Guide to Custom PC Building: Forging Your Digital Masterpiece Quantum Sensors: The Next Frontier in Precision Measurement with Unbreakable Physics{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unveiling the Algorithmic Oracle: Navigating the Perilous Landscape of AI Ethics & Governance?", "acceptedAnswer": { "@type": "Answer", "text": "A comprehensive, technical exploration of AI ethics, governance, and the imperative for responsible AI development, drawing on cutting-edge research and practical MLOps strategies." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unveiling the Algorithmic Oracle: Navigating the Perilous Landscape of AI Ethics & Governance?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Alexander Vance." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Kaan Demir
- 12 Jul, 2026 13:39
Beyond Silicon: Why Neuromorphic Computing Is The Brain's Ultimate Gambit Against AI's Energy Crisis
Introduction In the relentless pursuit of Artificial Intelligence, a silent crisis looms: the insatiable energy demands and the fundamental architectural limitations of conventional computing. From the colossal power draw of training GPT-4 sized models to the perennial "memory wall" that bottlenecks data movement between processor and memory, our silicon-based von Neumann architectures are increasingly becoming a gilded cage for advanced AI. The brain, conversely, operates on an entirely different principle: billions of neurons consuming a mere 20 watts, processing information with unparalleled efficiency, parallelization, and adaptability. This stark contrast isn't just an evolutionary marvel; it's a profound engineering blueprint. Enter neuromorphic computing – a radical paradigm shift that seeks to transcend the limitations of traditional hardware by mimicking the brain's structure and function. This isn't just about running neural networks faster; it's about fundamentally rethinking how computation happens, moving away from clock-driven, instruction-based processing to event-driven, massively parallel, and energy-proportional computation. For decades, it existed primarily in academic labs, but now, fueled by advancements in materials science, chip fabrication, and a deeper understanding of computational neuroscience, neuromorphic hardware is on the cusp of revolutionizing edge AI, IoT, robotics, and complex real-time decision-making. The future of AI isn't just about smarter algorithms; it's about hardware that thinks like a brain. This is the ultimate gambit against AI's energy crisis, promising a new era of intelligence that is both powerful and profoundly efficient. The Von Neumann Bottleneck and the Biological Imperative The ubiquitous von Neumann architecture, with its separate processing unit and memory, has served computing remarkably well for over 70 years. However, its Achilles' heel – the "memory wall" or "von Neumann bottleneck" – becomes acutely apparent with data-intensive workloads like modern deep learning. Data must constantly shuttle between the CPU/GPU and main memory, a process that consumes significant energy and time. For every operation, data transfer can be orders of magnitude more energy-intensive than the computation itself. As AI models scale, this bottleneck intensifies, leading to massive power consumption, increased latency, and diminished returns on performance improvements. Training a large language model can consume megawatt-hours of electricity, making sustainability a critical concern. The biological brain offers a compelling alternative. It is an exquisitely optimized, highly parallel, and energy-efficient computing machine. Information processing and memory are not distinctly separated; instead, computation occurs in situ, within and between neurons, where synapses also store information (weights). This "in-memory computing" paradigm eliminates the memory wall. Furthermore, the brain operates in an event-driven, asynchronous manner, utilizing sparse "spikes" to communicate information only when necessary. Unlike the synchronous, clock-gated operations of conventional chips, neurons only activate and consume energy when there's relevant input, leading to immense power savings. This biological imperative has driven the development of Spiking Neural Networks (SNNs), the computational model for most neuromorphic hardware. SNNs diverge from Artificial Neural Networks (ANNs) by processing information as discrete temporal events (spikes) rather than continuous activation values. A neuron in an SNN integrates incoming spikes, and when its membrane potential crosses a threshold, it emits its own spike, propagating information to downstream neurons. This temporal aspect introduces a powerful new dimension for information encoding and processing, making SNNs particularly adept at handling dynamic, real-time data streams with high energy efficiency. Challenges in training SNNs persist, primarily due to the non-differentiable nature of spike events, necessitating advanced techniques like surrogate gradients for backpropagation or biologically inspired Hebbian learning rules such as Spike-Timing-Dependent Plasticity (STDP). These efforts are extensively documented on arXiv, showcasing a vibrant research landscape aimed at unlocking the full potential of SNNs. # Simple Python implementation of a Leaky Integrate-and-Fire (LIF) neuron model import numpy as npclass LIFNeuron: def __init__(self, tau_m=10.0, V_rest=-70.0, V_threshold=-55.0, R_m=1.0): """ Initializes a Leaky Integrate-and-Fire (LIF) neuron. :param tau_m: Membrane time constant (ms) :param V_rest: Resting membrane potential (mV) :param V_threshold: Spike threshold potential (mV) :param R_m: Membrane resistance (MOhms) """ self.tau_m = tau_m self.V_rest = V_rest self.V_threshold = V_threshold self.R_m = R_m self.V_m = V_rest # Current membrane potential self.spiked = False def update(self, I_input, dt=1.0): """ Updates the neuron's membrane potential over a time step dt. :param I_input: Input current (nA) :param dt: Time step (ms) :return: True if the neuron spiked, False otherwise """ dV_dt = (-(self.V_m - self.V_rest) + self.R_m * I_input) / self.tau_m self.V_m += dV_dt * dt self.spiked = False if self.V_m >= self.V_threshold: self.V_m = self.V_rest # Reset membrane potential after spiking self.spiked = True return self.spiked# Example usage: neuron = LIFNeuron() input_current = 20.0 # Constant input current time_steps = 50 spike_train = []print(f"Initial V_m: {neuron.V_m} mV") for t in range(time_steps): spiked = neuron.update(input_current) if spiked: spike_train.append(1) print(f"Time {t+1} ms: Neuron spiked! V_m reset to {neuron.V_m} mV") else: spike_train.append(0) # print(f"Time {t+1} ms: V_m = {neuron.V_m:.2f} mV")# print("\nSpike train:", spike_train)Architectural Innovations: From Wafer to Workload Neuromorphic hardware represents a radical departure from traditional chip design, embracing massive parallelism and in-memory computation. Key players like Intel with Loihi, IBM with TrueNorth, and BrainChip with Akida have pioneered distinct architectures, but share common foundational principles. Intel's Loihi research chip, for instance, integrates 128 "neuromorphic cores" on a single die, each containing 1024 spiking neurons and local memory. This local memory-processing unit eliminates the need for constant data transfers to external DRAM. The cores communicate asynchronously via an on-chip mesh network, only transmitting data (spikes) when events occur, drastically reducing power consumption. Loihi supports various SNN neuron models and learning rules like STDP directly in hardware. Intel's latest iteration, Loihi 2, fabricated on Intel 4 process technology, boasts faster speeds, higher neuron counts (over a million per chip), and expanded programmability with a 10x-100x improvement in neuron capacity and speed per chip compared to its predecessor. This advancement, detailed in recent arXiv preprints, pushes the envelope for real-time, low-power AI inference at the edge. IBM's TrueNorth, an earlier but significant effort, packs 4096 neurosynaptic cores, each with 256 neurons and 256x256 synapses. TrueNorth is highly optimized for fixed-function SNNs, excelling at tasks like pattern recognition with incredibly low power envelopes (tens of milliwatts). Its strength lies in its tiled architecture, allowing for immense scalability by tiling multiple chips together. BrainChip's Akida is another commercial offering, designed for ultra-low power edge AI. Akida IP cores are configurable, allowing for integration into various SoC designs. It supports event-domain neural processing, converting conventional ANNs into SNNs for efficient inference on-device, often outperforming traditional methods in energy efficiency for specific tasks like gesture recognition and keyword spotting. These architectures are not just about raw neuron counts; they integrate specialized hardware features:In-Memory Computing: Memory elements (often SRAM, but increasingly non-volatile memory like RRAM/memristors) are co-located with processing elements (neurons/synapses) to minimize data movement. Asynchronous Event-Driven Processing: Computation only occurs when a spike arrives, contrasting with the continuous clock cycles of traditional chips. Massively Parallel, Distributed Processing: Thousands to millions of neurons and billions of synapses operate concurrently across the chip. Programmable Synapses: Synaptic weights can be updated on-chip, enabling various learning rules and online adaptation.The manufacturing processes for these chips often involve custom ASIC designs, sometimes leveraging advanced nodes (like TSMC's processes for BrainChip) to maximize density and efficiency. The underlying technology explores beyond standard CMOS, integrating novel devices such as memristors for analog synaptic weight storage, which promises even greater density and energy efficiency for future generations. # Conceptual YAML for deploying a simple SNN model on a neuromorphic emulator # This example illustrates how one might configure a workload for a Loihi-like system # using a high-level abstraction layer or SDK.apiVersion: neuromorphic.ai/v1alpha1 kind: SNNApplication metadata: name: gesture-recognition-snn spec: modelName: "spiking-gesture-net-v1" modelConfig: neuronType: "LIF" synapseLearningRule: "STDP_Triphasic" numLayers: 5 layerTopology: [784, 256, 128, 64, 10] # Input, Hidden, Output neurons hardwareTarget: type: "Emulator" emulatorConfig: name: "nxsdk_simulator" # Intel Loihi's Python SDK simulator cores: 16 # Number of simulated neuromorphic cores timesteps: 1000 # Simulation duration in timesteps inputData: source: "live_sensor_stream" dataFormat: "spike_event_stream" # Data already pre-processed into spike events samplingRateHz: 100 outputConfig: destination: "mqtt_broker" topic: "neuromorphic/gestures" format: "json" includeConfidence: true deploymentStrategy: priority: "real-time" powerBudgetMw: 20 # Target power budget in milliwatts continuousLearning: enabled: true learningRate: 0.001 adaptiveThresholds: trueSpiking Neural Networks: The Language of the Brain-Inspired Spiking Neural Networks (SNNs) are the cornerstone of neuromorphic computing, moving beyond the static, continuous activations of traditional Artificial Neural Networks (ANNs) to a dynamic, event-driven paradigm. Unlike ANNs where neurons compute and pass continuous values (e.g., ReLU, Sigmoid outputs), SNN neurons communicate via discrete, asynchronous "spikes"—brief electrical pulses—much like biological neurons. This fundamental difference is key to their energy efficiency and ability to process temporal information inherently. The most common SNN neuron models include the Leaky Integrate-and-Fire (LIF) model, which we saw earlier, and its variations like the Izhikevich model, which can simulate a wider range of biological spiking patterns. In a LIF neuron, incoming spikes cause its membrane potential to rise. If this potential exceeds a threshold, the neuron fires a spike and its potential is reset. Otherwise, the potential "leaks" back towards a resting state over time, mimicking biological membrane dynamics. This temporal integration allows SNNs to process information encoded not just in the presence of spikes, but also in their timing, frequency, and relative order. Training SNNs has historically been a significant challenge. The non-differentiable nature of a spike (it’s either 0 or 1, with an abrupt jump) prevents direct application of gradient-based backpropagation. Researchers have developed several innovative approaches:Conversion from ANNs: Pre-trained ANNs can be converted into SNNs by carefully scaling weights and biases, often achieving competitive accuracy with significantly reduced power consumption during inference. This method is prevalent in commercial neuromorphic solutions like BrainChip's Akida. Spike-Timing-Dependent Plasticity (STDP): A biologically inspired unsupervised learning rule where the change in synaptic weight depends on the relative timing of pre- and post-synaptic spikes. If a pre-synaptic spike consistently precedes a post-synaptic spike, the connection strengthens; if it consistently follows, it weakens. Many neuromorphic chips implement hardware-accelerated STDP. Backpropagation Through Time (BPTT) with Surrogate Gradients: This technique adapts standard backpropagation for SNNs. When a spike event occurs, its non-differentiable step function is replaced by a "surrogate" smooth function (e.g., sigmoid or arc-tangent approximation) during the backward pass, allowing gradients to propagate. Frameworks like snnTorch and Nengo heavily utilize this. Event-based Backpropagation: More recent methods aim to directly calculate gradients based on the timing of events, often leveraging adjoint methods or specialized event-driven optimizers.The software ecosystem for SNNs is rapidly maturing. Frameworks like snnTorch (built on PyTorch) provide a comprehensive environment for designing, training, and deploying SNNs, offering various neuron models, learning rules, and utility functions. Nengo (from Applied Brain Research) is a popular open-source framework for building large-scale SNNs and cognitive models, often targeting neuromorphic hardware like Loihi or their own custom chips. Brian2 is another powerful simulator, particularly favored by computational neuroscientists for detailed biological SNN modeling. These tools are crucial for bridging the gap between theoretical SNN advancements and practical applications on neuromorphic hardware, addressing the steep learning curve for developers accustomed to traditional ANNs. # Python code using snnTorch to define a simple spiking neuron layer import torch import torch.nn as nn import snntorch as snn from snntorch import surrogate# Define a simple SNN layer using snnTorch class SimpleSNN(nn.Module): def __init__(self, num_inputs, num_outputs, beta=0.9, threshold=1.0): super().__init__() # Linear layer mapping input to hidden dimensions self.fc = nn.Linear(num_inputs, num_outputs) # Leaky Integrate-and-Fire (LIF) neuron layer # beta: decay rate of membrane potential # threshold: voltage threshold for spiking # spike_grad: surrogate gradient function for backprop self.lif = snn.Leaky(beta=beta, threshold=threshold, spike_grad=surrogate.fast_sigmoid()) def forward(self, x): # Initialize membrane potential for the LIF neuron mem = self.lif.init_leaky() # Iterate over time steps (this is crucial for SNNs) spikes_output = [] for step in range(x.size(0)): # Assuming x is [time_steps, batch_size, features] cur_input = self.fc(x[step]) spike, mem = self.lif(cur_input, mem) spikes_output.append(spike) return torch.stack(spikes_output, dim=0)# Example Usage: # Define input data (e.g., a time-series of spike events) num_time_steps = 25 batch_size = 4 input_features = 10 output_features = 2# Create dummy input data (e.g., random spikes over time) input_data = torch.rand(num_time_steps, batch_size, input_features) > 0.8 input_data = input_data.float() # Convert to float for linear layer# Initialize the SNN model snn_model = SimpleSNN(input_features, output_features)# Forward pass output_spikes = snn_model(input_data)print(f"Input data shape: {input_data.shape}") # [time_steps, batch_size, input_features] print(f"Output spikes shape: {output_spikes.shape}") # [time_steps, batch_size, output_features] print(f"Total spikes in output (example for one batch item): {output_spikes[:, 0, :].sum()}")Applications and Edge AI Revolution Neuromorphic computing is not a general-purpose replacement for CPUs or GPUs, but rather a specialized accelerator poised to revolutionize specific domains, particularly Edge AI. Its inherent advantages—ultra-low power consumption, real-time event-driven processing, and continuous learning capabilities—make it ideal for intelligent systems operating at the periphery of networks, where energy budgets are tight and immediate decision-making is critical. Consider the pervasive landscape of the Internet of Things (IoT). Billions of sensors are deployed in diverse environments, from smart homes to industrial factories. Traditional AI inference on these devices often requires data to be sent to the cloud, incurring latency, bandwidth costs, and privacy concerns. Neuromorphic chips, operating at milliwatt power levels, can enable always-on, real-time inference directly on the sensor. Use cases include:Always-on Keyword Spotting/Voice Activity Detection: Devices can continuously listen for trigger phrases or human presence without draining batteries, as demonstrated by BrainChip's Akida in various benchmark tests. Gesture Recognition and Human-Machine Interaction: Low-power processing of camera or radar sensor data for intuitive, touch-free interfaces in consumer electronics, automotive interiors, or industrial settings. Predictive Maintenance in Industrial IoT: Real-time anomaly detection from sensor data (vibration, temperature, acoustic) on factory floors, identifying potential equipment failures before they occur, all with local processing. Autonomous Systems (Robotics, Drones, Self-Driving Cars): Neuromorphic processors can provide rapid, low-power processing for perception, navigation, and control, especially for event-based vision sensors (e.g., dynamic vision sensors, DVS cameras) which naturally output spike trains. Their ability to process information sparsely and asynchronously is a perfect match for dynamic environments. Biomedical Signal Processing: Real-time analysis of EEG, ECG, or EMG signals for medical diagnostics, wearable health monitoring, or brain-computer interfaces, where immediate feedback is crucial and power efficiency paramount.The energy efficiency gains are staggering. For specific SNN-optimized tasks, neuromorphic chips can achieve hundreds to thousands of times better energy efficiency (operations per Joule) compared to traditional CPUs or GPUs. For instance, Intel's Loihi has shown orders of magnitude power reduction for tasks like real-time gesture recognition and object classification with event-based sensors, outperforming conventional embedded processors. This translates directly to longer battery life for mobile and IoT devices, smaller form factors, and reduced operational costs for large-scale sensor networks. The "learning on the edge" capability, driven by hardware-accelerated STDP, also means that devices can continuously adapt and improve their performance in the field, without needing to offload data for retraining or complex model updates, a capability largely absent in traditional edge AI deployments. # Conceptual Bash commands for setting up a simulated neuromorphic environment # and deploying a simple SNN model for edge inference. # This assumes a pre-compiled SNN model and a neuromorphic runtime.# 1. Prepare a Docker image for the neuromorphic runtime (e.g., for an ARM-based edge device) # Dockerfile content might include snnTorch, Nengo, or Intel's NxSDK/Lava for Loihi emulation. # For simplicity, let's assume a pre-built image. echo "Building neuromorphic inference Docker image..." docker build -t neuromorphic-edge-runtime:1.0 . # (assuming Dockerfile is in current dir) # Example Dockerfile might look like: # FROM python:3.9-slim-buster # WORKDIR /app # COPY requirements.txt . # RUN pip install -r requirements.txt # COPY inference_script.py . # COPY s_gesture_model.npy . # Pre-trained SNN model # CMD ["python", "inference_script.py"]# 2. Deploy the container to a simulated edge device or a real one (e.g., Raspberry Pi with accelerator) echo "Deploying SNN model to edge device (simulated/actual)..." # Assuming the model expects a live stream of event data, e.g., from a DVS camera or sensor. # Mount necessary sensor data or configuration files. docker run -d --name edge-snn-inference \ --network host \ -v /dev/sensor_input:/dev/sensor_input \ -v /path/to/config:/app/config \ neuromorphic-edge-runtime:1.0 \ python /app/inference_script.py --model /app/s_gesture_model.npy --sensor-id /dev/sensor_inputecho "SNN inference service deployed. Monitoring logs..." docker logs -f edge-snn-inference # Expected output from inference_script.py might be detected gestures or anomalies.# 3. Example of stopping and cleaning up # docker stop edge-snn-inference # docker rm edge-snn-inference # docker rmi neuromorphic-edge-runtime:1.0The Road Ahead: Challenges and Breakthroughs Despite the extraordinary promise, neuromorphic computing is still a nascent field facing significant hurdles on its path to mainstream adoption. The "neuromorphic gap" refers to the chasm between biologically inspired principles and the practical engineering of robust, programmable, and scalable systems. One of the primary challenges lies in the software ecosystem and programming models. Developing applications for neuromorphic hardware is inherently different from traditional programming. It requires a paradigm shift from sequential instructions to event-driven, parallel computation. While frameworks like Intel's Lava SDK (for Loihi) and Nengo are making strides, there's a definite lack of mature, high-level abstractions, compilers, and debugging tools comparable to the vast ecosystems available for CPUs and GPUs (e.g., CUDA, TensorFlow, PyTorch). Training methodologies for SNNs, while improving with surrogate gradients and conversion techniques, still lag behind the robustness and generality of backpropagation for ANNs. Achieving state-of-the-art accuracy on complex, large-scale benchmarks with SNNs remains an active research area. Scalability and generality are also key concerns. While current neuromorphic chips excel at specific, low-power edge tasks, scaling them to compete with GPU clusters for training massive foundation models or running complex, diverse workloads is still a distant goal. The specialized nature of neuromorphic architectures means they are not a universal compute solution but rather specialized accelerators. Research into hybrid architectures – combining neuromorphic elements with traditional processors – is emerging as a practical path forward, allowing workloads to be intelligently partitioned for optimal performance and energy efficiency. Another frontier is novel device physics and materials science. While current chips primarily use CMOS technology, the ultimate vision for neuromorphic computing often involves non-von Neumann devices like memristors, phase-change memory (PCM), or resistive random-access memory (RRAM) for more efficient, dense, and analog synaptic weight storage and in-memory computation. These technologies promise even greater power efficiency and synapse density but come with their own manufacturing and reliability challenges. Optical neuromorphic computing, leveraging light to perform computations, is also an exciting, albeit early-stage, research direction, offering potential for ultra-high speeds and low power consumption. Significant investment from governments (e.g., DARPA, European Commission's Human Brain Project) and tech giants (IBM, Intel) continues to fuel research. Startups like SynSense and GrAI Matter Labs are pushing commercial applications, demonstrating traction in specific edge AI markets. The path forward involves continued interdisciplinary collaboration between neuroscientists, material scientists, computer architects, and software engineers to bridge these gaps. As the field matures, we can anticipate more standardized toolchains, improved programmability, and a clearer understanding of the optimal applications where neuromorphic computing truly shines, leading to transformative breakthroughs in AI capabilities at the very edge of our interconnected world. # Python example illustrating a simplified Spike-Timing-Dependent Plasticity (STDP) rule # This demonstrates a fundamental unsupervised learning mechanism in SNNsclass Synapse: def __init__(self, weight=0.5, learning_rate_plus=0.01, learning_rate_minus=0.01): self.weight = weight self.last_pre_spike = -np.inf # Time of last presynaptic spike self.last_post_spike = -np.inf # Time of last postsynaptic spike self.lr_plus = learning_rate_plus self.lr_minus = learning_rate_minus self.tau = 20.0 # Time constant for STDP window (ms) def update_weight(self, pre_spike_time, post_spike_time): """ Updates the synaptic weight based on STDP rule. :param pre_spike_time: Time of the current presynaptic spike :param post_spike_time: Time of the current postsynaptic spike """ # Only update if both pre- and post-synaptic spikes have occurred if pre_spike_time is not None and post_spike_time is not None: delta_t = post_spike_time - pre_spike_time if delta_t > 0: # Post-synaptic spike after pre-synaptic: Potentiation delta_w = self.lr_plus * np.exp(-delta_t / self.tau) self.weight += delta_w elif delta_t < 0: # Post-synaptic spike before pre-synaptic: Depression delta_w = self.lr_minus * np.exp(delta_t / self.tau) self.weight -= delta_w # Ensure weight stays within reasonable bounds self.weight = np.clip(self.weight, 0.0, 1.0) # Example bounds# Simulate a simple scenario with two neurons and one synapse synapse = Synapse(weight=0.5)# Scenario 1: Pre-synaptic spike before post-synaptic (Potentiation) pre_spike_t1 = 10 post_spike_t1 = 15 # Post happens 5ms after pre synapse.update_weight(pre_spike_t1, post_spike_t1) print(f"Scenario 1 (Potentiation, delta_t={post_spike_t1 - pre_spike_t1}ms): New weight = {synapse.weight:.4f}")# Scenario 2: Pre-synaptic spike after post-synaptic (Depression) synapse = Synapse(weight=0.5) # Reset for new scenario pre_spike_t2 = 20 post_spike_t2 = 18 # Post happens 2ms before pre synapse.update_weight(pre_spike_t2, post_spike_t2) print(f"Scenario 2 (Depression, delta_t={post_spike_t2 - pre_spike_t2}ms): New weight = {synapse.weight:.4f}")# Scenario 3: No significant spike timing difference, small change (or no change if delta_t=0) synapse = Synapse(weight=0.5) pre_spike_t3 = 30 post_spike_t3 = 30 synapse.update_weight(pre_spike_t3, post_spike_t3) # delta_t = 0, no change with this simple model print(f"Scenario 3 (No change): New weight = {synapse.weight:.4f}")Comparative Overview of Leading Neuromorphic ProcessorsFeature / Processor Intel Loihi (Loihi 2) IBM TrueNorth BrainChip AkidaArchitecture Event-driven, asynchronous spiking neural network processor with on-chip learning. Multi-core. Fixed-point, highly parallel tiled neurosynaptic core array. Event-domain neural processor, IP core for SoC integration.Key Processing Model Spiking Neural Networks (SNNs) with programmable neuron models (e.g., LIF, Izhikevich) and learning rules (STDP). Spiking Neural Networks (SNNs) with 4 neuron models and 16 synapse types. Converts ANNs to SNNs for inference; supports CNNs, RNNs, fully connected layers.Neuron Count (per chip) Up to 1 million (Loihi 2) 1 million (approx.) ~1.2 million (Akida 1.0)Synapse Count (per chip) 128 million (Loihi 2) 256 million (approx.) ~10 million (Akida 1.0)Typical Power Consumption <100 mW (inference) ~20-70 mW (inference) ~100 µW - 10 mW (inference)Key Strengths Research platform, on-chip learning, flexible SNN models, real-time control, sensor fusion. Extreme power efficiency, high density, proven for pattern recognition. Ultra-low power edge inference, IP core flexibility, ease of ANN-to-SNN conversion.Programming Model NxSDK (Python-based), Lava SDK (open-source framework) Corelet programming model, proprietary SDK. Akida SDK (Python/C++), integrates with TensorFlow, Keras.Use Cases Robotics, autonomous systems, continuous learning, pattern recognition, constraint satisfaction. Real-time sensor analytics, surveillance, embedded vision. Always-on IoT, medical devices, automotive, smart home, industrial control.Availability Academic/Research access (Intel Neuromorphic Research Community) Research platform, limited commercial access. Commercial IP, evaluation kits available.Fabrication Intel 4 (Loihi 2) Samsung 28nm TSMC 28nmLearning Support On-chip unsupervised (STDP), supervised through host. Limited on-chip learning, primarily fixed inference. On-device incremental learning and few-shot learning.This table provides a snapshot of the distinct approaches and capabilities offered by some of the most prominent neuromorphic processors, highlighting their specialized design for energy-efficient, event-driven AI tasks. Each processor targets slightly different niches, showcasing the diverse potential of brain-inspired computing. Conclusion Neuromorphic computing represents one of the most exciting and critical frontiers in the evolution of Artificial Intelligence. As the demands on AI models continue to skyrocket, pushing conventional hardware to its absolute limits in terms of power consumption and efficiency, the brain's elegant solution to parallel, in-memory, event-driven computation offers not just inspiration, but a direct pathway forward. We are moving beyond the era where simply throwing more compute at a problem guarantees progress. The future of AI demands smarter, more sustainable hardware. The advancements in Intel Loihi, IBM TrueNorth, BrainChip Akida, and the rapidly maturing SNN software ecosystem like snnTorch and Nengo, illustrate a clear trajectory towards practical, deployable neuromorphic solutions. While significant challenges remain in bridging the "neuromorphic gap" – from developing truly general-purpose programming models to scaling for ever-larger tasks and integrating novel materials – the momentum is undeniable. These brain-inspired chips are not poised to replace general-purpose CPUs and GPUs, but rather to complement them, unleashing unparalleled energy efficiency and real-time intelligence at the edge, in robotics, autonomous systems, and pervasive IoT. The dawn of truly intelligent machines, capable of learning and adapting with a fraction of the energy budget of today's systems, is no longer a distant dream. It is an engineering reality being built, silicon by spike, in labs and fabs across the globe. The ultimate gambit against AI's energy crisis is underway, and it is profoundly brain-inspired. Kaan Demir#NeuromorphicComputing #AIHardware #SpikingNeuralNetworks #EdgeAI #BrainInspiredAI#AI #NeuromorphicComputing #EnergyCrisis #TechInnovation #FutureOfAI Related InsightsReal-Time Analytics with Apache Flink and Kafka: Powering Instant Insights The Digital Scalpel: Architecting High-Fidelity Haptic Feedback in Robotic Surgery Simulation The Architecture of Trust: Deconstructing the Post-Cookie Web3 Paradigm{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Beyond Silicon: Why Neuromorphic Computing Is The Brain's Ultimate Gambit Against AI's Energy Crisis?", "acceptedAnswer": { "@type": "Answer", "text": "Explore neuromorphic computing, a revolutionary paradigm leveraging brain-inspired hardware to overcome AI's energy and performance bottlenecks, paving the way for truly efficient edge intelligence." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Beyond Silicon: Why Neuromorphic Computing Is The Brain's Ultimate Gambit Against AI's Energy Crisis?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Kaan Demir." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Lukas Richter
- 12 Jul, 2026 12:08
Unlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears
In an era increasingly defined by data, the promise of Artificial Intelligence often collides head-on with the paramount demand for privacy. As AI models grow more sophisticated, their insatiable hunger for vast, diverse datasets presents an ethical and regulatory tightrope walk. Companies and researchers alike grapple with a fundamental dilemma: how do we harness the collective intelligence locked away in silos of sensitive data—be it personal health records, financial transactions, or proprietary enterprise information—without exposing individuals or compromising competitive advantage? The traditional approach of centralizing data for training AI models is not merely fraught with privacy risks; it is often logistically impossible due to regulatory constraints like GDPR, HIPAA, and CCPA, not to mention the sheer scale of data generated at the edge. This tension between innovation and protection has catalyzed a paradigm shift, giving rise to one of the most transformative advancements in machine learning: Federated Learning (FL). Pioneered by Google in 2016 for their Gboard keyboard predictions, FL fundamentally redefines how AI models learn. Instead of bringing all the data to a central server, FL brings the model to the data. It’s a decentralized approach where clients—whether individual mobile devices, hospitals, financial institutions, or IoT sensors—locally train a shared global model using their own datasets. Only aggregated model updates, not raw data, are sent back to a central server, which then orchestrates the consolidation of these updates into an improved global model. This revolutionary methodology allows AI to thrive on the richness of distributed information while rigorously upholding privacy, securing a future where intelligent systems can flourish without sacrificing our most fundamental right to data sovereignty.The Core Mechanics of Federated Learning: Beyond Centralized Paradigms At its heart, Federated Learning (FL) is an iterative, collaborative process designed to build a robust global model from disparate, localized datasets. Unlike traditional machine learning, where data is typically pooled onto a central server for training, FL flips the script. The core philosophy is "data stays local, models travel." This seemingly simple reversal has profound implications for privacy, scalability, and regulatory compliance. The FL cycle generally unfolds in several distinct phases, orchestrated by a central server (or orchestrator) that coordinates numerous participating clients. This process typically begins with the server initializing a global model (or retrieving the current global model) and distributing it to a selected subset of clients. Each client then takes this global model and trains it locally on its own private dataset. Crucially, this local training step leverages the client’s unique, sensitive data without ever exposing it outside its secure environment. The client processes its data, computes local model updates (e.g., gradients or updated model weights), and then securely transmits only these aggregated updates back to the central server. The raw data itself never leaves the client device. Upon receiving updates from multiple clients, the central server aggregates these contributions to produce a new, improved version of the global model. One of the most common and foundational aggregation algorithms is Federated Averaging (FedAvg), introduced by Brendan McMahan et al. in 2017 (arXiv:1602.05629). FedAvg simply averages the weights of the models received from participating clients, often weighted by the amount of data each client trained on. This aggregated model then becomes the basis for the next round of training, distributed back to the clients, and the cycle continues until the global model converges or a predefined number of rounds are completed. Consider a practical example using a simplified Pythonic representation for a client's local training: # Conceptual Python class for a Federated Learning Client import torch import torch.nn as nn import torch.optim as optimclass FederatedClient: def __init__(self, client_id, model, local_dataset, learning_rate=0.01): self.client_id = client_id self.model = model self.local_dataset = local_dataset self.optimizer = optim.SGD(self.model.parameters(), lr=learning_rate) self.criterion = nn.CrossEntropyLoss() def receive_global_model(self, global_model_weights): # Update client's model with global weights self.model.load_state_dict(global_model_weights) def train_local_model(self, epochs=1): self.model.train() for epoch in range(epochs): for inputs, labels in self.local_dataset: # self.local_dataset is typically a DataLoader self.optimizer.zero_grad() outputs = self.model(inputs) loss = self.criterion(outputs, labels) loss.backward() self.optimizer.step() # Return the locally updated model weights return self.model.state_dict() def send_local_update(self, local_model_weights): # In a real system, this would involve a secure network transmission # to the central server. For demonstration, we just return them. print(f"Client {self.client_id} sending model update.") return local_model_weights# Example usage (simplified server-side interaction) # global_model = SomeNeuralNetwork() # Initial global model # global_model_weights = global_model.state_dict() # # client_data = [...] # Client-specific data loaders # client_a = FederatedClient(1, SomeNeuralNetwork(), client_data[0]) # client_b = FederatedClient(2, SomeNeuralNetwork(), client_data[1]) # # # Round 1 # client_a.receive_global_model(global_model_weights) # client_b.receive_global_model(global_model_weights) # # update_a = client_a.train_local_model() # update_b = client_b.train_local_model() # # # Server aggregates updates (e.g., simple averaging) # aggregated_weights = { # key: (update_a[key] + update_b[key]) / 2 # for key in update_a.keys() # } # global_model.load_state_dict(aggregated_weights) # print("Global model updated.")This fundamental cycle ensures that sensitive data never leaves its source, providing a baseline privacy guarantee that is crucial for building trust and enabling AI in highly regulated domains. Architectures and Communication Protocols: Orchestrating Decentralized Intelligence The practical implementation of Federated Learning requires robust architectures and sophisticated communication protocols to manage the distributed training environment effectively. Two primary architectural paradigms dominate the FL landscape: cross-device and cross-silo FL, each catering to different use cases and scales. Cross-device Federated Learning, often referred to as horizontal FL, typically involves a massive number of mobile devices (smartphones, IoT sensors, wearables) with relatively small, non-IID datasets. Think of millions of smartphones collaboratively training an autocorrect model without sending individual keyboard usage data. The communication is often intermittent, unreliable, and bandwidth-constrained. Frameworks like TensorFlow Federated (TFF) and Google's internal systems are designed to handle this scale, focusing on efficient communication and robustness against device dropouts. The server acts as an orchestrator, selecting a subset of active clients for each round, distributing models, and aggregating updates. Cross-silo Federated Learning, or vertical FL, involves a smaller number of organizations (e.g., hospitals, banks, research institutions) each possessing large, often complementary datasets that share common entities but different feature sets. For instance, two banks might want to collaboratively build a fraud detection model using their respective customer data without merging their sensitive customer records. In this scenario, clients are typically powerful servers or data centers with reliable network connections. Here, secure multi-party computation (SMPC) and homomorphic encryption (HE) play a more prominent role to ensure privacy during the intermediate computation steps where features might be aligned or combined. Regardless of the architecture, effective communication protocols are paramount. gRPC (Google Remote Procedure Call) is a popular choice for its efficiency, multi-language support, and bi-directional streaming capabilities, making it ideal for the client-server interactions of FL. Secure channels (TLS/SSL) are always a baseline requirement for encrypting data in transit. Frameworks like Flower (a general-purpose FL framework), PySyft (from OpenMined, focusing on privacy-preserving AI), and TensorFlow Federated (TFF) provide abstractions for building FL systems. They handle client selection, model distribution, secure aggregation, and fault tolerance. Here's a conceptual docker-compose.yaml to illustrate setting up a simple multi-client FL simulation environment with a central server and multiple clients, using a framework like Flower or TFF as the underlying orchestration layer. Each service would run a Python script for either the server or client logic. version: '3.8' services: # Federated Learning Server server: build: context: ./server dockerfile: Dockerfile ports: - "8080:8080" environment: # Optional: specify number of clients, rounds, etc. SERVER_PORT: 8080 networks: - fl_network command: python /app/server.py # Federated Learning Clients client_1: build: context: ./client dockerfile: Dockerfile environment: CLIENT_ID: "client_1" SERVER_ADDRESS: "server:8080" # Connect to the server service networks: - fl_network depends_on: - server command: python /app/client.py client_2: build: context: ./client dockerfile: Dockerfile environment: CLIENT_ID: "client_2" SERVER_ADDRESS: "server:8080" networks: - fl_network depends_on: - server command: python /app/client.py client_3: build: context: ./client dockerfile: Dockerfile environment: CLIENT_ID: "client_3" SERVER_ADDRESS: "server:8080" networks: - fl_network depends_on: - server command: python /app/client.pynetworks: fl_network: driver: bridgeThis docker-compose.yaml file defines a simple FL network where a server orchestrates three clients. Each server.py and client.py would contain the specific logic for model exchange and training, typically leveraging an FL framework's API. For example, a client.py using Flower might look like: # client/client.py (Flower client example) import flower as fl import tensorflow as tf # Or PyTorch from model import get_model, train, test # Assume these are defined elsewhereclass CifarClient(fl.client.NumPyClient): def __init__(self, model, x_train, y_train, x_test, y_test): self.model = model self.x_train, self.y_train = x_train, y_train self.x_test, self.y_test = x_test, y_test def get_parameters(self, config): return self.model.get_weights() def fit(self, parameters, config): self.model.set_weights(parameters) self.model, results = train(self.model, self.x_train, self.y_train, config) return self.model.get_weights(), len(self.x_train), results def evaluate(self, parameters, config): self.model.set_weights(parameters) loss, accuracy = test(self.model, self.x_test, self.y_test) return loss, len(self.x_test), {"accuracy": accuracy}if __name__ == "__main__": # Load data and create model (simplified) # (x_train, y_train), (x_test, y_test) = tf.keras.datasets.cifar10.load_data() # model = get_model() # A Keras model # client = CifarClient(model, x_train, y_train, x_test, y_test) # fl.client.start_numpy_client(server_address="server:8080", client=client) print("Flower client started, waiting for connection...") # Placeholder for actual client logicThis distributed setup demonstrates how FL leverages existing network technologies to enable collaborative AI without centralizing raw data.Enhancing Privacy Guarantees: Differential Privacy and Secure Aggregation While Federated Learning inherently protects privacy by keeping raw data local, sophisticated attacks can still infer sensitive information from the shared model updates. Researchers have shown that even aggregated model weights can, under certain conditions, reveal characteristics of individual training samples through techniques like membership inference attacks or model inversion. To counter these threats, FL integrates advanced privacy-enhancing technologies (PETs), notably Differential Privacy (DP) and Secure Multi-Party Computation (SMPC), often complemented by Homomorphic Encryption (HE). Differential Privacy (DP) provides a strong, mathematically quantifiable guarantee of privacy. Its core idea is to inject carefully calibrated noise into the model updates (or directly into the training process) such that the contribution of any single data point becomes indistinguishable to an adversary. This means that an attacker observing the global model or aggregated updates cannot confidently determine if a specific individual's data was included in the training dataset. DP is parameterized by epsilon (ε) and delta (δ), where a smaller ε indicates stronger privacy (but potentially lower model utility), and δ represents the probability of privacy leakage exceeding ε. Implementing DP in FL often involves adding noise to the local model updates before they are sent to the server (client-side DP) or adding noise to the aggregated model on the server before distributing it (server-side DP). Frameworks like Opacus (for PyTorch) or TensorFlow Privacy make it easier to integrate DP into deep learning models. Here's a conceptual Python example using Opacus to apply Differential Privacy to a PyTorch model during local training within an FL client: # Conceptual Python snippet for a DP-enabled FL client from opacus import PrivacyEngine import torch.nn as nn import torch.optim as optimclass DP_FederatedClient(FederatedClient): # Inherits from earlier FederatedClient def __init__(self, client_id, model, local_dataset, learning_rate=0.01, epsilon=1.0, delta=1e-5, max_grad_norm=1.0): super().__init__(client_id, model, local_dataset, learning_rate) self.privacy_engine = PrivacyEngine( self.model, batch_size=32, # Batch size for local training sample_size=len(local_dataset.dataset), # Total samples in client's local dataset alphas=[1 + x / 10.0 for x in range(1, 100)] + list(range(10, 60)), noise_multiplier=0, # Will be set by privacy_engine.make_private max_grad_norm=max_grad_norm, ) # Apply DP to the optimizer self.optimizer = optim.SGD(self.model.parameters(), lr=learning_rate) # The make_private method automatically wraps the optimizer and adds hooks for DP # This calculates the appropriate noise_multiplier for the given epsilon, delta self.optimizer, self.data_loader, self.privacy_engine = self.privacy_engine.make_private( module=self.model, optimizer=self.optimizer, data_loader=self.local_dataset, noise_multiplier_target=epsilon, # Opacus uses this as target epsilon target_delta=delta, epochs=1 # Number of local epochs ) print(f"Client {self.client_id}: Noise multiplier: {self.optimizer.noise_multiplier}") def train_local_model(self, epochs=1): self.model.train() for epoch in range(epochs): for inputs, labels in self.local_dataset: self.optimizer.zero_grad() outputs = self.model(inputs) loss = self.criterion(outputs, labels) loss.backward() self.optimizer.step() return self.model.state_dict()Secure Multi-Party Computation (SMPC) is another cornerstone. SMPC protocols allow multiple parties to collectively compute a function on their private inputs without revealing those inputs to each other. In FL, SMPC can be used during the aggregation phase: clients encrypt their model updates before sending them, and the server (or a set of aggregation servers) can compute the sum of these encrypted updates without decrypting individual contributions. Only the final aggregated sum is revealed. This protects against a malicious server or colluding clients from learning individual updates. Homomorphic Encryption (HE) takes SMPC a step further by allowing computations (like addition or multiplication) directly on encrypted data. A client could encrypt its model updates using an HE scheme, send the ciphertext to the server, and the server could perform aggregation (e.g., summation) on these ciphertexts. The result is an encrypted aggregate, which only the client (or an authorized party with the decryption key) can decrypt. HE offers strong privacy guarantees but comes with significant computational overhead, making it more suitable for scenarios with fewer, powerful clients and simpler models (e.g., cross-silo FL). The trade-off is clear: stronger privacy often comes at the cost of increased computational complexity, communication overhead, or a slight reduction in model utility. The choice of PETs depends on the specific privacy requirements, threat model, and available computational resources. By intelligently combining these techniques, Federated Learning moves beyond simply distributed training to truly privacy-preserving AI. Tackling Data Heterogeneity and System Challenges: The Real-World Gauntlet While Federated Learning offers compelling advantages, its deployment in real-world scenarios is far from trivial. Two major categories of challenges emerge: data heterogeneity and system-level complexities. Successfully navigating these requires sophisticated algorithmic and engineering solutions. Data Heterogeneity (Non-IID Data): This is arguably the most significant algorithmic hurdle in FL. In idealized centralized training, data is assumed to be Independent and Identically Distributed (IID) across mini-batches. However, in FL, clients typically possess data that is inherently non-IID. For instance, a mobile phone user's keyboard usage patterns (autocorrect data) will differ significantly from another user's, reflecting unique vocabulary, topics, and typing styles. Similarly, medical records from different hospitals might have varying patient demographics, prevalent diseases, or diagnostic procedures. Training on non-IID data can lead to several problems:Client Drift: Local models diverge significantly from the global model due to unique local data, making aggregation less effective. Slower Convergence: The global model may take many more rounds to converge, or even fail to converge, as aggregated updates conflict with each other. Performance Degradation: The final global model may perform poorly on individual clients, or generalize poorly to unseen data, particularly on clients with underrepresented data distributions.To mitigate non-IID issues, various research directions have emerged. Personalization techniques, like FedProx (Li et al., 2018, arXiv:1812.06127), add a proximal term to the client's local loss function, penalizing divergence from the global model and encouraging clients to stay closer to the aggregate. Other approaches involve model-agnostic meta-learning (MAML) or knowledge distillation, where clients learn a personalized model or distill knowledge from the global model. System Challenges: Beyond data distribution, the sheer distributed nature of FL introduces significant engineering complexities:Device Heterogeneity: Clients can range from powerful data centers to low-power IoT devices with varying computational capabilities, memory, and battery life. Communication Constraints: Bandwidth limitations, high latency, and intermittent connectivity are common, especially in cross-device FL. This necessitates efficient compression techniques for model updates and robust communication protocols. Client Availability and Reliability: Devices can drop out mid-training, go offline, or have corrupted data. The FL system must be resilient to these "stragglers" and failures, potentially by employing asynchronous aggregation or robust client selection strategies. Security and Trust: Malicious clients can attempt data poisoning (injecting bad data to corrupt the model) or model poisoning (submitting adversarial updates to sabotage the global model). Robust aggregation methods like Krum (Blanchard et al., 2017, arXiv:1703.02757) or Trimmed Mean are designed to identify and filter out outlier updates.Here's a conceptual Python snippet demonstrating how to simulate non-IID data partitioning for clients, a common setup for research and experimentation: # Conceptual Python snippet for non-IID data partitioning import numpy as np import torch from torchvision import datasets, transformsdef partition_data_by_label_skew(dataset, num_clients, num_shards_per_client, num_classes): """ Partitions data to simulate non-IID client datasets with label skew. Each client gets a specific number of shards (e.g., each shard contains data from only one class) to ensure non-IIDness. """ label_indices = [[] for _ in range(num_classes)] for i, (_, label) in enumerate(dataset): label_indices[label].append(i) # Shuffle indices for each label for i in range(num_classes): np.random.shuffle(label_indices[i]) # Assign shards to clients client_datasets = [[] for _ in range(num_clients)] current_label_shard_idx = [0] * num_classes for client_id in range(num_clients): # Determine which classes this client will primarily have # A simple strategy: each client gets data from a few specific classes chosen_classes = np.random.choice(num_classes, size=num_shards_per_client, replace=False) for class_idx in chosen_classes: start_idx = current_label_shard_idx[class_idx] end_idx = start_idx + (len(label_indices[class_idx]) // num_clients // num_shards_per_client) # Ensure we don't go out of bounds if start_idx >= len(label_indices[class_idx]): continue # No more data for this class shard_indices = label_indices[class_idx][start_idx:end_idx] client_datasets[client_id].extend(shard_indices) current_label_shard_idx[class_idx] = end_idx # Create Subset objects for each client client_subsets = [] for indices in client_datasets: client_subsets.append(torch.utils.data.Subset(dataset, indices)) return client_subsets# Example Usage: # transform = transforms.Compose([transforms.ToTensor(), transforms.Normalize((0.5,), (0.5,))]) # train_dataset = datasets.MNIST('./data', train=True, download=True, transform=transform) # # num_clients = 10 # num_shards_per_client = 2 # Each client gets data from 2 classes primarily # num_classes = 10 # MNIST has 10 classes # # client_data_subsets = partition_data_by_label_skew(train_dataset, num_clients, num_shards_per_client, num_classes) # # # Now client_data_subsets[i] can be used to create a DataLoader for client i # # For example: client_i_dataloader = torch.utils.data.DataLoader(client_data_subsets[i], batch_size=32) # print(f"Generated {len(client_data_subsets)} client datasets.") # for i, subset in enumerate(client_data_subsets): # labels_in_subset = [train_dataset[j][1] for j in subset.indices] # unique_labels, counts = np.unique(labels_in_subset, return_counts=True) # print(f"Client {i} dataset size: {len(subset)}, labels: {list(zip(unique_labels, counts))}")This function highlights the complexity of creating realistic non-IID scenarios for experimentation, a crucial step in developing robust FL algorithms that can handle the unpredictability of real-world data distributions. Overcoming these challenges is vital for FL's widespread adoption and for delivering its full promise of privacy-preserving AI. Real-World Applications and The Regulatory Landscape: FL's Impact and Future Federated Learning is rapidly transitioning from an academic curiosity to a critical enabler of AI solutions across diverse industries, particularly where data privacy and ownership are paramount. Its real-world impact is already evident and continues to expand. In the consumer tech space, Google's pioneering use of FL for its Gboard keyboard is a prime example. Gboard uses FL to train next-word prediction models and emoji suggestions directly on user devices without sending keystroke data to Google's servers. Apple similarly leverages FL for features like Face ID improvement and health data analysis within its HealthKit ecosystem, ensuring sensitive biometric and health information remains on the user's device. Healthcare stands to benefit immensely. NVIDIA's Clara Federated Learning framework, for instance, enables hospitals to collaboratively train AI models for medical image analysis (e.g., tumor detection, disease diagnosis) using their proprietary patient datasets. This allows for the creation of more robust and generalizable models that leverage diverse patient populations, circumventing the need to centralize highly sensitive Protected Health Information (PHI), which is heavily regulated by HIPAA. Y Combinator-backed startups in the health AI space are actively exploring FL to unlock insights from fragmented datasets, accelerating drug discovery and personalized medicine. Financial services are another frontier. Banks and credit card companies can use FL to develop more accurate fraud detection models or credit scoring systems by collaborating on transaction data without sharing raw customer details. This can lead to stronger models that identify novel fraud patterns more quickly across a wider base, while adhering to strict financial data regulations. Similarly, autonomous vehicle companies could collaboratively train perception models on driving data from different fleets without exchanging raw sensor readings, enhancing safety and accelerating development. The rapid rise of FL directly intersects with the evolving regulatory landscape governing data privacy. Regulations like Europe's General Data Protection Regulation (GDPR), California's Consumer Privacy Act (CCPA), and sector-specific rules like HIPAA and PCI DSS, impose stringent requirements on how personal data is collected, processed, and stored. By design, FL aligns exceptionally well with the core principles of these regulations, particularly data minimization and purpose limitation. Since only aggregated model updates (which are often differentially private) are shared, and raw data remains on the client device, FL significantly reduces the attack surface and simplifies compliance by avoiding the transfer of sensitive raw data across organizational or national boundaries. However, the regulatory landscape is not without its nuances. The concept of "personal data" in the context of model updates or gradients can still be debated, especially in cases where sophisticated inference attacks are possible. This drives the necessity for integrating advanced privacy-enhancing techniques like Differential Privacy and Secure Multi-Party Computation within FL, creating a layered defense. Ethical considerations also remain crucial, including preventing bias in federated models if client populations are not representative, and safeguarding against data poisoning or model inversion attacks. Open-source initiatives, such as the Linux Foundation AI & Data's "Open Federated Learning (OBLR)" project, are working to standardize and secure FL implementations, fostering wider adoption and trust. FL is not just a technical solution; it's a strategic imperative for organizations navigating a data-rich, privacy-conscious world. Its continued evolution promises a future where AI's immense potential can be realized responsibly and ethically. Federated Learning Frameworks Comparison To put the concepts into practice, several robust Federated Learning frameworks have emerged, each with its strengths and target audience. Understanding their differences is key to selecting the right tool for your project.Feature / Framework TensorFlow Federated (TFF) Flower PySyft (OpenMined) NVIDIA Clara Federated LearningOrigin / Focus Google. Designed for scalable cross-device FL. ETH Zurich. General-purpose, highly flexible, framework-agnostic. OpenMined. Strong emphasis on privacy-preserving ML (DP, SMPC, HE). NVIDIA. Specific focus on medical imaging and healthcare AI.ML Frameworks TensorFlow PyTorch, TensorFlow, JAX (via custom strategies) PyTorch, TensorFlow, Keras PyTorchPrivacy Features Built-in DP (TensorFlow Privacy), secure aggregation (via TFF) Pluggable DP, secure aggregation, custom strategies for PETs Deep integration of DP, SMPC, HE. Core mission is privacy. Integrates DP, secure aggregation, homomorphic encryption.Scalability Excellent for large-scale cross-device (millions of clients) Highly scalable for various FL architectures Good for cross-silo, cross-device. Can handle large client bases. Tailored for cross-silo in medical domain (fewer, powerful clients).Ease of Use / API Steep learning curve, functional API Pythonic, intuitive, flexible API More complex due to advanced privacy features, evolving API Relatively straightforward for PyTorch users, specific to domain.Community Support Large, active community (Google-backed) Growing, active community, excellent documentation Active research community, strong focus on privacy research Enterprise-focused, strong support for healthcare partners.Key Use Cases Mobile device applications (Gboard), large distributed ML Research, prototyping, custom FL deployments, diverse ML Highly sensitive data (healthcare, finance), privacy research Medical image analysis, drug discovery, clinical insights.Advantages Highly optimized, robust for scale, strong DP integration Flexible, framework-agnostic, good for research & production Strongest native support for advanced PETs, cutting-edge privacy Optimized for medical data, integrates with NVIDIA hardware.Considerations TensorFlow-centric, complex API for beginners Requires careful implementation of PETs, less out-of-the-box Higher complexity, overhead for advanced PETs Domain-specific, limited to PyTorch.This comparison highlights that while all frameworks aim to facilitate federated learning, they each offer unique strengths, making the choice dependent on the project's specific requirements regarding scale, privacy guarantees, ML framework preference, and industry domain. Conclusion Federated Learning stands as a pivotal advancement in the ongoing quest to reconcile the immense potential of Artificial Intelligence with the foundational right to privacy. We've journeyed through its core mechanics, understanding how models learn collaboratively without ever centralizing sensitive raw data. We've explored the sophisticated architectures and communication protocols that enable decentralized intelligence, from countless mobile devices to powerful institutional silos. Crucially, we've delved into the advanced privacy-enhancing technologies like Differential Privacy and Secure Multi-Party Computation, which act as formidable shields against inference attacks, mathematically quantifying and fortifying data sovereignty. Yet, we've also acknowledged the formidable real-world gauntlet FL faces, from the pervasive challenge of data heterogeneity (non-IID distributions) to system-level complexities like device dropouts and communication constraints. The continued innovation in algorithms and robust aggregation methods is a testament to the community's commitment to overcoming these hurdles. The impact of FL is not theoretical; it's already reshaping industries from consumer technology and healthcare to finance, aligning AI development with stringent global privacy regulations like GDPR and HIPAA. Federated Learning is more than just a technique; it is a philosophy that champions responsible AI development. It promises a future where intelligence is truly collective, derived from a wealth of diverse data sources, yet meticulously respectful of individual and organizational privacy. The path ahead involves continuous research into scalability, fairness, and the integration of even more advanced cryptographic methods. As we push the boundaries of AI, Federated Learning will undoubtedly be at the forefront, ensuring that our pursuit of innovation does not come at the cost of our most fundamental digital rights. The revolution is here, and it’s federated. Lukas Richter, Senior Software Engineer, AI Researcher, Elite Tech Blogger#FederatedLearning #AI #MachineLearning #Privacy #Cybersecurity #DistributedSystems Related InsightsUSB-C: The Silent Revolution Powering Your Digital Life from Phones to Supercomputers The Evolution and Impact of the Smartphone Camera: How a Pocket Device Revolutionized Photography The Future is Illuminating: A Deep Dive into OLED Technology{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears?", "acceptedAnswer": { "@type": "Answer", "text": "Explore Federated Learning's transformative power, enabling robust AI models while rigorously protecting sensitive user data across industries." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Lukas Richter." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Claire Beaufort
- 12 Jul, 2026 11:38
Beyond the Veil: Unpacking AI's Black Box for Unprecedented Trust & Transparency with XAI
The pervasive integration of Artificial Intelligence into every facet of our lives, from personalized healthcare recommendations to autonomous vehicle navigation and critical financial decisions, has ushered in an era of unprecedented technological advancement. Yet, with this power comes a profound challenge: the "black box" problem. Many state-of-the-art AI models, particularly deep neural networks, operate with an opaque decision-making process, making it exceedingly difficult for humans to understand why a particular prediction or action was taken. This opacity breeds skepticism, hinders debugging, and poses significant ethical, legal, and safety risks. Enter Explainable AI (XAI) – a burgeoning field dedicated to making AI systems more transparent, interpretable, and understandable to humans. XAI is not merely an academic pursuit; it's a critical enabler for trust, accountability, and the responsible deployment of AI in regulated and high-stakes environments. As an AI researcher and senior software engineer, I've witnessed firsthand the paradigm shift XAI is bringing, transforming complex algorithms from mysterious oracles into collaborative decision-making partners. This article will delve deep into the technical intricacies of XAI, exploring its foundational principles, advanced methodologies, and the critical role it plays in securing our AI-driven future. We'll unpack the tools, techniques, and architectural considerations that empower us to demystify these powerful black boxes, offering practical insights and code examples to illuminate the path forward. Join me as we journey beyond mere prediction, towards profound understanding. The Imperative for Transparency: Why XAI is the Cornerstone of Trust in Modern AI The "black box" phenomenon in AI is no longer a fringe concern; it's a central debate shaping regulatory frameworks and industry best practices. While models like BERT, GPT-4, and advanced CNNs achieve astounding predictive accuracy, their internal mechanisms often remain inscrutable. This lack of transparency has tangible, often severe, consequences. Consider a diagnostic AI recommending a life-altering medical treatment without any justification, or an algorithmic trading system executing trades that cause significant market shifts without a clear rationale. In such scenarios, understanding "why" is not just desirable; it's absolutely essential for safety, ethical governance, and legal compliance. Regulations like the European Union's GDPR explicitly grant individuals a "right to explanation" for decisions made by algorithms that significantly affect them. The forthcoming EU AI Act and similar initiatives globally underscore the legal imperative for explainable systems, particularly in "high-risk" applications. From a debugging perspective, an inexplicable error in a complex deep learning model can be nearly impossible to trace and rectify without interpretable insights into its internal workings. Furthermore, without explainability, inherent biases hidden within training data can propagate and amplify, leading to discriminatory outcomes in areas like loan applications, hiring, or criminal justice. XAI provides the tools to audit models for fairness, uncover and mitigate biases, and ensure ethical decision-making. Researchers at institutions like IBM and Google have extensively documented the pitfalls of unexplainable AI, highlighting issues ranging from model drift to adversarial attacks that exploit latent vulnerabilities only detectable through robust explainability frameworks. The demand for XAI is driven by a confluence of regulatory pressure, ethical considerations, the practical needs of debugging and maintenance, and a fundamental human desire for understanding. Let's consider a simple conceptual example where an opaque model might pose issues. Imagine a credit scoring model. import pandas as pd from sklearn.ensemble import RandomForestClassifier# Sample data data = { 'income': [50000, 70000, 30000, 100000, 45000], 'credit_score_history': [700, 750, 550, 800, 600], 'loan_amount': [10000, 20000, 5000, 50000, 8000], 'employment_duration_years': [5, 10, 2, 15, 4], 'default': [0, 0, 1, 0, 1] # 0 = no default, 1 = default } df = pd.DataFrame(data)X = df[['income', 'credit_score_history', 'loan_amount', 'employment_duration_years']] y = df['default']# Train an opaque model (e.g., RandomForest) model = RandomForestClassifier(random_state=42) model.fit(X, y)# Predict for a new applicant new_applicant = pd.DataFrame([[60000, 680, 15000, 7]], columns=X.columns) prediction = model.predict(new_applicant) prediction_proba = model.predict_proba(new_applicant)print(f"Applicant prediction: {'Default' if prediction[0] == 1 else 'No Default'}") print(f"Default probability: {prediction_proba[0][1]:.2f}")# Without XAI, if this applicant is denied, we can't easily explain why. # Was it income? Credit history? Loan amount? A combination? # This is where XAI provides the 'why'.This simple RandomForest output gives a prediction, but no insight into why an applicant was deemed high-risk. This is the exact gap XAI aims to fill, making the decision-making process transparent and auditable.Dissecting the Black Box: Foundational Techniques for Local and Global Explainability XAI methodologies generally fall into two broad categories: local explanations, which clarify a single prediction, and global explanations, which provide an overarching understanding of the model's behavior across its entire dataset. Both are crucial for comprehensive model understanding and validation. Local Explainability focuses on understanding why a model made a specific prediction for a specific instance.LIME (Local Interpretable Model-agnostic Explanations): Pioneered by Ribeiro et al. (arXiv:1602.04938), LIME works by perturbing a single data instance and observing how the model's prediction changes. It then trains a simple, interpretable model (like a linear model or decision tree) locally around this perturbed instance. This surrogate model approximates the black box's behavior in that local region, providing feature importances for the specific prediction. LIME is "model-agnostic," meaning it can be applied to any black-box model. SHAP (SHapley Additive exPlanations): Based on cooperative game theory, SHAP values (Lundberg & Lee, arXiv:1704.03037) assign each feature an "importance value" for a particular prediction. These values represent the average marginal contribution of a feature value across all possible coalitions of features. SHAP offers a unified framework for interpreting any machine learning model, providing both local and global interpretability. Tools like shap on GitHub are widely adopted due to their theoretical soundness and flexibility.Global Explainability aims to understand the overall behavior of a model and how features generally influence predictions.Permutation Feature Importance (PFI): This method assesses the importance of a feature by calculating how much the model's performance decreases when the values of that feature are randomly shuffled (permuted). A significant drop in performance indicates a highly important feature. PFI is model-agnostic and gives a global view of feature impact. Partial Dependence Plots (PDPs) and Individual Conditional Expectation (ICE) plots: PDPs show the marginal effect of one or two features on the predicted outcome of a model. They average out the effects of all other features, providing a global understanding of the relationship between selected features and the prediction. ICE plots, a disaggregated version of PDPs, show the dependence for each instance individually, revealing heterogeneities that might be obscured by averaging.These techniques allow us to peer into the inner workings of complex models. Let's see how SHAP can be applied: import shap import pandas as pd from sklearn.ensemble import RandomForestClassifier from sklearn.model_selection import train_test_split# Load a classic dataset for demonstration from sklearn.datasets import load_iris iris = load_iris() X, y = iris.data, iris.target feature_names = iris.feature_names target_names = iris.target_names# Simplify to a binary classification problem for clarity: predict Versicolor vs. other y_binary = (y == 1).astype(int) # Split data X_train, X_test, y_train, y_test = train_test_split(X, y_binary, test_size=0.2, random_state=42)# Train a RandomForest model (our 'black box') model = RandomForestClassifier(random_state=42) model.fit(X_train, y_train)# Select a single instance from the test set for local explanation instance_to_explain = X_test[0] predicted_class = model.predict(instance_to_explain.reshape(1, -1))[0] print(f"Instance: {instance_to_explain}, Predicted Class (0=Not Versicolor, 1=Versicolor): {predicted_class}")# --- SHAP Explanation --- # 1. Create a SHAP Explainer object. For tree models, TreeExplainer is efficient. explainer = shap.TreeExplainer(model)# 2. Calculate SHAP values for the instance shap_values = explainer.shap_values(instance_to_explain)# shap_values will be a list of arrays for multi-output models; for binary it's [class0_values, class1_values] # We're interested in the values for the predicted class (class 1 in our binary case) shap_values_for_prediction = shap_values[predicted_class]print("\nSHAP values for the instance's prediction:") for i, feature in enumerate(feature_names): print(f" {feature}: {shap_values_for_prediction[i]:.4f}")# 3. Visualize the explanation (requires matplotlib) # shap.initjs() # For JS plots in notebooks # shap.force_plot(explainer.expected_value[predicted_class], shap_values_for_prediction, instance_to_explain, feature_names=feature_names) # For console/text-based output, we can interpret the values: # Positive SHAP value means the feature increases the prediction towards the positive class (Versicolor). # Negative SHAP value means the feature decreases the prediction towards the positive class.print("\nInterpretation:") print("The SHAP values indicate how much each feature contributed to pushing the model's output from the base value (average prediction) to the final prediction for this specific instance.") print(f"Features with higher absolute SHAP values had a stronger impact on the prediction of class '{predicted_class}'.")This SHAP example directly illustrates how features like petal length (cm) or sepal width (cm) specifically contributed to the model's classification of a single iris flower, allowing us to understand the individual prediction.Architecting for Clarity: Designing Inherently Interpretable AI Models While post-hoc explainability techniques like LIME and SHAP are powerful, an alternative strategy for achieving transparency is to design AI models that are inherently interpretable from the ground up. These models, by their very nature, allow direct insight into their decision-making logic without requiring additional tools or complex computations. This approach often trades some predictive power for superior transparency, a worthwhile compromise in many high-stakes applications where trust and audibility are paramount. Common Inherently Interpretable Models:Linear Regression and Logistic Regression: These foundational models express the relationship between features and the target variable through simple linear equations. The coefficients directly indicate the magnitude and direction of each feature's influence. For example, a positive coefficient in logistic regression means an increase in that feature increases the likelihood of the positive class. Decision Trees: These models mimic human decision-making with a series of if-then-else rules. The entire decision path for any prediction can be easily traced and visualized, making them highly transparent. While complex ensembles of trees (like Random Forests or Gradient Boosting) become less interpretable, individual decision trees are remarkably clear. Generalized Additive Models (GAMs): GAMs extend linear models by allowing for non-linear relationships between individual features and the target variable through smooth functions, while still maintaining additivity. This means the effect of each feature can be visualized independently, providing both flexibility and interpretability. Tools like interpret-ml on GitHub (from Microsoft Research) provide excellent implementations for GAMs and other interpretable models. Rule-Based Systems: These systems operate on a set of predefined rules (e.g., "IF age > 65 AND medical_condition = 'heart_disease' THEN recommended_treatment = 'cardiology_consult'"). Their logic is explicitly coded and therefore inherently transparent. Attention Mechanisms in Transformers: In natural language processing, Transformer models use attention mechanisms to weigh the importance of different words in a sequence when generating an output. These attention weights can be visualized, providing insight into which parts of the input the model focused on for a particular decision. While the overall Transformer is still complex, the attention map offers a critical window into its reasoning for specific outputs.The choice between an inherently interpretable model and a powerful black box with post-hoc XAI depends heavily on the specific use case, regulatory environment, and the acceptable trade-off between performance and transparency. For applications demanding absolute clarity, such as regulatory compliance in finance or safety-critical systems, an inherently interpretable architecture might be the preferred choice. Here’s a Python example demonstrating the inherent interpretability of a simple Decision Tree: from sklearn.tree import DecisionTreeClassifier, export_graphviz from sklearn.datasets import load_iris import graphviz import pandas as pd# Load Iris dataset iris = load_iris() X = pd.DataFrame(iris.data, columns=iris.feature_names) y = iris.target# Train a Decision Tree Classifier dt_model = DecisionTreeClassifier(max_depth=3, random_state=42) # Limit depth for visual clarity dt_model.fit(X, y)# Export the decision tree to a DOT format file dot_data = export_graphviz(dt_model, out_file=None, feature_names=iris.feature_names, class_names=iris.target_names, filled=True, rounded=True, special_characters=True) # Render the DOT file into a visual graph (requires graphviz to be installed) graph = graphviz.Source(dot_data) # graph.render("iris_decision_tree", view=True) # Uncomment to save and view the tree imageprint("Decision Tree Structure (truncated for console, full view requires graphviz rendering):") print("Root node condition:", dt_model.tree_.feature[0], " <= ", dt_model.tree_.threshold[0]) print("This output demonstrates the direct, rule-based nature of decision trees.") print("Each node represents a clear decision based on a feature value, making its logic inherently transparent.")The export_graphviz function directly provides the rules that the model uses to make decisions, which is a prime example of inherent interpretability.XAI in Action: Operationalizing Explanations within MLOps Pipelines Integrating XAI into research is one thing; operationalizing it within robust MLOps pipelines is quite another. For XAI to deliver its promise of trust and transparency in production systems, it must be seamlessly woven into the entire machine learning lifecycle, from data ingestion and model training to deployment, monitoring, and governance. This shift requires specific tools, architectural considerations, and a cultural commitment to responsible AI. Key Integration Points in MLOps:Model Development & Experimentation: During this phase, XAI tools like LIME, SHAP, and permutation importance are invaluable for model debugging, feature selection, and understanding potential biases before deployment. Data scientists use these explanations to refine models, ensure fairness, and build confidence in their design choices. Many MLOps platforms, such as MLflow, now integrate artifacts specifically for storing explanations alongside models. Pre-deployment Validation & Auditing: Before a model goes live, its explanations are critical for validation. Compliance teams can use XAI outputs to verify regulatory adherence, while domain experts can cross-check if the model’s reasoning aligns with human intuition or established domain knowledge. This can involve generating comprehensive explanation reports and storing them with model versions. Deployment as a Service: XAI capabilities can be deployed as dedicated microservices alongside the predictive model. When a prediction request comes in, the XAI service can generate an explanation on demand, either in real-time or asynchronously. This is crucial for applications requiring immediate justification (e.g., fraud detection, medical diagnosis). Continuous Monitoring & Retraining: Post-deployment, XAI plays a vital role in detecting model drift or unexpected behavior. If explanations start to change significantly or indicate reliance on irrelevant features, it signals a potential problem, triggering alerts for investigation or retraining. Platforms like IBM AI Explainability 360 (AIX360) and Microsoft Azure Machine Learning's Responsible AI dashboard offer integrated capabilities for monitoring explanations over time. Feedback Loops & Human-in-the-Loop Systems: Explanations facilitate better human-AI collaboration. Users can understand why a recommendation was made, provide informed feedback, and potentially correct the system. This feedback loop is essential for continuous improvement and building long-term trust.Consider a microservice architecture where an XAI component provides explanations for a deployed model. This might involve a Docker Compose setup for local development or a Kubernetes deployment in production. # docker-compose.yml for a local MLOps setup with XAI version: '3.8' services: model_service: build: context: ./model_api dockerfile: Dockerfile ports: - "8000:8000" environment: - MODEL_PATH=/app/model.pkl # Path to the pre-trained model volumes: - ./model_api:/app networks: - ai_network xai_service: build: context: ./xai_api dockerfile: Dockerfile ports: - "8001:8001" environment: - MODEL_SERVICE_URL=http://model_service:8000/predict volumes: - ./xai_api:/app networks: - ai_network depends_on: - model_servicenetworks: ai_network: driver: bridgeIn this docker-compose.yml, model_service hosts the main AI model, while xai_service provides explanations by querying the model service and applying XAI techniques (e.g., LIME or SHAP). This modular approach ensures that the explanation logic is decoupled, maintainable, and scalable, fitting perfectly within modern MLOps paradigms. The xai_api directory would contain a Python Flask/FastAPI app that takes input, sends it to model_service for a prediction, then generates and returns an explanation based on that input and prediction.The Horizon of Trust: Advanced Concepts and Future Challenges in Explainable AI The field of XAI is rapidly evolving, driven by ongoing research and the increasing complexity of AI systems. Beyond current techniques, several advanced concepts are emerging that promise to push the boundaries of interpretability, addressing both the technical nuances and the human factors involved in understanding AI. Emerging Trends:Causal XAI: Most current XAI methods identify correlations – which features are important for a prediction. Causal XAI (e.g., Pearl's causality framework applied to ML) aims to uncover why a feature causes a certain outcome. This moves beyond mere importance to a deeper understanding of the underlying causal mechanisms, which is critical for interventions and counterfactual explanations ("what if" scenarios). Recent arXiv papers delve into this, proposing frameworks that integrate causal inference models with traditional ML. Human-Centered XAI (HCAI): The ultimate goal of XAI is to help humans understand AI. HCAI focuses on tailoring explanations to the specific needs, expertise, and cognitive biases of different stakeholders – be it a data scientist, a domain expert, a regulator, or a lay user. This involves user studies, cognitive science, and human-computer interaction principles to design effective, actionable, and trustworthy explanations. Multimodal XAI: As AI models increasingly process and integrate data from multiple modalities (e.g., text, images, audio, tabular data), XAI must evolve to provide coherent, integrated explanations across these diverse inputs. For instance, explaining why a medical AI diagnosed a condition based on both a patient's textual history and an MRI scan. Adversarial Robustness and XAI: Explanations themselves can be manipulated or misleading. Research is exploring how to make XAI methods robust against adversarial attacks, ensuring that explanations are genuine and reliable. Conversely, explanations can help identify vulnerabilities in models, making them more robust. Concept-Based Explanations: Instead of just feature importance, some XAI approaches focus on identifying and explaining which human-understandable "concepts" (e.g., "stripes" in an image classifier for zebras) influence a model's decision, making explanations more intuitive.Lingering Challenges:Quantifying Explanation Quality: How do we objectively measure if one explanation is "better" than another? Metrics for fidelity (how accurately the explanation reflects the black box) and comprehensibility (how well humans understand it) are still under active development. Scalability: Generating explanations for massive, high-dimensional datasets or extremely complex models can be computationally expensive and time-consuming, hindering real-time applications. The "Trade-off" Conundrum: The inherent tension between model accuracy and interpretability often persists. While XAI aims to mitigate this, achieving both simultaneously at peak levels remains a significant challenge. Misleading Explanations: A poorly designed or maliciously crafted explanation can be more dangerous than no explanation at all, providing a false sense of security or justification. Ensuring the trustworthiness of explanations is paramount.The future of XAI lies in developing methods that are not only technically sound but also practically deployable, scalable, and genuinely useful to a diverse range of human users. It's a journey from simply knowing what an AI predicts to truly understanding why, ushering in an era of more responsible, transparent, and trustworthy artificial intelligence. This is not just about building better algorithms; it's about building better human-AI partnerships. # Conceptual Python snippet for a Causal XAI setup (simplified for illustration) # This code aims to demonstrate the concept of causal reasoning in a simple scenario. # Real causal inference requires careful design, domain knowledge, and specific libraries (e.g., DoWhy, CausalPy).import numpy as np import pandas as pd from sklearn.linear_model import LogisticRegression# Simulate data with a known causal structure # Assume 'feature_A' causally influences 'feature_B', which then influences 'target'. # And 'feature_C' directly influences 'target'.np.random.seed(42) num_samples = 1000feature_A = np.random.normal(loc=10, scale=2, size=num_samples) # e.g., Education level feature_B = feature_A * 0.5 + np.random.normal(loc=0, scale=1, size=num_samples) # e.g., Income, causally linked to Education feature_C = np.random.normal(loc=5, scale=1.5, size=num_samples) # e.g., Skill level, independent of A/B# Target: Probability of getting a job offer # Assume: Higher income (B) and higher skill (C) increase job offer probability. # A also indirectly affects target via B. prob_target = 1 / (1 + np.exp(-(0.2 * feature_B + 0.5 * feature_C - 5))) target = (np.random.rand(num_samples) < prob_target).astype(int)df_causal = pd.DataFrame({ 'feature_A': feature_A, 'feature_B': feature_B, 'feature_C': feature_C, 'target': target })# Train a simple model to predict 'target' X_causal = df_causal[['feature_A', 'feature_B', 'feature_C']] y_causal = df_causal['target']model_causal = LogisticRegression(solver='liblinear', random_state=42) model_causal.fit(X_causal, y_causal)print("Logistic Regression Coefficients:") for i, feature in enumerate(X_causal.columns): print(f" {feature}: {model_causal.coef_[0][i]:.4f}")print("\nCausal XAI Insight (Conceptual):") print("Traditional XAI (like feature coefficients here) shows feature_A has a positive correlation with target.") print("However, Causal XAI would aim to show that feature_A's *direct causal effect* on target is negligible,") print("and its influence is primarily *mediated* through feature_B.") print("This distinction is crucial for understanding true drivers and for policy interventions.") print("For instance, increasing 'feature_A' might only benefit 'target' if it successfully boosts 'feature_B'.")This conceptual example highlights that a simple coefficient (correlation) doesn't always reveal the underlying causal chain. Causal XAI aims to unravel these deeper relationships for more robust and trustworthy explanations. XAI Methodologies: A Comparative Overview Understanding the strengths and weaknesses of different XAI approaches is crucial for selecting the right tool for a specific task. Here's a brief comparative table summarizing key methodologies discussed:Methodology Type of Explanation Model-Agnostic/Specific Pros Cons Best Use CasesLIME Local Model-Agnostic Provides intuitive, local explanations; easy to understand for diverse audiences. May not be stable (small perturbations can lead to different explanations); can be computationally intensive for complex models; local fidelity doesn't guarantee global understanding. Explaining individual predictions for non-technical users; debugging specific errors.SHAP Local & Global Model-Agnostic Theoretically sound (game theory based); unified framework for various models; provides both local and global insights. Computationally expensive for many instances or features (especially exact SHAP); can be difficult to interpret the exact meaning of a SHAP value without context. Auditing model fairness and bias; comprehensive understanding of feature contributions; regulatory compliance.Permutation Feature Importance (PFI) Global Model-Agnostic Simple to implement and understand; highlights the most impactful features globally. Only provides global insights; doesn't explain individual predictions; can be misleading if features are highly correlated; computationally expensive if many permutations are run. Feature selection; model debugging at a global level; understanding overall model behavior.Partial Dependence Plots (PDP) Global Model-Agnostic Visualizes marginal effect of one or two features on prediction; intuitive for understanding trends. Assumes feature independence (can be misleading if strong correlations exist); only shows average effect (hides individual variations). Understanding general trends and relationships between features and predictions.Individual Conditional Expectation (ICE) Local (aggregated) Model-Agnostic Disaggregates PDPs, revealing individual instance variations and heterogeneity. Can become cluttered with too many instances; still assumes feature independence for its interpretation; can be noisy. Identifying heterogeneous effects not visible in PDPs; deeper individual trend analysis.Decision Trees Inherently Interpretable Model-Specific Directly human-readable rules; easy to visualize decision paths; no post-hoc explanation needed. Can be prone to overfitting; performance often lower than complex black-box models; complex trees become difficult to interpret. Simple, auditable decisions in low-stakes or regulatory environments; baseline interpretability.Generalized Additive Models (GAMs) Inherently Interpretable Model-Specific Provides interpretable non-linear relationships for each feature independently; better predictive power than linear models. Interpretation of smooth functions can be slightly less intuitive than linear coefficients; computational complexity increases with number of features and basis functions. Predictive tasks requiring non-linear relationships with high interpretability; medical applications.This table provides a concise reference for navigating the XAI landscape, emphasizing that the "best" method often depends on the specific requirements of the AI application and the audience for the explanation. Conclusion & The Path Forward to Trustworthy AI The journey into Explainable AI is not merely a technical endeavor; it is a fundamental shift towards building trustworthy, accountable, and ethical AI systems. We've explored the profound imperative for transparency, delved into the powerful techniques like LIME and SHAP that demystify individual predictions, examined the architectural elegance of inherently interpretable models, and discussed how to operationalize XAI within robust MLOps pipelines. From the regulatory demands of GDPR to the critical need for bias detection and model debugging, XAI stands as the indispensable bridge between complex algorithms and human understanding. As an AI researcher, I'm particularly excited by the emerging frontiers of XAI – causal inference, human-centered design, and multimodal explanations – which promise to unlock even deeper levels of understanding and collaboration between humans and AI. While challenges remain, notably in quantifying explanation quality, ensuring scalability, and guarding against misleading interpretations, the trajectory is clear: XAI will become an increasingly integral part of every responsible AI development lifecycle. The future of AI is not just about intelligence; it's about intelligent systems we can trust. By embracing Explainable AI, we empower developers to build better, fairer models; we equip regulators to ensure compliance; and most importantly, we enable end-users to understand, question, and ultimately, confide in the AI that shapes their world. This commitment to transparency is how we truly unlock the full, benevolent potential of artificial intelligence.#ExplainableAI #XAI #AIEthics #MachineLearning #TrustworthyAI #MLOps #AIResearch Related InsightsLow-Code/No-Code Platforms: Empowering Citizen Developers and Accelerating Innovation Energy-Harvesting IoT: Powering Sensors Without Batteries Using Ambient Intelligence and Self-Sustaining Circuits Beyond the Horizon of 5G: Unlocking the Secrets of 6G Wireless Standards{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Beyond the Veil: Unpacking AI's Black Box for Unprecedented Trust & Transparency with XAI?", "acceptedAnswer": { "@type": "Answer", "text": "Explore Explainable AI (XAI) with Claire Beaufort. Dive deep into methods, tools, and real-world applications demystifying complex AI for trust, compliance, and innovation." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Beyond the Veil: Unpacking AI's Black Box for Unprecedented Trust & Transparency with XAI?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Claire Beaufort." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
Imagine a smart home that anticipates your needs, understands complex voice commands, and recognizes your face at the door—all without sending a single byte of your personal data to a corporate server. Until recently, this level of intelligence required the massive computing power of cloud data centers. But the rapid miniaturization of neural processing units (NPUs) and the optimization of open-source models have ushered in a new era: The Edge AI Smart Home. As a robotics engineer with a background in autonomous systems, I view the home as the ultimate localized robotic environment. Relying on cloud infrastructure for critical home operations is not just a privacy risk; it's an architectural flaw. #Robotics #AutonomousVehicles In this comprehensive, step-by-step guide, we will explore how to architect, hardware-provision, and deploy a privacy-first smart home using Edge AI hubs. We will cut the cord to the cloud and bring the brain of the operation directly into your living room. #EdgeAI #IoT What is Edge AI in the Context of a Smart Home? "Edge computing" means processing data at or near the source of data generation, rather than sending it across the internet to a centralized cloud. When we add "AI" to the mix, we are talking about running machine learning models—such as computer vision for security cameras or Large Language Models (LLMs) for voice assistants—locally on hardware physically located inside your home. The Three Pillars of Edge AI Privacy:Zero Data Exfiltration: Your audio recordings, video feeds, and daily routines never leave your local area network (LAN). Infinite Uptime: Because processing is local, your voice commands and automations work flawlessly even during internet outages. Instant Latency: Processing an image or a voice command locally takes milliseconds, compared to the round-trip latency of cloud APIs.Step 1: Choosing the Right Hardware for the Hub You cannot run advanced AI models on a standard $30 smart hub. You need compute power, specifically hardware optimized for AI inference. The Entry Level: Raspberry Pi 5 with an AI Accelerator The Raspberry Pi 5 is incredibly capable, but for Edge AI, you need to pair it with an accelerator like the Google Coral USB Accelerator or a Hailo-8 M.2 module. These specialized chips (TPUs/NPUs) can perform trillions of operations per second (TOPS), making them perfect for local object detection on camera feeds. The Power User: The N100 Mini PC or Mac Mini M-Series For running local LLMs (like Llama 3 8B or Mistral) to process natural language voice commands locally, you need significant RAM and a powerful CPU/GPU. A refurbished Mac Mini M1/M2 (due to its unified memory architecture) or an Intel N100-based Mini PC running Proxmox is the sweet spot for budget-conscious edge computing in 2026. Step 2: The Operating System - Proxmox and Home Assistant OS To maximize efficiency, we will use a hypervisor. Proxmox Virtual Environment (VE) allows you to split your Mini PC into multiple isolated virtual machines (VMs). Install Proxmox on your Mini PC via a bootable USB. Deploy Home Assistant OS (HAOS) as a primary Virtual Machine. HAOS will act as the central nervous system connecting all your IoT devices.Terminal Command: HAOS Proxmox Installation Script The community has created brilliant automation scripts for this. Log into your Proxmox web shell and execute: bash -c "$(wget -qLO - https://github.com/tteck/Proxmox/raw/main/vm/haos.sh)"Follow the prompts to allocate RAM (minimum 4GB) and storage (minimum 32GB). Within minutes, your local Home Assistant instance will be running. Step 3: Local Computer Vision with Frigate NVR Cloud cameras like Ring or Nest upload your continuous video feeds to external servers, analyze them for human movement, and send you a notification. We will replace this with Frigate, an open-source Network Video Recorder (NVR) built specifically for real-time local object detection. Frigate integrates directly into Home Assistant and utilizes the Google Coral TPU (which you plugged into your Mini PC) to analyze RTSP video streams from local, offline IP cameras (like Reolink or Amcrest). Sample Frigate Configuration (frigate.yml): mqtt: host: 192.168.1.100 detectors: coral: type: edgetpu device: usb cameras: front_door: ffmpeg: inputs: - path: rtsp://admin:password@192.168.1.50:554/h264Preview_01_main roles: - detect - rtmp detect: width: 1920 height: 1080 objects: track: - person - dog - carBecause the Coral TPU runs the inference locally, the moment a person steps onto your porch, the AI detects it in milliseconds, triggers a Home Assistant automation to turn on the porch light, and sends a snapshot to your phone via an encrypted local push notification—zero cloud required. #DataSecurityStep 4: Local Voice Processing (The Holy Grail) Voice assistants are the biggest privacy offenders. To replace them, we use the Home Assistant Assist pipeline, powered by local Whisper (for Speech-to-Text) and Piper (for Text-to-Speech). If you have a powerful enough Edge Hub (like an M2 Mac Mini or a machine with an Nvidia RTX GPU), you can route the transcribed text through a local LLM using Ollama. Running Ollama locally: # Install Ollama on your Linux VM curl -fsSL https://ollama.com/install.sh | sh# Pull a lightweight, highly capable model ollama run llama3:8bBy connecting Home Assistant to your local Ollama instance via the "Extended OpenAI Conversation" integration (pointing the API URL to http://localhost:11434/v1), your home becomes truly intelligent. You don't have to say rigid commands like "Turn on living room light." You can say, "It's getting a bit dark in here, and I want to read a book." Your local Edge AI processes the intent, understands you are in the living room, realizes reading requires light, and autonomously turns on the reading lamp. Step 5: Network Isolation (VLANs) The final, and most crucial, step in a privacy-first smart home is network isolation. Even if you don't use cloud services, many cheap IoT devices (like smart plugs or Wi-Fi bulbs) have hardcoded telemetry that constantly tries to "phone home" to servers in foreign countries. You must configure your router (using pfSense, OPNsense, or Unifi) to create an IoT VLAN.Move all IoT hardware to this separate Wi-Fi network. Create a firewall rule that Blocks all traffic from the IoT VLAN to the WAN (Internet). Create a rule that allows your Home Assistant server to initiate communication with the IoT VLAN.Now, your devices are trapped. They cannot spy on you, they cannot update their firmware without your permission, and they cannot be compromised by external botnets. They exist purely to serve your local Edge AI hub. The Future is Local Building an Edge AI smart home requires more upfront effort than simply plugging in a Google Nest Hub. It requires tinkering with Docker containers, writing YAML, and managing subnets. However, the reward is absolute digital sovereignty. Your home becomes a fortress of privacy. Your automations execute with lightning speed. And you are utilizing cutting-edge neural processing technology exactly where it belongs: at the edge, serving you, and only you. Welcome to the true definition of a "Smart" Home.Have questions about hardware requirements or Proxmox setups? Let me know in the comments, and I'll help you architect your local edge server! Related InsightsAlgorithmic Sovereignty: Deconstructing the DAO Paradox in On-Chain Governance Revolutionizing Autonomous Task Execution: The Evolution of Large Action Models (LAMs) Holographic Displays: The Silent Revolution Reshaping AR/VR, 3D Visualization, and Human-Computer Interaction{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of How to Set Up a Privacy-First Smart Home Using Edge AI Hubs?", "acceptedAnswer": { "@type": "Answer", "text": "Learn how to build a 100% private smart home utilizing Edge AI hubs, local LLMs, and secure hardware without relying on external cloud servers." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on How to Set Up a Privacy-First Smart Home Using Edge AI Hubs?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Kaan Demir." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Alexander Vance
- 12 Jul, 2026 10:05
Top 10 Agentic AI SaaS Tools Transforming Developer Workflows in 2026
The software development lifecycle has undergone a seismic shift. If 2023 was the year of "Generative AI" acting as a smart autocomplete, 2026 is undoubtedly the era of Agentic AI. We have moved past prompting chat interfaces to write isolated functions; today, developers manage autonomous AI agents that proactively debug, refactor entire codebases, manage pull requests, and orchestrate complex deployments across multiple SaaS platforms. As an AI architect who has watched this evolution closely from within the walls of Silicon Valley, I can confirm that "Agentic AI" is not just a buzzword—it is a fundamental restructuring of how engineering teams operate. According to recent papers published on arXiv, development teams utilizing autonomous agents report a 40% reduction in time-to-merge for complex pull requests. #ArtificialIntelligence #SoftwareEngineering In this comprehensive guide, we will explore the top 10 Agentic AI SaaS tools that are fundamentally transforming developer workflows, complete with case studies and implementation examples. What makes an AI "Agentic"? Before diving into the tools, we must define the term. A standard Large Language Model (LLM) is reactive: you ask a question, it provides an answer. An Agentic AI is proactive and goal-oriented. It possesses the following capabilities:Tool Use: It can interact with external APIs, run terminal commands, and query databases. Reasoning & Planning: It breaks down complex, ambiguous goals into step-by-step execution plans. Memory: It remembers context across long sessions, maintaining an understanding of the entire repository architecture. Autonomy: It can execute loops, correct its own errors when a script fails, and continue working without human intervention until the primary goal is achieved.Let's look at the SaaS platforms leading this revolution.1. Devin by Cognition (Enterprise Tier) Devin remains the gold standard for autonomous software engineering. Unlike IDE plugins, Devin operates in its own secure cloud environment equipped with a terminal, browser, and code editor. Case Study: Legacy Migration A startup recently used Devin to migrate a monolithic Node.js backend to a serverless Cloudflare Workers architecture. Instead of writing code line-by-line, the lead engineer provided Devin with the GitHub repository URL and a prompt: "Migrate the /api/users endpoints to Cloudflare Workers using Hono.js. Ensure all PostgreSQL queries are compatible with Prisma Accelerate." Devin autonomously cloned the repo, read the documentation for Hono.js, rewrote the routes, installed the necessary dependencies via npm, ran the local test suite, observed a failing test due to a missing environment variable, fixed it, and submitted a pristine Pull Request. #TechStartups 2. GitHub Copilot Workspace GitHub has evolved Copilot from an IDE autocomplete tool into a full-fledged agentic workspace. Copilot Workspace allows developers to start a project from a GitHub Issue. The AI reads the issue, proposes a specification, generates a step-by-step plan, and executes the code changes across multiple files simultaneously. Terminal Integration Example: You can now ask the GitHub CLI to execute agentic tasks. gh copilot execute "Find all instances of the deprecated moment.js library in the frontend directory and replace them with date-fns, then run the linter and fix any formatting issues."The agent handles the regex searching, the AST parsing, the dependency replacement, and the execution of npm run lint --fix. 3. AutoGPT Pro (SaaS Edition) Originally an open-source experiment, AutoGPT has matured into a robust SaaS platform for developers. It excels at workflow automation that spans outside the codebase. For instance, AutoGPT Pro can be wired to your Jira and Slack. When a critical bug is reported in Jira, the agent reads the stack trace, pulls the relevant logs from Datadog via API, identifies the offending commit in GitLab, writes a patch, and posts a summary of the fix in the engineering Slack channel, awaiting human approval to merge. #AIAutomation 4. Cursor IDE (Agent Mode) While technically an editor (a fork of VS Code), Cursor's new "Agent Mode" functions as a SaaS backend that deeply understands your local workspace. It doesn't just suggest code; it navigates your file tree, reads your terminal output, and understands your project's specific conventions. If you run a build command and it fails with a cryptic Webpack error, you don't need to copy-paste the error. You simply press Cmd+K and type "Fix the build." The Cursor Agent reads the terminal output, identifies the conflicting dependency, updates your package.json, runs npm install, and restarts the dev server. 5. Sweep AI Sweep AI focuses exclusively on eliminating technical debt and handling minor feature requests. You install it as a GitHub application. When you create an issue with the label sweep, the AI agent wakes up, reads the issue, branches the code, writes the feature, and opens a PR. Implementation Step: To integrate Sweep into your CI/CD pipeline, you simply configure a sweep.yaml in your repository root defining the rules it must follow (e.g., "Always use TypeScript strict mode," "Never modify the core database schema without adding a migration file").6. Vercel v0 (Agentic Iteration) Vercel's v0 started as a UI generator, but its 2026 iteration acts as an agentic frontend developer. You provide it with a Figma link or a textual description, and it generates production-ready React/Next.js code using Tailwind CSS and Shadcn UI components. What makes it agentic is its ability to iterate. You can tell it, "The login form looks good, but wire it up to our Supabase authentication backend and handle the error states." The agent writes the API routes, manages the client-side state, and integrates the authentication tokens autonomously. #WebDevelopment 7. Superblocks AI Agent Superblocks is a platform for building internal tools. Their embedded AI agent allows non-technical founders or operations teams to build complex admin panels simply by describing the data flow. You can instruct the agent: "Create a dashboard that pulls user data from PostgreSQL, shows their subscription status from Stripe, and adds a button to issue a refund." The agent generates the SQL queries, configures the REST API calls to Stripe, and wires the UI components together, drastically reducing the burden on the core engineering team. 8. CodeQL Agent (by GitHub) Security testing has moved from passive scanning to active remediation. The CodeQL Agent doesn't just flag a SQL injection vulnerability; it autonomously generates the patch to fix it. Using Static Application Security Testing (SAST) principles, when a vulnerability is detected during a CI run, the agent opens a PR containing the exact code changes needed to sanitize the inputs, accompanied by an explanation of the exploit it prevented. #CyberSecurity 9. Supabase Studio AI Database administration is inherently risky, but Supabase has integrated an agentic assistant that acts as a senior DBA. If a specific query is slowing down your application, the agent analyzes the query execution plan via PostgreSQL's EXPLAIN ANALYZE and automatically suggests (or safely applies) the optimal composite indices to resolve the bottleneck. -- The agent autonomously identifies missing indices based on production telemetry CREATE INDEX CONCURRENTLY idx_users_email_status ON users (email, status);10. LangSmith by LangChain If you are building AI agents, LangSmith is the essential SaaS tool for debugging them. It provides unprecedented visibility into the thought process of your LLMs. You can trace exactly which external tools your agent decided to use, what data it retrieved, and why it made specific decisions. It is the ultimate observability platform for the new era of agentic software. The Future of the "10x Developer" The concept of the "10x Developer" has always been somewhat mythical. However, Agentic AI is turning this myth into a measurable reality. A single developer, armed with tools like Devin, Cursor, and Sweep AI, can now architect, execute, and maintain systems that previously required an entire pod of engineers. We are transitioning from being code writers to being code reviewers and system architects. The value of an engineer in 2026 is no longer defined by how fast they can type boilerplate React code, but by how effectively they can orchestrate an army of autonomous AI agents to build scalable, secure, and robust software architectures. The companies that embrace this paradigm shift will ship faster and dominate their markets. Those that insist on manual, legacy workflows will simply be left behind. Welcome to the future of development.Which Agentic AI tool has had the biggest impact on your workflow? Drop your experiences and recommendations in the comments below! Related InsightsBeyond the Horizon of 5G: Unlocking the Secrets of 6G Wireless Standards Data Mesh Architecture: Decentralizing Data Ownership for Scalability Data Governance in the Age of AI: Ensuring Ethical and Compliant Data Use{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Top 10 Agentic AI SaaS Tools Transforming Developer Workflows in 2026?", "acceptedAnswer": { "@type": "Answer", "text": "Discover how autonomous Agentic AI SaaS platforms are revolutionizing software development, automating GitHub workflows, and rewriting the rules of coding." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Top 10 Agentic AI SaaS Tools Transforming Developer Workflows in 2026?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Alexander Vance." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Lukas Richter
- 12 Jul, 2026 10:00
Home Assistant vs. Google Home in 2026: Why Local Control Wins for Privacy
In an era where every lightbulb, thermostat, and refrigerator demands a Wi-Fi connection and a cloud account, the smart home dream has slowly morphed into a privacy nightmare for many. We've reached 2026, and the landscape of home automation is fractured. On one side, we have tech behemoths like Google and Amazon pushing seamless, cloud-dependent ecosystems. On the other, a rapidly growing coalition of "Geeks," DIY enthusiasts, and privacy advocates championing absolute local control. This isn't just a debate about which voice assistant understands your accent better; it’s a fundamental battle over data sovereignty, latency, and the longevity of the hardware you own. If you've ever experienced the frustration of your smart lights failing because your internet went down, or felt a chill down your spine reading the privacy policy of a $15 smart plug, this deep dive is for you. Today, we are putting Home Assistant, the open-source titan of local control, head-to-head with Google Home, the ubiquitous cloud-based giant. We will explore why local control is winning the privacy war, how to transition your setup, and why relying on the cloud in 2026 is a significant security risk. #SmartHome #CyberSecurity #LocalControl The Fundamental Flaw of the Cloud-Dependent Smart Home To understand why a mass exodus toward local control is happening, we first need to dissect how ecosystems like Google Home, Alexa, and SmartThings (historically) operate. When you ask Google Assistant to turn on the living room lights, here is the typical journey of that command:Your voice is recorded by the smart speaker. The audio file is encrypted and sent to Google's cloud servers. Natural Language Processing (NLP) models in the cloud transcribe and understand the command. Google's server sends a command to the cloud server of your smart light manufacturer (e.g., Tuya, Philips Hue cloud, or TP-Link). The manufacturer's server sends a command back down to your router. Your router tells the lightbulb to turn on.This entire process usually takes less than a second, which is a marvel of modern engineering. However, it introduces three massive points of failure and concern: Latency, Reliability, and Privacy. Latency and Reliability: The "Internet Down" Scenario If your internet Service Provider (ISP) has an outage, your Google Home becomes a very expensive, albeit aesthetically pleasing, paperweight. The lights won't turn on via voice, routines will fail to execute, and your smart home effectively devolves into a "dumb" home. Furthermore, even with a fast connection, round-trip cloud communication introduces micro-latencies that make the smart home feel sluggish compared to a traditional physical switch. The Privacy Paradigm: Who Owns Your Habits? Every time a cloud API is invoked, data is logged. Google, Amazon, and third-party device manufacturers know when you wake up (because you turned on the bathroom light), when you leave for work (because the smart lock engaged), and when you go to bed. In a recent case study analyzing IoT traffic, researchers found that the average cloud-connected smart home pings external servers over 3,000 times a day, often sending telemetry data that the user never explicitly consented to sharing. In a world increasingly wary of data harvesting, handing over the intimate details of your daily routine to advertising companies is a tough pill to swallow. #DataPrivacy Enter Home Assistant: The Local Control Revolution Home Assistant (HA) flips the script entirely. It is an open-source home automation platform designed to run locally on your hardware—usually a Raspberry Pi, an Intel NUC, or a repurposed thin client. With Home Assistant, the brain of your smart home lives inside your house, not in a data center in California. How Local Control Works When you use a local Zigbee switch to trigger a smart light via Home Assistant:The switch sends a local Zigbee radio signal to your Home Assistant hub. Home Assistant processes the automation rule internally. Home Assistant sends a local network command (or another Zigbee signal) to the lightbulb.Result: Near-zero latency, absolute privacy, and it works perfectly even if your fiber optic cable is accidentally severed by a backhoe down the street. Step-by-Step: Deploying Home Assistant via Docker For tech enthusiasts, running Home Assistant via Docker on a local Linux server (like Ubuntu or Debian) offers the ultimate flexibility. Here is a quick case study on how to deploy it using docker-compose. Prerequisites: A machine running Linux with Docker and Docker Compose installed.Create the configuration directory: mkdir -p /opt/homeassistant/config cd /opt/homeassistantCreate the docker-compose.yml file: Using your favorite text editor (like nano or vim), create the following configuration: version: '3' services: homeassistant: container_name: homeassistant image: "ghcr.io/home-assistant/home-assistant:stable" volumes: - /opt/homeassistant/config:/config - /etc/localtime:/etc/localtime:ro - /run/dbus:/run/dbus:ro restart: unless-stopped privileged: true network_mode: hostDeploy the stack: docker-compose up -dWithin seconds, Home Assistant will boot up locally. You can access the interface by navigating to http://<YOUR_SERVER_IP>:8123 in your web browser. No cloud accounts, no forced updates, no data harvesting. Just you and your hardware. Matter and Thread: The Great Equalizer of 2026 We cannot discuss smart homes in 2026 without addressing the Matter protocol. Matter was supposed to be the "one ring to rule them all," allowing Apple, Google, Amazon, and SmartThings ecosystems to play nicely together over the local network using IPv6 and Thread (a low-power mesh networking technology). While Google Home has adopted Matter, it still uses it primarily to bridge devices into its cloud ecosystem for advanced automation and voice processing. Home Assistant, however, leverages Matter and Thread to their absolute fullest potential: pure, unadulterated local control. By plugging a SkyConnect USB dongle into your Home Assistant server, you can pair Matter-over-Thread devices completely offline. If a company goes bankrupt tomorrow and shuts down its servers, your Matter devices connected to Home Assistant will not care. They will continue to function flawlessly. This concept, known as "Future-Proofing," is a massive driving force behind the adoption of open-source automation.Advanced Automation: YAML vs. Google Routines Google Home's automation interface is designed for the masses. It is incredibly user-friendly but severely limited. You can create routines like "If it's 8:00 AM, turn on the coffee maker," but complex conditional logic is difficult or impossible. Home Assistant caters to developers and power users. You can write automations in the UI, or drop into YAML configuration for infinite possibilities. Case Study: The "Movie Time" Automation Let's say you want an automation that does the following: When I start playing a movie on Plex, IF the sun has set, dim the living room lights to 20%, turn off the kitchen lights, and lower the smart blinds. In Google Home, this is a nightmare to configure reliably. In Home Assistant, it's a beautifully simple YAML block: alias: "Cinema Mode: Plex Started" description: "Dim lights when a movie starts, only at night." trigger: - platform: state entity_id: media_player.living_room_plex to: "playing" condition: - condition: state entity_id: sun.sun state: "below_horizon" action: - service: light.turn_on target: entity_id: light.living_room_hue data: brightness_pct: 20 transition: 3 - service: light.turn_off target: entity_id: light.kitchen_main - service: cover.close_cover target: entity_id: cover.living_room_blinds mode: singleThis level of granular control is why developers and tech professionals are abandoning restricted ecosystems. Home Assistant allows you to integrate APIs from your Tesla, your solar inverter, your router's bandwidth monitor, and your weather station, combining them into unified, highly complex logic engines. The Security Audit: Why Local Hubs Win From a cybersecurity perspective, exposing every light switch to the public internet is a massive attack surface. Botnets like Mirai historically targeted cheap IoT devices with hardcoded cloud credentials. By utilizing a local hub like Home Assistant, you can implement a "VLAN (Virtual Local Area Network) Quarantine" strategy. Step-by-Step: Securing IoT DevicesCreate an IoT VLAN on your router (e.g., Unifi, pfSense, or Mikrotik). Connect all your Wi-Fi smart devices (cameras, vacuums, plugs) to this specific VLAN. Set Firewall Rules: Block the IoT VLAN from accessing the WAN (Internet) completely. Allow your Home Assistant server (which sits on a trusted management VLAN) to establish one-way communication into the IoT VLAN to send commands.By doing this, your cheap smart plugs cannot "phome home" to servers in foreign countries, nor can they be compromised remotely from the internet. They are completely isolated, yet fully functional through your local Home Assistant instance. Google Home simply cannot facilitate this level of enterprise-grade network security because it requires those devices to have WAN access to function. #NetworkSecurity #IoT Conclusion: Taking Back Your Home Google Home and Alexa still have their place. They are excellent, cheap voice interfaces. In fact, many power users integrate Google Assistant into Home Assistant purely for voice recognition, while keeping the actual logic and execution entirely local. However, as we move deeper into 2026, the sentiment is clear: Your home is your most private sanctuary. Relying on cloud servers to turn on your bedroom lights is an unnecessary surrender of data and reliability. By investing the time to set up an open-source, local-first system like Home Assistant, you are not just building a smarter house; you are reclaiming your digital sovereignty. You are ensuring that your routines, your data, and your hardware belong exclusively to you. And in the modern tech landscape, that level of control is priceless.Want to learn more about securing your local network or setting up Edge AI hubs? Let me know in the comments below, and don't forget to share this guide with your fellow DIY enthusiasts! Related InsightsThe Convergence of Quantum Entropy and Native Multimodal Architectures: A New Frontier in Information Processing Soulbound Tokens (SBTs): The Web3 Identity Revolution That Will Rewrite Trust and Reputation Silicon Beyond the Stratosphere: Architecting Autonomous Intelligence for Deep Space Exploration{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Home Assistant vs. Google Home in 2026: Why Local Control Wins for Privacy?", "acceptedAnswer": { "@type": "Answer", "text": "A deep dive into why local control with Home Assistant is replacing cloud-based ecosystems like Google Home for privacy-conscious smart home enthusiasts." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Home Assistant vs. Google Home in 2026: Why Local Control Wins for Privacy?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Lukas Richter." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 John Doe
- 18 Jun, 2026 10:00
The Evolution and Impact of the Smartphone Camera: How a Pocket Device Revolutionized Photography
In the grand tapestry of technological advancements over the last three decades, few innovations have reshaped human behavior, culture, and communication as profoundly as the smartphone camera. Once considered a mere novelty—a grainy, low-resolution gimmick tacked onto the back of early mobile phones—the integrated camera has evolved into a formidable imaging powerhouse. It has decimated the point-and-shoot camera market, challenged professional-grade DSLR and mirrorless systems, and democratized the art of photography for billions of people around the globe. Today, the question is no longer whether you have a camera on you, but rather how many lenses and neural processing algorithms your current device boasts. This article delves deep into the fascinating history, the relentless technological leaps, and the profound societal impacts of the smartphone camera, tracing its journey from a pixelated experiment to a pocket-sized studio. #SmartphoneCamera #TechRevolution #PhotographyDemocratized A Blurry Beginning: The Genesis of the Camera Phone To truly appreciate the multi-lens marvels we carry today, we must look back to the late 1990s and the dawn of the new millennium. The concept of marrying a digital camera with a cellular phone was not born overnight. One of the earliest and most famous instances of a camera phone in action was in 1997, when tech entrepreneur Philippe Kahn jury-rigged a digital camera to a Motorola StarTAC mobile phone. While his wife was in the maternity ward, Kahn wrote a few lines of code on his laptop to synchronize the devices, capturing and instantly sharing a photo of his newborn daughter, Sophie, with over 2,000 family members and friends. This makeshift contraption proved a concept that would soon ignite a multi-billion-dollar industry: the profound human desire for instant, wireless visual communication. #TechHistory #PhilippeKahn #Innovation Commercially, the race to bring a camera phone to the masses began in earnest in Japan and South Korea. In 1999, Kyocera launched the Visual Phone VP-210 in Japan, a device featuring a 0.11-megapixel front-facing camera designed primarily for video calls. Shortly after, in 2000, Samsung introduced the SCH-V200 in South Korea, which could store up to 20 photos at a 0.35-megapixel resolution. However, these photos had to be transferred to a computer via a cable to be viewed and shared properly. The true breakthrough in mobile photography integration came later in 2000 with the Sharp J-SH04, released by J-Phone (now SoftBank Mobile) in Japan. The J-SH04 allowed users to snap photos and, crucially, send them electronically to other users directly from the device. This was the birth of the modern Multimedia Messaging Service (MMS) era. #RetroTech #MobileInnovation #Early2000s These early devices produced images that were, by today's standards, comically poor. Resolutions were often sub-VGA (Video Graphics Array, usually 640x480 pixels or less), colors were washed out, dynamic range was practically nonexistent, and low-light performance was an exercise in futility. Yet, the appeal was never about replacing a dedicated camera; it was about spontaneity. The camera phone capitalized on the simple truth that the best camera is the one you have with you. This philosophical shift marked the beginning of photography not just as a means of memory preservation, but as a language of immediate, everyday communication. The Megapixel Race: Chasing Numbers and Sensor Sizes As camera phones gained traction in the early to mid-2000s, manufacturers engaged in a fierce marketing war known as the "Megapixel Race." Companies like Nokia, Sony Ericsson, Samsung, and Motorola vied for consumer attention by slapping increasingly higher megapixel counts on their devices. The logic was simple to market to consumers: more pixels logically equated to a better camera. #MegapixelWars #MobileTech #SonyEricsson #Nokia Sony Ericsson leveraged its established Cyber-shot branding from its standalone camera division to produce phones that looked and felt like digital cameras on one side and mobile phones on the other. Devices like the Sony Ericsson K800i brought features like dedicated shutter buttons, Xenon flashes, and active sliding lens covers, dramatically improving image quality and the shooting experience. Nokia, arguably the absolute king of the mobile phone era at the time, introduced the N-Series to flex its photographic muscles. The iconic Nokia N95, launched in 2006, featured a 5-megapixel sensor equipped with high-quality Carl Zeiss optics, recording video that was remarkably high quality for its time. It became a status symbol and a testament to how far mobile optics had come. Nokia would later push the boundaries even further with the PureView 808 in 2012 and the Lumia 1020 in 2013, which introduced massive 41-megapixel sensors. #CarlZeiss #NokiaLumia #MobilePhotography However, the industry soon realized a fundamental limitation of physics. Squeezing more pixels onto a tiny mobile sensor meant that each individual pixel (photosite) had to be physically smaller. Smaller pixels capture less light, leading to increased digital noise, artifacting, and incredibly poor performance in dim environments. The challenge for engineers became a delicate balancing act: increasing resolution while simultaneously increasing the physical sensor size, all without making the phone too thick or cumbersome. This realization paved the way for more sophisticated engineering. Manufacturers started utilizing a technique called "pixel binning" (or oversampling), where the data from multiple adjacent small pixels is combined into one larger "super pixel." This allowed for high-resolution sensors that could still perform admirably in low light. Yet, engineers knew that hardware alone would not win the mobile photography war in the long run. The true revolution was waiting in the software. #SensorSize #CameraPhysics #PixelBinning The Touchscreen Era and the App Ecosystem: Software Eats Photography The launch of the Apple iPhone in 2007 and the subsequent rise of the Android operating system marked a massive paradigm shift in mobile technology. Interestingly, the initial iPhone did not have the best camera on the market—it was a humble 2-megapixel fixed-focus shooter lacking a flash and video recording capabilities. However, what modern smartphones lacked in raw optical power compared to Nokia's behemoths, they made up for with their large, high-resolution multi-touch screens, intuitive interfaces, and constant internet connectivity. #iPhoneLaunch #AndroidOS #SmartphoneEra The true revolution of this era was the advent of the app ecosystem. Developers suddenly had unprecedented access to the camera hardware and the device's processing power, leading to an explosion of third-party photography applications. Apps like Hipstamatic and early Instagram capitalized on the limitations of mobile sensors by applying heavy, vintage-style filters that masked digital noise and optical imperfections, turning flaws into stylized, artistic choices. Photography became hyper-social and instantly malleable. The cycle of shooting, editing, and sharing, which once took hours or days using a computer, was compressed into mere seconds. #MobileApps #AppEcosystem #PhotoEditing Instagram, launched in 2010, transformed the cultural landscape entirely. It created a continuous visual feed of human existence, turning everyday users into amateur photographers and paving the way for the multi-billion-dollar influencer economy. The smartphone camera was no longer just a tool for capturing memories; it was a primary instrument for personal branding, status projection, and social validation. Furthermore, front-facing cameras—initially introduced for video calling services like Apple's FaceTime and Skype—birthed the cultural phenomenon of the "selfie." This fundamentally altered modern self-representation and identity, turning the lens inward and allowing users to curate their own image with unprecedented frequency and control. #SocialMedia #InstagramCulture #SelfieGeneration #DigitalIdentity The Dawn of Computational Photography: Breaking the Laws of Physics As smartphones became thinner and screens pushed closer to the edges, the physical space available for bulky camera modules shrank. Traditional camera manufacturers like Canon, Nikon, and Sony rely on large glass lenses and massive image sensors to capture light and create a natural depth of field. Smartphone manufacturers did not have this physical luxury. To compete, they had to turn to the realm of mathematics, computer science, and complex algorithms. Welcome to the era of computational photography. #ComputationalPhotography #Algorithms #AIPhotography Computational photography uses digital computation instead of traditional optical processes to improve or create images. One of the earliest and most impactful implementations of this was High Dynamic Range (HDR) imaging. In a traditional setup, capturing a scene with bright skies and dark shadows often results in blown-out highlights or crushed, pitch-black shadows. With computational HDR, when a user presses the shutter button, the camera doesn't just take one photo; it takes a rapid burst of several photos at varying exposure levels in a fraction of a second. The software then seamlessly aligns and merges these images together, taking the rich details from the shadows of the overexposed shots and the crisp details from the highlights of the underexposed shots to create a single, perfectly balanced image. The application of computational photography accelerated dramatically with the integration of Artificial Intelligence (AI) and specialized Neural Processing Units (NPUs) inside smartphone chipsets. Companies like Google, with its Pixel lineup, and Apple, with its Deep Fusion and Smart HDR technologies, led the charge. Night Mode is perhaps the most magical iteration of this technology. By combining long exposure techniques, machine learning to detect and align hand motion, and AI-driven noise reduction, modern smartphones can capture bright, detailed, and colorful images in near-pitch-black conditions—a feat that would require a heavy tripod, a fast lens, and significant technical expertise on a traditional DSLR. #NightMode #MachineLearning #TechInnovation Portrait Mode is another triumph of algorithmic engineering. To simulate the "bokeh" effect (the aesthetically pleasing blur of out-of-focus background areas) natively produced by large DSLR lenses, smartphones use depth-sensing cameras, Time-of-Flight (ToF) sensors, or dual-pixel autofocus to create a precise 3D depth map of the scene. Advanced AI then painstakingly segments the subject from the background, keeping the subject sharp while applying a synthetic, mathematically calculated blur to the rest of the image. What was once the exclusive domain of expensive, heavy portrait lenses was now available to anyone at the tap of a screen. #PortraitMode #BokehEffect #AItech Multiple Lenses and Advanced Sensors: A Studio in Your Pocket While algorithms can work wonders, there are some immutable optical realities that cannot be entirely faked or simulated without looking artificial. To provide users with greater optical versatility and pristine quality, manufacturers began adding multiple lenses to the back of their devices. What started as a dual-camera setup (usually a standard wide lens paired with a telephoto lens or a monochrome sensor for capturing better detail and contrast) quickly escalated into complex triple, quad, and even penta-camera arrays. #MultiLens #UltraWide #Telephoto The standard setup on premium flagship smartphones today typically includes three distinct focal lengths. The Primary Wide Lens is the workhorse; it boasts the largest physical sensor, the widest aperture (often f/1.5 or f/1.8 to let in massive amounts of light), and the most advanced optical image stabilization (OIS). It handles everyday shooting and demanding low-light scenarios. The Ultrawide Lens expands the field of view dramatically, often reaching 120 degrees or more. It allows users to capture sweeping landscapes, tight architectural interiors, and dramatic, exaggerated perspectives without having to physically step back. #WideAngle #LandscapePhotography #MobileOptics Finally, the Telephoto Lens allows for true optical zoom, bringing distant subjects closer without the severe pixelation and loss of quality associated with digital zoom. To overcome the physical thickness limitations of a phone—since a long focal length normally requires a long lens barrel—engineers developed the ingenious "periscope" telephoto lens. By using a prism to reflect light 90 degrees inward, the lens elements can be laid out horizontally within the phone's chassis. This optical ingenuity has enabled 5x, 10x, and even incredible 100x hybrid zoom capabilities, effectively putting a full bag of professional camera lenses into the pockets of the masses. #PeriscopeLens #OpticalZoom #EngineeringMarvel Furthermore, the inclusion of LiDAR (Light Detection and Ranging) scanners has pushed mobile photography further. By shooting invisible lasers to measure depth instantly and accurately, smartphones can now focus instantly in absolute darkness and map out rooms for advanced augmented reality (AR) applications. For the professionals, the ability to shoot in RAW formats (like Apple ProRAW or Expert RAW) retains all the uncompressed sensor data, allowing photographers to pull incredible detail out of the files in professional editing software like Adobe Lightroom. #LiDAR #RAWPhotography #ProCamera Video Capabilities and the Rise of Content Creation The evolution of the smartphone camera is not strictly limited to still photography; its impact on videography has been equally, if not more, revolutionary. Early camera phones could barely record choppy, stamp-sized videos at 15 frames per second. Today, they are highly sophisticated cinema cameras capable of recording in stunning 4K and 8K resolutions at high frame rates, complete with 10-bit HDR color science. #MobileVideography #4KVideo #ContentCreation The implementation of advanced hardware-based Optical Image Stabilization (OIS) combined with Electronic Image Stabilization (EIS) means that users can capture buttery-smooth, gimbal-like footage while walking, running, or shooting from moving vehicles. Features like Apple's Cinematic Mode utilize computational algorithms to shift focus smoothly from one subject to another in real-time, simulating the rack-focus work of a professional focus puller on a Hollywood movie set. This democratization of high-quality video production has been the primary fuel for the modern creator economy. Platforms like YouTube, TikTok, and Instagram Reels thrive entirely on the fact that anyone with a smartphone can shoot, edit, color-grade, and publish high-definition content to a global audience in minutes. Independent filmmakers, journalists, and vloggers rely heavily on smartphones to document stories that would be impossible, too expensive, or too intrusive to capture with a massive, traditional camera rig. The smartphone has lowered the financial and technical barrier to entry for visual storytelling to near zero. #CreatorEconomy #TikTokGeneration #VloggingLife #Filmmaking The Cultural Impact: A Society Remade Beyond the impressive specifications, the megapixels, and the hardware engineering, the sheer ubiquity of the smartphone camera has profoundly reshaped human society and culture at large. We now live in an aggressively visual, always-on culture. The camera has effectively become an external extension of our memory; we habitually document what we eat, where we travel, the concerts we attend, and who we spend our time with. While some sociologists and critics argue that viewing life primarily through a screen detaches us from the raw, present moment—leading to an "experience economy" where things are only done so they can be photographed—others highlight how it allows us to curate, celebrate, and share our diverse human experiences on an unprecedented global scale. #VisualCulture #DigitalSociety #ModernLife #PhilosophyOfTech One of the most critical and universally acknowledged societal impacts has been the rise of citizen journalism. With billions of high-definition cameras distributed globally, virtually every major public event, natural disaster, and instance of social injustice is now recorded and broadcasted in real-time. The smartphone camera has become an indispensable tool for accountability. It has been used to expose police brutality, political corruption, and human rights abuses that might otherwise have gone completely undocumented or covered up. Videos captured by ordinary citizens on their phones have sparked global protests, influenced elections, and shifted the course of modern history. #CitizenJournalism #SocialJustice #PowerToThePeople #HumanRights Conversely, this constant presence of cameras has raised severe, ongoing privacy concerns. We navigate a world where anyone can be recorded, photographed, and broadcasted at any time, often without their knowledge or consent. The integration of facial recognition technology and AI analysis into camera systems and social media platforms poses profound questions about mass surveillance and the fundamental right to anonymity in public spaces. The very tool that empowers citizens is also a potent instrument for data collection by corporations and governments. #PrivacyConcerns #SurveillanceState #DigitalEthics Professional Photography vs. Smartphones: An Ongoing Debate With smartphones consistently producing such stunning, ready-to-share images, the question inevitably arises: is the traditional, dedicated camera dead? For the average consumer and the casual vacationer, the answer is a resounding yes. The compact point-and-shoot camera market, which once dominated retail shelves, has been effectively eradicated by the smartphone. However, in the professional and enthusiast realms, the debate is much more nuanced. #DSLRvsSmartphone #ProPhotography #CameraDebate Professional DSLR and mirrorless cameras still hold distinct, physically unalterable advantages. Their image sensors are massively larger—a full-frame sensor is roughly 10 to 30 times larger than a typical smartphone sensor. This immense size advantage allows them to capture significantly more light naturally, yielding vastly superior dynamic range, authentic and buttery depth of field, and immaculate, noise-free detail that holds up when printed on massive billboards. Professional cameras also offer tactile, physical controls, an ecosystem of specialized interchangeable lenses, and the essential ability to seamlessly trigger and sync with complex external studio lighting systems. Yet, the gap is rapidly narrowing every year. Smartphones excel in point-and-shoot convenience, aggressive weight reduction, immediate internet connectivity for client delivery, and intelligent software that corrects complex lighting errors instantly. For many commercial applications today—ranging from social media marketing campaigns and influencer sponsorships to real estate photography and photojournalism—a high-end smartphone is more than sufficient. The professional camera is slowly evolving into a niche tool for highly specialized artistic, sports, wildlife, and high-end commercial endeavors, while the smartphone capably handles the vast bulk of the world's daily photographic needs. #PhotographyTrends #TechEvolution #GearTalk The Future of Smartphone Cameras: What Lies Ahead As we look to the horizon, the smartphone camera shows absolutely no signs of stagnation. Hardware and software will continue to converge in fascinating, previously unimaginable ways. We are already seeing the integration of massive 1-inch type sensors into flagship smartphones from manufacturers like Sony, Xiaomi, and Vivo. This pushes the physical limits of mobile optics to their absolute maximum, capturing DSLR-like light and natural depth without relying as heavily on software processing. #FutureTech #NextGenCameras #MobileOptics Under-display cameras are also poised to become the new industry standard. By hiding the front-facing selfie camera completely beneath the screen's active pixels, manufacturers can finally eliminate the need for distracting notches and hole-punches, resulting in true, uninterrupted edge-to-edge displays. We will also likely see the refinement of continuous optical zoom lenses, where the internal lens elements physically move within the phone's body to provide a smooth, variable optical zoom range (e.g., smoothly zooming from 3x to 5x optically), rather than relying on digitally cropping between multiple fixed-focal-length lenses. The most transformative and disruptive changes, however, will undoubtedly come from Generative Artificial Intelligence. We are rapidly moving beyond the era of computational photography and entering the realm of computational creation. Future smartphone cameras won't just passively capture what is there; they will intuitively understand what the user wants to be there. Generative AI will allow users to seamlessly remove photobombers, drastically alter lighting conditions and weather after the fact, and perhaps even generate completely new details that were never present in the original physical scene. This looming technological leap raises profound philosophical questions about the authenticity of a photograph. If a smartphone camera generates parts of an image using an AI model trained on millions of other photos, is it still a photograph, or has it become a piece of digital art? Can it still be trusted as a documentary tool? As the technology evolves, our very definition of what constitutes a "photograph" will be forced to evolve alongside it. #GenerativeAI #FutureOfPhotography #AIArt #TechPhilosophy #Authenticity Conclusion The spectacular journey of the smartphone camera is a towering testament to the relentless pace of human innovation and engineering. From the grainy, 0.1-megapixel novelties of the late 1990s to the AI-powered, multi-lens, 8K-recording behemoths of today, the pocket camera has fundamentally changed the way we interact with the world, the way we remember our lives, and the way we communicate with each other. It has democratized the art of visual storytelling, empowered a new generation of citizen journalists, fueled entirely new global digital economies, and fundamentally altered our universal visual language. The smartphone camera is far more than just a convenient feature on a communication device; it is arguably the most ubiquitous, powerful, and culturally influential imaging tool in the history of humanity. As we continue to blur the boundary lines between optical reality and algorithmic enhancement, one timeless truth remains absolutely certain: the best camera in the world is still the one you have with you, and that camera is only getting smarter, faster, and more capable with every passing day. #SmartphonePhotography #EndOfAnEra #DigitalRevolution #FinalThoughts Related InsightsEdge Cloud Continuum - Part 01: Architecture and Deployment Strategies Smart Materials Rewired: From Self‑Healing Concrete to Adaptive Textiles Rust in Production: Why Developers Are Embracing Memory Safety and Performance{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Evolution and Impact of the Smartphone Camera: How a Pocket Device Revolutionized Photography?", "acceptedAnswer": { "@type": "Answer", "text": "An in-depth look at how the smartphone camera evolved from a low-resolution gimmick to a revolutionary tool that changed photography, society, and human connection forever." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Evolution and Impact of the Smartphone Camera: How a Pocket Device Revolutionized Photography?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by John Doe." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- John Doe
- 15 Jun, 2026 10:00
The Need for Speed: The Ultimate Guide to the High-Flying World of Drone Racing
The Genesis of a Futuristic Motorsport In the ever-evolving landscape of modern sports, few spectacles can rival the visceral thrill, technological sophistication, and sheer velocity of drone racing. What began as a niche, almost underground hobby among radio-control enthusiasts in open fields and abandoned warehouses has rapidly metamorphosed into a professional, globally recognized motorsport. At its core, drone racing is an aviation sport where pilots control small, custom-built multirotor aircraft—commonly known as drones or quadcopters—around three-dimensional obstacle courses at dizzying speeds. These machines are not your average photography drones; they are highly tuned, aerodynamic projectiles capable of reaching speeds in excess of 120 miles per hour in a matter of seconds. The magic of drone racing lies in its unique fusion of physical reality and immersive digital perspective, a paradigm known as First Person View (FPV). Through FPV, pilots wear specialized goggles that stream live, low-latency video directly from a camera mounted on the nose of the drone. When a pilot straps on these goggles, they are visually teleported into the cockpit of their aircraft. Every bank, dive, roll, and high-speed corner is experienced firsthand, creating a sensory experience that blurs the line between human and machine. It is as close to being a bird of prey—or a fighter pilot—as one can get without leaving the ground. As we delve deep into the universe of #DroneRacing, we will explore the intricate technology that powers these aerial rockets, the profound level of skill required to pilot them, the evolution of course design, the rise of professional leagues, and the vibrant culture that sustains this high-flying community. Whether you are a seasoned FPV veteran, an aspiring pilot looking to take your first flight, or simply an intrigued spectator, the world of FPV racing offers a fascinating glimpse into the future of competitive sports. The Anatomy of a Racing Drone: Engineering for Extreme Speed To truly appreciate the sport, one must understand the anatomy of a racing drone. Unlike commercial camera drones, which are designed for stability, ease of use, and automated flight (using GPS and optical flow sensors), racing drones are built entirely for speed, agility, and durability. They are stripped of all non-essential components, relying entirely on the pilot's manual input and a sophisticated array of electronics. The typical FPV racing drone is a masterclass in miniaturized engineering. #FPVTechnology The Frame: The Skeleton of the Beast The foundation of any racing drone is its frame. Traditionally constructed from high-grade carbon fiber, the frame must be exceptionally rigid to eliminate vibrations that can confuse the flight controller, yet light enough to maximize the thrust-to-weight ratio. The arms of the frame must also be incredibly durable to withstand the inevitable high-speed crashes into concrete pillars, metal gates, and the ground. Modern frames often employ a true-X or stretched-X geometry to ensure balanced flight characteristics and optimal aerodynamics. The thickness of the carbon fiber plates, the arrangement of standoffs, and the overall geometry are meticulously debated by frame designers to shave off mere grams of weight while maintaining structural integrity. #CarbonFiber Motors and Propellers: The Propulsion System The raw power of a racing drone comes from its brushless DC motors. These motors are incredibly powerful for their size, capable of spinning at tens of thousands of revolutions per minute. Paired with the motors are polycarbonate propellers. The pitch, length, and number of blades on the propellers dictate how the drone "grips" the air. A steeper pitch provides higher top speed but requires more torque from the motor, whereas a lower pitch offers better efficiency and low-end control. The delicate balance between motor size, stator volume (commonly expressed in numbers like 2207 or 2306), and propeller configuration is a constant subject of optimization among pilots depending on whether the track is tight and technical or fast and flowing. The Flight Controller (FC): The Brain If the frame is the skeleton and the motors are the muscle, the flight controller is the central nervous system. The FC is a tiny circuit board equipped with a microprocessor and an inertial measurement unit (IMU) containing a gyroscope and an accelerometer. The FC runs highly specialized open-source firmware, such as Betaflight, EmuFlight, or KISS, which interprets the pilot's commands from the radio receiver and calculates exactly how fast each of the four motors must spin to achieve the desired movement. These calculations occur thousands of times per second (loop times), allowing for incredibly crisp, responsive, and locked-in flight characteristics. Pilots spend hours tuning the PID (Proportional, Integral, Derivative) controllers to ensure the drone responds perfectly to stick inputs without oscillating. Electronic Speed Controllers (ESCs): The Nervous System Sitting between the flight controller and the motors are the Electronic Speed Controllers. The ESCs translate the digital signals from the flight controller into the precise pulses of alternating current required to spin the brushless motors. In modern racing drones, these are often combined into a single 4-in-1 board to save weight and simplify wiring. They must be capable of handling massive spikes in electrical current—often over 40 to 50 amps per motor during a full-throttle punch-out. The protocol used to communicate between the FC and the ESC, such as DShot, ensures incredibly fast and reliable data transfer. The Battery: The Powerhouse Racing drones are powered by High-Voltage Lithium Polymer (LiPo) batteries. These batteries are chosen for their ability to discharge massive amounts of energy almost instantaneously. The standard voltage for modern racing drones is 6S (six cells in series, totaling 22.2 volts nominal), though some still use 4S configurations. Because of the intense power draw, flight times in a typical race are astonishingly short—often lasting between 60 seconds and three minutes before the battery is completely depleted. Managing battery voltage mid-race is a crucial skill; pushing the battery too hard for too long can result in a catastrophic failure or permanent damage to the cells. #LiPoBattery The FPV System: The Eyes The most defining component of a racing drone is its FPV system, comprising an FPV camera and a Video Transmitter (VTX). The camera is usually an analog or low-latency digital camera designed to handle rapid changes in lighting, such as transitioning from the dark shadows of a forest into bright sunlight. The VTX broadcasts the video signal over a specific radio frequency—usually 5.8 GHz—to the pilot's goggles. Historically, analog video has been the standard due to its absolute zero-latency performance and consistent degradation (static) at the edge of range, which warns pilots before a complete signal loss. However, digital systems developed by companies like DJI, HDZero, and Walksnail have revolutionized the sport. These systems offer crystal-clear, high-definition video with latency low enough for competitive racing, allowing pilots to spot tiny branches or course markers from much further away. #DigitalFPV The Art of Piloting: Flying on the Razor's Edge Piloting a racing drone is fundamentally different from flying a stabilized consumer drone. FPV pilots fly in what is known as "Acro Mode" (acrobatic mode) or "Rate Mode." In this mode, the flight controller makes no attempt to auto-level the aircraft. If the pilot pitches the drone forward 45 degrees and lets go of the stick, the drone will maintain that 45-degree angle indefinitely until another command is given. This requires constant, minute adjustments on the control sticks just to keep the drone airborne, let alone race it through a dense obstacle course. The control scheme on a standard radio transmitter consists of two highly sensitive joysticks. #DronePilot The Left Stick: Throttle and Yaw In the standard "Mode 2" configuration used by most pilots globally, the left stick controls throttle (vertical axis) and yaw (horizontal axis). Throttle dictates the overall speed of all four motors simultaneously. It controls altitude and forward speed depending on the angle of the drone. Pushing the stick forward increases power. Yaw rotates the drone around its vertical axis, much like the rudder on an airplane. It is used to point the nose of the drone in the desired direction while maintaining a flat horizon relative to the drone's tilt. The Right Stick: Pitch and Roll The right stick controls pitch (vertical axis) and roll (horizontal axis). Pitch tilts the nose of the drone up or down. Tilting the nose down directs the thrust backward, accelerating the drone forward. Pulling the nose up slows the drone down or accelerates it backward. Roll tilts the drone left or right, allowing it to bank into turns, perform aileron rolls, or correct for wind drift. Mastering the interaction between these four axes requires thousands of hours of practice. To execute a smooth, fast turn at 80 miles per hour, an FPV pilot must simultaneously roll into the turn, pull back slightly on pitch to maintain altitude, adjust throttle to counteract the loss of vertical lift, and add just enough yaw to keep the camera pointed precisely where they are going. The mental bandwidth required is staggering, demanding intense focus, deep flow states, and lightning-fast reflexes that border on the superhuman. #AcroMode Telemetry and On-Screen Display (OSD): Information at the Speed of Light In the heat of a race, a pilot cannot afford to take their eyes off the course for even a fraction of a second to check a screen or look at their radio. This is where the On-Screen Display (OSD) and telemetry become vital. The OSD overlays critical flight data directly onto the video feed inside the pilot's goggles, much like a heads-up display in a modern fighter jet. Crucial information such as battery voltage, current draw, flight time, artificial horizon, and radio link quality (RSSI or LQ) are constantly visible. If a pilot sees their battery voltage sagging dangerously low, they know they must finish the lap quickly or risk a mid-air power failure, colloquially known as "falling out of the sky." Advanced telemetry systems also send this data back to the pilot's radio transmitter, allowing it to vibrate or call out audible voice warnings, further enhancing the pilot's situational awareness. #OSD Course Design: The Three-Dimensional Racetrack Unlike Formula 1 or MotoGP, where racers are bound to a two-dimensional ribbon of asphalt, drone racing takes place in three dimensions. Course designers exploit this freedom to create complex, mind-bending tracks that challenge every aspect of a pilot's skill. The track is not just about left and right turns; it is about managing altitude, momentum, and spatial awareness in a fully 3D environment. A typical track consists of various elements:Gates: Large illuminated squares, circles, or arches that the drone must pass through. Missing a gate usually results in a severe penalty or requires the pilot to turn around and complete it, effectively destroying their lap time. Flags: Vertical pylons that pilots must navigate around, often used to create tight, high-speed slaloms. Dive Gates: Gates positioned vertically, sometimes attached to the ceilings of stadiums or the tops of tall structures, forcing the pilot to climb high and perform a controlled free-fall directly downward through the opening. Tunnels and Corridors: Enclosed spaces that severely restrict the pilot's ability to correct mistakes, punishing any deviation from the perfect racing line. Split-S and Immelmann Turns: Complex aerobatic maneuvers explicitly required by the track layout to transition between different elevations or directions smoothly.Tracks are often illuminated with bright LED lights to help the cameras see the obstacles and to create a visually stunning, cyberpunk-esque experience for spectators. The environment can be anything from a massive football stadium or an intricate forest canopy to an abandoned shopping mall, an underground parking garage, or a specially constructed neon-lit indoor arena. #RacetrackDesign The Rise of Professional Organizations As the grassroots community grew, it was inevitable that formal organizations would emerge to structure and monetize the sport. Today, several major leagues dominate the professional landscape, each offering a slightly different flavor of competition. The Drone Racing League (DRL) The Drone Racing League is perhaps the most recognizable professional organization in the world. Founded in 2015, DRL operates on a unique model: rather than having pilots build and bring their own drones, DRL engineers design and manufacture a fleet of identical, custom-built racing drones (such as the Racer3 and Racer4 models). This ensures that the competition is entirely based on pilot skill rather than technological superiority or access to better parts. DRL events are highly produced, million-dollar spectacles, held in iconic locations around the world, and broadcast on major television networks like NBC, Sky Sports, and various streaming platforms. The league has been instrumental in bringing drone racing to a mainstream audience, framing the pilots as the cyberpunk athletes of the future. #DRL MultiGP While DRL is the premier invitational and highly produced league, MultiGP is the lifeblood of the grassroots and competitive community. MultiGP is the largest drone racing league in the world, boasting hundreds of local chapters across the globe. They provide standard rules, uniform timing systems, and globally standardized track designs, allowing pilots of all skill levels to compete locally and earn points to qualify for regional and national championships. The annual MultiGP Championship is considered the definitive test of the best "bring-your-own-drone" pilots on the planet, where technological innovation and pilot skill are tested in equal measure. #MultiGP Drone Champions League (DCL) Operating primarily in Europe, the Drone Champions League blurs the lines between physical and virtual racing. DCL features team-based competition, where teams of pilots compete in breathtaking, high-profile locations, such as the salt mines of Romania, the ruins of a castle in Austria, or the Champs-Élysées in Paris. Furthermore, DCL places a heavy emphasis on their official simulator, DCL - The Game, allowing gamers to compete virtually and even draft their way onto a real-world professional team based on their simulator performance. #DCL Historic Milestones and Past Major Events The journey from a hobbyist pastime to a global sport has been marked by several key events. The 2016 World Drone Prix in Dubai was a watershed moment. Boasting a staggering $1 million prize pool, it attracted the best pilots from around the world to compete on a futuristic, custom-built outdoor track set against the backdrop of the Dubai skyline. The event was won by a 15-year-old British pilot, Luke Bannister, proving early on that in drone racing, reaction times and hand-eye coordination trumped age, background, and traditional piloting experience. In 2018, the FAI (Fédération Aéronautique Internationale), the world governing body for air sports, officially recognized drone racing as a legitimate sporting discipline and began hosting the FAI World Drone Racing Championship. This gave the sport legitimate international backing and standardized the rules globally, further cementing its status alongside traditional aviation sports like aerobatics and gliding. The Simulator Revolution: Merging Virtual and Reality One of the most fascinating aspects of drone racing is the critical role of flight simulators. Because crashing a real drone is expensive and repairing them is time-consuming, simulators have become the primary training ground for both amateurs and professionals. Simulators like Velocidrone, Liftoff, and Uncrashed use advanced physics engines to replicate the exact aerodynamic properties, weight distribution, and thrust characteristics of a racing drone. Pilots plug their actual radio transmitters into their computers via USB and fly virtual representations of real-world tracks. The physics have become so accurate that the muscle memory and spatial awareness skills learned in the simulator translate directly to the real world with minimal adjustment. In fact, many of today's top-tier professional pilots began their careers purely on simulators, only picking up a real drone after they had already mastered the virtual realm. This accessibility has democratized the sport, allowing anyone with a computer and a controller to learn how to fly before making a significant financial investment in hardware. #DroneSimulator #eSports The Economics of the Sport: Funding, Sponsorship, and Prize Money The rapid professionalization of drone racing has brought significant capital into the ecosystem. The Drone Racing League, for instance, has raised tens of millions of dollars from high-profile investors including RSE Ventures, Liberty Media (owners of Formula 1), and Sky. Sponsorships have also become a major revenue stream, with tech giants, telecommunications companies, and even traditional aerospace firms eager to associate their brands with the cutting-edge, high-tech image of drone racing. For the pilots, making a living solely from racing is still challenging but increasingly possible for the top echelon. Top pilots earn salaries from their leagues, command significant prize money at major events, and supplement their income through sponsorships from component manufacturers, YouTube ad revenue, and Patreon supporters. The "influencer" aspect of the sport is massive, with pilots regularly uploading their high-octane DVR (Digital Video Recorder) and HD action camera footage to social media platforms to showcase their skills, review new parts, and build their personal brands. #SportsEconomics The Future Horizon: AI and the Next Evolution As technology continues to advance at an exponential rate, the future of drone racing looks incredibly exciting and slightly terrifying. One of the most significant developments on the horizon is the integration of Artificial Intelligence. In recent years, researchers and engineers have been developing autonomous racing drones that navigate the course without any human input, relying entirely on onboard cameras, LiDAR, and deep neural networks to calculate the optimal racing line. In a landmark achievement, an AI-driven drone developed by researchers at the University of Zurich successfully defeated world champion human pilots on a real-world track. While human pilots still hold the edge in adaptability and dealing with unpredictable environmental factors (such as wind gusts, changing lighting conditions, or moving obstacles), the gap is closing rapidly. Organizations like the Artificial Intelligence Racing League (AIRL) are already exploring formats where AI and humans can compete side-by-side or in separate autonomous categories. Furthermore, advancements in battery technology, specifically the anticipated development of solid-state batteries, promise to drastically increase flight times and reduce weight, fundamentally altering the physics and pacing of the sport. We are also likely to see further miniaturization of components, allowing for races in incredibly tight, intricate micro-environments that are currently impossible to navigate. #AI #AutonomousDrones Conclusion: The Ultimate Test of Man and Machine Drone racing is more than just an emerging sport; it is a profound celebration of human ingenuity, superhuman reflexes, and the relentless pursuit of speed. It represents the perfect symbiosis of the pilot's physical skill and the engineer's technological prowess. When a pilot dons their FPV goggles and pushes the throttle to the absolute maximum, they transcend the physical limitations of the human body and experience the pure, unadulterated freedom of flight. From the quiet workbench smelling of flux where carbon fiber frames are assembled and firmware is meticulously tuned, to the dazzling lights of a multi-million-dollar stadium event, the community surrounding drone racing is passionate, fiercely innovative, and deeply dedicated. As the technology continues to mature, latency drops to zero, and the global audience expands, drone racing is poised to become one of the defining spectator sports of the 21st century. It is a sport where the sky is not the limit, but merely the starting line. The high-speed revolution has only just begun, and the world is strapping in for the ride. #FutureOfSports #AviationSports #FPVRacing #DroneRacing #FPV #Technology #eSports Related Insights{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Need for Speed: The Ultimate Guide to the High-Flying World of Drone Racing?", "acceptedAnswer": { "@type": "Answer", "text": "Discover the exhilarating sport of drone racing, from cutting-edge First Person View (FPV) technology to the global leagues transforming this hobby into a futuristic motorsport." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Need for Speed: The Ultimate Guide to the High-Flying World of Drone Racing?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by John Doe." } }, { "@type": "Question", "name": "Where can I find more related content about Sports?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Sports category page." } } ] }
- John Doe
- 15 Jun, 2026 10:00
The Dawn of Cognitive Machinery: A Comprehensive Exploration of Large Language Models
The story of human civilization is inextricably linked to our ability to communicate. From the earliest cave paintings to the development of written scripts, the printing press, and the global expanse of the internet, every leap forward in our collective progress has been driven by new ways to share, store, and process information. Today, we stand on the precipice of what may be the most profound revolution in communication yet: the advent of Artificial Intelligence that can understand, generate, and interact with human language in ways that were once strictly the domain of science fiction. At the very heart of this technological renaissance lies a marvel of modern computer science known as the Large Language Model. #ArtificialIntelligence #TechInnovation #HistoryOfTech But what exactly is a Large Language Model, often abbreviated as an LLM? To grasp the magnitude of this technology, we must first break down the terminology. At its core, a language model is a type of artificial intelligence system designed to understand and generate text. It operates on the principles of probability, attempting to predict the next word or sequence of words based on the context provided by the preceding text. However, the "Large" in Large Language Models is what truly sets them apart from their predecessors. This largeness refers to two critical dimensions: the astronomical volume of data they are trained on, and the immense complexity of their underlying neural network architectures, which often comprise billions or even trillions of parameters. #LLM #MachineLearning #DeepLearning The journey to developing these massive models has been decades in the making. For many years, Natural Language Processing (NLP) relied on rules-based systems and smaller statistical models that struggled to grasp the nuance, context, and ambiguity inherent in human language. They could parse simple sentences, but ask them to summarize a complex document or write a coherent essay, and they would quickly fall apart. The true paradigm shift occurred with the intersection of big data, exponential increases in computational power, and a revolutionary breakthrough in neural network design. Today's LLMs are not just tools for processing text; they are sophisticated engines of cognition that can write code, compose poetry, diagnose medical conditions, and simulate human reasoning. In this comprehensive exploration, we will delve deep into the mechanics, training paradigms, emergent capabilities, real-world applications, and the profound ethical challenges presented by Large Language Models. #NLP #TechRevolution #FutureIsNowThe Architecture of Intelligence: The Transformer Revolution To truly appreciate the power of Large Language Models, one must look under the hood at the architectural engine that drives them. For a long time, the dominant architectures for sequence-to-sequence tasks in natural language processing were Recurrent Neural Networks (RNNs) and Long Short-Term Memory networks (LSTMs). These architectures processed text sequentially, word by word. While this mimicked the way humans read, it presented a massive bottleneck for machine learning. Sequential processing meant that training could not be easily parallelized across multiple graphic processing units (GPUs). Furthermore, RNNs and LSTMs suffered from the "vanishing gradient" problem, which made it incredibly difficult for the models to retain context over long passages of text. By the time an RNN reached the end of a long paragraph, it had essentially "forgotten" the beginning. #NeuralNetworks #TechHistory #ComputerScience This all changed in 2017 when a team of researchers at Google published a seminal paper titled "Attention Is All You Need." This paper introduced the Transformer architecture, a radical departure from sequential processing. The core innovation of the Transformer is the "self-attention" mechanism. Instead of processing text linearly, the self-attention mechanism allows the model to look at an entire sequence of words simultaneously. For every word in a sentence, the Transformer calculates an attention score that determines how heavily that word should weigh or "attend to" every other word in the sequence, regardless of their physical distance from one another in the text. #TransformerArchitecture #GoogleResearch #Innovation Imagine reading a complex legal document. The word "bank" could refer to a financial institution, or the side of a river. In an RNN, the context might be lost if the clues defining "bank" were several sentences away. In a Transformer, the self-attention mechanism instantly draws connections between "bank" and words like "deposit," "interest," or "loan" located elsewhere in the text, immediately disambiguating the meaning. This ability to capture long-range dependencies is what gives LLMs their remarkable contextual awareness. #DataScience #ContextMatters #AIAlgorithms Moreover, because Transformers do not process data sequentially, their training can be massively parallelized. This means that researchers could suddenly feed unprecedented amounts of data into the network and train it across sprawling clusters of powerful GPUs. The architecture itself is made up of encoders and decoders, though many modern generative LLMs—like the famed GPT (Generative Pre-trained Transformer) series—rely primarily on deep stacks of decoder blocks. The text is broken down into "tokens," which can be whole words, syllables, or even single characters. These tokens are then converted into high-dimensional mathematical vectors called "embeddings." Within this high-dimensional space, words with similar meanings are positioned closer together. The Transformer manipulates these embeddings through dozens or hundreds of layers of self-attention and feed-forward neural networks, refining its understanding of the text with each layer. The sheer mathematical elegance of the Transformer is the bedrock upon which the modern AI revolution is built. #Mathematics #DeepTech #AlgorithmsThe Training Paradigm: From Pre-training to Human Alignment The creation of a Large Language Model is an arduous, multi-stage process that requires staggering amounts of computational resources, often costing tens of millions of dollars in electricity and hardware alone. The lifecycle of an LLM typically unfolds in three distinct phases: pre-training, supervised fine-tuning, and alignment. #AITraining #TechInfrastructure #BigData The first and most resource-intensive phase is pre-training. During this stage, the model is exposed to a vast, unfiltered corpus of text scraped from the internet. This dataset includes everything from Wikipedia articles and digitized books to scientific papers, forum discussions, and open-source code repositories. We are talking about hundreds of billions, sometimes trillions, of words. The objective during pre-training is deceptively simple: next-word prediction. The model is given a sequence of tokens and asked to predict the next token. Initially, its guesses are entirely random. But through a process called backpropagation, the model compares its prediction to the actual word in the text, calculates its error, and incrementally adjusts its billions of internal parameters to improve its accuracy for the next time. #DataMining #InternetScraping #DeepLearning Over months of continuous training, something remarkable happens. In its quest to minimize the prediction error, the model is forced to learn the underlying structure of human language. It learns grammar, syntax, and vocabulary. But more profoundly, because language is a reflection of the world, the model also learns facts about history, science, geography, and human psychology. It learns how to structure a logical argument, how to write functional Python code, and how to mimic the prose of Shakespeare. By the end of pre-training, we have a "base model." This base model is incredibly knowledgeable but highly unpredictable. If you prompt it with a question, it might answer it, but it might just as easily generate a list of related questions, because it is merely continuing the pattern of the text it has seen. #KnowledgeGraph #MachineLearningModels #AIResearch To turn this raw statistical engine into a useful assistant, it must undergo Supervised Fine-Tuning (SFT). In this phase, human experts write thousands of high-quality prompt-and-response pairs. The model is trained on these specific examples to learn the format of a helpful conversation. It learns that when asked a question, it should provide a direct, informative answer rather than completing a pattern. #FineTuning #DataAnnotation #TechDevelopment However, supervised fine-tuning is not enough to ensure the model behaves safely and aligns with human values. This brings us to the final, crucial phase: Reinforcement Learning from Human Feedback (RLHF). During RLHF, the model generates multiple different responses to a single prompt. Human evaluators rank these responses based on criteria such as helpfulness, accuracy, and safety (e.g., avoiding hate speech or instructions for illegal activities). These rankings are used to train a separate "reward model," which is then used to automatically score and guide the LLM's behavior via reinforcement learning algorithms like Proximal Policy Optimization (PPO). This alignment process is what gives modern chatbots their polite, helpful, and generally safe demeanor. It bridges the gap between raw computational power and human-centric usability. #RLHF #AIAlignment #SafeAIEmergent Abilities: The Illusion of Understanding? As Large Language Models have scaled up in parameter count and training data, researchers have observed a fascinating and somewhat bewildering phenomenon: emergent abilities. In the study of complex systems, emergence occurs when quantitative changes lead to qualitative leaps—when a system exhibits properties that cannot be predicted by analyzing its individual parts. In the context of LLMs, as models cross certain thresholds of scale, they suddenly demonstrate capabilities they were never explicitly trained to perform. #EmergentAbilities #CognitiveScience #ComplexityTheory Smaller language models are generally only good at the specific tasks they were fine-tuned for. But massive models exhibit zero-shot learning, meaning they can successfully perform a task they have never seen before, simply by following the instructions in the prompt. They can translate between obscure languages, summarize complex technical documents, or format data into tables without needing explicit examples. Even more impressive is their capacity for few-shot learning, where providing just two or three examples in the prompt dramatically boosts their performance on highly specialized tasks. #ZeroShotLearning #FewShotLearning #AIAdvancements One of the most profound emergent abilities is reasoning, or at least the simulation thereof. Researchers discovered that by simply adding the phrase "Let's think step by step" to a prompt, an LLM's ability to solve complex math word problems or logic puzzles skyrocketed. This technique, known as Chain of Thought (CoT) prompting, encourages the model to break down a problem into intermediate logical steps before arriving at a final answer. The fact that a model trained purely on next-word prediction can articulate a logical chain of reasoning has sparked intense debate within the AI and cognitive science communities. #ChainOfThought #Logic #ProblemSolving This brings us to a philosophical crossroads: do these models actually "understand" what they are saying, or are they merely "stochastic parrots," mindlessly regurgitating statistical correlations from their training data? Skeptics argue that LLMs possess no grounding in the physical world; they manipulate symbols without grasping their meaning. They do not know what an apple tastes like; they only know that the token "apple" is frequently associated with tokens like "red," "fruit," and "crisp." Proponents, however, argue that meaning is entirely relational. If a model can perfectly manipulate language to simulate reasoning, solve novel problems, and construct coherent worldviews, is that not a form of functional understanding? Whether LLMs possess true cognition or merely a hyper-sophisticated simulation of it, their practical utility remains undeniable. #StochasticParrots #PhilosophyOfAI #CognitionReal-World Applications: Transforming the Global Economy The transition of Large Language Models from research laboratories into commercial products has unleashed a wave of disruption across virtually every sector of the global economy. We are witnessing the automation of cognitive labor on a scale previously thought impossible. #FutureOfWork #Economy #DigitalTransformation In the realm of software development, LLMs have become indispensable companions. AI coding assistants, powered by models trained on millions of repositories of source code, can now write entire functions, debug complex errors, and translate code between programming languages. Developers report massive increases in productivity, allowing them to focus on high-level system architecture while the AI handles boilerplate code. This democratization of coding is lowering the barrier to entry, enabling non-programmers to build applications simply by describing what they want in natural language. #SoftwareEngineering #Coding #DevTools The healthcare industry is also undergoing a profound transformation. LLMs are being deployed to analyze vast quantities of unstructured medical data, including patient histories, clinical notes, and research papers. They can assist doctors in diagnosing rare diseases by cross-referencing patient symptoms with global medical literature in seconds. Furthermore, specialized LLMs are accelerating the process of drug discovery. By understanding the "language" of biology—such as amino acid sequences in proteins or chemical structures—these models can predict how molecules will fold and interact, drastically reducing the time and cost required to bring life-saving medications to market. #HealthTech #MedTech #BioInformatics In the creative and marketing sectors, generative AI has fundamentally altered the content creation pipeline. LLMs are drafting marketing copy, writing blog posts, scripting videos, and even helping authors brainstorm plot points for novels. While purists debate the artistic merit of machine-generated prose, the commercial efficiency is indisputable. Marketing agencies can now generate highly personalized ad campaigns tailored to specific demographics in real-time, operating at a scale that human copywriters could never match. #MarketingDigital #ContentCreation #GenerativeArt Education and customer service are experiencing similar revolutions. LLMs are powering intelligent tutoring systems that can adapt to a student's individual learning pace, explaining complex concepts in multiple ways until the student understands. In customer service, the frustrating, rule-based chatbots of the past are being replaced by conversational agents capable of resolving nuanced customer disputes with empathy and precision. The overarching theme is that any industry reliant on the processing, synthesis, or generation of text is being irrevocably altered by LLM technology. #EdTech #CustomerExperience #InnovationInEducationThe Dark Side: Hallucinations, Bias, and Existential Risks For all their miraculous capabilities, Large Language Models are fraught with significant vulnerabilities and ethical perils. The very nature of their statistical generation makes them susceptible to a phenomenon known as hallucination. Because an LLM's primary objective is to predict the most likely next word, it can confidently generate information that is entirely false, citing non-existent research papers, inventing historical events, or providing fabricated legal precedents. In contexts like medical diagnosis or legal counsel, a hallucinating AI can have catastrophic, real-world consequences. Ensuring factual accuracy and "grounding" the models in verifiable truth remains one of the greatest unsolved challenges in AI research. #AIHallucinations #FactChecking #TechEthics Equally concerning is the issue of bias. An LLM is only as objective as the data it was trained on. Because these models are fed massive swathes of the internet, they inevitably absorb and amplify the prejudices, stereotypes, and toxic language embedded in human history and online discourse. Without rigorous alignment and safety filtering, LLMs can generate sexist, racist, or politically biased outputs. Mitigating this requires a delicate balancing act; attempts to aggressively filter models can lead to "over-refusal," where the AI becomes unhelpfully constrained, or "woke-washing," where the model forcibly inserts diversity in historically inaccurate contexts. #BiasInAI #EthicalTech #SocialJustice The environmental impact of Large Language Models is another hidden cost. The compute power required to train a state-of-the-art model consumes thousands of megawatt-hours of electricity, generating a carbon footprint equivalent to hundreds of transcontinental flights. As companies race to build ever-larger models, the strain on global energy grids and the associated carbon emissions are becoming a critical environmental concern. #GreenTech #Sustainability #ClimateAction Furthermore, there is the specter of malicious use and cybersecurity. Bad actors are leveraging LLMs to industrialize cybercrime. The technology can generate highly convincing, personalized phishing emails at scale, automate the creation of polymorphic malware, and power massive disinformation campaigns capable of swaying democratic elections. The ability of LLMs to generate realistic deepfake audio and text is blurring the line between truth and fiction, eroding public trust in digital media. #CyberSecurity #InfoSec #DeepFakes This litany of risks has prompted a frantic scramble for global regulation. Governments around the world are grappling with how to govern a technology that is evolving faster than the legislative process. Initiatives like the European Union's AI Act attempt to classify AI systems by risk, imposing strict transparency and safety requirements on the most powerful foundation models. However, striking the right balance between protecting the public and fostering innovation remains a deeply contentious geopolitical issue. #AIAct #TechPolicy #GovernanceThe Future Horizon: Towards General Intelligence As we look toward the future, the trajectory of Large Language Models points toward even greater integration and capability. The current frontier is multimodality. The next generation of models are not just "language" models; they are natively multimodal, capable of processing and generating text, images, audio, and video simultaneously. A multimodal LLM can look at a photograph of the contents of your refrigerator and instantly generate a recipe, or watch a video of a mechanical failure and diagnose the problem. By grounding their text-based knowledge in visual and auditory data, these models are moving closer to a holistic understanding of the physical world. #MultimodalAI #ComputerVision #NextGenTech Simultaneously, there is a push towards efficiency and Edge AI. While massive models dominate the headlines, researchers are developing highly optimized, smaller models (often called Small Language Models, or SLMs) that can run locally on smartphones and laptops. This shift toward edge computing enhances user privacy, reduces latency, and decreases reliance on energy-hungry cloud servers. Techniques like quantization and model distillation are proving that you don't necessarily need a trillion parameters to achieve exceptional performance on specific tasks. #EdgeAI #MobileTech #Efficiency Ultimately, the relentless advancement of LLMs is fueling the pursuit of Artificial General Intelligence (AGI)—a hypothetical AI that can understand, learn, and apply knowledge across a wide range of tasks at a level equal to or surpassing human capabilities. Whether LLMs are the direct path to AGI, or merely an impressive stepping stone requiring fundamentally new architectures, is a subject of fierce debate. #AGI #ArtificialGeneralIntelligence #FutureTech What is certain, however, is that Large Language Models have forever altered the trajectory of human progress. They are not merely sophisticated software; they represent the dawn of cognitive machinery. As we continue to refine, scale, and integrate these systems into the fabric of society, our greatest challenge will not be technical, but philosophical. We must learn to navigate a world where intelligence is no longer exclusively human, ensuring that as we build machines that can think, we guide them to think in ways that elevate and preserve the human spirit. The conversation between humanity and its greatest creation has just begun. #HumanityAndTech #TechPhilosophy #TheFutureIsNow #LLM #NLP #GenerativeAI #Transformers #DeepLearning Related InsightsHolographic Displays: The Silent Revolution Reshaping AR/VR, 3D Visualization, and Human-Computer Interaction The Quantum Leap: Unlocking the Secrets of Next-Gen Qubit Architectures Unlocking the Potential of Extended Reality (XR): Enterprise Applications and Digital Collaboration{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Dawn of Cognitive Machinery: A Comprehensive Exploration of Large Language Models?", "acceptedAnswer": { "@type": "Answer", "text": "Dive deep into the world of Large Language Models (LLMs). Explore their architecture, training processes, real-world applications, and the ethical challenges they present." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Dawn of Cognitive Machinery: A Comprehensive Exploration of Large Language Models?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by John Doe." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- John Doe
- 15 Jun, 2026 10:00
The Heartbeat of the Modern World: A Deep Dive into the Lithium-Ion Battery
The Heartbeat of the Modern World: A Deep Dive into the Lithium-Ion Battery In the grand tapestry of human technological advancement, certain inventions stand out as fundamental pillars that have irreversibly altered the trajectory of our civilization. The wheel, the printing press, the steam engine, and the semiconductor all hold their rightful places in the pantheon of human ingenuity. Yet, as we navigate the complexities of the 21st century, another ubiquitous but often overlooked marvel silently powers our daily existence: the lithium-ion battery. From the smartphones nestled in our pockets to the electric vehicles silently gliding down our highways, and the massive grid storage facilities balancing renewable energy sources, the lithium-ion battery is the unsung hero of the modern era. It is the lifeblood of our increasingly portable, connected, and electrified world. #LithiumIon #TechRevolution #ModernEnergy To truly appreciate the magnitude of this technology, one must look beyond the sleek exterior of our modern devices and delve into the fascinating microscopic dance of ions that makes it all possible. This comprehensive exploration will unravel the rich history of the lithium-ion battery, demystify its intricate electrochemical workings, dissect the various chemical formulations that tailor it to specific applications, and address the pressing environmental and geopolitical challenges that accompany its global dominance. Furthermore, we will cast our gaze toward the horizon, examining the future of energy storage and the innovations poised to revolutionize the industry once again. #BatteryTech #EnergyStorage #ScienceExplained The Genesis: From Dream to Commercial Reality The journey of the lithium-ion battery is a testament to the power of perseverance, international collaboration, and the relentless pursuit of scientific understanding. The narrative begins in the tumultuous decade of the 1970s, an era defined by geopolitical instability and a global oil crisis that starkly highlighted the vulnerabilities of fossil fuel dependency. It was against this backdrop that researchers worldwide intensified their search for alternative energy storage solutions, recognizing that a sustainable future required a dramatic shift in how we harness and deploy power. #BatteryHistory #EnergyCrisis #Innovation At the forefront of this scientific endeavor was British chemist M. Stanley Whittingham, working at Exxon. Whittingham was exploring the concept of superconductivity when he discovered an extremely energy-rich material: titanium disulfide. He realized that this material could house lithium ions within its molecular structure—a process known as intercalation. Whittingham ingeniously paired a titanium disulfide cathode with an anode made of metallic lithium. The resulting battery was revolutionary, boasting an unprecedented voltage and the ability to operate at room temperature. However, the use of pure metallic lithium presented a catastrophic flaw: the formation of needle-like structures called dendrites. As the battery was repeatedly charged and discharged, these dendrites grew from the anode, eventually piercing the separator and causing short circuits that frequently led to spectacular and dangerous fires. Exxon ultimately deemed the technology too hazardous for commercialization. #ScienceHistory #Whittingham #Chemistry The torch was subsequently passed to John B. Goodenough, an American physicist working at the University of Oxford in the 1980s. Goodenough possessed a profound understanding of solid-state physics and reasoned that metal oxides would offer a superior alternative to metal sulfides for the cathode material. After rigorous experimentation, Goodenough's team discovered that lithium cobalt oxide (LCO) could serve as an exceptional cathode. This material not only safely housed lithium ions but also nearly doubled the voltage potential of Whittingham's earlier design. Goodenough's breakthrough was a watershed moment, providing the high energy density necessary to power portable electronics. #NobelPrize #JohnGoodenough #MaterialsScience Yet, the danger of the metallic lithium anode remained unresolved. Enter Akira Yoshino, a Japanese chemist at the Asahi Kasei Corporation. In 1985, Yoshino completely eliminated pure lithium from the battery, substituting the metallic anode with a carbonaceous material—specifically, petroleum coke—that could safely intercalate lithium ions just like the Goodenough cathode. This momentous modification birthed the first safe, viable prototype of the modern lithium-ion battery. It was no longer a fire hazard, but a robust, rechargeable power source capable of enduring hundreds of cycles. Recognizing the monumental commercial potential, Sony partnered with Asahi Kasei to release the world's first commercial lithium-ion battery in 1991. This trio of visionaries—Whittingham, Goodenough, and Yoshino—was rightfully awarded the Nobel Prize in Chemistry in 2019, cementing their legacy as the architects of the wireless revolution. #AkiraYoshino #Sony #NobelLaureates The Anatomy of a Powerhouse: How It Works To understand the magic of a lithium-ion battery, one must visualize it not as a static reservoir of power, but as a dynamic, microscopic ecosystem where billions of ions engage in a continuous, synchronized migration. At its core, every lithium-ion cell is composed of four primary components: the cathode (positive electrode), the anode (negative electrode), the electrolyte, and the separator. The fundamental operating principle is eloquently simple and is often referred to as the "rocking-chair" mechanism, describing the gentle back-and-forth movement of lithium ions between the two electrodes. #Electrochemistry #RockingChairMechanism #BatteryScience The cathode is the source of the lithium ions and dictates the battery's voltage and overall capacity. It is typically composed of a lithium metal oxide structure. The anode, conversely, is responsible for storing the lithium ions when the battery is fully charged and is almost universally constructed from graphite, a crystalline form of carbon. Separating these two electrodes is a microscopically thin, porous polymer membrane known as the separator. This vital component prevents physical contact between the anode and cathode—which would cause a catastrophic short circuit—while simultaneously allowing the infinitesimally small lithium ions to pass through its pores. #BatteryComponents #GraphiteAnode #Cathode Bathing the entire internal structure is the electrolyte, a chemical medium that facilitates the transport of ions. In traditional lithium-ion batteries, this electrolyte is a liquid solution comprising lithium salts, such as lithium hexafluorophosphate (LiPF6), dissolved in organic carbonate solvents. #Electrolyte #LiPF6 #ChemicalEngineering When you plug your device into a charger, an external electrical current is applied to the cell. This energy forces the lithium ions to detach from the cathode lattice. They dive into the liquid electrolyte, swim through the pores of the separator, and embed themselves within the layered atomic structure of the graphite anode. This process is known as intercalation. The battery is now in a charged state, akin to a coiled spring brimming with potential energy. #Intercalation #ChargingCycle #TechExplained When you unplug the device and begin to use it, the process reverses. The lithium ions, seeking a more stable energy state, spontaneously release themselves from the graphite anode and travel back across the electrolyte and separator to nestle once again within the cathode. As they make this internal journey, electrons—which cannot pass through the electrically insulating separator—are forced to travel through the external circuit of your device, providing the electrical current that illuminates your screen, powers your processor, or turns the wheels of an electric vehicle. #DischargeCycle #Electricity #PowerGeneration A Symphony of Materials: Chemistries and Trade-offs While the fundamental "rocking-chair" mechanism remains constant, not all lithium-ion batteries are created equal. The specific performance characteristics of a battery—its energy density, power output, lifespan, safety profile, and cost—are heavily dictated by the precise chemical composition of its cathode. This has led to the development of a diverse family of lithium-ion chemistries, each tailored to excel in distinct applications. There is no universally perfect battery; there are only calculated trade-offs. #BatteryChemistries #MaterialsEngineering #Innovation The pioneer of the commercial era, Lithium Cobalt Oxide (LCO), remains a staple in the realm of portable electronics. LCO boasts an exceptionally high specific energy, meaning it can store a tremendous amount of power in a very compact, lightweight package. This makes it the undisputed champion for smartphones, tablets, and laptops, where every millimeter of space and gram of weight is fiercely contested. However, LCO is hampered by a relatively short lifespan, poor thermal stability (making it prone to overheating), and a heavy reliance on cobalt—a toxic, expensive, and ethically fraught metal. #LCO #ConsumerElectronics #Smartphones For applications demanding high power and greater stability, such as power tools, e-bikes, and the vast majority of modern electric vehicles (EVs), the industry has pivoted toward Lithium Nickel Manganese Cobalt Oxide (NMC). NMC is the workhorse of the EV revolution. By blending the high energy density of nickel, the structural stability of manganese, and the conductive properties of cobalt, engineers can fine-tune the cathode's performance. The automotive industry is constantly pushing for lower cobalt and higher nickel content (such as NMC 811) to increase driving range and reduce costs, though this requires highly sophisticated battery management systems to maintain safety. #NMC #ElectricVehicles #EVRevolution A close cousin to NMC is Lithium Nickel Cobalt Aluminum Oxide (NCA), famously championed by Tesla and Panasonic. NCA shares many of the high-energy characteristics of NMC but substitutes manganese with aluminum to enhance the battery's overall lifespan and structural integrity. It offers exceptional driving range and fast-charging capabilities, cementing its status in the premium EV market. #NCA #Tesla #CleanEnergy Contrasting sharply with the nickel-based chemistries is Lithium Iron Phosphate (LFP). While LFP possesses a significantly lower energy density than NMC or NCA—meaning an LFP battery will be heavier and bulkier for the same amount of power—it compensates with an unmatched safety profile and an extraordinary cycle life. The robust chemical bond between iron, phosphorus, and oxygen makes LFP highly resistant to thermal runaway, even when punctured or severely damaged. Furthermore, LFP entirely eliminates the need for expensive nickel and controversial cobalt, utilizing abundant, low-cost materials. Originally confined to heavy-duty applications like electric buses and grid-scale storage, LFP has experienced a massive resurgence in recent years, increasingly powering standard-range passenger EVs due to its cost-effectiveness and unparalleled longevity. #LFP #EnergyStorage #SustainableTech On the anode side of the equation, the pursuit of greater energy capacity is leading researchers away from traditional graphite and toward silicon. A single silicon atom can theoretically bind with four lithium ions, offering a staggering tenfold increase in capacity compared to graphite. However, silicon undergoes severe volumetric expansion—swelling by up to 300% during charging—which causes the anode to physically fracture and degrade rapidly. The current industry compromise involves blending small amounts of silicon into graphite anodes, a delicate balancing act that incrementally boosts capacity without compromising structural integrity. #SiliconAnode #NextGenBatteries #MaterialScience The Manufacturing Odyssey The transformation of raw metallic powders and chemical solvents into a precision-engineered, high-performance battery cell is a marvel of modern industrial manufacturing. The process is remarkably complex, demanding exacting tolerances, hyper-clean environments, and sophisticated automation. #ManufacturingProcess #IndustrialTech #Engineering The odyssey begins in the mixing room, where the active cathode or anode powders are meticulously blended with specialized polymer binders and conductive carbon additives. This dry mixture is then combined with a solvent to create a viscous, ink-like substance known as a slurry. The consistency and homogeneity of this slurry are paramount; even microscopic agglomerations can create "hot spots" that severely degrade battery performance. #BatterySlurry #ChemicalProcessing #QualityControl Next, the slurry undergoes a coating process. It is continuously pumped onto a massive, rapidly moving roll of ultra-thin metallic foil—aluminum for the cathode and copper for the anode. The coated foil passes through sprawling, multi-stage drying ovens that meticulously evaporate the solvent, leaving behind a solid, uniform layer of electrode material firmly adhered to the metal current collector. To maximize the battery's energy density, the coated foils are subsequently fed through massive, highly pressurized rollers in a process called calendering. This compresses the electrode material to an exact porosity, ensuring optimal electrical conductivity and ion transport. #RollToRoll #ElectrodeCoating #PrecisionManufacturing The giant rolls of calendered electrodes are then slit into precise widths and transferred to an ultra-dry environment, as even trace amounts of ambient humidity can fatally react with the battery's internal components. In the assembly phase, the anode, cathode, and polymeric separator are layered together. In cylindrical cells (like those ubiquitous in laptops and many EVs), these layers are tightly wound together into a spiral structure known as a "jelly roll." In pouch or prismatic cells, the layers are stacked individually or continuously z-folded. #JellyRoll #CellAssembly #DryRoom The assembled internal structure is inserted into its final casing—a steel cylinder, a rigid aluminum rectangle, or a flexible polymer pouch. The cell is securely welded, leaving only a tiny port open. Through this port, the liquid electrolyte is vacuum-injected, completely saturating the internal pores of the electrodes and separator. Finally, the cell is permanently sealed. #ElectrolyteFilling #CellSealing #BatteryProduction However, the manufacturing process is not yet complete. The freshly sealed cell is essentially dormant; it must be brought to life through a critical, time-consuming process known as "formation." During formation, the battery undergoes its very first, carefully controlled charge and discharge cycles at highly specific voltages and temperatures. This initial charging process electrochemically decomposes a small fraction of the electrolyte, forming a protective microscopic shield on the surface of the graphite anode called the Solid Electrolyte Interphase (SEI). A stable, robust SEI layer is absolutely critical for the battery's long-term safety and lifespan. Once formation is complete, the cells undergo rigorous quality assurance testing and a period of aging to identify any latent defects before they are shipped to power the world. #SEILayer #BatteryFormation #QualityAssurance The Shadows: Degradation, Safety, and Thermal Runaway Despite its transformative capabilities, the lithium-ion battery is not invincible. It is inherently a consumable component, subject to irreversible electrochemical wear and tear over time. Furthermore, the immense amount of energy densely packed within these cells necessitates profound respect for safety protocols. Understanding the mechanisms of degradation and failure is crucial for pushing the boundaries of battery technology. #BatteryDegradation #SafetyFirst #TechChallenges The primary culprit behind a battery's gradual loss of capacity is the continuous thickening of the SEI layer. While the initial SEI layer formed during manufacturing is essential for protection, it slowly but inexorably continues to grow with every charge and discharge cycle. This parasitic growth consumes active lithium ions, permanently removing them from the rocking-chair mechanism, and simultaneously increases the internal electrical resistance of the cell. Eventually, the battery can no longer hold a practical charge. #CapacityFade #LithiumLoss #BatteryLife Another severe degradation mechanism is lithium plating. If a battery is charged too rapidly (fast charging) or at excessively low temperatures, the lithium ions may not be able to intercalate into the graphite structure fast enough. Instead, they pile up on the surface of the anode, reverting to metallic lithium. This not only causes a massive loss of usable capacity but also seeds the growth of dendrites. #LithiumPlating #FastCharging #ColdWeather Dendrites are the terrifying specter haunting the lithium-ion industry. These microscopic, needle-like metallic projections grow from the anode towards the cathode. If a dendrite manages to pierce the incredibly thin polymer separator, it creates an internal short circuit. The massive, uncontrolled flow of electrical current generates intense, localized heat. Because the liquid electrolyte is highly flammable and the metal oxide cathode readily releases oxygen when heated, this short circuit can trigger a catastrophic chain reaction known as thermal runaway. #Dendrites #ShortCircuit #ThermalRunaway During thermal runaway, the temperature inside the cell surges exponentially in seconds, causing the electrolyte to boil and rupture the casing, resulting in violent venting, smoke, and self-sustaining fires that are notoriously difficult to extinguish. To mitigate these risks, modern battery packs—especially in EVs—are equipped with sophisticated Battery Management Systems (BMS). The BMS acts as the brain of the battery, continuously monitoring the voltage, current, and temperature of every individual cell, dynamically adjusting charging rates, and actively cooling the pack to prevent dangerous conditions. #BMS #BatterySafety #EngineeringSolutions The Geopolitical and Environmental Equation The exponential surge in demand for lithium-ion batteries has precipitated a global scramble for the raw materials necessary to build them. This insatiable appetite has profoundly reshaped global supply chains and brought complex geopolitical and environmental issues to the forefront. The metals required—lithium, cobalt, nickel, and manganese—are heavily concentrated in specific geographic regions, creating strategic vulnerabilities and intense international competition. #Geopolitics #SupplyChain #CriticalMinerals Lithium, often dubbed "White Petroleum," is primarily extracted in two ways. In the arid salt flats of the "Lithium Triangle" (Chile, Argentina, and Bolivia), lithium-rich brine is pumped to the surface and left to evaporate in massive, colorful ponds over several months. While relatively low-cost, this method consumes vast amounts of scarce water resources in already parched ecosystems, negatively impacting indigenous communities and local agriculture. Alternatively, lithium is mined from hard rock spodumene deposits, predominantly in Australia. This process is faster but significantly more energy-intensive, leaving a larger carbon footprint. #LithiumMining #WhitePetroleum #WaterScarcity Cobalt presents the most profound ethical and geopolitical challenges. Over 70% of the world's cobalt supply is mined in the Democratic Republic of the Congo (DRC). While large-scale industrial mining accounts for the majority of output, a significant portion is extracted by artisanal miners operating in horrific, unregulated conditions. Reports of child labor, severe human rights abuses, and devastating environmental degradation have plagued the DRC's cobalt industry. Consequently, battery manufacturers and automakers are aggressively engineering new chemistries to reduce or entirely eliminate cobalt from their supply chains. #CobaltMining #HumanRights #DRC Nickel, essential for high-energy EV batteries, carries its own environmental baggage. The processing of laterite nickel ores, predominantly found in Indonesia, relies heavily on High-Pressure Acid Leaching (HPAL)—a complex, capital-intensive process that generates massive quantities of toxic tailings. Disposing of this waste safely in tropical, seismically active regions is an ongoing environmental challenge. Furthermore, the processing of these metals is heavily dominated by China, granting them immense geopolitical leverage over the global energy transition. The realization of a truly sustainable, electrified future demands not only technological innovation but also a complete paradigm shift towards responsible, transparent, and diversified global mining practices. #Nickel #EnvironmentalImpact #GlobalTrade The Afterlife: Recycling and the Circular Economy As the first generation of mass-market electric vehicles approaches the end of its operational lifespan, the world is facing a looming wave of spent lithium-ion batteries. Disposing of these incredibly dense, chemically complex, and potentially hazardous modules in landfills is both an environmental disaster and a catastrophic waste of valuable resources. Consequently, establishing a robust, efficient recycling infrastructure is arguably the most critical hurdle facing the battery industry today. The goal is to forge a "circular economy" where the metals from old batteries are continuously recovered and repurposed to build new ones. #BatteryRecycling #CircularEconomy #Sustainability Currently, battery recycling is a technologically daunting and economically challenging endeavor. Traditional methods predominantly rely on pyrometallurgy, a process that involves literally tossing whole batteries into massive, energy-intensive smelting furnaces. While pyrometallurgy effectively recovers valuable heavy metals like cobalt, nickel, and copper in a mixed alloy form, the crucial lithium, aluminum, and organic electrolytes are completely destroyed or lost in the slag. #Pyrometallurgy #RecyclingChallenges #Ewaste The industry is rapidly pivoting toward more sophisticated hydrometallurgical techniques. In hydrometallurgy, the spent batteries are meticulously discharged, mechanically shredded into a substance known as "black mass," and then subjected to a series of chemical leaching processes using potent acids and solvents. This complex chemical separation allows for the highly efficient recovery of battery-grade lithium, cobalt, nickel, and manganese salts, which can then be directly reintegrated into the manufacturing supply chain. However, hydrometallurgy requires massive chemical inputs, generates highly toxic wastewater, and demands extensive purification steps. #Hydrometallurgy #BlackMass #GreenTech A nascent but highly promising frontier is "direct recycling." Instead of destroying the complex crystalline structure of the cathode material only to rebuild it from scratch, direct recycling seeks to physically separate the cathode powder, clean it, and "heal" its degraded structure by re-injecting fresh lithium. If successfully scaled, direct recycling promises to drastically reduce the energy consumption, chemical waste, and overall cost of recycling. #DirectRecycling #Innovation #CleanEnergyTransition Beyond chemical recycling, a vibrant market is emerging for "second-life" applications. An EV battery is typically considered at the end of its automotive life when its capacity drops to around 80%. While no longer capable of providing sufficient driving range, these batteries still possess a vast amount of viable energy storage capacity. Instead of being immediately recycled, these degraded packs can be repurposed for stationary grid storage, absorbing excess solar and wind power during the day and discharging it during peak evening hours, effectively extending their useful life by a decade or more. #SecondLifeBatteries #GridStorage #RenewableEnergy Beyond Lithium-Ion: The Horizon of Energy Storage While the lithium-ion battery will undoubtedly remain the bedrock of global energy storage for the foreseeable future, the inherent physical limitations of the technology are coming into sharp focus. The quest for greater energy density, faster charging speeds, superior safety, and absolute independence from critical, scarce minerals is driving intense research into next-generation battery architectures. The horizon is teeming with innovative contenders vying to dethrone, or at least supplement, the lithium-ion sovereign. #NextGenBatteries #FutureTech #EnergyInnovation The most highly anticipated breakthrough is the Solid-State Battery. As the name suggests, this architecture entirely replaces the highly flammable, unstable liquid electrolyte and polymer separator with a solid, ion-conducting ceramic or polymer layer. This fundamental shift eliminates the risk of catastrophic thermal runaway, creating a fundamentally safer cell. Furthermore, a solid electrolyte provides sufficient physical resistance to suppress the growth of dendrites, allowing for the use of a pure metallic lithium anode. This substitution theoretically doubles the energy density of the battery, promising electric vehicles that can travel over a thousand miles on a single charge and recharge in mere minutes. While solid-state technology remains extremely challenging to manufacture at scale, monumental billions are being poured into its commercialization. #SolidStateBatteries #QuantumScape #FutureOfEVs Another major avenue of research is the Lithium-Sulfur (Li-S) battery. By pairing a lithium metal anode with a sulfur-based cathode, engineers can achieve theoretical energy densities up to five times greater than traditional lithium-ion. Sulfur is abundant, extremely cheap, and environmentally benign. However, Li-S batteries are currently plagued by the "polysulfide shuttle effect," a complex chemical reaction that rapidly degrades the battery's capacity within just a few dozen cycles. Solving this electrochemical puzzle remains one of the holy grails of materials science. #LithiumSulfur #MaterialScience #Chemistry Simultaneously, the industry is witnessing the rapid rise of the Sodium-Ion (Na-ion) battery. Sodium sits directly below lithium on the periodic table and behaves in a remarkably similar electrochemical manner. However, sodium is thousands of times more abundant than lithium, readily extractable from the world's oceans, and completely immune to the geopolitical constraints associated with the Lithium Triangle. While sodium ions are larger and heavier than lithium ions—resulting in a lower energy density that makes them unsuitable for long-range EVs or lightweight electronics—sodium-ion batteries are exceptionally cheap to produce, perform remarkably well in extreme cold, and are perfectly positioned to dominate the massive, rapidly expanding market for stationary grid storage and low-cost urban transit. #SodiumIon #AbundantEnergy #GridScale Conclusion: The Pulse of Tomorrow The story of the lithium-ion battery is a magnificent narrative of human curiosity intersecting with desperate necessity. From a fragile, dangerous experiment in an oil company laboratory to the ubiquitous, indispensable powerhouse that defines our daily lives, its evolution has been nothing short of miraculous. It has untethered us from the wall socket, empowered the telecommunications revolution, and provided the critical technological foundation necessary to finally break our century-long addiction to fossil fuels. #LithiumBattery #EnergyTransition #ClimateAction As we stand on the precipice of a completely electrified global economy, the challenges are undeniable. We must untangle complex, ethically fraught supply chains, minimize ecological destruction, and conquer the monumental task of establishing a truly circular battery economy. Yet, the same relentless spirit of innovation that guided Whittingham, Goodenough, and Yoshino continues to drive thousands of brilliant minds worldwide. Whether through the perfection of solid-state architecture, the mastery of abundant sodium, or the relentless optimization of existing lithium-ion chemistries, the pursuit of superior energy storage remains the most critical technological endeavor of our time. The lithium-ion battery is not merely an invention; it is the beating heart of a cleaner, more sustainable, and infinitely more connected tomorrow. #TheFutureIsElectric #SustainableFuture #InnovationJourney #LithiumIon #Batteries #ElectricVehicles #EnergyStorage #Tech Related InsightsAI’s Alchemy in Pharma: How Generative Models Are Brewing the Next Blockbuster Drugs Fusing the Senses: The Integration of LiDAR and Computer Vision in Level 4 Autonomy Beyond the Fingerprint: Unlocking Identity with Iris, Vein, and Behavioral Biometrics{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Heartbeat of the Modern World: A Deep Dive into the Lithium-Ion Battery?", "acceptedAnswer": { "@type": "Answer", "text": "An exhaustive exploration of the lithium-ion battery, unraveling its history, intricate chemistry, manufacturing processes, environmental impacts, and what the future holds for energy storage." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Heartbeat of the Modern World: A Deep Dive into the Lithium-Ion Battery?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by John Doe." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
The Symphony of Keystrokes: The Ultimate Guide to Mechanical Keyboards There is a distinct, almost romantic rhythm to the sound of a well-tuned mechanical keyboard. It is a symphony of plastic, metal, and springs—a staccato drumbeat that accompanies the flow of thoughts onto a digital canvas. For decades, the ubiquitous, mushy rubber-dome keyboard dominated the desks of offices and homes around the world, treating typing as a purely utilitarian chore. But in recent years, a massive cultural and technological renaissance has taken place. The mechanical keyboard has returned from the annals of computing history to claim its rightful throne, captivating enthusiasts, gamers, and writers alike. #MechanicalKeyboards #TechRenaissance But what exactly is a mechanical keyboard? Why are people willing to spend hundreds, if not thousands, of dollars on a peripheral that comes free with most pre-built computers? This comprehensive guide will take you on a journey through the intricate, obsessive, and endlessly fascinating world of mechanical keyboards. Whether you are a competitive gamer looking for an edge, a programmer looking to save your fingers from fatigue, or simply an aesthetically minded desk-setup enthusiast, this guide will serve as your ultimate resource. #DeskSetup #PCGaming A Brief History: From Typewriters to Membranes and Back Again To appreciate the modern mechanical keyboard, one must briefly look back at the history of typing interfaces. The earliest typewriters were entirely mechanical marvels of levers, arms, and ink ribbons. They required immense physical force to operate but provided undeniably clear feedback. As the world transitioned to electronic computers in the mid-20th century, early terminals carried over this robust mechanical ethos. Keyboards in the 1970s and 1980s, such as the legendary IBM Model F and Model M, used incredibly complex and heavy physical switch mechanisms. They were built like tanks and cost a small fortune to manufacture. However, as the personal computing revolution exploded in the 1990s, manufacturers faced intense pressure to slash costs. The solution was the membrane and rubber-dome keyboard. By replacing dozens of individual mechanical switches with a single sheet of printed circuitry and a layer of molded rubber domes, manufacturers reduced the cost of a keyboard from a hundred dollars to mere pennies. The world embraced this cheaper alternative, and for two decades, the "mushy" typing experience became the global standard. The tactile magic of the early PC era was all but forgotten by the mainstream. #RetroTech #ComputingHistory The resurgence of mechanical keyboards began in the late 2000s and early 2010s, spearheaded almost entirely by the PC gaming community. Brands like Razer, SteelSeries, and Corsair realized that gamers needed precise, durable, and highly responsive inputs. They resurrected the Cherry MX mechanical switch—a design that had quietly survived in industrial point-of-sale systems—and wrapped it in aggressive, RGB-lit "gamer" aesthetics. Soon after, purists and typing enthusiasts splintered off from the gaming mainstream, creating the "Custom Mechanical Keyboard" community we know today. This subculture focused intensely on acoustics, premium materials, minimalist aesthetics, and the joy of DIY building. The Fundamentals: Anatomy of a Mechanical Switch To understand the appeal of mechanical keyboards, one must understand what happens beneath the keycaps. Most modern, budget-friendly keyboards use the aforementioned membrane technology. When you press a key, you collapse a rubber dome, which then pushes down on a membrane to complete an electrical circuit. This design has a fatal flaw: it offers no distinct tactile feedback until the key has "bottomed out" (hit the very bottom of the plastic housing). It feels like typing on a wet sponge. #KeyboardAnatomy #TechExplained A mechanical keyboard uses individual, self-contained physical switches beneath every single key. The classic MX-style mechanical switch is composed of four primary parts:The Housing: Divided into a top housing and a bottom housing, usually made of plastics like Nylon, Polycarbonate, or POM. The housing holds all the components together and significantly influences the switch's sound signature. The Stem: The moving plastic piece inside the switch. Its shape determines whether the switch is linear, tactile, or clicky. The top of the stem features a cross-shaped mount that holds the keycap. The Spring: A coiled metal spring that dictates the "weight" of the keystroke. Springs are measured in grams of force required to bottom out (e.g., a 62g spring vs. an 80g spring). The Contact Leaf: Two tiny pieces of metal inside the bottom housing. When the stem moves downward, it pushes the leaves together, completing the electrical circuit and registering the keystroke.This mechanism offers profound advantages. Mechanical switches are incredibly durable, often rated for 50 million to 100 million keystrokes. They offer absolute consistency, ensuring the keys feel identical year after year. Most importantly, because the actuation point (where the key registers) happens before the key bottoms out, typists can learn to strike keys with just enough force, floating over the keyboard and reducing long-term finger and wrist fatigue. #Ergonomics #TypingTips The Holy Trinity of Switches: Linear, Tactile, and Clicky If the mechanical keyboard is a musical instrument, the switches are its strings. They are the heart and soul of the typing experience. While there are hundreds of different boutique switches on the market today, almost all of them fall into three primary categories based on their feel and sound profile. #MechanicalSwitches Linear Switches Linear switches are the smoothest of the bunch. As the name implies, their travel path is a straight, uninterrupted line from top to bottom. There is no bump, no click, and no resistance other than the steady, linear pushback of the coil spring. Gamers heavily favor linear switches because the lack of a tactile bump allows for rapid, successive keystrokes without any physical friction interrupting the flow. Double-tapping keys in a fast-paced shooter feels effortless. The most famous example is the Cherry MX Red. However, the custom community has pushed the envelope far beyond basic Cherry switches. Enthusiasts now seek out boutique linear switches like the Gateron Ink Black V2, NovelKeys Cream, C³ Tangerines, and Alpaca switches. These switches are engineered with proprietary plastic blends to offer unprecedented, frictionless smoothness, especially when carefully lubricated by hand. #LinearSwitches #PCGamer Tactile Switches For software developers, copywriters, and anyone who types thousands of words a day, tactile switches are often the holy grail. Partway through the downward keypress, the stem of a tactile switch features a physical protrusion that brushes past the metal contact leaf. This creates a small, satisfying bump that you can feel in your fingertips, letting you know exactly when the keystroke has been registered. This feedback allows touch typists to stop pressing down the moment they feel the bump, preventing bottom-outs and increasing overall typing speed. The Cherry MX Brown is the quintessential entry-level tactile switch, often recommended to beginners as a middle-ground between gaming and typing. But for enthusiasts seeking a much more pronounced, sharp, and satisfying tactile event, switches like the Drop Holy Panda, Zealios V2, and Gazzew Boba U4T have become legendary gold standards. These "hyper-tactile" switches deliver a massive, rounded bump that makes typing feel incredibly rhythmic and purposeful. #TypingEnthusiast #TactileFeedback Clicky Switches Clicky switches take the tactile bump and add an intentional, audible, high-pitched "click" sound. This acoustic feedback is achieved either via a "click jacket" (a two-part plastic stem where the bottom sleeve slides down and violently snaps against the housing) or a "click bar" (a tiny metal bar stretched across the housing that gets pinged by the passing stem like a guitar string). Clicky switches offer the most sensory feedback of any switch type. You feel the sharp bump, and you hear the crisp click. The Cherry MX Blue is the most famous clicky switch, producing a nostalgic, typewriter-esque clatter. However, Kailh's Box Jade and Box Navy switches have revolutionized the clicky market with their thick click-bar mechanisms, producing a crisper, heavier, and far more satisfying acoustic signature. A crucial word of caution: clicky switches are notoriously loud. They are universally considered unacceptable for open-plan offices, quiet libraries, or shared living spaces. Bring them to work at your own peril. #ClickClack #OfficeEtiquette Beyond the Basics: Alternative Switch Technologies While the traditional MX-style mechanical switch dominates the current landscape, history and modern innovation have provided several fascinating alternative technologies that eschew traditional metal contact leaves. #VintageTech #KeyboardInnovation Buckling Springs (The IBM Legacy) No deep dive into mechanical keyboards is complete without paying respect to the grandfather of them all: the IBM Model M. Introduced in the 1980s, this massive, indestructible beige behemoth used patented "buckling spring" technology. Beneath each keycap sits a long coil spring. When pressed, the spring compresses until it literally buckles and folds outward, violently striking the side of the plastic barrel and completing a capacitive or membrane circuit below. This buckling action creates a massive, resonant metallic "PING" and a sharp, incredibly heavy tactile bump. It is a legendary, aggressive typing experience that many purists argue has never been surpassed by modern plastics. Topre (Electro-Capacitive) Hailing from Japan, Topre switches are a fascinating, highly premium hybrid. They utilize a rubber dome, but not in the cheap, mushy way budget keyboards do. Beneath a high-quality, perfectly tuned rubber dome sits a conical metal spring over a printed circuit board. As you press the key, the dome collapses (providing a beautifully rounded tactile bump), and the coil spring compresses. The PCB reads the change in capacitance generated by the spring's proximity and registers the keystroke well before the key bottoms out. Topre switches offer a deeply satisfying, thumping "thock" sound and a pillowy feel that is often described as typing on rain drops. Keyboards featuring Topre switches, such as the Happy Hacking Keyboard (HHKB) and Realforce lines, are extremely expensive but possess a fiercely loyal cult following. #Topre #HHKB Optical and Hall Effect Switches Modern competitive gaming has driven innovation toward hyper-fast response times and absolute durability. Optical switches eliminate metal contacts entirely, instead using a beam of infrared light inside the switch housing. When the stem moves down, it breaks (or allows) the light beam, instantly registering the key at the speed of light. Because there are no physical metal leaves to bounce against each other, optical switches don't require software "debouncing" algorithms, reducing input latency. Even more revolutionary are Hall Effect switches, like those utilized by Wooting and SteelSeries. These switches use magnets embedded in the stem and sensors on the PCB to measure the exact, analog distance the key has traveled in real-time. This allows users to dynamically set custom actuation points via software. You can set your WASD keys to an ultra-sensitive 0.1mm actuation for split-second strafing in a shooter, and your typing keys to a deeper 2.0mm actuation to prevent typos. It even enables true analog input, where pressing a key halfway makes a game character walk, and pressing it fully makes them sprint, much like the analog stick on a console controller. #GamingTech #HallEffect Form Factors: How Many Keys Do You Really Need? When you picture a keyboard, you likely visualize a standard "Full-Size" board with 104 or 108 keys. This includes the alphanumeric cluster, a function row (F1-F12), navigation keys (Home, End, Page Up), arrow keys, and a dedicated number pad on the far right. But in the mechanical keyboard world, bigger is rarely considered better. Removing rarely used keys frees up valuable desk real estate, allows you to bring your mouse closer to the center of your body for superior ergonomics, and vastly improves the aesthetic balance of a desk setup. #Ergonomics #Minimalism #DeskSetupTenkeyless (TKL / 80%): The most popular alternative layout. It simply chops off the number pad on the right side, leaving the arrow keys and navigation cluster perfectly intact. This is the ideal layout for gamers who need more sweeping space for their mouse but cannot live without dedicated arrow and function keys. 75%: A slightly more compact evolution of the TKL. It retains the function row and arrow keys but squishes everything together into a single, contiguous block without any gaps, saving an extra inch or two of width. 65%: The function row is completely removed, relegated to a secondary "layer" accessed by holding a "Fn" key (pressing Fn + 1 outputs F1). Dedicated arrow keys and a vertical column of essential navigation keys (like Delete and Page Up) remain. This is widely considered the perfect sweet spot for enthusiasts. 60%: The true minimalist standard. No function row, no number pad, no navigation cluster, and no dedicated arrow keys. Everything outside the alphanumeric cluster and modifiers is accessed via layers. It is highly portable, perfectly symmetrical, and incredibly popular among hardcore custom builders. 40% and Ortholinear: The extreme, uncompromising end of the spectrum. These tiny keyboards strip away the number row entirely, leaving only letters and a few modifiers. Typists use complex "chords" and multiple deeply programmed layers to type numbers and symbols. Furthermore, many of these boards are "Ortholinear," meaning the keys are aligned in a perfect, un-staggered grid. Proponents argue this vertical alignment is vastly superior for finger ergonomics, as it mimics the natural curling motion of the human hand rather than the slanted stagger inherited from mechanical typewriters. #Ortholinear #CustomLayoutsKeycaps: The Crown Jewels of Customization A keyboard's switches dictate how it feels, but its keycaps dictate how it looks and, to a surprisingly massive extent, how it sounds. Upgrading keycaps is the easiest and most profound visual transformation you can apply to a keyboard. #Keycaps #CustomPC The Plastics: ABS, PBT, and Beyond Keycaps are almost exclusively injection-molded from two types of plastic: Acrylonitrile Butadiene Styrene (ABS) and Polybutylene Terephthalate (PBT). ABS is the standard plastic used on almost all mass-market consumer keyboards. It is relatively cheap, easy to mold perfectly, and allows for extremely vibrant, saturated colors. However, ABS has a significant downside for typists: it degrades and wears quickly. Over time, the mild friction and natural oils from your fingertips polish the surface of the plastic, causing the keycaps to develop an unappealing, greasy-looking "shine." PBT is the discerning enthusiast's plastic of choice. It is a denser, vastly harder plastic that strongly resists finger oils and almost never develops a shine, even after years of heavy use. PBT keycaps typically feature a slightly textured, matte, sandy feel and produce a deeper, lower-pitched, "bassier" sound when struck. While PBT historically struggled to hold bright colors without warping during manufacturing, modern techniques have largely closed the color-vibrancy gap. In recent years, experimental materials have entered the fray. POM (Polyoxymethylene) keycaps offer a slick, buttery feel, while boutique artisan manufacturers have even produced entire keycap sets cast out of cold, heavy Ceramic, offering an acoustic signature unlike anything else on earth. The Legends: Double-Shot vs. Dye-Sublimation How the letters and symbols (the "legends") are applied to the keycaps is just as important as the material. Cheap, mass-market keyboards use pad printing or laser etching. These methods essentially paint the letters onto the surface, meaning they will inevitably chip, fade, and wear off entirely with heavy use, leaving you with blank plastic nubs. High-end enthusiast keycaps utilize two premium manufacturing methods to ensure the legends last forever. Double-shot injection molding is an incredibly complex process where the inner legend is molded out of one color of plastic, and then the outer shell of the keycap is molded entirely around it in a second color. Because the legend is a physical, three-dimensional piece of plastic running all the way through the cap, it is literally impossible for it to ever wear away. Dye-sublimation (Dye-Sub) is a process used primarily on PBT keycaps where intense heat is used to vaporize ink, sinking it deep into the molecular structure of the plastic itself, staining it permanently rather than resting on top. Both methods ensure that your keyboard will look pristine for decades to come. #Design #Engineering The Profiles: Sculpting the Typing Experience Keycaps are not perfectly flat cubes. They are sculpted into different vertical "profiles" designed to cradle your fingers and reduce reaching. The OEM profile is standard on most pre-built boards, featuring a medium height and a cylindrical top row angled toward the user. The legendary "Cherry" profile is similar but slightly lower in height, and is universally beloved by enthusiasts for its supreme comfort and fast typing angle. For those who love vintage aesthetics, high-profile sets like SA (Spherical All) and MT3 dominate the market. These towering, retro-looking keycaps feature deep, bowl-like spherical indents on the top that violently hug your fingertips. Because of the massive amount of empty plastic space inside them, high-profile caps act like acoustic echo chambers, producing a massive, cavernous, booming "thock" sound. Conversely, flat, "uniform" profiles like DSA and XDA feature all rows at the exact same height and angle. While some find them less ergonomic, their uniformity makes them incredibly versatile for mixing and matching keycaps across bizarre custom layouts like 40% and split ergonomic boards. Case Materials, Plates, and Mounting Styles Once you step past entry-level keyboards, the chassis (or case) itself becomes a primary focus of engineering. Budget keyboards use cheap, hollow, injection-molded ABS plastic cases that rattle and amplify high-pitched pinging noises. Premium custom keyboards are precision CNC-milled from massive, solid blocks of aircraft-grade 6063 Aluminum, Polycarbonate (for a frosted, translucent look that diffuses RGB lighting beautifully), or even solid brass and exotic woods. A heavy, dense case absorbs harsh vibrations and anchors the keyboard to the desk, creating a premium, luxurious heft. Inside the case sits the "Plate," the rigid sheet that holds the switches in place above the PCB. The material of the plate drastically changes the typing feel. Aluminum is the standard, offering a stiff, bright typing experience. Brass plates are incredibly rigid and produce a high-pitched, musical bottom-out sound. Polycarbonate and POM plates are soft and flexible, offering a bouncy, forgiving typing feel that reduces finger fatigue. FR4 (the same fiberglass material used to make PCBs) offers a highly desirable middle-ground: softer than aluminum, but crisper than polycarbonate. How the plate and PCB are mounted to the external case—the "Mounting Style"—is the deepest rabbit hole in modern keyboard design. Tray Mount: The oldest and cheapest method. The PCB is screwed directly into standoffs at the bottom of the case. This creates an uneven, stiff typing feel, as keys near the screws are rock hard, while keys in the middle flex. Top Mount: The plate features tabs that are screwed into the top frame of the case. This offers a much more consistent, even typing feel and a clean sound profile. Gasket Mount: The current industry obsession. The plate is sandwiched between the top and bottom case using thick strips of poron foam, silicone, or rubber gaskets. The plate and PCB never touch the hard metal of the case directly. This isolates vibrations and creates a remarkably soft, bouncy, and acoustically muted typing experience that is highly sought after. #KeyboardBuild #DIYThe Art of Tuning: Lubing, Filming, and Modding For the true mechanical keyboard enthusiast, simply buying expensive parts and snapping them together is not enough. A keyboard is not finished until it has been meticulously tuned. This is where the hobby transcends mere consumerism and becomes an exercise in obsessive craftsmanship. #Modding #DIYProject The single most impactful modification one can perform is switch lubrication. Using tiny paintbrushes and highly specialized, expensive industrial lubricants like Krytox 205g0 or TriboSys 3203, enthusiasts painstakingly open each individual switch and coat the internal friction points—the stem rails, the spring, and the bottom housing. This intensely tedious process, which can easily take three to four hours for a single keyboard, completely transforms the switch. It eliminates the scratchy acoustic sound of plastic rubbing against plastic, entirely kills metallic spring "ping," and makes the keystroke feel as smooth as gliding on warm glass. Many builders also add "Switch Films"—paper-thin gaskets placed between the top and bottom housing of the switch—to eliminate any microscopic wobble and tighten the sound profile. Stabilizers—the wire mechanisms that keep long keys like the Spacebar, Shift, and Enter key from wobbling left to right—also require immense attention. An un-tuned spacebar produces a horrific, high-pitched rattling noise that can ruin the acoustic profile of an entire $500 keyboard. Enthusiasts will "clip" the plastic feet off the stabilizer stems to make them strike the PCB perfectly flat. They will heavily lubricate the metal wire with thick dielectric grease (or specialized Krytox XHT-BDZ) to eliminate metal-on-plastic rattle. They may even perform the "Holee Mod"—inserting tiny, microscopic strips of medical fabric tape inside the stabilizer stem to completely cushion the wire. Furthermore, acoustic dampening has become an esoteric art form. Builders pour liquid silicone into the bottom of their cases to add weight and kill hollowness. They carefully cut and layer dense neoprene, Poron foam, or even PE foam (the packing material) directly under the switches to manipulate the acoustics. A popular and highly accessible trick is the "Tape Mod," which involves covering the entire back of the PCB in layers of blue painter's tape. The tape acts as an acoustic low-pass filter, absorbing high-pitched pings and accentuating a deep, creamy, "marbly" sound signature that has taken platforms like YouTube and TikTok by storm. #SoundDesign #Thock #Marbly The Custom Community and the Group Buy Ecosystem If you want to enter the highest echelons of this hobby, you cannot simply log onto Amazon and add a premium custom keyboard to your digital cart. The high-end, boutique market operates almost entirely on a crowdfunding model known as the "Group Buy." #Community #GroupBuy Because boutique keyboard cases and custom keycap sets require massive upfront manufacturing and tooling costs, independent designers must crowdsource the funding. A designer will create highly detailed 3D renders of a keyboard or keycap set and run an "Interest Check" (IC) on community forums like Geekhack, KeebTalk, or the massive /r/MechanicalKeyboards subreddit. If there is enough community interest and feedback, the Group Buy officially opens for a window of a few weeks, allowing people to pre-order. Once the Group Buy closes, the collected funds are sent to overseas manufacturers. Because these are highly complex, low-volume manufacturing runs requiring strict color-matching and quality control, the wait times are substantial. Waiting six to twelve months for a milled aluminum keyboard case, or up to two years for a highly sought-after GMK double-shot ABS keycap set, is considered entirely normal in this hobby. It requires immense patience and trust, but the ultimate reward is a piece of functional, bespoke art that is entirely unique, highly personalized, and built to incredibly exacting standards that mass-market brands simply cannot replicate. The Artisan Touch No custom board is truly finished without the addition of an artisan keycap. These are singular, custom-made keycaps—usually placed on the Escape key or in the top right corner of the board—that serve as a focal point of intense artistic expression. Hand-sculpted from clay and painstakingly cast in multicolored resin, or intricately CNC-machined from exotic metals like titanium and copper, artisan keycaps are the ultimate flex in the keyboard world. They can resemble anything from menacing demonic skulls and cute animals, to incredibly detailed miniature dioramas containing tiny snow-capped mountains or koi ponds suspended in clear, polished resin. They are highly collectible, strictly limited in production, and often sold exclusively via random-draw "raffle" sales. A highly coveted artisan keycap from makers like Keyforge, Artkey, or GAF can easily fetch hundreds, or even thousands, of dollars on the aftermarket. #ArtisanKeycaps #FunctionalArt Conclusion: A Tactile Revelation Diving headfirst into the world of mechanical keyboards can be overwhelming. The endless sea of acronyms, the esoteric switch names, the fierce debates over mounting styles, and the agonizing wait times of group buys can seem entirely absurd to an outsider. Why on earth would anyone put so much effort, time, and money into a device whose sole, basic purpose is to input text into a computer? The answer is surprisingly simple: because we touch our keyboards more than almost any other object in our modern lives. For software developers, writers, data entry clerks, and dedicated gamers, the keyboard is the primary interface between the physical human mind and the digital realm. It is the tool through which we work, play, create, and communicate. To upgrade from a cheap, mushy, unsatisfying rubber dome to a bespoke, heavy, perfectly tuned mechanical keyboard is to profoundly elevate the mundane. It transforms every email you send, every line of code you compile, and every late-night gaming session from a repetitive chore into a deeply satisfying, tactile, and auditory experience. A custom mechanical keyboard is not just a computer peripheral; it is an instrument. It is a testament to the belief that the tools we use every single day should be beautiful, durable, and an absolute joy to interact with. So take the plunge, do your research, find your perfect switch, and discover the symphony of keystrokes waiting at your fingertips. Your hands will thank you. #KeyboardBuild #TechEnthusiast #MechanicalKeyboards #MechanicalKeyboards #Tech #Typing #Gaming Related InsightsThe Robotics & Autonomous Systems Engineer: Architecting the Future of Intelligent Machines Fusing the Senses: The Integration of LiDAR and Computer Vision in Level 4 Autonomy Digital Twins in Precision Medicine: Real-Time Health Monitoring and Adaptive Therapy{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Symphony of Keystrokes: The Ultimate Guide to Mechanical Keyboards?", "acceptedAnswer": { "@type": "Answer", "text": "Discover the captivating world of mechanical keyboards. From switch types and keycap profiles to the intricate art of custom building and tuning, explore why the click-clack revolution is here to stay." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Symphony of Keystrokes: The Ultimate Guide to Mechanical Keyboards?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by John Doe." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }