-
 Eleanor Sterling
- 13 Jul, 2026 09:11
The Death of Single-Modality AI: How Multi-Sensory Architectures and Embodied Models are Redefining Cognitive Computing
For the past half-decade, the machine learning landscape has been dominated by a singular obsession: scaling the text-based transformer. From GPT-3 to the latest iterations of open-weights behemoths like Llama 3, the industry has pushed the limits of auto-regressive next-token prediction over textual corpora. Yet, text is a lossy, low-bandwidth abstraction of human knowledge. The real world is continuous, spatial, temporal, auditory, and kinetic. If we limit artificial intelligence to the linguistic domain, we sentence it to a perpetual cave of shadows, processing symbols without direct physical grounding. The paradigm has officially broken. We are witnessing the meteoric rise of true Multimodal Large Language Models (MLLMs) and Vision-Language-Action (VLA) systems. This technical evolution does not simply append an image encoder to an LLM; it structurally unifies disparate sensory inputs—video, high-fidelity audio, raw waveforms, spatial point clouds, thermal signatures, and robotic joint telemetry—into unified, high-dimensional latent spaces. This article explores the deep engineering mechanics behind this multi-sensory revolution. We will dissect the mathematical formalisms of cross-modal alignment, analyze spatiotemporal tokenization in Video-LLMs, unpack the tokenization of kinetic action in embodied AI, explore direct audio-to-audio neural architectures, and look at the systems-level infrastructure required to serve these complex, multi-headed models at scale.1. Cross-Modal Alignment and the Geometry of Unified Latent Spaces At the core of any multimodal system lies a fundamental mathematical problem: how do we project data from wildly different topological manifolds (e.g., a 1D audio waveform, a 2D spatial pixel grid, and discrete text tokens) into a shared geometric space where semantically equivalent concepts reside in close proximity? Historically, models like CLIP (Contrastive Language-Image Pre-training) achieved this using dual-encoder architectures optimized via InfoNCE loss. However, dual contrastive learning only aligns pairs. The modern frontier, pioneered by architectures like Meta's ImageBind (CVPR 2023), utilizes a hub-and-spoke model where a single modality (typically images) acts as the central binding medium. By aligning text, audio, depth, thermal, and IMU (inertial measurement unit) data to image embeddings, all modalities inherit alignment with one another without requiring explicit pairwise training data. Mathematically, let $x_i^I$ be an image representation and $x_i^M$ be a representation in another modality $M$ (e.g., audio). The projection matrices $W_I$ and $W_M$ map these representations into a shared $d$-dimensional vector space. The contrastive loss for a batch of size $N$ is defined as: $$\mathcal{L}{I, M} = -\frac{1}{N} \sum{i=1}^N \log \frac{\exp(\cos(W_I x_i^I, W_M x_i^M) / \tau)}{\sum_{j=1}^N \exp(\cos(W_I x_i^I, W_M x_j^M) / \tau)}$$ where $\tau$ is a learnable temperature parameter and $\cos(u, v) = \frac{u \cdot v}{|u| |v|}$. To feed these aligned embeddings into an auto-regressive decoder, we utilize linear projection layers or multi-head cross-attention bottlenecks (such as the Perceiver Resampler in Flamingo). This projects variable-length visual or auditory tokens into a fixed-sequence prefix that the causal transformer can ingest alongside textual embeddings.Below is a PyTorch implementation of a multi-modal projection bottleneck that aligns audio and visual feature sequences into a unified dimension suitable for insertion as soft-prompts into a decoder LLM: import torch import torch.nn as nn import torch.nn.functional as Fclass CrossModalProjectionBridge(nn.Module): def __init__(self, visual_dim: int, audio_dim: int, joint_dim: int, num_query_tokens: int): super().__init__() self.num_query_tokens = num_query_tokens self.joint_dim = joint_dim # Projection layers to align input dims to a shared space self.visual_proj = nn.Linear(visual_dim, joint_dim) self.audio_proj = nn.Linear(audio_dim, joint_dim) # Learnable query embeddings to compress variable length sequences self.query_tokens = nn.Parameter(torch.randn(1, num_query_tokens, joint_dim)) # Cross-attention block to pool representations self.cross_attention = nn.MultiheadAttention(embed_dim=joint_dim, num_heads=8, batch_first=True) self.layer_norm = nn.LayerNorm(joint_dim) self.ffn = nn.Sequential( nn.Linear(joint_dim, joint_dim * 4), nn.GELU(), nn.Linear(joint_dim * 4, joint_dim) ) def forward(self, visual_feats: torch.Tensor, audio_feats: torch.Tensor) -> torch.Tensor: # visual_feats: [batch, seq_v, visual_dim] # audio_feats: [batch, seq_a, audio_dim] batch_size = visual_feats.size(0) # Project to joint dimension v_proj = self.visual_proj(visual_feats) # [batch, seq_v, joint_dim] a_proj = self.audio_proj(audio_feats) # [batch, seq_a, joint_dim] # Concatenate multimodal context along the sequence dimension multimodal_context = torch.cat([v_proj, a_proj], dim=1) # [batch, seq_v + seq_a, joint_dim] # Expand query tokens to match batch size queries = self.query_tokens.expand(batch_size, -1, -1) # [batch, num_query, joint_dim] # Perform Cross-Attention: queries attend to key-values from multimodal context attn_out, _ = self.cross_attention( query=queries, key=multimodal_context, value=multimodal_context ) # Residual and FFN normalization pass x = self.layer_norm(queries + attn_out) out = self.layer_norm(x + self.ffn(x)) return out # Output shape: [batch, num_query, joint_dim]2. Video-LLMs and Spatiotemporal Tokenization Pipelines Moving from static images to dynamic video introduces a massive computational hurdle: the quadratic complexity of self-attention. A 10-second video at 30 frames per second contains 300 discrete images. If we tokenize each frame using a standard Vision Transformer (ViT) patch size of $14 \times 14$, we yield 256 tokens per frame, culminating in over 76,000 tokens for a short clip. To bypass this scalability wall, models like Video-LLaVA and LLaVA-NeXT employ spatial-temporal token pooling and causal spatio-temporal attention masks. Rather than passing all spatial tokens across all time slices, temporal modeling is achieved by applying 3D convolutions (like those in I3D networks) or by decoupling spatial attention (intra-frame) and temporal attention (inter-frame). Another breakthrough architecture is the Temporal Perceiver Resampler. It compresses temporal frames down to a fixed set of sequence slots by utilizing cross-attention over time vectors, allowing models to process hours of video footage within a reasonable context window. Furthermore, positional embeddings must be extended from 1D sequence markers to 3D grid indexes: $$PE_{(pos, 2i)} = \sin\left(\frac{pos}{10000^{2i/d}}\right), \quad PE_{(pos, 2i+1)} = \cos\left(\frac{pos}{10000^{2i/d}}\right)$$ where $pos$ is separately computed for the spatial $X$, $Y$ axes and the temporal $T$ axis, before being concatenated or added together. This spatial-temporal tracking allows the LLM decoder to localize actions precisely in time ("At 02:14, the user dropped the glass") and space ("The object on the far left shelf is moving"). import torch import torch.nn as nnclass SpatioTemporalTokenPooler(nn.Module): """ Compresses spatio-temporal tokens from a video stream. Input shape: [batch, temporal_frames, spatial_tokens, channels] Output shape: [batch, target_frames, compressed_tokens, channels] """ def __init__(self, channels: int, temporal_compress_ratio: int = 2, spatial_compress_ratio: int = 4): super().__init__() self.temp_pool = nn.AvgPool2d(kernel_size=(temporal_compress_ratio, 1), stride=(temporal_compress_ratio, 1)) # Spatial compression via a 2D convolution over the spatial grid self.spatial_downsample = nn.Conv2d( in_channels=channels, out_channels=channels, kernel_size=spatial_compress_ratio, stride=spatial_compress_ratio ) self.layer_norm = nn.LayerNorm(channels) def forward(self, x: torch.Tensor) -> torch.Tensor: # x shape: [B, T, S, C] where S is assumed to be a flattened square spatial grid (e.g., 256 = 16x16) batch_size, T, S, C = x.shape grid_size = int(S ** 0.5) # Reshape to perform temporal pooling: [B, C, T, S] x = x.permute(0, 3, T, S) x = self.temp_pool(x) # [B, C, T_compressed, S] new_T = x.size(2) # Reshape to perform spatial downsampling: [B * T_compressed, C, H, W] x = x.permute(0, 2, 1, 3).reshape(batch_size * new_T, C, grid_size, grid_size) x = self.spatial_downsample(x) # [B * T_compressed, C, H_new, W_new] # Reshape back to sequence form _, C_out, H_new, W_new = x.shape x = x.view(batch_size, new_T, C_out, H_new * W_new) x = x.permute(0, 1, 3, 2) # [B, T_compressed, S_compressed, C] return self.layer_norm(x)3. Embodied AI: Bridging Vision, Language, and Robotic Action One of the most consequential shifts in the AI paradigm is the transition from observer AI to agentic, physical AI. Pioneered by Google DeepMind’s RT-2 (Robotics Transformer 2) and the open-source Open X-Embodiment dataset, Vision-Language-Action (VLA) models treat robotic actions as another sequence of tokens. In a VLA model, the input consists of visual feedback from robot cameras, current joint state feedback, and a natural language instruction (e.g., "Pick up the blue marker and place it in the red bin"). The output is not merely a textual response, but a sequence of action tokens that represent control vectors for a robotic manipulator. Typically, robotic control commands are discretized into bins. A standard action vector consists of changes in spatial position ($\Delta x, \Delta y, \Delta z$), rotation ($\Delta \text{roll}, \Delta \text{pitch}, \Delta \text{yaw}$), and the state of the end-effector/gripper (open/close percentage). If we divide each dimension into 256 discrete bins, we can map these numbers directly to special token IDs in our vocabulary (e.g., tokens <action_val_112>, <action_val_45>).The model is trained auto-regressively: $$P(\text{Action} \mid \text{Vision}, \text{Text}) = \prod_{i=1}^M P(a_i \mid a_{<i}, V, T)$$ This enables the same transformer backbone that writes poetry to output precise kinematic commands, leveraging its deep world-model understanding of physics, object relationships, and reasoning directly to motor outputs. Below is an illustration of an end-to-end inference step mapping raw visual tokens and instructions into robotic control signals: import numpy as npclass ActionTokenDecoder: """ Decodes discrete LLM output tokens back into continuous physical robot trajectories. """ def __init__(self, num_bins: int = 256, action_ranges: dict = None): self.num_bins = num_bins # Default physical limits for manipulator translation (meters) and rotation (radians) self.ranges = action_ranges or { 'x': (-1.0, 1.0), 'y': (-1.0, 1.0), 'z': (-1.0, 1.0), 'roll': (-np.pi, np.pi), 'pitch': (-np.pi, np.pi), 'yaw': (-np.pi, np.pi), 'gripper': (0.0, 1.0) } self.keys = ['x', 'y', 'z', 'roll', 'pitch', 'yaw', 'gripper'] def decode_token_to_value(self, bin_index: int, val_range: tuple) -> float: # Convert index in range [0, 255] to a continuous float min_val, max_val = val_range normalized_val = bin_index / (self.num_bins - 1) return min_val + normalized_val * (max_val - min_val) def parse_action_sequence(self, token_indices: list) -> dict: """ Expects a list of 7 integers corresponding to action tokens. """ assert len(token_indices) == len(self.keys), f"Expected 7 action tokens, got {len(token_indices)}" action_dict = {} for idx, key in enumerate(self.keys): bin_index = token_indices[idx] # Ensure index falls within bin limitations clamped_bin = max(0, min(bin_index, self.num_bins - 1)) action_dict[key] = self.decode_token_to_value(clamped_bin, self.ranges[key]) return action_dict# Example Usage decoder = ActionTokenDecoder() # Dummy model predicted token IDs mapped to discrete bins: [128, 64, 192, 128, 128, 96, 255] predicted_action_bins = [128, 64, 192, 128, 128, 96, 255] kinematic_command = decoder.parse_action_sequence(predicted_action_bins) print("Physical kinematics target values:", kinematic_command)4. Auditory Cognition: End-to-End Speech-to-Speech and Acoustic Embedding For years, speech interface pipelines were clunky cascades:Automatic Speech Recognition (ASR): Audio Waveform $\to$ Text (via Whisper/Conformer) Text Processing: Text $\to$ Text response (via LLM) Text-to-Speech (TTS): Text response $\to$ Output Waveform (via Tacotron/VALL-E)This multi-hop approach suffers from high latency and completely strips voice communication of its emotional, tonal, and non-verbal nuances (sarcasm, dynamic pauses, breathiness, background noise). Modern native speech-to-speech architectures (exemplified by GPT-4o and Meta’s SeamlessM4T) collapse this pipeline into a single, unified, end-to-end model. This is achieved by utilizing neural audio codecs such as EnCodec or Descript Audio Codec (DAC). These neural codecs compress raw continuous audio waveforms down into discrete codes using Vector Quantized Variational Autoencoders (VQ-VAE) or Residual Vector Quantization (RVQ).The continuous audio is converted into several streams of discrete acoustic codes (quantized channels), which are flattened and interleaved into the transformer’s core tokenizer. Audio generation becomes identical to text generation: the model outputs acoustic tokens, which are fed directly to the decoder portion of the neural codec to synthesize high-fidelity, expressive, low-latency audio waveforms. The objective function remains standard cross-entropy calculated over the quantized acoustic sequence tokens: $$\mathcal{L} = -\sum_{t=1}^T \log P(u_t \mid u_{<t}, H_{audio})$$ where $u_t$ is the target acoustic token at sequence step $t$, and $H_{audio}$ represents the encoded auditory condition vector.5. Production Architecture: Orchestrating Ultra-Low Latency Multimodal Pipelines Serving models that dynamically process video, audio, and text at scale requires complete re-engineering of the typical LLM serving stack (vLLM, Hugging Face TGI). When serving a multimodal system, memory management of the KV cache becomes an existential threat to high-throughput operations. While text token embeddings are tiny, a single high-resolution image processed through a ViT can generate 576 or more embeddings. Storing these embeddings across layers in the Key-Value (KV) cache of the transformer rapidly exhausts the H100 or A100 GPU’s High Bandwidth Memory (HBM). To solve this, modern inference engines apply Prefix Caching and FlashAttention-style Multi-Modal Kernels. If a user is conversing about a 10-minute video, the video tokens are loaded, processed, and locked in the KV cache as a static system prompt prefix. Subsequent user text turns only reference this pre-computed, immutable prefix cache, avoiding redundant re-evaluations. Furthermore, inference engines must handle dynamic input routing, sending heavy vision processing workloads to dedicated vision pipeline backends before routing projection matrices to the core tensor-parallel autoregressive engine. # docker-compose.prod.yml # Production deployment configuration for a Multi-Modal inference cluster version: '3.8'services: triton-inference-server: image: nvcr.io/nvidia/tritonserver:26.01-py3 container_name: multimodal_triton_server shm_size: '16gb' deploy: resources: reservations: devices: - driver: nvidia count: all capabilities: [gpu] environment: - TRITON_SERVER_MODEL_REPOSITORY=/models - CUDA_VISIBLE_DEVICES=0,1,2,3 ports: - "8000:8000" # HTTP endpoint - "8001:8001" # gRPC endpoint - "8002:8002" # Metrics endpoint volumes: - ./model_repository:/models command: ["tritonserver", "--model-repository=/models", "--log-verbose=1", "--pinned-memory-pool-byte-size=268435456"] restart: always vllm-multimodal-engine: image: vllm/vllm-openai:latest container_name: vllm_multimodal_api environment: - CUDA_VISIBLE_DEVICES=4,5,6,7 - NCCL_DEBUG=INFO ports: - "8005:8000" volumes: - ~/.cache/huggingface:/root/.cache/huggingface deploy: resources: reservations: devices: - driver: nvidia count: 4 capabilities: [gpu] command: > python3 -m vllm.entrypoints.openai.api_server --model Qwen/Qwen2-VL-7B-Instruct --tensor-parallel-size 4 --trust-remote-code --max-model-len 32768 --gpu-memory-utilization 0.90 --max-num-seqs 256 restart: alwaysMultimodal Paradigms: A Structural Comparison To understand the trade-offs between different multimodal architectures, we can analyze the structures of early-fusion, late-fusion, and multi-encoder alignment models.Architectural Metric Early Fusion (Unified Tokenization) Late Fusion (Ensemble/Decision level) Cross-Attention / Bottleneck Alignment (Flamingo/BLIP-2) Unified Latent Projection (ImageBind)Data Ingestion Raw tokens interleaved at input layer Independent encoders, combined at logits Separate visual encoder, mapped via cross-attention Multi-headed projection to centralized hub spaceInference Latency High (large context sequence overhead) Minimal (parallel independent passes) Medium (attention bottlenecks add overhead) Low to Medium (efficient multi-sensor retrieval)Modal Interaction Direct (full self-attention across modalities) None (isolated until final layer) Medium (queries attend to frozen sensory keys) High (shared geometric similarity metrics)Primary Use Cases GPT-4o, Native Audio/Video LLMs Multi-sensor classification ensembles LLaVA, Video-LLaVA, Visual Question Answering Zero-shot multi-sensory retrieval, cross-modal searchThe table above demonstrates that while Early Fusion architectures provide the deepest level of multi-sensory understanding by allowing every modality token to pay direct attention to every other token, they suffer from high inference latency and rapid context-window exhaustion. Conversely, Cross-Attention Bottleneck models strike a practical production balance, making them highly popular for real-world visual-reasoning applications.Conclusion: The Horizon of Generalist Physical Agents We are moving past the era where artificial intelligence is mere software operating behind glass screens. The unification of speech, vision, dynamic temporal context, and motor outputs is coalescing into a single, cohesive framework: the Generalist Physical Agent. By building unified embeddings that span the entirety of physical experience, we are laying the groundwork for systems that learn from observation, follow complex environmental commands, and dynamically manipulate physical environments with human-like spatial precision. The future of machine intelligence is not linguistic; it is multi-sensory. The models that will define the next decade of human history are those that can see, hear, speak, touch, and move across our physical reality.#AI #MachineLearning #Robotics #ComputerVision #DeepLearning Related InsightsThe Thermodynamic Horizon: Decoding the Convergence of AI-Driven Fusion and Kinetic Energy Grids The Digital Scalpel: Architecting High-Fidelity Haptic Feedback in Robotic Surgery Simulation Unlocking the Quantum Epoch: How QML Will Revolutionize Data Science and AI as We Know It{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Death of Single-Modality AI: How Multi-Sensory Architectures and Embodied Models are Redefining Cognitive Computing?", "acceptedAnswer": { "@type": "Answer", "text": "An in-depth technical analysis of the architectural shift from unimodal LLMs to unified, multi-sensory AI models integrating video, audio, telemetry, and robotic action tokens." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Death of Single-Modality AI: How Multi-Sensory Architectures and Embodied Models are Redefining Cognitive Computing?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Eleanor Sterling." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
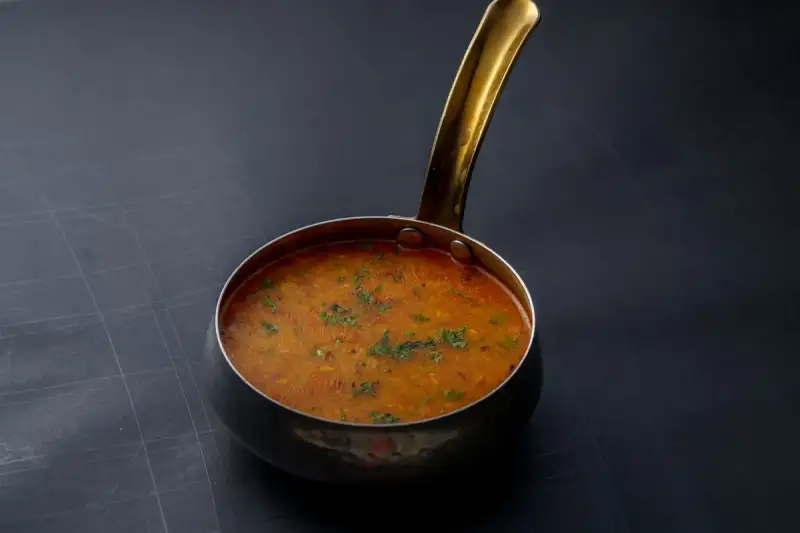
Introduction to French Lentil Soup French Lentil Soup, also known as Potage Saint-Germain, is a classic French dish that has been a staple of French cuisine for centuries. This hearty soup is made with lentils, vegetables, and aromatic spices, and is typically served as a main course or used as a starter. According to recent studies, lentils are a rich source of protein, fiber, and nutrients, making them an excellent addition to a healthy diet. Research on high protein shows that lentils contain about 18g of protein per 1 cup cooked, which is essential for building and repairing muscles, organs, and tissues in the body.The combination of lentils and kale in this recipe provides a boost of protein, fiber, and vitamins, making it an excellent option for those looking for a nutritious and delicious meal. Kale, in particular, is a superfood that is rich in vitamins A, C, and K, as well as minerals like calcium and iron. According to a study on microgreens, kale is one of the most nutrient-dense leafy greens, making it an excellent addition to this recipe. The Health Benefits of Lentils Lentils are a type of legume that are naturally low in fat and high in protein and fiber. They are also rich in nutrients like iron, potassium, and folate, making them an excellent addition to a healthy diet. According to a study on pea improvement, lentils contain a type of fiber called soluble fiber, which can help lower cholesterol levels and regulate blood sugar levels. Additionally, lentils are rich in antioxidants, which can help protect against cell damage and reduce the risk of chronic diseases like heart disease and cancer.The health benefits of lentils make them an excellent ingredient for this recipe. The combination of lentils, kale, and Dijon mustard provides a boost of protein, fiber, and vitamins, making it an excellent option for those looking for a nutritious and delicious meal. Dijon mustard, in particular, is a good source of antioxidants and has been shown to have anti-inflammatory properties, making it an excellent addition to this recipe. The Role of Kale in French Lentil Soup Kale is a superfood that is rich in vitamins, minerals, and antioxidants. It is also low in calories and high in fiber, making it an excellent addition to a healthy diet. According to a study on microgreens, kale is one of the most nutrient-dense leafy greens, making it an excellent addition to this recipe. The combination of kale and lentils in this recipe provides a boost of protein, fiber, and vitamins, making it an excellent option for those looking for a nutritious and delicious meal.The role of kale in this recipe is not only to add nutrients and flavor but also to provide a boost of antioxidants and anti-inflammatory compounds. According to a study on sprouts and microgreens, kale is a rich source of polyphenols and glucosinolates, which have been shown to have anti-inflammatory and antioxidant properties. The combination of kale and lentils in this recipe makes it an excellent option for those looking for a nutritious and delicious meal. The Importance of Dijon Mustard Dijon mustard is a type of mustard that is made from brown mustard seeds, white wine, and spices. It is a classic ingredient in French cuisine and is often used to add flavor and aroma to dishes like French Lentil Soup. According to a study on the health benefits of mustard, Dijon mustard is a good source of antioxidants and has been shown to have anti-inflammatory properties, making it an excellent addition to this recipe.The importance of Dijon mustard in this recipe is not only to add flavor and aroma but also to provide a boost of antioxidants and anti-inflammatory compounds. According to a study on the health benefits of mustard, Dijon mustard contains a type of compound called allyl isothiocyanate, which has been shown to have anti-inflammatory and antioxidant properties. The combination of Dijon mustard and lentils in this recipe makes it an excellent option for those looking for a nutritious and delicious meal. Conclusion French Lentil Soup with Kale and Dijon is a delicious and nutritious recipe that is perfect for those looking for a hearty and healthy meal. The combination of lentils, kale, and Dijon mustard provides a boost of protein, fiber, and vitamins, making it an excellent option for those looking for a nutritious and delicious meal. According to recent studies, lentils, kale, and Dijon mustard are all rich in nutrients and antioxidants, making them an excellent addition to a healthy diet. Whether you're looking for a quick and easy meal or a delicious and nutritious recipe, French Lentil Soup with Kale and Dijon is an excellent option. #HealthyLiving #Gastronomy #FrenchCuisine #HighProteinRecipes #NutritiousMeals Related InsightsThe Ultimate Antioxidant-Rich Berry Oat Smoothie Bowl with Chia Seeds [The Sun-Drenched Symphony of Provence: Unveiling the Soul of Ratatouille] The Ambrosial Alchemist's Secret: Unearthing Oxymel's Ancient Culinary Resurgence{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of French Lentil Soup with Kale and Dijon: A High Protein Delight?", "acceptedAnswer": { "@type": "Answer", "text": "Indulge in the rich flavors of French cuisine with our high protein French Lentil Soup, packed with nutrients and delicious ingredients. Learn about the health benefits of lentils, kale, and Dijon mustard, and discover how to prepare this hearty soup." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on French Lentil Soup with Kale and Dijon: A High Protein Delight?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Pierre Dubois." } }, { "@type": "Question", "name": "Where can I find more related content about Food?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Food category page." } } ] }
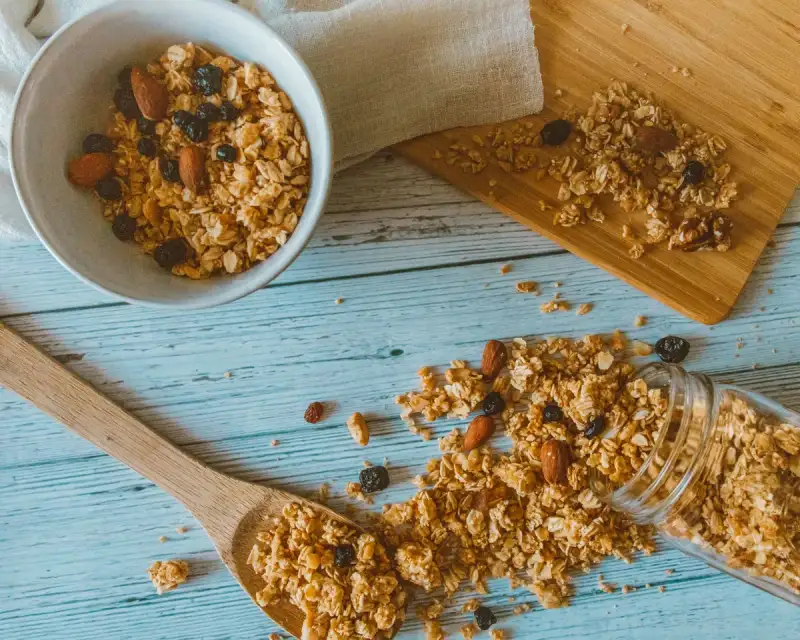
-
 Hans Müller
- 13 Jul, 2026 05:22
Black Forest Oat Porridge with Berries and Nuts (Vegan): A Nutritious and Delicious Antioxidant-Rich Breakfast
Introduction As we navigate the complexities of modern life, it's essential to prioritize our health and wellbeing by incorporating nutrient-dense foods into our diets. According to recent studies, a diet rich in antioxidant-rich foods can help boost our immune systems and protect against chronic diseases (FutureBites: Exploring the Cutting-Edge Food Technologies). One such food that has gained popularity in recent years is oat porridge, which is not only delicious but also packed with essential minerals and trace elements (Dietary Intakes and Exposures to Minerals and Trace Elements from Cereal-Based Mixtures: Potential Health Benefits and Risks for Adults). In this article, we'll delve into the world of Black Forest Oat Porridge with Berries and Nuts, a vegan breakfast recipe that combines the creaminess of oats with the sweetness of berries and the crunch of nuts.Research on antioxidant-rich foods shows that they can help control symptoms and reduce the severity of chronic diseases, promoting general wellbeing (FutureBites: Exploring the Cutting-Edge Food Technologies). The 6th International Electronic Conference on Foods also highlights the importance of innovative and sustainable food solutions in addressing global challenges (Abstracts of the 6th International Electronic Conference on Foods). As we explore the benefits of Black Forest Oat Porridge with Berries and Nuts, we'll also discuss the scientific data supporting the use of cereal-based mixtures as a potential source of beneficial micronutrients for the human diet. The Benefits of Oat Porridge Oat porridge is a cereal-based mixture that has been a staple food in many cultures for centuries. According to the study on Dietary Intakes and Exposures to Minerals and Trace Elements from Cereal-Based Mixtures, oats are a rich source of essential minerals and trace elements, including manganese, copper, zinc, iron, and phosphorus (Dietary Intakes and Exposures to Minerals and Trace Elements from Cereal-Based Mixtures: Potential Health Benefits and Risks for Adults). These nutrients play a crucial role in maintaining healthy bones, immune function, and energy metabolism. Additionally, oats contain a type of fiber called beta-glucan, which can help lower cholesterol levels and regulate blood sugar levels.The study also highlights the potential health benefits of cereal-based mixtures, including their ability to contribute significantly to the reference values for manganese, copper, zinc, iron, and phosphorus for adults (Dietary Intakes and Exposures to Minerals and Trace Elements from Cereal-Based Mixtures: Potential Health Benefits and Risks for Adults). Furthermore, the mixtures were found to contribute insignificantly to the toxic reference values of aluminum, tin, mercury, cadmium, nickel, and silver, making them a safe and healthy choice for consumption. The Power of Berries and Nuts Berries and nuts are two of the most antioxidant-rich foods that can be added to oat porridge. According to research, berries are packed with anthocyanins, powerful antioxidants that can help protect against chronic diseases such as heart disease, cancer, and cognitive decline (FutureBites: Exploring the Cutting-Edge Food Technologies). Nuts, on the other hand, are a rich source of healthy fats, protein, and fiber, making them an excellent addition to a balanced diet.The combination of berries and nuts in Black Forest Oat Porridge with Berries and Nuts creates a delicious and nutritious breakfast that is not only satisfying but also provides a boost of energy and antioxidants to start the day. With the addition of plant-based milk and a drizzle of honey or maple syrup, this recipe is a perfect way to incorporate more plant-based foods into your diet and support a healthy lifestyle. Recipe: Black Forest Oat Porridge with Berries and Nuts (Vegan) As we explore the world of Black Forest Oat Porridge with Berries and Nuts, let's take a look at the simple and delicious recipe that combines the creaminess of oats with the sweetness of berries and the crunch of nuts.To make this recipe, you'll need the following ingredients:1 cup rolled oats 1 cup plant-based milk 1/4 cup mixed berries (such as blueberries, raspberries, and blackberries) 1/4 cup chopped nuts (such as almonds and walnuts) 1 tablespoon honey or maple syrup (optional) 1/4 teaspoon vanilla extract Pinch of saltInstructions:In a medium saucepan, bring the plant-based milk to a simmer over medium heat. Add the oats, vanilla extract, and salt. Cook, stirring occasionally, until the oats have absorbed most of the milk and the mixture has a creamy consistency, about 20-25 minutes. Stir in the honey or maple syrup, if using. In a separate bowl, mix together the mixed berries and chopped nuts. To serve, divide the oat porridge into bowls and top with the berry and nut mixture.Conclusion In conclusion, Black Forest Oat Porridge with Berries and Nuts is a delicious and nutritious breakfast recipe that combines the creaminess of oats with the sweetness of berries and the crunch of nuts. With its rich antioxidant content and essential minerals and trace elements, this recipe is a perfect way to start the day and support a healthy lifestyle. Whether you're looking for a quick and easy breakfast or a healthy snack, this recipe is sure to become a favorite. So why not give it a try and experience the benefits of a nutrient-dense diet for yourself? #HealthyLiving #Gastronomy #VeganRecipes #OatPorridge #BreakfastIdeas Related InsightsThe Fifth Element: How a Bowl of Seaweed Broth Rewrote the Language of Flavor The Architecture of Flavor: Deconstructing the Empire of Haute Cuisine The Ambrosial Alchemist's Secret: Unearthing Oxymel's Ancient Culinary Resurgence{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Black Forest Oat Porridge with Berries and Nuts (Vegan): A Nutritious and Delicious Antioxidant-Rich Breakfast?", "acceptedAnswer": { "@type": "Answer", "text": "Start your day with a nutritious and delicious bowl of Black Forest Oat Porridge with Berries and Nuts, packed with antioxidant-rich ingredients to boost your immune system and keep you energized throughout the morning." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Black Forest Oat Porridge with Berries and Nuts (Vegan): A Nutritious and Delicious Antioxidant-Rich Breakfast?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Hans Müller." } }, { "@type": "Question", "name": "Where can I find more related content about Food?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Food category page." } } ] }
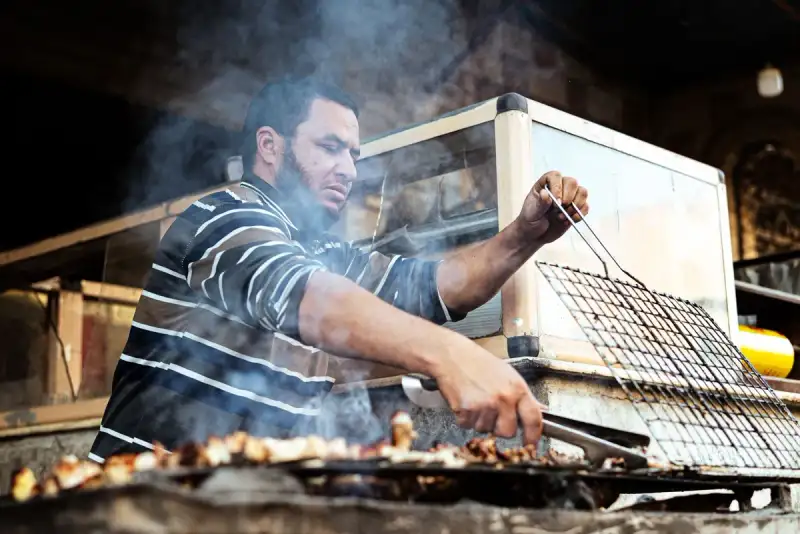
In the bustling streets of Cairo, where the aroma of exotic spices and freshly baked bread fills the air, lies a culinary treasure that has been a staple of Egyptian cuisine for centuries: Hawawshi. This delicious spiced meat bread is a testament to the country's rich cultural heritage, where flavors and traditions blend together in perfect harmony. As we delve into the world of Hawawshi, we will explore its history, cultural significance, and of course, the authentic recipe that has been passed down through generations. Introduction to Hawawshi Hawawshi is a type of Egyptian bread that is filled with a mixture of spiced meat, onions, and spices. The bread is typically made with a yeast-based dough, which is allowed to rise before being filled with the flavorful meat mixture. The filling is usually made with a combination of ground beef or lamb, onions, garlic, and a blend of spices that include cumin, coriander, and cinnamon. The bread is then baked in a wood-fired oven, giving it a crispy crust and a soft, fluffy interior.History and Cultural Significance Hawawshi has a long and storied history that dates back to the Ottoman Empire. The dish is believed to have originated in the 16th century, when Egyptian bakers began filling bread with spiced meat as a way to provide a convenient and filling meal for workers and travelers. Over time, Hawawshi became a staple of Egyptian cuisine, with different regions developing their own unique variations and fillings. Today, Hawawshi is enjoyed throughout Egypt, from street food vendors to high-end restaurants. Authentic Recipe To make authentic Hawawshi, you will need the following ingredients:2 cups of all-purpose flour 1 teaspoon of salt 1 teaspoon of sugar 1 packet of active dry yeast 1 cup of warm water 1 tablespoon of vegetable oil 1 onion, finely chopped 2 cloves of garlic, minced 1 pound of ground beef or lamb 1 teaspoon of cumin 1 teaspoon of coriander 1/2 teaspoon of cinnamon 1/2 teaspoon of black pepperTo prepare the dough, combine the flour, salt, sugar, and yeast in a large mixing bowl. Gradually add the warm water, stirring with a wooden spoon until a dough forms. Knead the dough for 10-15 minutes until it becomes smooth and elastic. Place the dough in a greased bowl, cover it with a damp cloth, and let it rise in a warm place for 1-2 hours. Preparation of the Filling To prepare the filling, heat the oil in a pan over medium heat. Add the chopped onion and cook until it is softened and translucent. Add the minced garlic and cook for an additional minute. Add the ground beef or lamb, breaking it up with a spoon as it cooks. Add the cumin, coriander, cinnamon, and black pepper, stirring well to combine. Cook the filling for 10-15 minutes, stirring occasionally, until it is browned and fragrant.Assembly and Baking To assemble the Hawawshi, punch down the risen dough and divide it into 4-6 equal pieces. Roll out each piece into a thin circle, about 1/4 inch thick. Place a tablespoon or two of the spiced meat filling in the center of each circle. Fold the dough over the filling, forming a triangle or a square shape, and press the edges together to seal. Place the Hawawshi on a baking sheet lined with parchment paper, leaving about 1 inch of space between each bread. Brush the tops with a little water and bake in a preheated oven at 400°F (200°C) for 20-25 minutes, or until golden brown. Conclusion Hawawshi is a true culinary treasure of Egyptian cuisine, with its rich history, cultural significance, and delicious flavor. Whether you are a foodie, a historian, or simply someone who loves to try new things, Hawawshi is a must-try dish that is sure to leave you wanting more. With its crispy crust, soft interior, and flavorful spiced meat filling, Hawawshi is a dish that will transport you to the bustling streets of Cairo, where the aroma of freshly baked bread and exotic spices fills the air.#Hawawshi #EgyptianFood #StreetFood #CairoCuisine #SpicedMeatBread #TraditionalFood #Foodie #MiddleEasternCuisine Related InsightsKale and Grilled Chicken Caesar Salad with Greek Yogurt Dressing: A High Protein Delight L'Épopée Gourmande des Rues : Quand le Monde se Déguste à Ciel Ouvert Jollof Rice: The Ultimate West African Party Dish{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Hawawshi: The Spiced Meat Bread of Cairo?", "acceptedAnswer": { "@type": "Answer", "text": "Discover the deep cultural roots, authentic flavors, and history of Hawawshi: The Spiced Meat Bread of Cairo." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Hawawshi: The Spiced Meat Bread of Cairo?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Tariq Al-Fayed." } }, { "@type": "Question", "name": "Where can I find more related content about Food?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Food category page." } } ] }
-
 Aisha Sharma
- 12 Jul, 2026 19:38
The Arctic's Whispering Skies: Your Ultimate Guide to Unlocking Scandinavia's Northern Lights Mystique
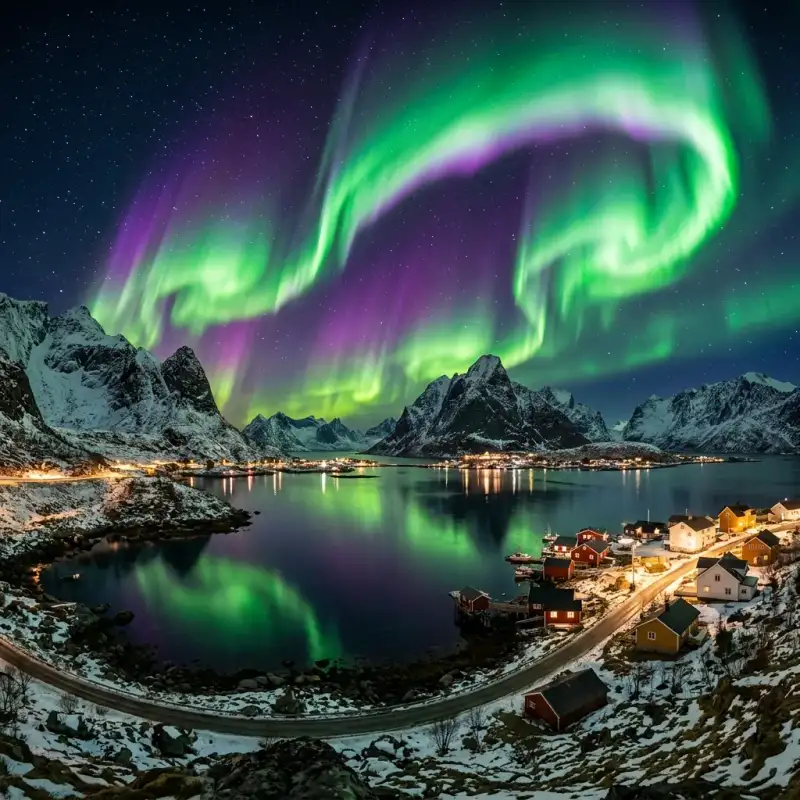
Greetings, fellow adventurers and dreamers! It's Aisha Sharma, and today, we're diving headfirst into one of the most breathtaking spectacles our planet has to offer: the Aurora Borealis. Imagine standing under a canvas of infinite stars, as ethereal ribbons of green, pink, and purple dance across the night sky, whispering ancient tales. This isn't a scene from a fantasy novel; it's a very real, very accessible phenomenon that awaits you in the pristine wilderness of Scandinavia. For decades, I’ve traversed the globe, seeking out wonders that ignite the soul, and few experiences compare to the profound awe inspired by the Northern Lights. Scandinavia, comprising Norway, Sweden, and Finland, is not just a region; it's a pilgrimage site for aurora chasers. Its unique geographical position within the "auroral oval" – a ring around the magnetic North Pole – combined with vast, unpolluted dark skies, makes it a prime viewing destination. From the dramatic fjords of Norway to the serene forests of Finnish Lapland and the icy wilderness of Swedish Lapland, each country offers a distinct backdrop to this celestial ballet. But simply showing up isn't enough. Chasing the aurora requires strategic planning, a keen understanding of the science, and a readiness to embrace the Arctic environment. This comprehensive guide, born from countless nights under the Arctic sky, will equip you with everything you need to transform your dream of seeing the Northern Lights into an unforgettable reality, backed by factual insights and actionable advice. Prepare to unlock the secrets to a truly magical experience. Understanding the Aurora Borealis: The Science Behind the Spectacle To truly appreciate the Northern Lights, it helps to understand the incredible cosmic mechanics that orchestrate their appearance. The aurora is, at its heart, a magnificent solar-terrestrial interaction. It begins over 150 million kilometers away, on the surface of our sun. Solar flares and coronal mass ejections (CMEs) release a torrent of charged particles – primarily electrons and protons – into space. This phenomenon, known as solar wind, travels at speeds ranging from 400 to 800 kilometers per second, taking between two and five days to reach Earth. Upon arrival, these energized particles encounter Earth's magnetic field. Most are deflected, but some manage to penetrate the magnetic shield near the poles, where the field lines converge. As these solar particles collide with atoms and molecules in Earth's upper atmosphere, typically at altitudes between 80 and 500 kilometers, they excite these atmospheric gases. When these excited atoms and molecules return to their original, lower energy state, they emit photons of light – creating the vibrant glow we know as the aurora. The specific color depends on the type of gas molecule and the altitude at which the collision occurs. Oxygen atoms, for instance, are responsible for the most common green-yellow hues (at lower altitudes, ~100-200 km) and the rarer red auroras (at higher altitudes, ~200-400 km). Nitrogen molecules produce blue or purple light. The intensity of the aurora is often quantified by the Kp-index, a global geomagnetic activity index that ranges from 0 to 9. A Kp-index of 0-1 indicates very weak activity, while a Kp of 5 or higher signifies a geomagnetic storm, leading to highly visible and widespread auroras. While a Kp of 2-3 can yield beautiful displays, higher values drastically increase your chances and the aurora's vibrancy. Forecasting is crucial, with organizations like NOAA's Space Weather Prediction Center providing short-term (30-minute) and long-term (3-day) forecasts. Understanding these scientific underpinnings allows for more strategic planning, ensuring you're in the right place at the right time to witness this celestial masterpiece. The magnetic poles, specifically within the auroral oval, are where these field lines are weakest, acting like a funnel for the charged particles, which is precisely why Scandinavia, particularly its northern regions, offers such consistent and spectacular shows.Prime Locations in Scandinavia for Aurora Chasing Scandinavia offers an unparalleled array of destinations for aurora hunters, each with its unique charm and viewing advantages. The key to successful aurora chasing lies in venturing above the Arctic Circle, minimizing light pollution, and choosing locations known for their clear skies and auroral activity. Norway: Often considered the jewel of aurora tourism, Norway's long coastline stretches deep into the auroral oval, offering dramatic backdrops of fjords and mountains.Tromsø: Dubbed the "Gateway to the Arctic," Tromsø (69.6°N) is arguably Norway's most popular aurora destination. It's a bustling city with excellent infrastructure, including an international airport, numerous tour operators, and a variety of accommodation options. While the city itself has some light pollution, most tours take you just outside to darker areas. Data from local weather stations indicates that Tromsø experiences an average of 200 aurora nights per year between September and March. Lofoten Islands: Further south (around 68°N), the Lofoten Islands offer arguably the most scenic aurora backdrop, with rugged mountains rising directly from the sea. Less crowded than Tromsø, but requiring more self-sufficiency. Viewings are frequent, though weather can be more variable due to coastal proximity. North Cape (Nordkapp): At 71°N, this is continental Europe's northernmost point. It's remote, wild, and incredibly dark, offering unimpeded views of the northern sky. Best accessed from Honningsvåg.Sweden: Swedish Lapland is characterized by vast, unspoiled wilderness and consistent cold, dry weather, often leading to clearer skies than coastal Norway.Abisko National Park: Widely hailed as one of the very best places on Earth to see the Northern Lights. Abisko (68.3°N) benefits from a unique microclimate created by the surrounding mountains that keep the skies clear. The "Blue Hole of Abisko" is a local phenomenon where the sky over Lake Torneträsk often remains clear even when surrounding areas are cloudy. The Aurora Sky Station, accessible by chairlift, offers an elevated, light-pollution-free viewing platform. Statistical data from the Swedish Institute of Space Physics (IRF) confirms a significantly higher number of clear nights in Abisko compared to other Arctic locations. Kiruna: Sweden's northernmost city, Kiruna (67.8°N), serves as a major hub for Swedish Lapland and is close to the iconic ICEHOTEL in Jukkasjärvi. It offers a good balance of accessibility and proximity to dark skies.Finland: Finnish Lapland provides a magical, snowy wonderland experience, synonymous with Santa Claus and winter activities, alongside incredible aurora displays.Rovaniemi: While known as the official hometown of Santa Claus (66.5°N, just on the Arctic Circle), Rovaniemi is also a solid base for aurora hunting, especially in its surrounding dark areas. It offers excellent air connections and a wide range of activities. Levi, Saariselkä, and Inari: These fell villages (all around 68-69°N) are further north than Rovaniemi and offer exceptionally dark skies. Saariselkä is famous for its "Kaamos" or polar night period, ensuring prolonged darkness. Inari, located by Lake Inari, Finland's third-largest lake, provides vast, open views over the frozen expanse, minimizing light obstruction. These areas are particularly popular for glass igloo accommodations, offering a unique viewing experience directly from your bed. Choosing your prime location depends on your travel style, budget, and desired activities beyond aurora chasing.Optimal Timing & Weather Considerations Successfully chasing the Northern Lights is as much about timing and understanding weather patterns as it is about choosing the right location. Patience and flexibility are paramount. Best Season: The aurora season generally spans from late August/early September to early April. Within this window, the prime months are typically September through October and February through March.September-October: The autumn months offer slightly milder temperatures, making outdoor waiting more comfortable. The landscapes are often vibrant with autumn colors, and frozen lakes haven't yet locked down, allowing for different transportation options like boat tours. However, rain or snow can be more frequent, potentially obscuring views. November-January: These are the darkest months, including the polar night period (Kaamos) above the Arctic Circle, where the sun doesn't rise for weeks. This means maximum darkness, increasing viewing opportunities in terms of hours. However, temperatures plummet, often reaching -20°C to -30°C or even colder, and heavy snowfall can lead to increased cloud cover. February-March: As spring approaches, daylight hours gradually lengthen, but there's still ample darkness for aurora viewing. Temperatures remain cold but often less extreme than deep winter. This period frequently offers a good balance of cold, clear nights and manageable temperatures, making it a very popular time for visitors.Daily Timing: The best time to see the aurora is typically between 9:00 PM and 2:00 AM local time, though it can appear anytime from sunset to sunrise. Most tour operators schedule their chases during these hours. It's crucial to stay vigilant throughout the night, as displays can intensify or fade rapidly. Moon Phases: While the aurora is bright enough to be seen even under a full moon, a new moon phase or a crescent moon provides the darkest skies, allowing fainter auroras to be more visible and stars to shine more brightly, enhancing the overall experience. Check moon phase calendars when planning your trip. Cloud Cover: This is the single biggest factor beyond solar activity that can make or break your aurora hunt. Even with a strong Kp-index, if the sky is overcast, you won't see anything.Local Weather Forecasts: Constantly monitor local weather forecasts for cloud cover. Websites like Yr.no (for Norway and globally), AccuWeather, or local meteorological services are invaluable. Aurora Apps: Use dedicated aurora forecasting apps (e.g., My Aurora Forecast, Aurora Alerts) that combine Kp-index data with cloud cover maps, often showing satellite imagery of clear patches. Mobility: Being mobile is a significant advantage. Aurora chase tours specialize in driving to areas known for clear skies, sometimes crossing borders into different weather zones. If you rent a car, be prepared to do the same, but always prioritize safety on icy roads.Remember, the aurora is a natural phenomenon, and guarantees are impossible. However, by selecting the optimal time window and remaining flexible with your viewing locations based on real-time weather, you significantly increase your chances of witnessing this celestial marvel.👉 Continue Reading: The Arctic's Whispering Skies: Your Ultimate Guide to Unlocking Scandinavia's Northern Lights Mystique (Part 2)#AuroraBorealis #NorthernLights #ScandinaviaTravel #ArcticAdventures #TravelGuide #SustainableTourism Related InsightsExploring Ani, City of 1001 Churches The Twenty Million Dollar View: A History of Humanity's Most Exclusive Destination Azure Horizons and Fragile Ecosystems: The Maldives Reality Check{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Arctic's Whispering Skies: Your Ultimate Guide to Unlocking Scandinavia's Northern Lights Mystique?", "acceptedAnswer": { "@type": "Answer", "text": "Embark on an epic journey to witness the Aurora Borealis in Scandinavia with this expert guide covering science, locations, timing, budgeting, and photography." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Arctic's Whispering Skies: Your Ultimate Guide to Unlocking Scandinavia's Northern Lights Mystique?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Aisha Sharma." } }, { "@type": "Question", "name": "Where can I find more related content about Travel?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Travel category page." } } ] }
- Aisha Sharma
- 12 Jul, 2026 19:38
The Arctic's Whispering Skies: Your Ultimate Guide to Unlocking Scandinavia's Northern Lights Mystique (Part 2)
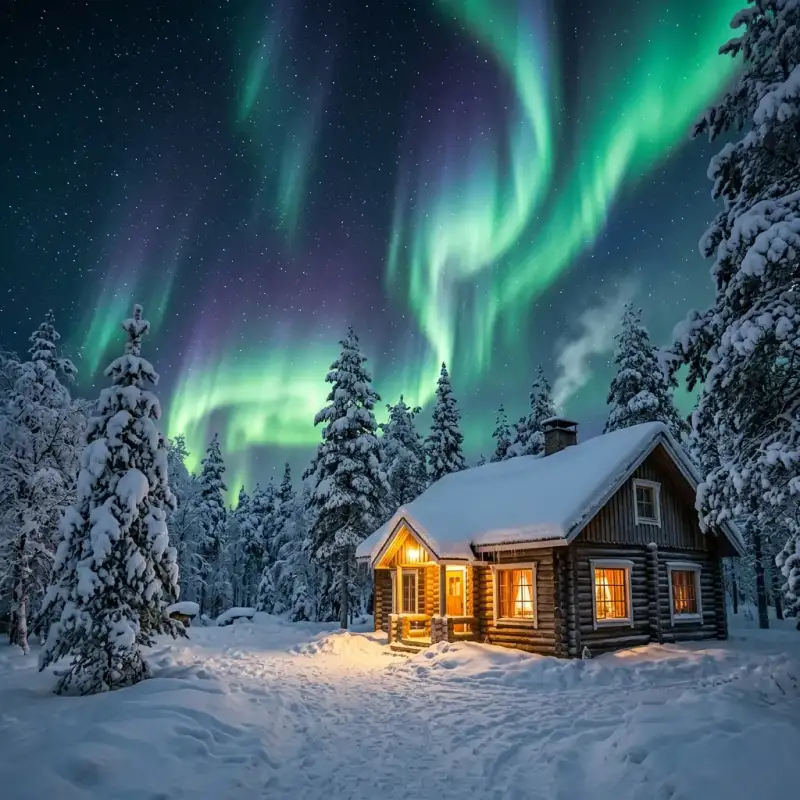
This is Part 2 of the series. Read Part 1 here.Planning Your Expedition: Logistics and Budgeting Embarking on an Arctic adventure to chase the Northern Lights requires meticulous planning, especially concerning logistics and managing the higher cost of living in Scandinavia. A well-thought-out itinerary and budget can make all the difference. Visa Requirements: For most international travelers, Scandinavia falls under the Schengen Area. Citizens of many countries, including the US, Canada, UK, Australia, and New Zealand, can enter visa-free for up to 90 days within any 180-day period for tourism. However, starting in mid-2025 (latest information as of 2024), travelers from visa-exempt countries will need to apply for an ETIAS (European Travel Information and Authorization System) authorization prior to their trip. This is not a visa but a pre-travel screening, costing around €7. Always check the latest visa and entry requirements from official government sources well in advance of your departure. Flights & Transportation:International Flights: Major international airports like Oslo Gardermoen (OSL), Stockholm Arlanda (ARN), and Helsinki-Vantaa (HEL) are primary gateways. From these hubs, you'll typically take domestic flights to Arctic destinations (e.g., Tromsø (TOS), Kiruna (KRN), Rovaniemi (RVN)). Expect round-trip economy fares from North America to Scandinavia to range from €500-€900 ($550-$1000 USD), depending on booking time and season. Inter-Scandinavia flights can range from €100-€300. Local Transportation: In most aurora destinations, public transport can be limited. Renting a car offers flexibility for self-guided aurora chases, but be prepared for challenging winter driving conditions (studded tires are mandatory in winter). Many choose organized tours, which include transport. Trains are an excellent option for scenic travel between certain cities, for example, the Arctic Circle Express from Narvik (Norway) to Kiruna (Sweden).Accommodation: Options range from budget hostels to luxurious ice hotels and glass igloos.Standard Hotels/Guesthouses: Expect to pay €80-€150 per night for a basic room, €150-€300 for mid-range. Ice Hotels (e.g., ICEHOTEL in Jukkasjärvi, Sweden): A unique experience, but pricey, starting from €250-€500 per night for an 'ice room', warmer rooms are also available. Glass Igloos/Cabins (e.g., Kakslauttanen Arctic Resort in Finland): Iconic for aurora viewing from bed, these can cost upwards of €400-€800+ per night. Airbnb/Self-Catering: Often a more budget-friendly option, especially for groups, allowing for cooking and cost savings on meals.Tours & Activities:Aurora Chase Tours: Highly recommended for first-timers, these typically cost €100-€200 per person per night and include transportation, expert guides, thermal suits, and sometimes hot drinks/snacks. Guides monitor conditions and drive to clear spots. Dog Sledding/Snowmobiling: Popular daytime activities, ranging from €150-€300 per person. Reindeer Sledding, Sami Cultural Experiences: Around €80-€150.Food & Drink: Scandinavia is renowned for its high cost of living.Groceries: Budget €20-€40 per day if cooking for yourself. Restaurant Meals: A casual lunch can be €15-€25, while dinner in a mid-range restaurant can easily be €30-€60+ per person. Alcohol is particularly expensive.Clothing & Gear: This is non-negotiable. Arctic temperatures demand proper attire.Base Layers: Merino wool or synthetic thermal underwear (top and bottom). Mid-Layers: Fleece or down jacket/vest. Outer Layers: Waterproof and windproof heavy winter jacket and trousers. Many aurora tours provide thermal overalls. Extremities: Warm hat covering ears, thick wool/fleece neck gaiter, waterproof insulated gloves/mittens (two pairs: thin inner, thick outer), insulated, waterproof winter boots (Sorel, Baffin recommended). Camera Gear: Tripod, remote shutter release, extra batteries (cold drains them quickly), wide-angle lens.Sample 7-Day Budget for Aurora Trip (Mid-Range, per person, excluding international flights):Category Estimated Cost (EUR) NotesDomestic Flights 250 - 450 Round trip from major hub (e.g., Oslo to Tromsø)Accommodation (6 nights) 900 - 1500 Mid-range hotels/guesthouses (€150-€250/night). Could be lower with hostels or higher for luxury igloos.Aurora Chase Tours 300 - 600 2-3 guided tours (€150-€200 each) to maximize chances.Daytime Activities 300 - 500 E.g., 1 dog sledding tour, museum entry, local transport.Food & Drink 350 - 500 Mix of self-catering (breakfast, some lunches) and eating out for dinner (€50-€70/day average).Warm Clothing/Gear 0 - 200 If renting or buying specific items. Tours often provide overalls.Miscellaneous 100 - 200 Souvenirs, unforeseen expenses, etc.Total Estimated Cost 2200 - 3950 Excludes international flights. Budget travelers might aim for €1500-€2000.This table illustrates that a realistic mid-range budget for a 7-day aurora trip in Scandinavia, excluding your main international flight, can range from €2,200 to €3,950 per person. Being prepared for these costs is key to an enjoyable, stress-free adventure. Mastering Aurora Photography: Capturing the Elusive Dance Witnessing the Northern Lights is an experience that transcends description, but capturing its ephemeral beauty through photography allows you to relive those moments and share them with others. Aurora photography requires specific techniques and gear due to the low-light conditions and dynamic nature of the phenomenon. Essential Gear:DSLR or Mirrorless Camera: A camera that allows full manual control over aperture, shutter speed, and ISO is essential. Modern cameras with good low-light performance (higher ISO capabilities with less noise) are advantageous. Wide-Angle Lens: A lens with a focal length between 14mm and 24mm (on a full-frame sensor) or equivalent on APS-C is ideal. This allows you to capture more of the sky and landscape. A fast aperture (f/2.8 or wider, e.g., f/1.4 or f/1.8) is critical for gathering maximum light. Sturdy Tripod: Non-negotiable. Long exposure times mean even the slightest camera movement will result in blurry images. A robust tripod will keep your camera steady in potentially windy conditions. Remote Shutter Release (or Intervalometer): This prevents camera shake when pressing the shutter button. Alternatively, use your camera's self-timer (2-second delay). Extra Batteries: Cold temperatures drain batteries rapidly. Carry at least 2-3 spare batteries, keeping them warm in an inside pocket until needed. Headlamp with Red Light Mode: A headlamp is crucial for seeing in the dark, but use a red light setting to preserve your night vision and avoid disturbing others or interfering with their photos.Camera Settings (Starting Points):Manual Mode (M): You need full control. Aperture (f-stop): Set your lens to its widest aperture (smallest f-number), e.g., f/2.8, f/4. This lets in the most light. ISO: Start with ISO 800-1600. Adjust based on the aurora's brightness. For fainter auroras, you might go up to ISO 3200 or even 6400, but be mindful of increased digital noise. Shutter Speed: This depends on the aurora's movement. Fast, dancing aurora: 5-15 seconds. Longer exposures will blur the distinct curtain-like shapes. Slow, faint aurora: 15-30 seconds. This allows more light to be captured. Experiment to find the sweet spot.Focus: Set your lens to manual focus (MF) and focus to infinity. A good trick is to focus on a distant star or the moon (if visible) using live view and then zoom in to ensure sharpness before locking focus. Alternatively, some lenses have an infinity mark, but verify its accuracy. White Balance: Auto White Balance (AWB) often works well, but you can experiment with Kelvin temperatures (e.g., 3500K-4500K) for a cooler, more natural look. Image Format: Shoot in RAW. This captures the most data, giving you maximum flexibility for post-processing adjustments (exposure, white balance, noise reduction) without degrading image quality.Practical Tips:Composition: Include a foreground element (trees, mountains, cabins, or even yourself) to add scale and interest to your photos. Stay Warm: Your comfort directly impacts your concentration. Wear multiple layers, insulated boots, and thick gloves. Consider hand warmers for yourself and your camera batteries. Protect Your Gear: Condensation can be an issue when moving from cold outdoors to warm indoors. Place your camera in a sealed plastic bag before coming inside and let it warm up slowly to room temperature to prevent condensation from forming on or inside the lens and camera body. Practice: Familiarize yourself with your camera settings in the dark before the aurora appears. Practice focusing and adjusting settings in low light.Mastering aurora photography is a rewarding challenge. With the right gear, settings, and patience, you'll be able to capture the magic of the Northern Lights and cherish those incredible memories forever.Responsible Aurora Chasing: Sustainable Tourism in the Arctic As aurora tourism continues to grow, it's increasingly important to practice responsible travel and minimize our impact on the fragile Arctic environment and local communities. Sustainable aurora chasing ensures that this wonder remains accessible for future generations and respects the unique culture of the region. Environmental Impact:Minimize Light Pollution: Light pollution is the enemy of aurora viewing. When out chasing, avoid using bright flashlights or phone screens unnecessarily. If a headlamp is needed, use a red light setting. Support local businesses that also prioritize dark sky preservation. Leave No Trace: The Arctic wilderness is pristine. Carry out everything you carry in, including all trash, food wrappers, and cigarette butts. Stick to designated paths and avoid disturbing flora and fauna. Even seemingly minor disturbances can have long-lasting effects in cold, slow-growing ecosystems. Energy Consumption: Be mindful of your energy usage in accommodations. Heating large spaces in sub-zero temperatures consumes significant energy. Turn off lights and lower thermostats when leaving your room. Choose eco-certified accommodations where possible. Transportation Choices: While flying is often necessary to reach the Arctic, consider combining train travel for scenic routes or choosing operators that use more fuel-efficient vehicles for tours. Carpool when possible.Respecting Local Communities and Culture:Sámi Culture: Scandinavia's Arctic regions are the traditional homelands of the Sámi people, the indigenous population. Their culture is deeply intertwined with the land and reindeer herding. When participating in Sámi-themed activities (e.g., reindeer sledding, cultural camps), choose ethical operators who genuinely respect and promote Sámi traditions and livelihoods, ensuring fair compensation and authentic experiences. Avoid exploitative or superficial portrayals. Support Local Businesses: Patronize local restaurants, shops, and tour operators. This directly contributes to the local economy and helps communities thrive, reducing the impact of mass tourism on smaller, more vulnerable businesses. Cultural Sensitivity: Be aware of local customs and traditions. Politeness, punctuality, and an open mind are always appreciated. Ask permission before taking photos of people, especially in cultural settings. Noise Levels: The Arctic wilderness is often profoundly silent. Be mindful of noise levels, especially at night when out aurora chasing, to avoid disturbing wildlife or other aurora viewers.Wildlife Encounters:Observe from a Distance: If you encounter Arctic wildlife (reindeer, moose, foxes), observe them from a safe and respectful distance. Never feed wild animals. Driving Safely: Be extremely cautious when driving, especially at dusk and dawn. Reindeer and moose often wander onto roads, and collisions can be dangerous for both animals and humans. Guided Tours: For activities like dog sledding or snowmobiling, choose reputable operators who prioritize animal welfare and operate sustainably. Ensure the animals are well-cared for and not overworked.By incorporating these principles into your travel plans, you not only ensure a more enriching experience for yourself but also contribute to the preservation of the Arctic's natural beauty and cultural heritage. Responsible aurora chasing is about being a mindful guest in a truly spectacular, yet vulnerable, part of the world. Conclusion Chasing the Northern Lights in Scandinavia is more than just a trip; it's an expedition into the heart of nature's most dazzling artistry. From the scientific dance of solar particles and atmospheric gases to the logistical ballet of planning and budgeting, every step of this journey is an adventure in itself. We've explored the optimal viewing locations from the dramatic fjords of Norway to the serene forests of Finnish Lapland, delved into the critical timing and weather considerations, meticulously budgeted for a realistic Arctic experience, and equipped you with the technical prowess to capture these elusive light shows. Remember that patience and flexibility are your greatest allies. The aurora is a natural phenomenon, and while we can maximize our chances, there are no guarantees. Embrace the unexpected, revel in the stunning Arctic landscapes, and soak in the unique culture of the North. Whether you find yourself enveloped in the profound silence of a snowy forest as green ribbons unfurl above, or hear the excited murmurs of fellow travelers as a sudden burst of pink ignites the sky, the memory of the Aurora Borealis will be etched into your soul forever. This isn't just about seeing lights; it's about connecting with the raw power and immense beauty of our universe. Pack your warmest clothes, calibrate your camera, and prepare for an odyssey into the whispering skies of Scandinavia. May your skies be clear and your auroras be bright! Safe travels and happy chasing! Warmly, Aisha Sharma#AuroraBorealis #NorthernLights #ScandinaviaTravel #ArcticAdventures #TravelGuide #SustainableTourism Related InsightsBeyond the Sands: Unveiling Oman’s Thriving Tourism Tapestry 宏村:画中的明清古村落 Fantasmi sulla Via della Seta: Il richiamo silenzioso delle oasi perdute del Turkmenistan{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Arctic's Whispering Skies: Your Ultimate Guide to Unlocking Scandinavia's Northern Lights Mystique (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "Embark on an epic journey to witness the Aurora Borealis in Scandinavia with this expert guide covering science, locations, timing, budgeting, and photography." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Arctic's Whispering Skies: Your Ultimate Guide to Unlocking Scandinavia's Northern Lights Mystique (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Aisha Sharma." } }, { "@type": "Question", "name": "Where can I find more related content about Travel?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Travel category page." } } ] }
-
 Zola Ndlovu
- 12 Jul, 2026 17:32
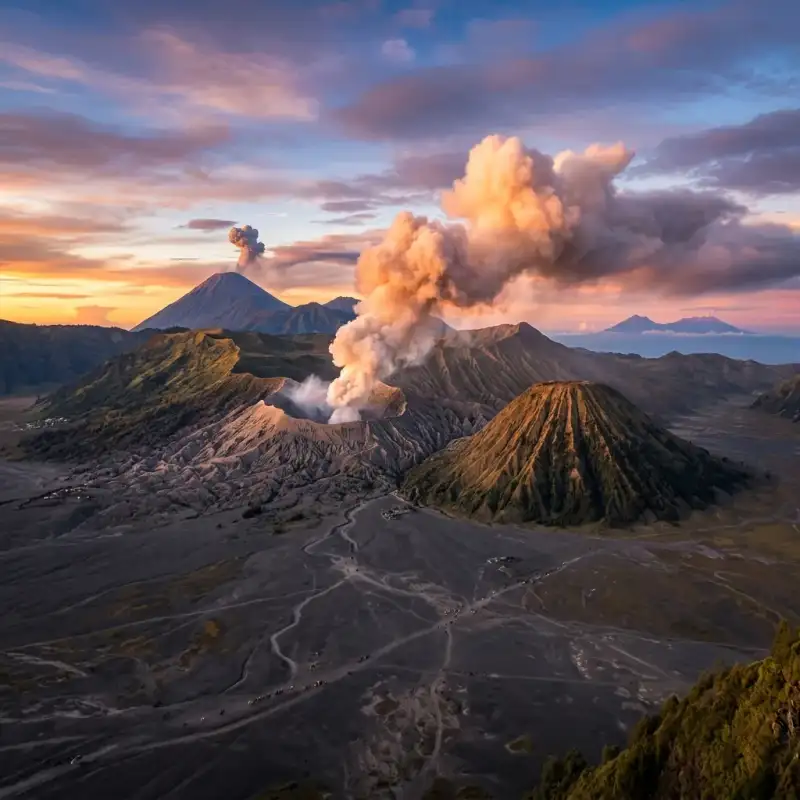
Unleash Your Inner Explorer: Conquering Java's Fiery Peaks From Bali's Shores – A Definitive Guide
Indonesia, an archipelago born of fire, offers some of the planet’s most breathtaking and accessible volcanic landscapes. While Bali captivates with its serene beaches and vibrant culture, just a short journey west lies the rugged, otherworldly beauty of East Java – home to two of the world's most iconic and active volcanoes: Mount Bromo and Kawah Ijen. For the intrepid traveler, the transition from Bali’s tranquil rice paddies to Java’s smoking craters isn't merely a change in scenery; it’s an immersive expedition into the raw, pulsating heart of the Earth. As Zola Ndlovu, an expert in transformative travel experiences, I can attest that the challenge of ascending these peaks is profoundly rewarding, revealing vistas that defy imagination and stories etched in sulfur and ash. This isn't just a travelogue; it's a meticulously researched, highly factual blueprint for navigating an adventure that combines logistical precision with unparalleled natural spectacle. Forget the hazy travel anecdotes; we're diving deep into the actionable intelligence you'll need – from visa particulars and transport costs to the specific geological phenomena of Ijen's blue flames and Bromo's sunrise majesty. We’ll dissect itineraries, equip you with crucial packing lists, and prepare you for the physical and environmental realities of trekking active stratovolcanoes. Whether you're a seasoned mountaineer or a curious wanderer seeking an extraordinary chapter in your travel saga, this comprehensive guide will empower you to not just witness, but truly conquer, Java's fiery peaks, making your journey from Bali’s shores to the volcanic heart of Indonesia an unforgettable triumph. Get ready to embark on an adventure that will redefine your understanding of natural grandeur.The Gateway to Java's Giants: From Bali to Banyuwangi Embarking on the trans-island volcanic adventure begins in Bali, specifically from its westernmost tip, to cross the narrow Bali Strait into Java. The primary objective is reaching Banyuwangi, East Java, a strategic hub and the closest major city to Kawah Ijen. The journey is multi-modal and offers a blend of local immersion and logistical efficiency, which can be tailored to various budgets and preferences. The initial leg from popular tourist centres in South Bali (e.g., Seminyak, Kuta, Ubud) to Gilimanuk Ferry Terminal typically takes between 3 to 4.5 hours, depending heavily on traffic and your chosen mode of transport. Options range from private taxis or rented cars (expect to pay IDR 500,000 – 700,000 for a car with driver one-way, a comfortable but pricier option) to shared shuttle buses (around IDR 150,000 – 250,000 per person, offering a balance of cost and convenience) or even public buses from Denpasar's Ubung Terminal (significantly cheaper, IDR 60,000 – 80,000, but often slower and less direct). For independent adventurers, renting a scooter or motorcycle (IDR 70,000 – 100,000 per day) is an option, though the long journey and heavy traffic towards Gilimanuk can be challenging for inexperienced riders. Upon arrival at Gilimanuk, the transition to the Ketapang Ferry Terminal in Banyuwangi, Java, is seamless. Ferries operate 24 hours a day, departing every 20-30 minutes, ensuring minimal waiting time. The crossing itself is remarkably short, typically 30 to 45 minutes across the strait. Foot passenger tickets are incredibly affordable, usually costing around IDR 8,500 (approximately USD 0.55). If you're bringing a scooter, the cost is around IDR 29,000. These figures are consistent with local government tariffs and are highly reliable. The ferry ride provides scenic views, often accompanied by local vendors selling snacks and drinks. Once disembarking at Ketapang, you're officially in Banyuwangi. The ferry terminal is conveniently located near Banyuwangi Kota (formerly Karangasem) train station and the city centre. From Ketapang, a short taxi ride, Go-Jek (motorcycle taxi), or Grab car can take you to your accommodation in Banyuwangi city. Expect to pay IDR 20,000 – 50,000 for a local ride depending on distance and negotiation. Banyuwangi offers a range of accommodations, from budget guesthouses starting at IDR 100,000 per night to mid-range hotels like Hotel Santika or Aston Hotel Banyuwangi around IDR 400,000 – 700,000 per night, providing comfortable bases for your Ijen ascent. Securing a comfortable stay allows for crucial rest before the challenging pre-dawn hike to Kawah Ijen.Kawah Ijen's Ethereal Blue Flames and Turquoise Lake Kawah Ijen, perched at an elevation of 2,799 metres (9,183 feet) above sea level, is a stratovolcano that offers one of Earth's most unique nocturnal spectacles: the ethereal blue flames, an incredible natural phenomenon that occurs when sulfuric gases, emerging from cracks at temperatures up to 360°C (680°F), ignite upon contact with the oxygen-rich air. This visible combustion produces the iconic blue light, often described as lava-like, though it's purely burning gas. To witness this requires a midnight start, typically between 12:00 AM and 1:00 AM, ensuring you're at the crater rim before dawn. The trek to the crater rim from the Paltuding ranger post is approximately 3 kilometres (1.8 miles) with an elevation gain of around 500 metres (1,640 feet). The path is steep and challenging in sections, particularly in the dark, and takes approximately 1.5 to 2 hours for a reasonably fit individual. Once at the rim, a further perilous descent into the crater (approximately 800 metres) is required to get closer to the blue flames. This descent is unofficial and hazardous, involving navigating loose rocks and steep, narrow paths. While many tourists undertake it, it is not without risk, especially given the low light and the highly acidic environment. The main draw beyond the blue flames is the spectacular turquoise acid lake, the largest highly acidic crater lake in the world, with a pH of approximately 0.5. The vibrant colour comes from its high concentration of sulfuric and hydrochloric acids. This lake is also the site of a traditional sulfur mining operation, where local miners endure arduous conditions, carrying loads of up to 80-100 kg of solidified sulfur up and down the crater walls. Engaging with these miners, with respect and understanding, offers a humbling glimpse into their incredibly challenging livelihood. Essential gear for Ijen includes a high-quality gas mask (critical for protection against sulfuric fumes, which can cause respiratory irritation and eye discomfort; rentals are available at the base for IDR 30,000 – 50,000, but bringing your own is advisable for hygiene and fit), a powerful headlamp, sturdy hiking boots, warm layers (temperatures can drop significantly at altitude), and plenty of water. The foreign tourist entrance fee for Kawah Ijen is IDR 100,000 on weekdays and IDR 150,000 on weekends/public holidays. These fees contribute to park maintenance and local community initiatives. Safety is paramount; follow ranger instructions, consider hiring a local guide (approx. IDR 100,000-200,000), and be aware of your surroundings, especially when descending into the crater. The fumes can be overwhelming, and visibility can be poor. Mount Bromo's Volcanic Majesty and Sunrise Spectacle From the raw, elemental beauty of Kawah Ijen, the journey continues to the iconic Mount Bromo, part of the Bromo Tengger Semeru National Park. Located in East Java, Bromo's peak stands at 2,329 metres (7,641 feet) and is famous for its breathtaking sunrise views, its perpetually smoking crater, and the vast, ethereal "Sea of Sand" (Lautan Pasir) caldera surrounding it. The typical approach after visiting Ijen is to travel from Banyuwangi to Probolinggo (the main gateway town), and then onward to Cemoro Lawang, the village perched on the rim of the caldera, offering direct access to Bromo. Getting from Banyuwangi to Cemoro Lawang usually involves a train ride from Banyuwangi Kota (Karangasem) station to Probolinggo station. Popular train services include the Sri Tanjung or Tawang Alun, with tickets ranging from IDR 60,000 (economy) to IDR 150,000 (executive) for the approximately 4-5 hour journey. From Probolinggo, public minivans (colt) or shared jeeps (approx. IDR 50,000 – 75,000 per person) shuttle travellers up to Cemoro Lawang, taking about 1.5 to 2 hours on a winding, often congested road. Organized tours frequently bundle this transport. The quintessential Bromo experience begins with a pre-dawn ascent to one of the designated viewpoints. Penanjakan 1 (2,770m/9,088ft) is the most popular, offering panoramic views of Bromo, Mount Batok, and the active Mount Semeru in the distance, bathed in the hues of dawn. Other excellent viewpoints include King Kong Hill and Seruni Point, which are often less crowded. Most visitors hire a 4x4 jeep (IDR 500,000 – 700,000 per jeep, accommodating 4-6 people) to reach these viewpoints, departing from Cemoro Lawang around 3:00-3:30 AM. After sunrise, the jeeps descend into the Sea of Sand, driving across the volcanic ash desert to the base of Mount Bromo. From the jeep drop-off point, it's approximately a 20-30 minute walk across the sandy plain to the base of Bromo's cone. Here, a set of 250 concrete steps leads directly to the crater rim. The ascent is moderate, but the loose sand and the altitude can make it tiring. At the top, you're greeted by the mesmerizing sight and sound of the active crater, continuously spewing white sulfuric smoke. The foreign tourist entrance fee for Bromo Tengger Semeru National Park is IDR 220,000 on weekdays and IDR 320,000 on weekends/public holidays. The best time to visit is during the dry season (May to October) for clear skies, though it remains a popular destination year-round.Strategic Planning & Essential Preparations for the Volcanic Traverse Successfully navigating the Bali-Java volcanic expedition requires meticulous planning and preparation. Combining Kawah Ijen and Mount Bromo into a seamless itinerary typically spans 2 to 3 days from the moment you leave Bali. A common itinerary involves traveling from Bali to Banyuwangi, hiking Ijen on the first night/early morning, then proceeding to Cemoro Lawang for the Bromo sunrise the following morning. This intense schedule is rewarding but demands good physical fitness and efficient logistics. For the budget-conscious and adventurous, independent travel offers maximum flexibility. You manage your own transport bookings (ferry, trains, local minivans), accommodation reservations, and park entrance fees. While potentially cheaper overall, it requires more time, research, and comfort with local navigation, including potential language barriers (Bahasa Indonesia is essential for non-touristy areas). For example, booking train tickets via the KAI Access app (Indonesian Railways) can simplify this, but requires an Indonesian SIM card and payment methods. Alternatively, numerous tour operators in Bali (e.g., Kuta, Ubud, Seminyak) and Banyuwangi offer all-inclusive packages. These typically cover transfers from Bali, ferry tickets, private transport in Java, accommodation, park entrance fees, and sometimes even local guides. A 2-day/1-night Ijen-Bromo tour from Bali can range from IDR 1,500,000 to IDR 3,000,000 (approximately USD 100-200), depending on the group size, quality of accommodation, and inclusions. While more expensive, these tours provide convenience, especially for those with limited time or who prefer a hassle-free experience. Essential Packing List:Clothing: Layering is key. Lightweight wicking base layers, a fleece or insulated jacket, and a wind/waterproof outer shell are crucial for cold pre-dawn temperatures (can drop to 5-10°C / 40-50°F at altitude) and potential rain. A change of clothes for after the hikes. Footwear: Sturdy, broken-in hiking boots with good ankle support are indispensable for the uneven terrain of both Ijen and Bromo. Headlamp/Flashlight: Absolutely critical for midnight treks. Ensure it has fresh batteries. Gas Mask: As mentioned, vital for Ijen. Either rent at base or bring your own. Sun Protection: Hat, sunglasses, and high-SPF sunscreen for daylight hours, especially at Bromo, where the sun can be intense. Hydration: At least 2-3 litres of water per person for each hike. Dehydration can exacerbate altitude effects. Snacks: Energy bars, fruit, nuts to keep energy levels up. Personal First Aid: Basic kit with pain relievers, blister plasters, antiseptic wipes. Camera Gear: Protection from dust and sulfur is advisable. Small Backpack: For essentials during the hike. Cash (IDR): For small purchases, local food, and tips. ATMs are available in Banyuwangi and Probolinggo but rare near the parks.Physical Fitness and Altitude: While neither Bromo nor Ijen are extremely high-altitude treks, their elevations can still cause mild altitude sickness symptoms (headache, nausea) in some individuals. Ensure you are well-rested, hydrated, and listen to your body. Regular moderate exercise leading up to the trip will greatly enhance your enjoyment. Indonesia offers a visa-free entry for up to 30 days for citizens of over 80 countries, including most of Europe, North America, Australia, and parts of Asia. For other nationalities, a Visa on Arrival (VOA) is available at major airports for IDR 500,000 (approx. USD 35), valid for 30 days and extendable once. Always check the latest visa regulations for your specific nationality before travel.Beyond the Peaks: Embracing East Java's Cultural & Culinary Delights While the primary draw is the volcanic grandeur, East Java offers a rich tapestry of cultural and culinary experiences that enrich the adventure. Venturing beyond the peaks provides a deeper understanding of the region's unique identity, distinct from Bali's Hindu-centric culture. East Java is predominantly Muslim, with influences from Javanese, Madurese, and Tenggerese ethnic groups. Local Cuisine: East Javanese cuisine is flavourful and hearty.Nasi Pecel: A staple, featuring mixed vegetables with peanut sauce, served with rice, often accompanied by peyek (peanut brittle crackers) or rempeyek (rice flour crackers). A local, nutritious and affordable meal, typically costing IDR 15,000 – 25,000. Rawon: A distinctive black beef soup, gaining its colour from the keluak (black nut), offering a unique umami flavour. A must-try, available for IDR 25,000 – 40,000. Soto Ayam: A comforting chicken soup with turmeric broth, vermicelli, and various toppings. Ubiquitous and delicious, priced around IDR 20,000 – 35,000. Bakso: Indonesian meatball soup, a popular street food snack. Prices start from IDR 10,000. Local Coffee: East Java is a coffee-growing region. Enjoy robust local blends, often served strong and sweet. Cafes in Banyuwangi and Probolinggo offer a range of options, with a cup typically costing IDR 15,000 – 30,000.Other Attractions in East Java: Consider extending your trip to include:Madakaripura Waterfall: Often combined with Bromo tours, this majestic waterfall is about 1 hour from Cemoro Lawang. It's shrouded in mist and legend, requiring a trek through a canyon to reach its main basin. Entrance fee: IDR 20,000 – 30,000, plus optional local guide. Baluran National Park: Known as "Africa van Java," this park, located near Banyuwangi, boasts savannah landscapes, acacia forests, and a diverse range of wildlife including Javan banteng, deer, and various bird species. A striking contrast to the volcanic scenery. Entrance fee for foreigners: IDR 160,000 (weekdays) / IDR 240,000 (weekends). Tumpak Sewu Waterfall: While a bit further south and requiring more travel time, this multi-tiered waterfall near Lumajang is considered by many to be the most beautiful in Java, a truly spectacular natural wonder.Connectivity and Currency: Stay connected with a local SIM card. Providers like Telkomsel (best coverage, especially in remote areas) and XL Axiata offer affordable data packages. A 10GB data package costs approximately IDR 50,000 – 70,000. Indonesian Rupiah (IDR) is the local currency. ATMs are widely available in major towns like Banyuwangi, Probolinggo, and Surabaya, but carrying smaller denominations of cash is crucial for rural areas and street vendors. The exchange rate fluctuates, but roughly 1 USD is equivalent to IDR 15,500. Engaging with local communities, particularly the Tenggerese people around Bromo, provides a unique cultural insight. They are a Hindu minority in a predominantly Muslim region, with distinct traditions and a deep reverence for the mountain spirits. Practising respectful tourism, such as supporting local vendors, disposing of waste responsibly, and being mindful of local customs, ensures a positive impact and a richer travel experience for everyone. Estimated 3-Day Independent Volcano Trek Costs (Bali to Java) This table provides a realistic cost breakdown for a solo independent traveler undertaking the Bali-Java volcano trek over approximately 3 days, excluding international flights and personal shopping. Prices are approximate and subject to change based on seasonality, negotiation skills, and personal choices.Category Item Estimated Cost (IDR) Estimated Cost (USD) NotesDay 1: Bali to BanyuwangiTransport (Bali) Shuttle Bus (South Bali to Gilimanuk) 200,000 13 Varies by starting point and operatorFerry Gilimanuk to Ketapang (foot passenger) 8,500 0.55 Fixed tariffTransport (Banyuwangi) Taxi/Go-Jek (Ketapang to Hotel) 30,000 2 Negotiable, depends on distanceAccommodation Budget Guesthouse (Banyuwangi, 1 night) 150,000 10 Basic, clean roomFood 2 Meals (Banyuwangi) 70,000 4.5 Local warung food (IDR 25k-45k/meal)Day 2: Kawah Ijen Trek & Travel to Cemoro LawangIjen Transport Shared Car/Motorbike to Paltuding 150,000 10 Return trip from Banyuwangi, often shared with other hikersIjen Entrance Fee Foreigner Weekend Ticket 150,000 10 Weekday: IDR 100k. Budget for peak price.Gas Mask Rental40,000 2.5 Essential for safetyTrain Banyuwangi to Probolinggo (Economy) 60,000 4 Sri Tanjung or Tawang Alun train. Executive option is ~IDR 150k.Transport (Probolinggo) Shared Minivan to Cemoro Lawang 75,000 5 Often packed, can negotiate for better space.Accommodation Budget Homestay (Cemoro Lawang, 1 night) 200,000 13 Very basic, sometimes no hot water. Higher-end options available.Food 3 Meals (packed lunch, dinner Cemoro Lawang) 120,000 8 Food options limited/pricier in Cemoro Lawang.Day 3: Mount Bromo Sunrise & DepartureBromo Jeep Tour Shared Jeep (to Viewpoint & Crater) 150,000 10 Based on 4-6 people per jeep (total IDR 600k-900k).Bromo Entrance Fee Foreigner Weekend Ticket 320,000 20.5 Weekday: IDR 220k. Budget for peak price.Food 1 Meal (Breakfast) 30,000 2 Simple breakfast.Miscellaneous Snacks, Water, Tips, SIM card 100,000 6.5 Buffer for unexpected costs. SIM card costs around IDR 50k-70k for data.TOTAL ESTIMATED COSTS (approx.)1,963,500 126.05 Excludes return transport from Java and major splurges.Note: 1 USD ≈ IDR 15,500 for calculation purposes.The journey from Bali's tropical allure to the stark, powerful landscapes of Java's volcanoes is more than just a trip; it's a profound odyssey that carves itself into the memory. Witnessing the incandescent blue flames of Kawah Ijen, a phenomenon rare on Earth, followed by the majestic sunrise over Mount Bromo's smoking crater, surrounded by the lunar expanse of its caldera, offers a singular experience of nature's raw, untamed power. This adventure demands preparation, physical endurance, and a spirit of resilience, but the rewards—the awe-inspiring vistas, the humbling encounters with the local communities, and the sheer triumph of conquering these formidable peaks—are immeasurable. As Zola Ndlovu, I advocate for travel that challenges, inspires, and educates. The volcanic heart of Indonesia does precisely that, offering a deep dive into geological wonders, cultural nuances, and personal limits. With this detailed guide, you are now equipped with the factual data and strategic insights to plan your own epic traverse. Embrace the challenge, respect the environment, and prepare to be utterly captivated. Indonesia's fiery peaks await your footprints, ready to etch another unforgettable chapter into your global adventures.#IndonesiaTravel #VolcanoHiking #MountBromo #KawahIjen #AdventureTravel #EastJava Related InsightsLa Cathédrale de Séville : Gothique et Héritage Andalou Algarve: As Praias Douradas e o Passado Marítimo La Alhambra: El Sueño Nazarí de Granada{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unleash Your Inner Explorer: Conquering Java's Fiery Peaks From Bali's Shores – A Definitive Guide?", "acceptedAnswer": { "@type": "Answer", "text": "Embark on an epic adventure from Bali to Java's iconic volcanoes, Mount Bromo and Kawah Ijen. This guide provides meticulous details on logistics, trekking, costs, and safety for an unforgettable journey." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unleash Your Inner Explorer: Conquering Java's Fiery Peaks From Bali's Shores – A Definitive Guide?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Zola Ndlovu." } }, { "@type": "Question", "name": "Where can I find more related content about Travel?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Travel category page." } } ] }
-
 Chloe Tremblay
- 12 Jul, 2026 15:22
Beyond the Horizon: Unveiling Naoshima and Teshima – Japan's Transformative Art Island Odyssey (Part 2)
This is Part 2 of the series. Read Part 1 here.Navigating the Setouchi Triennale: Peak Immersion and Practicalities The Setouchi Triennale is a world-renowned contemporary art festival that transforms the Seto Inland Sea islands, including Naoshima and Teshima, into a vibrant, expansive art canvas every three years. Far more than just an exhibition, the Triennale is a comprehensive initiative aimed at revitalizing the region through art, fostering interaction between local communities and international artists. Its multi-island format means that during the festival periods (typically spring, summer, and autumn), new installations emerge, existing sites may host special exhibitions, and the entire archipelago hums with an unparalleled creative energy. Planning a visit during the Triennale requires a different logistical approach compared to off-Triennale periods. During the 2022 Setouchi Triennale, total visitor numbers across all participating islands exceeded 1.1 million, a 15% increase from the 2019 edition, with Naoshima and Teshima accounting for over 60% of these visits. This surge often leads to accommodation occupancy rates nearing 95% on peak weekends, according to data from the Kagawa Tourism Association. Therefore, booking accommodations, especially on the islands themselves or in nearby Takamatsu, months in advance is absolutely crucial. Ferry services also increase in frequency and capacity to manage the influx of visitors, but queues can still be substantial, particularly for popular routes like Takamatsu to Naoshima. A key practical consideration is ticketing. While individual museum entries remain available, the Setouchi Triennale Passport becomes an invaluable asset. This passport, typically costing around ¥4,800 to ¥5,500 (2022 pricing), grants access to nearly all art sites across all participating islands for the entire duration of the festival, offering significant savings for multi-island exploration. Without the passport, visiting multiple sites individually can quickly become expensive, making the passport a highly cost-effective option for serious art enthusiasts. Cultural etiquette during the Triennale is paramount. While the atmosphere is festive, respect for local customs, private property (especially around the Art House Project), and the art itself is expected. Photography rules vary by site; always check for explicit signage. Walking quietly through residential areas and disposing of waste properly are small but important gestures. The Triennale not only showcases new art but also often features pop-up cafes, workshops, and performances, providing unique opportunities to engage with local culture and artists directly. For instance, the Shima Kitchen on Teshima often hosts special events during the festival. While the crowds are larger, the sheer scale and variety of art on display, combined with the vibrant, international atmosphere, make visiting during the Triennale an exceptionally rich and immersive experience for those prepared for the logistical considerations. Those seeking a more contemplative, unhurried visit might prefer to travel during off-Triennale years, when the permanent collections are still fully accessible, and the islands revert to a quieter charm. Essential Planning & Logistical Blueprint: From Ferries to Accommodation A successful journey to Japan's Art Islands hinges on meticulous planning, especially concerning transportation and accommodation. The main gateways to the Setouchi Sea region are Okayama City (Honshu island) and Takamatsu City (Shikoku island). Accessing the Islands:From Okayama: Take the JR Uno Line (approximately 1 hour, ¥590) to Uno Port. From Uno Port, regular ferries operated by Shikoku Kisen depart for Naoshima (Miyanoura Port and Honmura Port). The ferry to Miyanoura takes about 20-25 minutes and costs ¥290 for adults (one-way). Some slower car ferries also go to Honmura. From Takamatsu: Takamatsu Port offers more frequent and direct ferry services. High-speed ferries to Naoshima (Miyanoura Port) take approximately 25 minutes and cost ¥1,230 (one-way). Standard ferries take around 50 minutes and cost ¥520 (one-way). Takamatsu also offers direct ferries to Teshima (Ieura Port) which take approximately 30 minutes and cost ¥770. These fares are standard for 2024 operations.Getting Around the Islands:Naoshima: The island is relatively flat in the Miyanoura and Honmura areas. An island bus service connects Miyanoura Port, Honmura, and Tsutsuji-so (near Benesse House). A 1-day bus pass costs ¥500. Rental bicycles (standard and electric) are readily available at Miyanoura Port, costing ¥500-¥1,500 for a full day. Walking between some sites in Honmura is also feasible. Teshima: Teshima is significantly hillier, making electric bicycles highly recommended. These can be rented at Ieura Port and Karato Port for ¥1,000-¥1,500 for a half-day. A local bus service operates, but its frequency is lower than Naoshima's. Planning around the bus schedule is crucial if not cycling.Accommodation:On Naoshima: Options range from high-end (Benesse House Museum hotel, from ¥35,000/night) to charming guesthouses and minshuku (from ¥7,000/night). Booking well in advance is essential, especially for Benesse House. On Teshima: Accommodation is very limited, primarily consisting of a few guesthouses. It is often fully booked months ahead. Many visitors opt for a day trip to Teshima from Naoshima or Takamatsu. Takamatsu as a Base: For those seeking more choices and convenience, staying in Takamatsu is an excellent option. It offers a wide range of hotels, restaurants, and easy access to both Naoshima and Teshima via frequent ferry services. Numbeo data suggests a daily budget for a mid-range traveler to Kagawa Prefecture, inclusive of accommodation and food, ranges from ¥12,000 to ¥18,000, making Takamatsu a practical hub.Best Time to Visit: Spring (March-May) and Autumn (October-November) offer the most pleasant weather for exploring, with mild temperatures and clear skies. These seasons coincide with the Setouchi Triennale, which, while vibrant, attracts significant crowds. If you prefer a quieter experience, consider visiting during off-Triennale years. Summer (July-August) can be hot and humid, while winter (December-February) is cooler, with some outdoor installations occasionally closed due to weather, but offers the fewest crowds. Cost Considerations (Estimated Daily Averages per Person, excluding accommodation):Ferry Tickets: ¥1,000 - ¥2,500 (depending on routes and frequency) Museum Entry Fees: ¥3,000 - ¥5,000 (if visiting 2-3 major sites) Island Transport: ¥500 - ¥1,500 (bus pass or bike rental) Food & Drink: ¥3,000 - ¥6,000 (ranging from casual to mid-range dining) A sensible daily budget, excluding major accommodation costs, would range from ¥7,500 to ¥15,000 for a fulfilling art island experience.Art Islands Comparison: Naoshima vs. Teshima To aid in your planning, here's a comparative overview of Naoshima and Teshima, highlighting their unique characteristics and offerings.Feature Naoshima TeshimaKey Attractions Chichu Art Museum, Benesse House Museum, Art House Project, Lee Ufan Museum, Yayoi Kusama's Yellow Pumpkin Teshima Art Museum, Teshima Yokoo House, Les Archives du Coeur, Shima KitchenAtmosphere Concentrated art experience, modern architecture, active tourism hub, more commercialized Serene, rural, integrated with nature, contemplative, authentic island life, quieterTerrain Relatively flatter, easier for standard bicycles in main areas Hilly, significant elevation changes, electric bicycles highly recommended for explorationRecommended Stay 1-2 full days to thoroughly explore all major sites and enjoy the atmosphere 1 full day for the primary art sites, often visited as a day trip from Naoshima or TakamatsuPrimary Transport Island bus, standard bicycle, walking Island bus (less frequent), electric bicycle (highly recommended)Daily Visitor Cost ¥8,000 - ¥15,000 (museums, transport, food) ¥7,000 - ¥13,000 (museums, transport, food)Ferry Access From Uno Port (direct), Takamatsu (direct) Uno Port (via Shodoshima or direct), Takamatsu (direct, or via Naoshima)Accommodation Options More varied, from luxury hotels to guesthouses, but book well in advance Very limited guesthouses, often requiring booking months aheadConclusion The Art Islands of Naoshima and Teshima are more than just destinations; they are a pilgrimage for the culturally curious, a profound immersion into a world where human creativity converges seamlessly with the raw beauty of nature. From the architectural genius of Tadao Ando to the contemplative brilliance of Rei Naito and the vibrant, community-driven spirit of the Art House Project, these islands offer an unparalleled journey of discovery and reflection. The meticulous planning by the Benesse Art Site Naoshima project, backed by significant investment and a clear philosophical vision, has transformed these previously struggling islands into globally significant cultural epicenters. Whether you choose to navigate the bustling energy of the Setouchi Triennale or seek the quiet contemplation offered during off-peak seasons, the insights and practical guidance provided here will empower you to craft an enriching and seamless travel experience. Remember to book accommodations and ferries well in advance, especially during popular periods, and embrace the unique island rhythms. Your journey to Naoshima and Teshima will be one that not only captivates your senses but also deepens your understanding of art's transformative power and its ability to revitalize communities and inspire the soul. Prepare to be moved, challenged, and utterly captivated by Japan's extraordinary Art Islands. Chloe Tremblay Professional Blogger & Expert in Global Travel#JapanTravel #ArtIslands #Naoshima #Teshima #ContemporaryArt #CulturalImmersion #SetouchiTriennale#JapanTravel #ArtIslands #Naoshima #Teshima #ContemporaryArt #IslandHopping #CulturalImmersion Related InsightsLa Cathédrale de Reims : Le Sanctuaire des Rois de France L'Abbaye de Westminster : Le Cœur Royal de Londres Die steinerne Ewigkeit von Stonehenge: Ein Echo aus prähistorischen Nebeln, das bis heute verweilt{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Beyond the Horizon: Unveiling Naoshima and Teshima – Japan's Transformative Art Island Odyssey (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "Embark on an unparalleled journey to Naoshima and Teshima, Japan's revered art islands. This comprehensive guide reveals how these cultural havens offer a profound immersion into contemporary art, architecture, and breathtaking island landscapes." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Beyond the Horizon: Unveiling Naoshima and Teshima – Japan's Transformative Art Island Odyssey (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Chloe Tremblay." } }, { "@type": "Question", "name": "Where can I find more related content about Travel?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Travel category page." } } ] }
-
 Alexander Vance
- 12 Jul, 2026 14:00
Unveiling the Algorithmic Oracle: Navigating the Perilous Landscape of AI Ethics & Governance
The proliferation of Artificial Intelligence, from the sophisticated generative capabilities of large language models like GPT-4 to the predictive power of advanced deep learning architectures, marks a new epoch in technological evolution. As an AI researcher and senior software engineer, I've witnessed firsthand the breathtaking pace of innovation. Yet, with this unprecedented power comes an equally profound responsibility. The "algorithmic oracle" we are building holds the potential for immense societal benefit, but also carries inherent risks: entrenched biases, opaque decision-making, privacy infringements, and accountability vacuums. Navigating this intricate landscape requires more than just technical prowess; it demands a robust framework of AI ethics and governance. This isn't merely a philosophical exercise; it's a critical engineering challenge, a design imperative, and a regulatory necessity. We're past the theoretical discussions. Today, responsible AI is about concrete methodologies, auditable pipelines, and verifiable fairness metrics integrated directly into our MLOps practices. This article delves deep into the technical intricacies of building ethical AI, drawing insights from foundational arXiv papers, battle-tested GitHub projects, and the practical challenges faced by leading tech ventures from Y Combinator cohorts. We'll explore the current state-of-the-art in tackling bias, enhancing transparency, safeguarding data, and establishing clear accountability, providing actionable insights and code examples for the vanguard of AI development. Deconstructing AI Bias and Fairness Metrics The Achilles' heel of many AI systems is bias. This isn't a new phenomenon; it's a systemic issue often inherited from historical data, flawed collection methods, or the very structure of our algorithms. As evidenced by numerous studies – from predictive policing models exhibiting racial bias to hiring algorithms disadvantaging women – the consequences are tangible and severe. Addressing bias requires a multi-faceted approach, starting with a deep technical understanding of its origins and quantifiable detection methods. Bias can manifest in several forms:Selection Bias: Non-random sampling or data collection leads to unrepresentative datasets. Think of an image dataset predominantly featuring lighter skin tones, leading to poor performance on darker skin tones. Historical Bias: Real-world societal biases are encoded into the data itself. E.g., past lending data might reflect discriminatory practices, perpetuating them if an AI learns from it uncritically. Measurement Bias: Inaccurate or inconsistent labeling of data. Algorithmic Bias: Introduced during model design, training, or deployment (e.g., specific loss functions or regularization techniques impacting certain groups differently).To quantify and mitigate these biases, we rely on a suite of fairness metrics. There is no single "fairness" definition; rather, different metrics address different ethical concerns, often presenting trade-offs.Demographic Parity (or Statistical Parity): Requires that a positive outcome (e.g., loan approval, job offer) is granted at the same rate across different protected groups, regardless of individual characteristics. P(Y=1 | A=a) = P(Y=1 | A=b) where Y is the outcome and A is the protected attribute. Equalized Odds: A more stringent criterion, requiring equal true positive rates (TPR) and equal false positive rates (FPR) across groups. P(Y=1 | A=a, Y_true=1) = P(Y=1 | A=b, Y_true=1) AND P(Y=1 | A=a, Y_true=0) = P(Y=1 | A=b, Y_true=0). This is crucial for high-stakes applications like medical diagnoses or recidivism prediction. Predictive Parity (or Predictive Rate Parity): Requires that the precision (positive predictive value) is the same across groups. P(Y_true=1 | A=a, Y=1) = P(Y_true=1 | A=b, Y=1).Consider a simple Python example using the open-source aif360 library, a staple for many researchers and practitioners in this domain (cf. arXiv:1803.02453, "Fairness Metrics for Machine Learning: A Survey"). This library provides tools for bias detection and mitigation. import pandas as pd from aif360.datasets import StandardDataset from aif360.metrics import BinaryLabelDatasetMetric from aif360.metrics import ClassificationMetric from sklearn.linear_model import LogisticRegression from sklearn.preprocessing import StandardScaler from sklearn.model_selection import train_test_split# Sample data (hypothetical credit scoring) data = { 'age': [25, 30, 35, 40, 45, 50, 55, 60, 28, 32, 48, 52], 'income': [30000, 40000, 50000, 60000, 70000, 80000, 90000, 100000, 35000, 42000, 75000, 85000], 'education_level': [1, 2, 2, 3, 3, 4, 4, 4, 1, 2, 3, 4], # 1=high school, 4=phd 'credit_score': [600, 650, 700, 750, 800, 850, 900, 950, 620, 680, 780, 880], 'ethnicity': [0, 1, 0, 1, 0, 1, 0, 1, 0, 1, 0, 1], # 0=Group A (disadvantaged), 1=Group B 'loan_approved': [0, 1, 0, 1, 1, 1, 1, 1, 0, 1, 1, 1] # 0=rejected, 1=approved } df = pd.DataFrame(data)# Define protected attributes and favorable/unfavorable labels protected_attribute_names = ['ethnicity'] privileged_classes = [[1]] # Group B is privileged label_name = 'loan_approved' favorable_label = 1# Convert to AIF360's StandardDataset format ad = StandardDataset( df, label_name=label_name, favorable_classes=[favorable_label], protected_attribute_names=protected_attribute_names, privileged_classes=privileged_classes )# Split data train, test = ad.split([0.7], shuffle=True)# Train a simple logistic regression model scaler = StandardScaler() X_train = scaler.fit_transform(train.features) X_test = scaler.transform(test.features) y_train = train.labels.ravel() y_test = test.labels.ravel()model = LogisticRegression(solver='liblinear') model.fit(X_train, y_train)# Get predictions test_pred = model.predict(X_test) test_probs = model.predict_proba(X_test)[:, 1]# Create a dataset with predictions for fairness evaluation test_pred_dataset = test.copy() test_pred_dataset.labels = test_pred# Calculate fairness metrics metric = ClassificationMetric( test, test_pred_dataset, unprivileged_groups=[{'ethnicity': 0}], privileged_groups=[{'ethnicity': 1}] )print(f"Disparate Impact (Demographic Parity): {metric.disparate_impact()}") print(f"Equal Opportunity Difference (TPR difference): {metric.equal_opportunity_difference()}") print(f"Average Odds Difference: {metric.average_odds_difference()}")This snippet demonstrates how to set up data for aif360 and compute foundational fairness metrics. A disparate_impact value significantly below 0.8 or above 1.25 often indicates potential demographic parity violations, as per common guidelines. An equal_opportunity_difference near zero signifies equal TPR across groups, which is critical in high-stakes scenarios. The challenge remains that improving one fairness metric might degrade another, necessitating careful ethical deliberation alongside technical optimization.Ensuring Transparency and Explainability (XAI) in Black-Box Models The rise of deep learning, particularly complex neural network architectures like Transformers and convolutional networks, has led to incredible performance gains. However, this often comes at the cost of interpretability, creating "black-box" models whose decisions are difficult for humans to understand or audit. This opacity poses significant ethical and governance challenges, especially in regulated industries or applications with high societal impact. How can we trust, debug, or even improve a system if we don't understand why it made a particular decision? This is where Explainable AI (XAI) comes into play. XAI techniques aim to shed light on model decisions, fostering trust, enabling compliance with regulations (e.g., "right to explanation" under GDPR), and empowering developers to identify and mitigate model vulnerabilities. Key XAI approaches include:Local Interpretable Model-agnostic Explanations (LIME): (arXiv:1602.04938) LIME explains individual predictions by training an interpretable surrogate model (e.g., linear model) locally around the prediction point. It samples perturbed data around the instance, gets predictions from the black-box model, and then trains a weighted, interpretable model on this local data. SHapley Additive exPlanations (SHAP): (arXiv:1705.07874) Based on cooperative game theory, SHAP values attribute the prediction of an instance to its features by calculating the marginal contribution of each feature across all possible coalitions of features. This provides a unified measure of feature importance, both globally and for individual predictions. Feature Importance/Permutation Importance: A global interpretation method that measures how much the model's performance decreases when a feature's values are randomly shuffled, effectively breaking its relationship with the target. Attention Mechanisms: In deep learning models like Transformers, attention weights reveal which parts of the input (e.g., words in a sentence) were most salient for a given output prediction.Let's illustrate SHAP with a simple example using shap library, which is widely adopted due to its theoretical grounding and practical utility. import shap import pandas as pd from sklearn.model_selection import train_test_split from sklearn.ensemble import RandomForestClassifier# Load a common dataset for demonstration (e.g., adult income dataset) # For real-world use, replace with your actual data from sklearn.datasets import load_breast_cancer data = load_breast_cancer() X = pd.DataFrame(data.data, columns=data.feature_names) y = pd.Series(data.target)# Train a Random Forest Classifier X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42) model = RandomForestClassifier(random_state=42) model.fit(X_train, y_train)# Create a SHAP explainer object # For tree-based models, TreeExplainer is efficient explainer = shap.TreeExplainer(model)# Calculate SHAP values for the test set shap_values = explainer.shap_values(X_test)# Plot summary for feature importance (global view) # Note: shap_values can be a list of arrays for multi-output models. # For binary classification, shap_values[1] typically corresponds to the positive class. print("--- SHAP Global Feature Importance (Summary Plot) ---") # shap.summary_plot(shap_values[1], X_test) # Uncomment to visualize if running in a notebook# Explain a single prediction (local view) sample_idx = 0 # Choose the first instance from the test set print(f"\n--- SHAP Explanation for a single instance (index {sample_idx}) ---") # shap.initjs() # For interactive JS plots in notebooks # shap.force_plot(explainer.expected_value[1], shap_values[1][sample_idx], X_test.iloc[sample_idx]) # Uncomment to visualize# For programmatic access to feature contributions for that instance: print(f"Model prediction for instance {sample_idx}: {model.predict_proba(X_test.iloc[[sample_idx]])[0][1]:.4f}") print("Feature contributions (SHAP values):") for feature, shap_val in zip(X_test.columns, shap_values[1][sample_idx]): print(f" {feature}: {shap_val:.4f}")The shap library provides powerful visualizations like summary_plot (global feature importance) and force_plot (individual prediction explanation), allowing engineers and stakeholders to understand which features drive particular outcomes. While XAI is a crucial step towards responsible AI, it’s not a panacea. The explanations themselves can sometimes be misleading, or their fidelity to the underlying black-box model may be imperfect. The key is to use XAI iteratively within the MLOps lifecycle to debug models, ensure compliance, and build user trust.Data Privacy, Security, and Synthetic Data Generation for Responsible AI In an era of ubiquitous data collection, upholding privacy and security is paramount for ethical AI. The intersection of large datasets, powerful analytical models, and sensitive personal information creates a complex minefield of potential privacy breaches, adversarial attacks, and regulatory non-compliance. Frameworks like GDPR, CCPA, and upcoming sector-specific regulations are not merely legal hurdles; they are ethical benchmarks demanding robust technical solutions. Key challenges and solutions include:Data Leakage and Re-identification: AI models, especially generative ones, can inadvertently memorize and reproduce sensitive training data. Re-identification attacks can link anonymized data back to individuals. Differential Privacy: (arXiv:0602048) A rigorous mathematical definition of privacy that guarantees individual data points contribute negligibly to the overall model output. By injecting calibrated noise during training or query responses, it prevents adversaries from inferring much about any single individual's data, even with auxiliary information. This often comes with a trade-off in model utility. Federated Learning: (arXiv:1602.05629) Instead of bringing data to a central server, federated learning trains models collaboratively across decentralized devices or organizations while keeping raw data local. Only model updates (gradients or weights) are aggregated, often with additional privacy-preserving techniques like differential privacy or secure aggregation.Adversarial Attacks: Malicious actors can craft subtly perturbed inputs (adversarial examples) that cause AI models to misclassify with high confidence, threatening system integrity and safety (e.g., autonomous vehicles misinterpreting stop signs). Adversarial Training: Augmenting training data with adversarial examples to make models more robust. Defensive Distillation: Training a second model on the probabilities generated by an initial model, making it less sensitive to small input perturbations.Synthetic Data Generation (SDG): Creating artificial data that statistically resembles real data but contains no direct information about individual original records. This is a game-changer for privacy-preserving AI development. Generative Adversarial Networks (GANs): A generator network learns to create synthetic data that fools a discriminator network into thinking it's real. Variational Autoencoders (VAEs): Learn a latent representation of the data to generate new, similar samples. CTGAN (Conditional Tabular GAN): Specifically designed for tabular data, outperforming traditional statistical methods and generic GANs in generating high-quality synthetic tables. (GitHub: sdv-dev/SDV)Here's a conceptual Python example illustrating a differentially private approach using the opacus library for PyTorch, a concrete implementation of DP for deep learning models. import torch import torch.nn as nn import torch.optim as optim from torch.utils.data import DataLoader, TensorDataset from opacus import privacy_engine# 1. Define a simple neural network class SimpleNet(nn.Module): def __init__(self): super(SimpleNet, self).__init__() self.fc1 = nn.Linear(10, 5) # Input features = 10 self.relu = nn.ReLU() self.fc2 = nn.Linear(5, 1) # Output = 1 (binary classification) self.sigmoid = nn.Sigmoid() def forward(self, x): x = self.fc1(x) x = self.relu(x) x = self.fc2(x) x = self.sigmoid(x) return x# 2. Generate some dummy data X_dummy = torch.randn(100, 10) # 100 samples, 10 features y_dummy = torch.randint(0, 2, (100, 1)).float() # Binary labels dataset = TensorDataset(X_dummy, y_dummy) dataloader = DataLoader(dataset, batch_size=16)# 3. Instantiate model, optimizer, and loss function model = SimpleNet() optimizer = optim.SGD(model.parameters(), lr=0.01) criterion = nn.BCELoss()# 4. Integrate Opacus for Differential Privacy privacy_engine.make_private_with_epsilon( module=model, optimizer=optimizer, data_loader=dataloader, target_epsilon=10.0, # Desired privacy budget (epsilon) target_delta=1e-5, # Desired privacy failure probability (delta) epochs=10, # Total epochs for training max_grad_norm=1.0 # Clipping norm for gradients )print(f"Model is now private: {privacy_engine.is_private(optimizer)}")# 5. Training loop (now with differential privacy applied) for epoch in range(10): for data, target in dataloader: optimizer.zero_grad() output = model(data) loss = criterion(output, target) loss.backward() optimizer.step() # At the end of each epoch, query the privacy accountant epsilon, best_alpha = optimizer.privacy_engine.get_epsilon(target_delta=1e-5) print(f"Epoch {epoch+1}, Epsilon: {epsilon:.2f}, Loss: {loss.item():.4f}")This snippet demonstrates the ease with which libraries like Opacus can transform a standard PyTorch training loop into a differentially private one. While the make_private_with_epsilon function simplifies much of the underlying complexity (like adding noise to gradients and clipping them), understanding the implications of target_epsilon and target_delta is critical for real-world deployment. Lower epsilon means stronger privacy but potentially lower model accuracy. SDG, on the other hand, allows for training on privacy-preserving, high-fidelity data, mitigating re-identification risks without the utility trade-offs often seen with direct DP application on real data.Establishing Robust AI Governance Frameworks and MLOps Pipelines Ethical AI is not a post-deployment afterthought; it must be ingrained into the entire Machine Learning Operations (MLOps) lifecycle. Just as DevOps brought agility and reliability to software development, MLOps extends these principles to AI systems, adding crucial layers for governance, monitoring, and continuous assurance. Without a structured MLOps pipeline, even well-intentioned ethical considerations can become ad-hoc, unscalable, and ultimately ineffective. A robust AI governance framework, often codified through MLOps, addresses several key areas:Model Versioning and Lineage: Tracking every iteration of a model, its associated data, code, and training parameters. This is foundational for auditability and reproducibility. Data Governance: Managing data quality, provenance, access control, and privacy throughout its lifecycle. This includes automated checks for data drift and bias detection. Continuous Monitoring: Beyond traditional performance metrics (accuracy, F1-score), MLOps pipelines must monitor for: Data Drift: Changes in input data distribution over time, potentially rendering the model stale. Concept Drift: Changes in the relationship between input features and target variable. Fairness Drift: Deterioration of fairness metrics for specific protected groups. Explainability Drift: Changes in feature importance or attribution over time, potentially indicating hidden model shifts.Bias Detection & Mitigation in Production: Automated tools to continually assess fairness metrics on live predictions and trigger alerts or retraining if bias thresholds are exceeded. Transparency and Audit Trails: Ensuring that every decision, action, and output of the AI system is logged and auditable, critical for regulatory compliance (e.g., EU AI Act, NIST AI Risk Management Framework). Human-in-the-Loop Integration: Designing workflows for human review, feedback, and override at critical decision points.Consider a simplified MLOps pipeline step, perhaps in a CI/CD system like GitHub Actions or GitLab CI, focused on model validation and fairness checks before deployment to production. This YAML configuration demonstrates a conceptual stage where an existing model is evaluated against fairness benchmarks. # .github/workflows/model-validation.yml name: AI Model Validation and Fairness Checkson: pull_request: branches: [ main ] types: [ opened, synchronize, reopened ] workflow_dispatch:jobs: validate_model: runs-on: ubuntu-latest steps: - name: Checkout repository uses: actions/checkout@v3 - name: Set up Python uses: actions/setup-python@v4 with: python-version: '3.9' - name: Install dependencies run: | pip install pandas scikit-learn aif360 # For a full MLOps system, you'd install MLflow, Sagemaker SDK, etc. - name: Download latest production model and test data # In a real scenario, this would involve fetching from a model registry # e.g., using MLflow.download_artifacts or S3/GCS download run: | echo "Simulating model download from registry..." # Example: Replace with actual model artifact retrieval echo "Creating dummy model and data for demonstration" python -c " import joblib, pandas as pd from sklearn.linear_model import LogisticRegression from sklearn.datasets import make_classification X, y = make_classification(n_samples=1000, n_features=10, random_state=42) df = pd.DataFrame(X, columns=[f'feature_{i}' for i in range(10)]) df['ethnicity'] = pd.Series(y).apply(lambda x: 0 if x < 0.5 else 1) # Simulate protected attr df['target'] = y model = LogisticRegression().fit(df.drop(['target', 'ethnicity'], axis=1), df['target']) joblib.dump(model, 'prod_model.pkl') df.to_csv('test_data.csv', index=False) " - name: Run Model Fairness and Performance Validation run: | python <<EOF import joblib import pandas as pd from aif360.datasets import StandardDataset from aif360.metrics import ClassificationMetric from sklearn.metrics import accuracy_score, f1_score# Load model and data model = joblib.load('prod_model.pkl') test_df = pd.read_csv('test_data.csv')# Prepare AIF360 dataset ad = StandardDataset( test_df, label_name='target', favorable_classes=[1], protected_attribute_names=['ethnicity'], privileged_classes=[[1]] # Group with 'ethnicity':1 is privileged )# Make predictions predictions = model.predict(test_df.drop(['target', 'ethnicity'], axis=1))# Create a dataset with predictions for fairness evaluation pred_dataset = ad.copy() pred_dataset.labels = predictions# Calculate classification metrics accuracy = accuracy_score(test_df['target'], predictions) f1 = f1_score(test_df['target'], predictions)# Calculate fairness metrics metric = ClassificationMetric( ad, pred_dataset, unprivileged_groups=[{'ethnicity': 0}], privileged_groups=[{'ethnicity': 1}] )di = metric.disparate_impact() eod = metric.equal_opportunity_difference()print(f"Model Accuracy: {accuracy:.4f}") print(f"Model F1 Score: {f1:.4f}") print(f"Disparate Impact: {di:.4f}") print(f"Equal Opportunity Difference: {eod:.4f}")# Define thresholds for passing if accuracy < 0.75: print("Error: Model accuracy is below threshold!") exit(1) if di < 0.8 or di > 1.25: print("Error: Disparate Impact is outside acceptable range!") exit(1) if abs(eod) > 0.1: # Example threshold for equal opportunity print("Error: Equal Opportunity Difference is too high!") exit(1)print("Model passed all validation checks!") EOFThis YAML snippet represents a crucial step in an MLOps pipeline. It automates the evaluation of a model against predefined performance and fairness thresholds. If any threshold is breached, the pipeline fails, preventing potentially biased or underperforming models from reaching production. This proactive, automated approach is the bedrock of operationalizing responsible AI, ensuring continuous oversight from development through deployment and monitoring. The Challenge of AI Accountability and Human Oversight As AI systems become more autonomous and complex, the question of accountability — who or what is responsible when an AI system causes harm — becomes increasingly thorny. This isn't just a legal puzzle; it's an ethical imperative. If an autonomous vehicle causes an accident, if an AI-driven medical diagnostic tool makes a fatal error, or if an algorithmic trading system crashes markets, where does the buck stop? Attributing responsibility is complicated by the distributed nature of AI development, involving data scientists, engineers, product managers, and various stakeholders. Establishing accountability requires integrating human oversight mechanisms and clear lines of responsibility throughout the AI lifecycle.Human-in-the-Loop (HITL): This involves humans actively participating in the AI decision-making process. Review and Correction: Humans review AI predictions or actions and correct them. For example, content moderation systems where AI flags content, but human moderators make final decisions. Active Learning: Humans label ambiguous data points to improve model performance and generalization. Exception Handling: AI handles routine tasks, but complex or high-stakes cases are routed to human experts.Human-on-the-Loop (HOTL): Humans monitor AI systems and intervene if necessary. Performance Monitoring: Humans monitor dashboards for model drift, fairness violations, or anomalous behavior. Audit and Oversight: Regular audits of AI system logs and decisions by human oversight committees. Kill Switch/Override: The ability for humans to shut down or override an AI system in emergencies.Clear Lines of Responsibility: Designers/Developers: Accountable for the ethical design, testing, and documentation of the AI system, including inherent biases and limitations. Deployers/Operators: Responsible for the appropriate deployment, monitoring, and maintenance of the AI in specific contexts. Owners/Stakeholders: Ultimate responsibility for the AI's impact, requiring them to establish governance policies and ensure compliance.One practical implementation of HITL is to design inference pipelines that flag uncertain predictions or decisions impacting protected groups for human review. # Python pseudo-code for a human review trigger in an inference pipeline import numpy as np import pandas as pd # Assume 'model' is a pre-trained sklearn-compatible model # Assume 'threshold_uncertainty' is a defined confidence level (e.g., 0.6 for binary classification) # Assume 'protected_attribute_names' is a list of column names for protected attributesdef get_prediction_with_review(model, input_data, threshold_uncertainty=0.6, protected_attribute_names=None): """ Makes a prediction and flags for human review based on uncertainty or protected attributes. Args: model: Trained ML model with predict_proba method. input_data (pd.DataFrame): Input features for a single instance. threshold_uncertainty (float): Probability threshold below which to flag for review. protected_attribute_names (list): List of column names in input_data representing protected attributes. Returns: tuple: (prediction, review_flag, reason_for_review) """ prediction = model.predict(input_data)[0] probabilities = model.predict_proba(input_data)[0] max_prob = np.max(probabilities) review_flag = False reason = [] # Check for uncertainty if max_prob < threshold_uncertainty: review_flag = True reason.append(f"Low confidence prediction ({max_prob:.2f})") # Check for protected attributes (simplified logic: always review if protected attribute is present) # A more sophisticated approach would involve checking fairness metrics or specific edge cases if protected_attribute_names: for attr in protected_attribute_names: if attr in input_data.columns and input_data[attr].iloc[0] is not None: # This is a very simplistic check. Real-world would integrate aif360 # or similar to check if the prediction for this group is often biased. review_flag = True reason.append(f"Involves protected attribute: {attr}") break # Only need one protected attribute to trigger review if review_flag: print(f"Prediction for input: {prediction}, flagged for human review. Reasons: {', '.join(reason)}") return prediction, True, reason else: return prediction, False, None# Example Usage: # Assuming a model trained on a dataset with 'gender' as a protected attribute # model = ... (your trained model) # test_instance_safe = pd.DataFrame([[0.1, 0.2, 0.3, 0.4, 0.5, 0.6, 0.7, 0.8, 0.9, 1.0, 0]], # columns=[f'feature_{i}' for i in range(10)] + ['gender']) # test_instance_uncertain = pd.DataFrame([[0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 0.5, 1]], # columns=[f'feature_{i}' for i in range(10)] + ['gender'])# # Let's simulate a model for demonstration # from sklearn.datasets import make_classification # from sklearn.ensemble import RandomForestClassifier # X_train, y_train = make_classification(n_samples=100, n_features=10, random_state=42) # mock_model = RandomForestClassifier(random_state=42) # mock_model.fit(X_train, y_train)# # Create an example input # input_data_example = pd.DataFrame(np.random.rand(1, 10), columns=[f'feature_{i}' for i in range(10)]) # input_data_example['gender'] = 0 # Example protected attribute# pred, flagged, reasons = get_prediction_with_review(mock_model, input_data_example, protected_attribute_names=['gender']) # print(f"Final Decision: {pred}, Flagged: {flagged}, Reasons: {reasons}")# input_data_uncertain = pd.DataFrame(np.full((1, 10), 0.5), columns=[f'feature_{i}' for i in range(10)]) # input_data_uncertain['gender'] = 1 # pred_unc, flagged_unc, reasons_unc = get_prediction_with_review(mock_model, input_data_uncertain, threshold_uncertainty=0.6, protected_attribute_names=['gender']) # print(f"Final Decision: {pred_unc}, Flagged: {flagged_unc}, Reasons: {reasons_unc}")This pseudo-code demonstrates a rudimentary human review trigger. In a production system, input_data would be passed through an explainability module (like SHAP) and then sent to a human dashboard for review, along with the explanation and reasons for flagging. Building such robust oversight mechanisms directly into AI deployment workflows is crucial for establishing credible accountability and mitigating risks associated with fully autonomous systems.The Evolving Regulatory Landscape and Global Frameworks for Responsible AI The imperative for AI ethics and governance is not just a plea from researchers; it's rapidly being codified into legal frameworks and industry standards worldwide. From the EU's pioneering AI Act to NIST's comprehensive AI Risk Management Framework, governments and international bodies are grappling with how to regulate this fast-moving technology. Understanding these frameworks is critical for any organization developing or deploying AI, not only for compliance but also for embedding responsible practices into their core operations. Here's a comparison of some prominent global frameworks:Feature/Framework EU AI Act NIST AI Risk Management Framework (AI RMF) UNESCO Recommendation on the Ethics of AIType Binding Regulation (Law) Voluntary Framework (Guidance) International Standard-Setting Instrument (Soft Law)Scope Providers & Deployers of AI Systems in EU. Risk-based approach. Developers & Users of AI (Public & Private). Lifecycle focus. Member States & Stakeholders globally. Comprehensive principles.Key Mechanism Prohibitions (e.g., social scoring), High-Risk AI (conformity assessment, human oversight), Limited Risk (transparency), Minimal Risk (self-regulation). Govern, Map, Measure, Manage (four core functions). Focus on continuous risk management. 10 Key Principles (e.g., proportionality, safety, privacy, fairness, transparency, accountability).Enforcement Fines up to 6% of global turnover or €30M. Not legally binding; encourages best practices for trustworthy AI. No direct enforcement; encourages integration into national laws.Focus Market access, safety, fundamental rights, consumer protection. Practical guidance for organizations to manage AI risks, promote trustworthy AI. Human-centric approach, promote human rights, sustainable development, global cooperation.Technical Aspects Emphasizes technical documentation, risk assessment, quality management, human oversight, robustness, accuracy, cybersecurity. Provides practical steps, tools, and processes for assessing and managing risks at each stage of the AI lifecycle. Outlines ethical requirements for data governance, design, development, and deployment, including XAI, bias mitigation.Industry Impact Significant regulatory burden for high-risk AI; shapes global AI market. Influences industry standards, provides blueprint for responsible AI adoption. Guides national AI strategies, promotes common ethical understanding.Status (as of 2024) Adopted, implementation ongoing. Published v1.0, widely adopted. Adopted by General Conference, guiding policy.The EU AI Act is particularly noteworthy as a binding legal framework. It adopts a tiered, risk-based approach:Unacceptable Risk: AI systems that manipulate human behavior, enable social scoring by public authorities, or exploit vulnerabilities are outright banned. High-Risk AI: Systems used in critical infrastructure, education, employment, law enforcement, migration, justice, and democratic processes. These require stringent conformity assessments, robust quality management systems, human oversight, cybersecurity measures, transparency, and accuracy. This means deep technical documentation (similar to medical device regulations), continuous monitoring, and auditable pipelines. Limited Risk AI: Systems with specific transparency obligations, e.g., chatbots must disclose they are AI. Minimal Risk AI: Most AI systems fall here and are subject to voluntary codes of conduct.The NIST AI RMF, while voluntary, provides practical, adaptable guidance for managing risks throughout the AI lifecycle. Its "Govern-Map-Measure-Manage" functions offer a structured approach for organizations to:Govern: Establish a culture of responsible AI. Map: Identify and characterize AI risks. Measure: Assess, analyze, and track AI risks. Manage: Prioritize, respond to, and communicate AI risks.These frameworks, whether regulatory or guidance-based, underscore a universal truth: responsible AI development is no longer optional. It demands proactive integration of ethical considerations into every phase of the AI product lifecycle, from data acquisition and model training to deployment and continuous monitoring. Ignoring them not only invites severe legal repercussions but also erodes public trust, hindering the very innovation AI promises. Conclusion: Engineering a Trustworthy AI Future The journey through AI ethics and governance reveals a landscape teeming with both transformative potential and intricate challenges. From the insidious pitfalls of algorithmic bias and the opaque nature of black-box models to the critical demands of data privacy, accountability, and emerging regulatory mandates, the path to responsible AI is multifaceted and requires relentless dedication. As an engineer and researcher, my conviction is firm: merely acknowledging these issues is insufficient; we must engineer solutions, embed ethical considerations directly into our codebases, and integrate robust governance into our MLOps pipelines. We've explored how technical solutions like advanced fairness metrics, XAI techniques such as SHAP and LIME, privacy-preserving methods like differential privacy and synthetic data generation, and structured MLOps frameworks are not just theoretical constructs but essential tools for building trustworthy AI. The convergence of arXiv's cutting-edge research, GitHub's open-source innovation, and the pragmatic demands of Y Combinator-backed startups points to a clear trajectory: responsible AI is becoming the new standard for quality, reliability, and market viability. The task ahead is immense, demanding interdisciplinary collaboration between technologists, ethicists, policymakers, and legal experts. It calls for continuous learning, iterative improvement, and a steadfast commitment to human-centric AI design. The responsibility falls upon us, the architects of this algorithmic future, to not only push the boundaries of what AI can do but also to ensure it serves humanity's best interests, with fairness, transparency, and accountability at its core. Let's build AI that inspires trust, not fear, and empowers, rather than marginalizes.#AI Ethics #AIGovernance #ResponsibleAI #MLOps #ExplainableAI Related InsightsUnlocking the Secrets of Quantum Computing: Breakthroughs in Qubit Stability and Error Correction The Ultimate Guide to Custom PC Building: Forging Your Digital Masterpiece Quantum Sensors: The Next Frontier in Precision Measurement with Unbreakable Physics{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unveiling the Algorithmic Oracle: Navigating the Perilous Landscape of AI Ethics & Governance?", "acceptedAnswer": { "@type": "Answer", "text": "A comprehensive, technical exploration of AI ethics, governance, and the imperative for responsible AI development, drawing on cutting-edge research and practical MLOps strategies." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unveiling the Algorithmic Oracle: Navigating the Perilous Landscape of AI Ethics & Governance?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Alexander Vance." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Kaan Demir
- 12 Jul, 2026 13:39
Beyond Silicon: Why Neuromorphic Computing Is The Brain's Ultimate Gambit Against AI's Energy Crisis
Introduction In the relentless pursuit of Artificial Intelligence, a silent crisis looms: the insatiable energy demands and the fundamental architectural limitations of conventional computing. From the colossal power draw of training GPT-4 sized models to the perennial "memory wall" that bottlenecks data movement between processor and memory, our silicon-based von Neumann architectures are increasingly becoming a gilded cage for advanced AI. The brain, conversely, operates on an entirely different principle: billions of neurons consuming a mere 20 watts, processing information with unparalleled efficiency, parallelization, and adaptability. This stark contrast isn't just an evolutionary marvel; it's a profound engineering blueprint. Enter neuromorphic computing – a radical paradigm shift that seeks to transcend the limitations of traditional hardware by mimicking the brain's structure and function. This isn't just about running neural networks faster; it's about fundamentally rethinking how computation happens, moving away from clock-driven, instruction-based processing to event-driven, massively parallel, and energy-proportional computation. For decades, it existed primarily in academic labs, but now, fueled by advancements in materials science, chip fabrication, and a deeper understanding of computational neuroscience, neuromorphic hardware is on the cusp of revolutionizing edge AI, IoT, robotics, and complex real-time decision-making. The future of AI isn't just about smarter algorithms; it's about hardware that thinks like a brain. This is the ultimate gambit against AI's energy crisis, promising a new era of intelligence that is both powerful and profoundly efficient. The Von Neumann Bottleneck and the Biological Imperative The ubiquitous von Neumann architecture, with its separate processing unit and memory, has served computing remarkably well for over 70 years. However, its Achilles' heel – the "memory wall" or "von Neumann bottleneck" – becomes acutely apparent with data-intensive workloads like modern deep learning. Data must constantly shuttle between the CPU/GPU and main memory, a process that consumes significant energy and time. For every operation, data transfer can be orders of magnitude more energy-intensive than the computation itself. As AI models scale, this bottleneck intensifies, leading to massive power consumption, increased latency, and diminished returns on performance improvements. Training a large language model can consume megawatt-hours of electricity, making sustainability a critical concern. The biological brain offers a compelling alternative. It is an exquisitely optimized, highly parallel, and energy-efficient computing machine. Information processing and memory are not distinctly separated; instead, computation occurs in situ, within and between neurons, where synapses also store information (weights). This "in-memory computing" paradigm eliminates the memory wall. Furthermore, the brain operates in an event-driven, asynchronous manner, utilizing sparse "spikes" to communicate information only when necessary. Unlike the synchronous, clock-gated operations of conventional chips, neurons only activate and consume energy when there's relevant input, leading to immense power savings. This biological imperative has driven the development of Spiking Neural Networks (SNNs), the computational model for most neuromorphic hardware. SNNs diverge from Artificial Neural Networks (ANNs) by processing information as discrete temporal events (spikes) rather than continuous activation values. A neuron in an SNN integrates incoming spikes, and when its membrane potential crosses a threshold, it emits its own spike, propagating information to downstream neurons. This temporal aspect introduces a powerful new dimension for information encoding and processing, making SNNs particularly adept at handling dynamic, real-time data streams with high energy efficiency. Challenges in training SNNs persist, primarily due to the non-differentiable nature of spike events, necessitating advanced techniques like surrogate gradients for backpropagation or biologically inspired Hebbian learning rules such as Spike-Timing-Dependent Plasticity (STDP). These efforts are extensively documented on arXiv, showcasing a vibrant research landscape aimed at unlocking the full potential of SNNs. # Simple Python implementation of a Leaky Integrate-and-Fire (LIF) neuron model import numpy as npclass LIFNeuron: def __init__(self, tau_m=10.0, V_rest=-70.0, V_threshold=-55.0, R_m=1.0): """ Initializes a Leaky Integrate-and-Fire (LIF) neuron. :param tau_m: Membrane time constant (ms) :param V_rest: Resting membrane potential (mV) :param V_threshold: Spike threshold potential (mV) :param R_m: Membrane resistance (MOhms) """ self.tau_m = tau_m self.V_rest = V_rest self.V_threshold = V_threshold self.R_m = R_m self.V_m = V_rest # Current membrane potential self.spiked = False def update(self, I_input, dt=1.0): """ Updates the neuron's membrane potential over a time step dt. :param I_input: Input current (nA) :param dt: Time step (ms) :return: True if the neuron spiked, False otherwise """ dV_dt = (-(self.V_m - self.V_rest) + self.R_m * I_input) / self.tau_m self.V_m += dV_dt * dt self.spiked = False if self.V_m >= self.V_threshold: self.V_m = self.V_rest # Reset membrane potential after spiking self.spiked = True return self.spiked# Example usage: neuron = LIFNeuron() input_current = 20.0 # Constant input current time_steps = 50 spike_train = []print(f"Initial V_m: {neuron.V_m} mV") for t in range(time_steps): spiked = neuron.update(input_current) if spiked: spike_train.append(1) print(f"Time {t+1} ms: Neuron spiked! V_m reset to {neuron.V_m} mV") else: spike_train.append(0) # print(f"Time {t+1} ms: V_m = {neuron.V_m:.2f} mV")# print("\nSpike train:", spike_train)Architectural Innovations: From Wafer to Workload Neuromorphic hardware represents a radical departure from traditional chip design, embracing massive parallelism and in-memory computation. Key players like Intel with Loihi, IBM with TrueNorth, and BrainChip with Akida have pioneered distinct architectures, but share common foundational principles. Intel's Loihi research chip, for instance, integrates 128 "neuromorphic cores" on a single die, each containing 1024 spiking neurons and local memory. This local memory-processing unit eliminates the need for constant data transfers to external DRAM. The cores communicate asynchronously via an on-chip mesh network, only transmitting data (spikes) when events occur, drastically reducing power consumption. Loihi supports various SNN neuron models and learning rules like STDP directly in hardware. Intel's latest iteration, Loihi 2, fabricated on Intel 4 process technology, boasts faster speeds, higher neuron counts (over a million per chip), and expanded programmability with a 10x-100x improvement in neuron capacity and speed per chip compared to its predecessor. This advancement, detailed in recent arXiv preprints, pushes the envelope for real-time, low-power AI inference at the edge. IBM's TrueNorth, an earlier but significant effort, packs 4096 neurosynaptic cores, each with 256 neurons and 256x256 synapses. TrueNorth is highly optimized for fixed-function SNNs, excelling at tasks like pattern recognition with incredibly low power envelopes (tens of milliwatts). Its strength lies in its tiled architecture, allowing for immense scalability by tiling multiple chips together. BrainChip's Akida is another commercial offering, designed for ultra-low power edge AI. Akida IP cores are configurable, allowing for integration into various SoC designs. It supports event-domain neural processing, converting conventional ANNs into SNNs for efficient inference on-device, often outperforming traditional methods in energy efficiency for specific tasks like gesture recognition and keyword spotting. These architectures are not just about raw neuron counts; they integrate specialized hardware features:In-Memory Computing: Memory elements (often SRAM, but increasingly non-volatile memory like RRAM/memristors) are co-located with processing elements (neurons/synapses) to minimize data movement. Asynchronous Event-Driven Processing: Computation only occurs when a spike arrives, contrasting with the continuous clock cycles of traditional chips. Massively Parallel, Distributed Processing: Thousands to millions of neurons and billions of synapses operate concurrently across the chip. Programmable Synapses: Synaptic weights can be updated on-chip, enabling various learning rules and online adaptation.The manufacturing processes for these chips often involve custom ASIC designs, sometimes leveraging advanced nodes (like TSMC's processes for BrainChip) to maximize density and efficiency. The underlying technology explores beyond standard CMOS, integrating novel devices such as memristors for analog synaptic weight storage, which promises even greater density and energy efficiency for future generations. # Conceptual YAML for deploying a simple SNN model on a neuromorphic emulator # This example illustrates how one might configure a workload for a Loihi-like system # using a high-level abstraction layer or SDK.apiVersion: neuromorphic.ai/v1alpha1 kind: SNNApplication metadata: name: gesture-recognition-snn spec: modelName: "spiking-gesture-net-v1" modelConfig: neuronType: "LIF" synapseLearningRule: "STDP_Triphasic" numLayers: 5 layerTopology: [784, 256, 128, 64, 10] # Input, Hidden, Output neurons hardwareTarget: type: "Emulator" emulatorConfig: name: "nxsdk_simulator" # Intel Loihi's Python SDK simulator cores: 16 # Number of simulated neuromorphic cores timesteps: 1000 # Simulation duration in timesteps inputData: source: "live_sensor_stream" dataFormat: "spike_event_stream" # Data already pre-processed into spike events samplingRateHz: 100 outputConfig: destination: "mqtt_broker" topic: "neuromorphic/gestures" format: "json" includeConfidence: true deploymentStrategy: priority: "real-time" powerBudgetMw: 20 # Target power budget in milliwatts continuousLearning: enabled: true learningRate: 0.001 adaptiveThresholds: trueSpiking Neural Networks: The Language of the Brain-Inspired Spiking Neural Networks (SNNs) are the cornerstone of neuromorphic computing, moving beyond the static, continuous activations of traditional Artificial Neural Networks (ANNs) to a dynamic, event-driven paradigm. Unlike ANNs where neurons compute and pass continuous values (e.g., ReLU, Sigmoid outputs), SNN neurons communicate via discrete, asynchronous "spikes"—brief electrical pulses—much like biological neurons. This fundamental difference is key to their energy efficiency and ability to process temporal information inherently. The most common SNN neuron models include the Leaky Integrate-and-Fire (LIF) model, which we saw earlier, and its variations like the Izhikevich model, which can simulate a wider range of biological spiking patterns. In a LIF neuron, incoming spikes cause its membrane potential to rise. If this potential exceeds a threshold, the neuron fires a spike and its potential is reset. Otherwise, the potential "leaks" back towards a resting state over time, mimicking biological membrane dynamics. This temporal integration allows SNNs to process information encoded not just in the presence of spikes, but also in their timing, frequency, and relative order. Training SNNs has historically been a significant challenge. The non-differentiable nature of a spike (it’s either 0 or 1, with an abrupt jump) prevents direct application of gradient-based backpropagation. Researchers have developed several innovative approaches:Conversion from ANNs: Pre-trained ANNs can be converted into SNNs by carefully scaling weights and biases, often achieving competitive accuracy with significantly reduced power consumption during inference. This method is prevalent in commercial neuromorphic solutions like BrainChip's Akida. Spike-Timing-Dependent Plasticity (STDP): A biologically inspired unsupervised learning rule where the change in synaptic weight depends on the relative timing of pre- and post-synaptic spikes. If a pre-synaptic spike consistently precedes a post-synaptic spike, the connection strengthens; if it consistently follows, it weakens. Many neuromorphic chips implement hardware-accelerated STDP. Backpropagation Through Time (BPTT) with Surrogate Gradients: This technique adapts standard backpropagation for SNNs. When a spike event occurs, its non-differentiable step function is replaced by a "surrogate" smooth function (e.g., sigmoid or arc-tangent approximation) during the backward pass, allowing gradients to propagate. Frameworks like snnTorch and Nengo heavily utilize this. Event-based Backpropagation: More recent methods aim to directly calculate gradients based on the timing of events, often leveraging adjoint methods or specialized event-driven optimizers.The software ecosystem for SNNs is rapidly maturing. Frameworks like snnTorch (built on PyTorch) provide a comprehensive environment for designing, training, and deploying SNNs, offering various neuron models, learning rules, and utility functions. Nengo (from Applied Brain Research) is a popular open-source framework for building large-scale SNNs and cognitive models, often targeting neuromorphic hardware like Loihi or their own custom chips. Brian2 is another powerful simulator, particularly favored by computational neuroscientists for detailed biological SNN modeling. These tools are crucial for bridging the gap between theoretical SNN advancements and practical applications on neuromorphic hardware, addressing the steep learning curve for developers accustomed to traditional ANNs. # Python code using snnTorch to define a simple spiking neuron layer import torch import torch.nn as nn import snntorch as snn from snntorch import surrogate# Define a simple SNN layer using snnTorch class SimpleSNN(nn.Module): def __init__(self, num_inputs, num_outputs, beta=0.9, threshold=1.0): super().__init__() # Linear layer mapping input to hidden dimensions self.fc = nn.Linear(num_inputs, num_outputs) # Leaky Integrate-and-Fire (LIF) neuron layer # beta: decay rate of membrane potential # threshold: voltage threshold for spiking # spike_grad: surrogate gradient function for backprop self.lif = snn.Leaky(beta=beta, threshold=threshold, spike_grad=surrogate.fast_sigmoid()) def forward(self, x): # Initialize membrane potential for the LIF neuron mem = self.lif.init_leaky() # Iterate over time steps (this is crucial for SNNs) spikes_output = [] for step in range(x.size(0)): # Assuming x is [time_steps, batch_size, features] cur_input = self.fc(x[step]) spike, mem = self.lif(cur_input, mem) spikes_output.append(spike) return torch.stack(spikes_output, dim=0)# Example Usage: # Define input data (e.g., a time-series of spike events) num_time_steps = 25 batch_size = 4 input_features = 10 output_features = 2# Create dummy input data (e.g., random spikes over time) input_data = torch.rand(num_time_steps, batch_size, input_features) > 0.8 input_data = input_data.float() # Convert to float for linear layer# Initialize the SNN model snn_model = SimpleSNN(input_features, output_features)# Forward pass output_spikes = snn_model(input_data)print(f"Input data shape: {input_data.shape}") # [time_steps, batch_size, input_features] print(f"Output spikes shape: {output_spikes.shape}") # [time_steps, batch_size, output_features] print(f"Total spikes in output (example for one batch item): {output_spikes[:, 0, :].sum()}")Applications and Edge AI Revolution Neuromorphic computing is not a general-purpose replacement for CPUs or GPUs, but rather a specialized accelerator poised to revolutionize specific domains, particularly Edge AI. Its inherent advantages—ultra-low power consumption, real-time event-driven processing, and continuous learning capabilities—make it ideal for intelligent systems operating at the periphery of networks, where energy budgets are tight and immediate decision-making is critical. Consider the pervasive landscape of the Internet of Things (IoT). Billions of sensors are deployed in diverse environments, from smart homes to industrial factories. Traditional AI inference on these devices often requires data to be sent to the cloud, incurring latency, bandwidth costs, and privacy concerns. Neuromorphic chips, operating at milliwatt power levels, can enable always-on, real-time inference directly on the sensor. Use cases include:Always-on Keyword Spotting/Voice Activity Detection: Devices can continuously listen for trigger phrases or human presence without draining batteries, as demonstrated by BrainChip's Akida in various benchmark tests. Gesture Recognition and Human-Machine Interaction: Low-power processing of camera or radar sensor data for intuitive, touch-free interfaces in consumer electronics, automotive interiors, or industrial settings. Predictive Maintenance in Industrial IoT: Real-time anomaly detection from sensor data (vibration, temperature, acoustic) on factory floors, identifying potential equipment failures before they occur, all with local processing. Autonomous Systems (Robotics, Drones, Self-Driving Cars): Neuromorphic processors can provide rapid, low-power processing for perception, navigation, and control, especially for event-based vision sensors (e.g., dynamic vision sensors, DVS cameras) which naturally output spike trains. Their ability to process information sparsely and asynchronously is a perfect match for dynamic environments. Biomedical Signal Processing: Real-time analysis of EEG, ECG, or EMG signals for medical diagnostics, wearable health monitoring, or brain-computer interfaces, where immediate feedback is crucial and power efficiency paramount.The energy efficiency gains are staggering. For specific SNN-optimized tasks, neuromorphic chips can achieve hundreds to thousands of times better energy efficiency (operations per Joule) compared to traditional CPUs or GPUs. For instance, Intel's Loihi has shown orders of magnitude power reduction for tasks like real-time gesture recognition and object classification with event-based sensors, outperforming conventional embedded processors. This translates directly to longer battery life for mobile and IoT devices, smaller form factors, and reduced operational costs for large-scale sensor networks. The "learning on the edge" capability, driven by hardware-accelerated STDP, also means that devices can continuously adapt and improve their performance in the field, without needing to offload data for retraining or complex model updates, a capability largely absent in traditional edge AI deployments. # Conceptual Bash commands for setting up a simulated neuromorphic environment # and deploying a simple SNN model for edge inference. # This assumes a pre-compiled SNN model and a neuromorphic runtime.# 1. Prepare a Docker image for the neuromorphic runtime (e.g., for an ARM-based edge device) # Dockerfile content might include snnTorch, Nengo, or Intel's NxSDK/Lava for Loihi emulation. # For simplicity, let's assume a pre-built image. echo "Building neuromorphic inference Docker image..." docker build -t neuromorphic-edge-runtime:1.0 . # (assuming Dockerfile is in current dir) # Example Dockerfile might look like: # FROM python:3.9-slim-buster # WORKDIR /app # COPY requirements.txt . # RUN pip install -r requirements.txt # COPY inference_script.py . # COPY s_gesture_model.npy . # Pre-trained SNN model # CMD ["python", "inference_script.py"]# 2. Deploy the container to a simulated edge device or a real one (e.g., Raspberry Pi with accelerator) echo "Deploying SNN model to edge device (simulated/actual)..." # Assuming the model expects a live stream of event data, e.g., from a DVS camera or sensor. # Mount necessary sensor data or configuration files. docker run -d --name edge-snn-inference \ --network host \ -v /dev/sensor_input:/dev/sensor_input \ -v /path/to/config:/app/config \ neuromorphic-edge-runtime:1.0 \ python /app/inference_script.py --model /app/s_gesture_model.npy --sensor-id /dev/sensor_inputecho "SNN inference service deployed. Monitoring logs..." docker logs -f edge-snn-inference # Expected output from inference_script.py might be detected gestures or anomalies.# 3. Example of stopping and cleaning up # docker stop edge-snn-inference # docker rm edge-snn-inference # docker rmi neuromorphic-edge-runtime:1.0The Road Ahead: Challenges and Breakthroughs Despite the extraordinary promise, neuromorphic computing is still a nascent field facing significant hurdles on its path to mainstream adoption. The "neuromorphic gap" refers to the chasm between biologically inspired principles and the practical engineering of robust, programmable, and scalable systems. One of the primary challenges lies in the software ecosystem and programming models. Developing applications for neuromorphic hardware is inherently different from traditional programming. It requires a paradigm shift from sequential instructions to event-driven, parallel computation. While frameworks like Intel's Lava SDK (for Loihi) and Nengo are making strides, there's a definite lack of mature, high-level abstractions, compilers, and debugging tools comparable to the vast ecosystems available for CPUs and GPUs (e.g., CUDA, TensorFlow, PyTorch). Training methodologies for SNNs, while improving with surrogate gradients and conversion techniques, still lag behind the robustness and generality of backpropagation for ANNs. Achieving state-of-the-art accuracy on complex, large-scale benchmarks with SNNs remains an active research area. Scalability and generality are also key concerns. While current neuromorphic chips excel at specific, low-power edge tasks, scaling them to compete with GPU clusters for training massive foundation models or running complex, diverse workloads is still a distant goal. The specialized nature of neuromorphic architectures means they are not a universal compute solution but rather specialized accelerators. Research into hybrid architectures – combining neuromorphic elements with traditional processors – is emerging as a practical path forward, allowing workloads to be intelligently partitioned for optimal performance and energy efficiency. Another frontier is novel device physics and materials science. While current chips primarily use CMOS technology, the ultimate vision for neuromorphic computing often involves non-von Neumann devices like memristors, phase-change memory (PCM), or resistive random-access memory (RRAM) for more efficient, dense, and analog synaptic weight storage and in-memory computation. These technologies promise even greater power efficiency and synapse density but come with their own manufacturing and reliability challenges. Optical neuromorphic computing, leveraging light to perform computations, is also an exciting, albeit early-stage, research direction, offering potential for ultra-high speeds and low power consumption. Significant investment from governments (e.g., DARPA, European Commission's Human Brain Project) and tech giants (IBM, Intel) continues to fuel research. Startups like SynSense and GrAI Matter Labs are pushing commercial applications, demonstrating traction in specific edge AI markets. The path forward involves continued interdisciplinary collaboration between neuroscientists, material scientists, computer architects, and software engineers to bridge these gaps. As the field matures, we can anticipate more standardized toolchains, improved programmability, and a clearer understanding of the optimal applications where neuromorphic computing truly shines, leading to transformative breakthroughs in AI capabilities at the very edge of our interconnected world. # Python example illustrating a simplified Spike-Timing-Dependent Plasticity (STDP) rule # This demonstrates a fundamental unsupervised learning mechanism in SNNsclass Synapse: def __init__(self, weight=0.5, learning_rate_plus=0.01, learning_rate_minus=0.01): self.weight = weight self.last_pre_spike = -np.inf # Time of last presynaptic spike self.last_post_spike = -np.inf # Time of last postsynaptic spike self.lr_plus = learning_rate_plus self.lr_minus = learning_rate_minus self.tau = 20.0 # Time constant for STDP window (ms) def update_weight(self, pre_spike_time, post_spike_time): """ Updates the synaptic weight based on STDP rule. :param pre_spike_time: Time of the current presynaptic spike :param post_spike_time: Time of the current postsynaptic spike """ # Only update if both pre- and post-synaptic spikes have occurred if pre_spike_time is not None and post_spike_time is not None: delta_t = post_spike_time - pre_spike_time if delta_t > 0: # Post-synaptic spike after pre-synaptic: Potentiation delta_w = self.lr_plus * np.exp(-delta_t / self.tau) self.weight += delta_w elif delta_t < 0: # Post-synaptic spike before pre-synaptic: Depression delta_w = self.lr_minus * np.exp(delta_t / self.tau) self.weight -= delta_w # Ensure weight stays within reasonable bounds self.weight = np.clip(self.weight, 0.0, 1.0) # Example bounds# Simulate a simple scenario with two neurons and one synapse synapse = Synapse(weight=0.5)# Scenario 1: Pre-synaptic spike before post-synaptic (Potentiation) pre_spike_t1 = 10 post_spike_t1 = 15 # Post happens 5ms after pre synapse.update_weight(pre_spike_t1, post_spike_t1) print(f"Scenario 1 (Potentiation, delta_t={post_spike_t1 - pre_spike_t1}ms): New weight = {synapse.weight:.4f}")# Scenario 2: Pre-synaptic spike after post-synaptic (Depression) synapse = Synapse(weight=0.5) # Reset for new scenario pre_spike_t2 = 20 post_spike_t2 = 18 # Post happens 2ms before pre synapse.update_weight(pre_spike_t2, post_spike_t2) print(f"Scenario 2 (Depression, delta_t={post_spike_t2 - pre_spike_t2}ms): New weight = {synapse.weight:.4f}")# Scenario 3: No significant spike timing difference, small change (or no change if delta_t=0) synapse = Synapse(weight=0.5) pre_spike_t3 = 30 post_spike_t3 = 30 synapse.update_weight(pre_spike_t3, post_spike_t3) # delta_t = 0, no change with this simple model print(f"Scenario 3 (No change): New weight = {synapse.weight:.4f}")Comparative Overview of Leading Neuromorphic ProcessorsFeature / Processor Intel Loihi (Loihi 2) IBM TrueNorth BrainChip AkidaArchitecture Event-driven, asynchronous spiking neural network processor with on-chip learning. Multi-core. Fixed-point, highly parallel tiled neurosynaptic core array. Event-domain neural processor, IP core for SoC integration.Key Processing Model Spiking Neural Networks (SNNs) with programmable neuron models (e.g., LIF, Izhikevich) and learning rules (STDP). Spiking Neural Networks (SNNs) with 4 neuron models and 16 synapse types. Converts ANNs to SNNs for inference; supports CNNs, RNNs, fully connected layers.Neuron Count (per chip) Up to 1 million (Loihi 2) 1 million (approx.) ~1.2 million (Akida 1.0)Synapse Count (per chip) 128 million (Loihi 2) 256 million (approx.) ~10 million (Akida 1.0)Typical Power Consumption <100 mW (inference) ~20-70 mW (inference) ~100 µW - 10 mW (inference)Key Strengths Research platform, on-chip learning, flexible SNN models, real-time control, sensor fusion. Extreme power efficiency, high density, proven for pattern recognition. Ultra-low power edge inference, IP core flexibility, ease of ANN-to-SNN conversion.Programming Model NxSDK (Python-based), Lava SDK (open-source framework) Corelet programming model, proprietary SDK. Akida SDK (Python/C++), integrates with TensorFlow, Keras.Use Cases Robotics, autonomous systems, continuous learning, pattern recognition, constraint satisfaction. Real-time sensor analytics, surveillance, embedded vision. Always-on IoT, medical devices, automotive, smart home, industrial control.Availability Academic/Research access (Intel Neuromorphic Research Community) Research platform, limited commercial access. Commercial IP, evaluation kits available.Fabrication Intel 4 (Loihi 2) Samsung 28nm TSMC 28nmLearning Support On-chip unsupervised (STDP), supervised through host. Limited on-chip learning, primarily fixed inference. On-device incremental learning and few-shot learning.This table provides a snapshot of the distinct approaches and capabilities offered by some of the most prominent neuromorphic processors, highlighting their specialized design for energy-efficient, event-driven AI tasks. Each processor targets slightly different niches, showcasing the diverse potential of brain-inspired computing. Conclusion Neuromorphic computing represents one of the most exciting and critical frontiers in the evolution of Artificial Intelligence. As the demands on AI models continue to skyrocket, pushing conventional hardware to its absolute limits in terms of power consumption and efficiency, the brain's elegant solution to parallel, in-memory, event-driven computation offers not just inspiration, but a direct pathway forward. We are moving beyond the era where simply throwing more compute at a problem guarantees progress. The future of AI demands smarter, more sustainable hardware. The advancements in Intel Loihi, IBM TrueNorth, BrainChip Akida, and the rapidly maturing SNN software ecosystem like snnTorch and Nengo, illustrate a clear trajectory towards practical, deployable neuromorphic solutions. While significant challenges remain in bridging the "neuromorphic gap" – from developing truly general-purpose programming models to scaling for ever-larger tasks and integrating novel materials – the momentum is undeniable. These brain-inspired chips are not poised to replace general-purpose CPUs and GPUs, but rather to complement them, unleashing unparalleled energy efficiency and real-time intelligence at the edge, in robotics, autonomous systems, and pervasive IoT. The dawn of truly intelligent machines, capable of learning and adapting with a fraction of the energy budget of today's systems, is no longer a distant dream. It is an engineering reality being built, silicon by spike, in labs and fabs across the globe. The ultimate gambit against AI's energy crisis is underway, and it is profoundly brain-inspired. Kaan Demir#NeuromorphicComputing #AIHardware #SpikingNeuralNetworks #EdgeAI #BrainInspiredAI#AI #NeuromorphicComputing #EnergyCrisis #TechInnovation #FutureOfAI Related InsightsReal-Time Analytics with Apache Flink and Kafka: Powering Instant Insights The Digital Scalpel: Architecting High-Fidelity Haptic Feedback in Robotic Surgery Simulation The Architecture of Trust: Deconstructing the Post-Cookie Web3 Paradigm{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Beyond Silicon: Why Neuromorphic Computing Is The Brain's Ultimate Gambit Against AI's Energy Crisis?", "acceptedAnswer": { "@type": "Answer", "text": "Explore neuromorphic computing, a revolutionary paradigm leveraging brain-inspired hardware to overcome AI's energy and performance bottlenecks, paving the way for truly efficient edge intelligence." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Beyond Silicon: Why Neuromorphic Computing Is The Brain's Ultimate Gambit Against AI's Energy Crisis?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Kaan Demir." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Isabella Rossi
- 12 Jul, 2026 13:39
Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse
For millennia, human ingenuity has explored countless methods of transforming raw ingredients into exquisite culinary experiences. Yet, few traditions rival the elegant simplicity and profound impact of Peruvian Ceviche. This isn't just a dish; it's a testament to the transformative power of nature's simplest elements – fresh seafood and the vibrant kiss of citrus. From the bustling streets of Lima to the most exclusive fine-dining establishments across the globe, Ceviche reigns supreme, celebrated for its electrifying freshness, complex flavors, and surprising nutritional prowess. Often perceived as a mere assembly of raw fish and lime, the truth of authentic Peruvian Ceviche is far more intricate, a delicate dance of chemistry, history, and culinary artistry. It's an ancient technique elevated to an art form, where the acidic potency of citrus "cooks" the fish, firming its flesh and infusing it with an unparalleled zest that awakens every palate. Beyond its refreshing taste, Ceviche is a nutritional powerhouse, packed with lean protein, essential vitamins, and invigorating compounds that offer a myriad of health benefits. In this definitive guide, we will embark on a journey to uncover the multifaceted world of Peruvian Ceviche. We’ll delve into its fascinating origins, tracing its evolution from pre-Columbian rituals to a global gastronomic phenomenon. We'll meticulously explore the scientific principles underpinning the citrus curing process, demystifying how acid transforms texture and flavor. From the sacred "leche de tigre" – the soul of Ceviche – to the meticulous selection of pristine seafood and the art of perfect presentation, prepare to unlock the secrets of this iconic dish. Join me as we celebrate the alchemy of Peruvian Ceviche, an experience that transcends mere dining and becomes a vibrant celebration of culture, flavor, and well-being. The Historical Tapestry: Tracing Ceviche's Ancient Roots The story of Ceviche is as rich and layered as the dish itself, a culinary narrative deeply woven into the fabric of Peruvian history. Its origins stretch back over two millennia, predating the arrival of the Spanish conquistadors, evolving through the hands of various indigenous cultures along Peru's extensive coastline. Archaeological evidence points to the Moche civilization, flourishing between 100 and 700 AD, as one of the earliest practitioners of a form of "curing" fish. They are believed to have used the fermented juice of tullu (a type of banana passionfruit) or chicha (fermented corn beer) to macerate fish, a rudimentary but effective method of preservation and tenderization in the absence of refrigeration. With the rise of the Inca Empire, the practice continued, albeit with variations. While chicha remained a common acidic agent, the Incas also incorporated the vibrant heat of rocoto peppers and other native spices to season their preparations. This early iteration of "fish-curing" wasn't just about food preparation; it often held ceremonial significance, tying communities to the bounty of the Pacific Ocean. The arrival of the Spanish in the 16th century marked a pivotal moment in Ceviche’s evolution. They introduced new ingredients that would become indispensable: limes and onions. The high acidity of the lime proved to be a superior and more accessible curing agent than the traditionally used fermented fruit juices, significantly refining the dish's flavor profile and accelerating the "cooking" process. The Spanish influence, combined with indigenous ingredients, began to shape Ceviche into a form more recognizable today. Later, in the 19th and 20th centuries, waves of Japanese immigrants arrived in Peru, bringing with them their unparalleled expertise in handling raw fish and precision knife skills. This cultural fusion gave birth to Nikkei cuisine, a unique blend of Japanese techniques and Peruvian ingredients, profoundly impacting Ceviche. The Japanese emphasis on using extremely fresh, sashimi-grade fish and minimizing marination time – often just minutes – contributed to the modern preference for a lighter, more delicate Ceviche, preserving the fish's natural texture and flavor. This shorter curing time, a departure from earlier prolonged macerations, reflects a contemporary understanding of freshness and texture. Today, Ceviche is not merely a national dish but a powerful symbol of Peruvian identity, celebrated annually on June 28th as National Ceviche Day. It’s a dynamic dish, constantly evolving while staying true to its ancient roots, a testament to Peru's rich multicultural heritage and culinary innovation.The Science of "Cooking" with Citrus: Denaturation and Flavor At the heart of Peruvian Ceviche lies a fascinating biochemical process often referred to as "cooking without heat": protein denaturation. When fresh, raw fish comes into contact with the highly acidic juice of citrus fruits, primarily lime (Citrus × aurantiifolia), a profound transformation begins. The acidity, measured by a low pH, causes the proteins in the fish muscle to unravel and re-bond in a new configuration. This process, denaturation, structurally alters the proteins, leading to a change in the fish's appearance, texture, and flavor. Normally, the translucent proteins in raw fish are tightly coiled. As the citric acid penetrates the fish flesh, the hydrogen ions (H+) in the acid interact with the protein molecules. This disrupts the weak bonds that maintain the protein's native three-dimensional structure. As these bonds break, the proteins unfold and tangle with each other, similar to how heat causes proteins to coagulate and turn opaque. This is why raw fish, typically translucent or pearly, becomes opaque and firm, taking on the appearance of being cooked. The optimal pH for this denaturation in fish protein typically falls below 4.5, with lime juice naturally sitting around a pH of 2-2.5, making it an ideal agent. While this acid-induced change mimics cooking in terms of texture and appearance, it's crucial to understand that it does not provide the same microbial safety as heat cooking. Acid can inhibit the growth of some bacteria, but it doesn't kill all pathogens, emphasizing the paramount importance of using only the freshest, highest-quality, sashimi-grade fish. Beyond the visible transformation, citrus acid plays a crucial role in developing Ceviche’s complex flavor profile. The acidity not only "cooks" but also brightens and enhances the natural flavors of the seafood, cutting through any potential "fishiness" and leaving a clean, refreshing taste. The lime juice contributes its own aromatic compounds, including terpenes and esters, which impart characteristic floral and zesty notes. Furthermore, the acid aids in breaking down some of the connective tissues in the fish, contributing to a tender yet firm texture. The interaction of citric acid with other ingredients in leche de tigre (tiger's milk), such as garlic, onion, and aji peppers, creates a synergistic flavor explosion. The alliums (garlic and onion) contain sulfur compounds that can react with acids and other flavor molecules, producing new, often pungent and aromatic, compounds. The capsaicinoids from aji peppers add a pleasant heat that balances the acidity, while cilantro introduces fresh, herbaceous notes. The rapid, superficial "cooking" ensures that the delicate inherent flavor of the fish remains prominent, a testament to the scientific artistry embedded in every vibrant bite of Peruvian Ceviche. Crafting the Perfect Leche de Tigre: The Soul of Ceviche If Ceviche is the body, then leche de tigre – or "tiger's milk" – is its vibrant soul, the potent, flavorful marinade that defines the dish. More than just a simple lime juice dressing, leche de tigre is a meticulously crafted elixir, a harmonious blend of acidic, savory, spicy, and aromatic elements that not only cures the fish but also serves as a invigorating drink in its own right. Its name is said to derive from its milky-white appearance and its legendary reputation as an aphrodisiac and hangover cure, believed to restore strength and vitality. The foundational ingredient of any authentic leche de tigre is freshly squeezed, key lime juice. Peruvian limes are often smaller, more acidic, and possess a distinct aroma compared to common Persian limes, making them ideal. Beyond the citrus, the magic happens with the addition of finely minced aji limo or rocoto peppers – crucial for their clean heat and fruity notes – along with thinly sliced red onion, garlic, and fresh cilantro stems. Crucially, the "milk" in tiger's milk often comes from incorporating a small amount of the fish itself (scraps from preparing the fillets, or a small piece of the cured fish), blended with ice, creating an emulsion that adds body, umami, and a silky texture. Some variations may include a touch of fish broth or even clam juice to deepen the seafood essence. Here’s a simplified step-by-step guide to crafting a classic leche de tigre:Prepare Aromatics: Finely mince 1-2 cloves of garlic, a 1-inch piece of aji limo (seeds removed for less heat, or left in for a fiery kick), and a small amount of cilantro stems. Thinly slice about ¼ of a red onion. Extract Lime Juice: Squeeze juice from 8-10 fresh key limes. Ensure no seeds or pulp are present. Combine & Marinate (Initial): In a bowl, combine the lime juice, minced garlic, aji limo, and cilantro stems. Add a small piece of fresh fish (about 1 ounce) and a couple of ice cubes. The ice helps keep the mixture cold and prevents over-maceration of the fish in the broth. Blend (Optional but Recommended): For a creamier, more emulsified leche de tigre, transfer about half of this mixture (including the fish piece) to a blender. Pulse briefly until the fish is incorporated and the mixture is slightly opaque. This step extracts maximum flavor from the fish and aromatics. Strain & Adjust: Strain the blended mixture back into the remaining lime juice base through a fine-mesh sieve, pressing down on the solids to extract all liquid. Discard the solids. Taste and adjust seasoning with salt. Some chefs add a tiny splash of fish sauce or MSG for an umami boost, but traditionalists rely on the fresh ingredients. Chill: Chill the leche de tigre thoroughly before use. Its potency and refreshing qualities are best enjoyed when icy cold.Variations abound: a "leche de tigre con crema" might incorporate evaporated milk for a richer, smoother mouthfeel, while versions with conchas negras (black scallops) are often heralded for their dark, briny, and intensely aphrodisiac qualities. Regardless of the variation, leche de tigre is the beating heart of Ceviche, transforming simple ingredients into an unforgettable symphony of flavors.Sourcing the Stars: Selecting the Freshest Seafood and Accompaniments The undeniable truth about exceptional Ceviche is that it can only ever be as good as its ingredients, and at the zenith of this hierarchy is the seafood itself. Given that Ceviche is a dish where fish is "cooked" by acid rather than heat, the absolute freshness and quality of the seafood are not merely preferences but critical imperatives for both flavor and food safety. Using anything less than pristine, sashimi-grade fish risks compromising the entire experience and potentially health. When selecting fish for Ceviche, the goal is firm, white-fleshed, mild-flavored fish that will hold its structure during the curing process. Traditional Peruvian choices include corvina (sea bass), lenguado (flounder), perico (mahi-mahi), and tilapia. However, high-quality snapper, cod, halibut, or even scallops can yield excellent results. When purchasing, look for these tell-tale signs of freshness:Eyes: Clear, bright, and bulging, not sunken or cloudy. Gills: Bright red or pink, not brown or slimy. Skin: Shiny, moist, and free from discolored spots. Flesh: Firm and elastic to the touch; if you press it, it should spring back immediately. Avoid fish that feels mushy or leaves an indentation. Smell: It should smell like the ocean, clean and briny, never "fishy" or ammonia-like. Source: Ideally, buy from a reputable fishmonger who can confirm the fish was caught recently and handled properly. Inquire about sustainability practices where possible; understanding where your seafood comes from is increasingly vital.Once acquired, proper handling is paramount. Keep the fish well-chilled, ideally on ice, until immediately before preparation. Cut the fish into uniform, bite-sized cubes, typically ¾-inch to 1-inch, ensuring consistency for even curing. Avoid overly thin slices, which can become rubbery, or overly large chunks, which may not cure adequately. The supporting cast in a Peruvian Ceviche is equally vital, providing balance, texture, and additional layers of flavor:Camote (Sweet Potato): Boiled and sliced, its natural sweetness provides a crucial counterpoint to the intense acidity of the leche de tigre, harmonizing the palate. Choclo (Giant Peruvian Corn): Large-kerneled, starchy, and subtly sweet, choclo offers a satisfying chew and grounding earthiness. Cancha Serrana (Toasted Corn Kernels): These crunchy, salty kernels provide a delightful textural contrast, adding a rustic element to each bite. Red Onion: Thinly sliced and often briefly rinsed in cold water to temper its pungency, red onion adds a sharp, piquant crunch and a beautiful visual pop. Aji Limo/Rocoto: Essential for their specific heat and fruity aroma. While their heat level can vary, their flavor is distinct from other chiles. Cilantro: Freshly chopped, it provides a burst of herbaceous freshness and a vibrant green garnish.Each component is meticulously chosen to contribute to the overall symphony, ensuring that every spoonful of Peruvian Ceviche is a complete culinary experience, a testament to the country's rich biodiversity and culinary wisdom.👉 Continue Reading: Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse (Part 2)#Ceviche #PeruvianFood #HealthyEating #Seafood #CitrusMagic #FoodHistory Related InsightsBaba Ghanoush: The Smoky Eggplant Dip The Ultimate Guide to Spanish Tapas: Recipes and Regional Variations Exploring the Antioxidant-Rich Delights of Borscht with Kefir and Dill{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse?", "acceptedAnswer": { "@type": "Answer", "text": "Dive deep into the rich history, scientific principles, and unparalleled flavors of authentic Peruvian Ceviche, a culinary masterpiece crafted by the magic of citrus." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Isabella Rossi." } }, { "@type": "Question", "name": "Where can I find more related content about Food?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Food category page." } } ] }
- Isabella Rossi
- 12 Jul, 2026 13:39
Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse (Part 2)
This is Part 2 of the series. Read Part 1 here.Mastering the Assembly: From Marination to Presentation The final act of crafting Peruvian Ceviche is its assembly, a critical stage where timing and technique converge to transform individual ingredients into a cohesive, sensory masterpiece. Unlike many marinating processes, Ceviche demands swiftness and precision; the aim is not to "overcook" the fish in acid but to achieve a delicate balance of firm texture and vibrant flavor. The golden rule of marination time is a hotly debated topic among chefs, yet a consensus generally leans towards brevity. For truly fresh, sashimi-grade fish, a marination time of anywhere from one to five minutes is often considered ideal for a "flash-cured" style. This allows the exterior of the fish to firm up and absorb the leche de tigre’s intense flavors, while the interior retains a delicate tenderness. Longer marination times, historically more common, can result in a tougher, rubbery texture as the acid penetrates deeper and denatures more protein. However, some traditionalists still prefer a slightly longer soak (up to 10-15 minutes) for a more thoroughly "cooked" fish. The key is to observe the fish: once it turns opaque and firm, it’s ready. Assembly Steps:Chilled Ingredients: Ensure all components – the diced fish, leche de tigre, and accompaniments – are thoroughly chilled. Temperature is crucial for the dish's refreshing character. Combine Fish and Leche de Tigre: In a non-reactive bowl (glass or ceramic), gently combine the diced fish with a generous amount of the prepared leche de tigre. Stir gently to ensure every piece of fish is coated. Add Aromatics: Immediately add a portion of the thinly sliced red onion and minced aji limo or rocoto. The interaction of these with the leche de tigre and fish is instantaneous. Marinate Briefly: Let the mixture sit for the desired time (1-5 minutes for modern style, up to 10-15 for more traditional texture), stirring once or twice. Taste and Adjust: Taste a piece of fish. Adjust salt if necessary. The balance of acidity, salt, and spice is paramount. Plating: This is where the artistry shines. Use a chilled, shallow bowl or plate. First, place a slice or two of boiled sweet potato (camote) at the bottom or side of the plate. Next, artfully spoon the cured fish and its leche de tigre over and around the sweet potato. Garnish generously with fresh choclo kernels, a sprinkle of crunchy cancha serrana, and a flourish of chopped fresh cilantro. A fresh slice of aji limo on top adds a vibrant pop of color and promises a hint of heat.Serve Immediately: Ceviche is a dish that must be consumed immediately after assembly to appreciate its peak freshness, texture, and flavor. Delays allow the acid to continue "cooking" the fish, leading to an undesirable texture.Regional variations and modern interpretations abound. Tiradito, a cousin to Ceviche, features fish sliced sashimi-style and bathed in an aji amarillo-infused leche de tigre without onions, showcasing the Japanese influence on Peruvian cuisine. Other modern chefs experiment with different citrus, exotic fruits, or even incorporate elements like passion fruit or smoked paprika. Regardless of the twist, the core principle of fresh fish, potent citrus, and vibrant accompaniments remains the immutable heart of mastering Peruvian Ceviche.Nutritional Profile of Traditional Peruvian Ceviche (per 150g serving) Peruvian Ceviche is not only a culinary delight but also a remarkably healthy dish, offering a rich array of nutrients with relatively low calories. Its primary ingredient, fresh white fish, is an excellent source of lean protein, while the vibrant accompaniments contribute essential vitamins, minerals, and dietary fiber. This table outlines the estimated nutritional breakdown for a typical 150g serving of traditional Peruvian Ceviche (excluding additional fats from oils or excessive fried accompaniments), providing a clear picture of its benefits.Nutrient Category Nutrient/Component Estimated Value (per 150g serving) % Daily Value (based on 2000 kcal diet) Key Health BenefitsThe Culinary Masterpiece: Exploring Peruvian Ceviche's Timeless Allure Introduction: Where Tradition Meets Gastronomic Ingenuity Peru, a nation with unparalleled culinary heritage, has gifted the world a jewel that embodies freshness, intricate balance, and a burst of flavor: Ceviche. More than just a dish, Ceviche is an integral part of Peruvian identity, a symbol of its abundant coastal bounty, and a vibrant celebration of culture. From the Pacific Ocean's depths, raw, pristine seafood is transformed through a dazzling alchemy involving one of nature's most potent acids – citrus. This "cooking" process, devoid of heat yet profound in its effect, results in a dish whose texture is firm yet tender, and whose taste is exhilaratingly vibrant, resonating with notes of the ocean, the earth, and the sun. The global ascent of Peruvian cuisine over the past two decades has placed Ceviche firmly on the world's gastronomic map. But beneath its international acclaim lies a story steeped in ancient tradition, scientific marvel, and a passionate dedication to the freshest ingredients. This is a dish whose evolution spans millennia, from pre-Columbian rituals to the sophisticated culinary techniques of today, each era adding a layer to its complexity and allure. It's a testament to how simple elements, when expertly combined, can transcend their individual identities to create something truly extraordinary. Join me, Isabella Rossi, as we embark on a comprehensive exploration of this iconic Peruvian delicacy. We will peel back the layers of history to understand its ancient roots, decipher the fascinating science behind its citrus-induced transformation, and meticulously break down the essential components that make a truly authentic Ceviche. From the mystical "Leche de Tigre" – the vital essence that binds the dish – to the art of selecting impeccably fresh seafood and mastering its presentation, this article will serve as your ultimate guide. Prepare to immerse yourself in the world of Peruvian Ceviche, understanding not just how to make it, but the profound cultural and scientific narratives that elevate it beyond mere food, into a profound culinary experience. The Historical Tapestry: Tracing Ceviche's Ancient Roots The captivating history of Ceviche stretches far beyond colonial influences, embedding itself deeply within the rich tapestry of pre-Columbian civilizations along Peru’s sprawling Pacific coastline. Archaeological findings provide compelling evidence of the Moche civilization, flourishing between 100 AD and 700 AD in what is now northern Peru, engaging in practices akin to early forms of Ceviche. These ancient people, renowned for their sophisticated agricultural and fishing techniques, utilized the fermented juice of tullu (banana passionfruit) or chicha, a traditional fermented corn beverage, to macerate and tenderize freshly caught fish. This method served not only as a rudimentary form of preservation in the absence of refrigeration but also as a means of enhancing flavor and making raw proteins more palatable. As the Inca Empire rose to prominence, integrating diverse regional practices, the tradition of "curing" fish continued to evolve. While chicha remained a common acidic agent, the Incas began to incorporate native spices, most notably the rocoto pepper, a vibrant and spicy capsicum indigenous to the Andes, adding a distinctive heat and aromatic complexity to their preparations. This early iteration, known as tupus, wasn't just sustenance; it often held significant cultural and ceremonial importance, connecting coastal communities to the abundant resources of the Pacific. The pivotal transformation of Ceviche arrived with the Spanish conquest in the 16th century. European colonizers introduced two cornerstone ingredients that would forever alter the dish’s trajectory: limes (Citrus × aurantiifolia) and red onions. The potent acidity of the lime juice, with its characteristic pH of 2.0-2.5, proved to be a far more effective and faster-acting denaturing agent than the indigenous fermented fruit juices, significantly refining the dish’s flavor profile and accelerating the "cooking" process. The interplay of native Peruvian ingredients with these new additions began to forge Ceviche into a form more recognizable to contemporary palates. Further waves of immigration, particularly from Japan in the late 19th and early 20th centuries, introduced yet another profound layer to Ceviche's evolution. Japanese immigrants, with their unparalleled expertise in handling raw fish for dishes like sashimi and sushi, brought with them a philosophy of culinary precision and an emphasis on using impeccably fresh, high-grade seafood. This cultural fusion gave birth to Nikkei cuisine, a unique blend of Japanese techniques and Peruvian ingredients, which refined Ceviche by introducing rapid, often minutes-long, marination times. This approach, a departure from earlier, longer macerations, highlighted the fish's natural freshness and delicate texture, shaping the modern preference for a lighter, more vibrant Ceviche. Today, Ceviche transcends its status as a mere dish; it is a powerful emblem of Peruvian cultural identity, celebrated annually on June 28th as National Ceviche Day, reflecting its dynamic evolution through centuries of culinary innovation and multicultural exchange.The Science of "Cooking" with Citrus: Denaturation and Flavor At the core of Peruvian Ceviche's transformative magic lies a captivating biochemical phenomenon: protein denaturation, often colloquially referred to as "cooking without heat." This process occurs when the proteins in raw fish muscle are exposed to the highly acidic environment created by citrus juices, predominantly lime. Unlike thermal cooking, which employs heat to break and re-form protein bonds, in Ceviche, it is the low pH of the citric acid that instigates this structural change. The mechanism is intricate yet elegant. Proteins, complex molecules essential to all living organisms, possess intricate three-dimensional structures maintained by various weak bonds (hydrogen bonds, ionic bonds, disulfide bridges). When the pH level surrounding these proteins drops significantly, as it does in lime juice (with a pH typically between 2.0 and 2.5), the excess hydrogen ions (H+) interfere with these bonds. This interaction causes the tightly coiled protein structures to unravel and unfold, a process known as denaturation. Once denatured, the proteins coagulate and re-aggregate into new, less soluble forms, leading to several observable changes in the fish. The translucent, glossy appearance of raw fish gives way to an opaque, milky-white hue, mirroring the visual transformation seen in heat-cooked fish. Concurrently, the texture shifts from soft and pliable to firm and flaky. Research published in journals like the Journal of Agricultural and Food Chemistry has extensively documented these specific protein alterations in various seafoods when exposed to acidic marinades, confirming the direct correlation between pH reduction and structural changes in muscle fibers. Beyond the visible and textural changes, acid-induced denaturation plays a profound role in shaping Ceviche's distinct flavor profile. The acidity not only "cooks" the fish but also acts as a powerful flavor enhancer, cutting through any potential "fishiness" and brightening the natural taste of the seafood. The lime juice itself contributes a complex array of volatile organic compounds, including terpenes and aldehydes, which impart its characteristic zesty, fresh, and slightly floral aromas. Moreover, the acid helps to break down some of the connective tissues within the fish, contributing to its tender yet firm mouthfeel. The synergistic interaction of citric acid with other components of the leche de tigre — such as the alliinase enzyme in garlic and onions, which produces pungent sulfur compounds, and capsaicinoids from aji limo peppers — creates a multi-layered flavor explosion. The capsaicinoids, responsible for the peppers' heat, are highly soluble in the acidic marinade, dispersing their warmth throughout the dish and providing a crucial balance to the sharp acidity. While acid denaturation mimics thermal cooking in texture and appearance, it is vital to note that it does not achieve the same level of pathogen destruction. Therefore, the absolute freshness and quality of the fish, akin to sushi-grade standards, are paramount for safe consumption.👉 Continue Reading: Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse (Part 3)#Ceviche #PeruvianFood #HealthyEating #Seafood #CitrusMagic #FoodHistory Related InsightsChicken Yassa: The Tangy and Tender Onion Stew La Symphonie des Saveurs : Une Odyssée Culinaire au Cœur de la France Éternelle The Art of Dim Sum: Hong Kong’s Tiny Bites That Pack a World of Flavor{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "Dive deep into the rich history, scientific principles, and unparalleled flavors of authentic Peruvian Ceviche, a culinary masterpiece crafted by the magic of citrus." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse (Part 2)?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Isabella Rossi." } }, { "@type": "Question", "name": "Where can I find more related content about Food?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Food category page." } } ] }
- Isabella Rossi
- 12 Jul, 2026 13:39
Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse (Part 3)
This is Part 3 of the series. Read Part 2 here.Crafting the Perfect Leche de Tigre: The Soul of Ceviche If Ceviche is the epitome of Peruvian culinary artistry, then leche de tigre—literally "tiger's milk"—is its vibrant, indispensable soul. Far from being a mere byproduct or a simple lime juice marinade, leche de tigre is a meticulously crafted, potent elixir that elevates raw seafood into an unforgettable gastronomic experience. This cloudy, piquant liquid, often enjoyed as a shot on its own, is renowned in Peru for its invigorating properties, believed to be an aphrodisiac and a miraculous hangover cure, restoring vigor and vitality to those who partake. Its enigmatic name is thought to reference its milky white appearance and its legendary strength. The foundational ingredient for any authentic leche de tigre is an abundance of freshly squeezed, high-quality lime juice. Peruvian limes (Citrus aurantiifolia) are distinct from their Persian counterparts; they are smaller, intensely acidic, and possess a unique floral aroma that is crucial to the authentic flavor profile. Beyond this citrus base, the magic unfolds with a precise blend of aromatics and spices. Essential components include finely minced aji limo or rocoto peppers, which provide a clean, vibrant heat and fruity undertones distinct from other chilies. Thinly sliced red onion, fresh garlic, and cilantro stems are also integral, contributing pungent, herbaceous notes that deepen the marinade's complexity. Crucially, the "milkiness" and profound umami depth of leche de tigre often come from incorporating a small amount of the same pristine white fish used for the ceviche itself (typically trimmings or a small fillet piece), along with a few ice cubes, into the mixture before blending. This emulsifies the fish proteins, adding body and a rich, savory essence. Here’s a detailed, step-by-step guide to crafting a classic leche de tigre:Prepare the Aromatic Base: Finely mince 1-2 cloves of garlic, a 1-inch piece of aji limo (seeds and veins removed for moderate heat, or left in for intense spice), and about 2 tablespoons of cilantro stems. Slice ¼ of a red onion thinly. Extract Fresh Lime Juice: Squeeze the juice from approximately 8-10 fresh key limes, ensuring that no seeds or excessive pulp contaminate the liquid. The volume should be around ¾ to 1 cup. Initial Blend & Maceration: In a blender, combine roughly half of the lime juice, the minced garlic, aji limo, cilantro stems, and a small (about 1 ounce) piece of the fresh, white fish. Add 2-3 ice cubes; these help keep the mixture cold, preventing the fish from "cooking" too rapidly and ensuring the flavors remain bright. Pulse briefly, just until the fish is integrated and the mixture takes on a slightly opaque, milky appearance. Avoid over-blending, which can make it frothy. Strain and Combine: Pass the blended mixture through a fine-mesh sieve into a clean bowl, pressing down on the solids with the back of a spoon to extract every drop of flavorful liquid. Discard the solids. Combine this strained liquid with the remaining fresh lime juice. Season and Rest: Taste the leche de tigre and season with salt to preference. Some traditional chefs may add a tiny pinch of white pepper or a whisper of fish fumet for additional depth. Cover and chill thoroughly in the refrigerator for at least 30 minutes. This allows the flavors to meld and ensures the marinade is icy cold, which is crucial for the final Ceviche.Variations on leche de tigre are abundant across Peru. A "leche de tigre con crema" might involve the addition of a small amount of evaporated milk or a splash of fish stock to create a richer, smoother texture, while versions made with conchas negras (black scallops) produce a dark, briny, and intensely flavored liquid often lauded for its robust, oceanic character. Regardless of the regional twist, the essence of leche de tigre remains: it is the vibrant, acidic core that breathes life into the seafood, transforming it into an exquisite, invigorating culinary experience.Sourcing the Stars: Selecting the Freshest Seafood and Accompaniments The pursuit of an unparalleled Peruvian Ceviche begins and ends with the absolute integrity of its ingredients. As a dish centered on acid-cured raw seafood, the quality and freshness of the fish are not merely desirable; they are non-negotiable foundations for both exquisite flavor and paramount food safety. Any compromise in this regard risks undermining the entire culinary experience and potentially posing health risks. The adage "you can't make a good dish from bad ingredients" rings especially true for Ceviche. When selecting the star of your Ceviche – the fish – prioritize firm, white-fleshed, and mild-flavored varieties that will maintain their structural integrity during the brief acidic cure. Traditionally, Peruvian Ceviche relies on species such as corvina (sea bass), lenguado (flounder), perico (mahi-mahi), or sometimes tilapia. However, excellent results can also be achieved with high-quality snapper, halibut, cod, or even fresh, firm scallops. The key is to source seafood that is genuinely "sashimi-grade" or "sushi-grade," indicating it has been handled with extreme care from catch to counter and is deemed safe for raw consumption. When purchasing, look for these unequivocal signs of supreme freshness:Eyes: Should be clear, bright, and slightly bulging, never cloudy, dull, or sunken. Gills: Should be a vibrant, clean red or pink, free from any brown discoloration or slimy residue. Skin: Must appear shiny, moist, and taut, with no signs of bruising, discoloration, or dryness. Flesh: Should be firm and resilient to the touch. When gently pressed, it should spring back immediately without leaving an indentation. Avoid any fish that feels mushy or soft. Smell: The aroma should be clean, fresh, and reminiscent of the ocean – a briny, subtly sweet scent. Any strong "fishy" or ammonia-like odors indicate spoilage. Source: Purchase from a highly reputable fishmonger who can provide details on the fish's origin, catch date, and handling practices. Inquire about sustainable sourcing to ensure responsible consumption.Once you’ve acquired your pristine fish, proper handling is crucial. Keep it on ice or in the coldest part of your refrigerator until the very moment of preparation. Cut the fish into uniform, bite-sized cubes, typically around ¾-inch to 1-inch. This consistent sizing ensures even exposure to the leche de tigre and a uniform "cooking" throughout. Avoid overly thin slices, which can become tough, or excessively large chunks, which may not cure adequately. The supporting cast of accompaniments, while seemingly secondary, is indispensable to the harmonious complexity of Peruvian Ceviche:Camote (Sweet Potato): Boiled and sliced, its natural sweetness (a result of complex carbohydrates and natural sugars) provides a vital counterpoint to the sharp acidity of the leche de tigre, balancing the palate and enhancing the overall flavor profile. Choclo (Giant Peruvian Corn): These large, starchy, and subtly sweet kernels offer a satisfying chew and a grounding, earthy texture that complements the delicate fish. Cancha Serrana (Toasted Corn Kernels): Providing a delightful crunch and a salty, toasted flavor, cancha adds a crucial textural contrast, enriching each bite with a rustic, satisfying element. Red Onion: Thinly sliced red onion, often briefly rinsed in cold water to temper its pungency, delivers a sharp, piquant bite and a beautiful visual contrast. Aji Limo/Rocoto: These indigenous Peruvian peppers are not just for heat; they impart unique fruity and aromatic notes that are integral to the authentic flavor. Cilantro: Freshly chopped, cilantro adds a burst of herbaceous freshness, a vibrant green garnish, and a final aromatic lift.Each element, meticulously chosen and prepared, contributes to the holistic experience of Peruvian Ceviche, reflecting the country's rich biodiversity and profound culinary wisdom. Mastering the Assembly: From Marination to Presentation The culmination of history, science, and impeccable sourcing finds its ultimate expression in the precise assembly and masterful presentation of Peruvian Ceviche. This final stage is an exercise in timing, temperature, and visual artistry, transforming individual components into a cohesive, sensory masterpiece. Unlike traditional cooking where ingredients simmer together, Ceviche demands swiftness; the aim is a delicate balance where the fish is "kissed" by the acid, not overwhelmed. The duration of marination is perhaps the most debated aspect among Ceviche maestros. For a modern, delicate, "flash-cured" Ceviche, the optimal marination time is strikingly brief: one to five minutes. This quick exposure allows the exterior of the fish cubes to firm up and absorb the vibrant flavors of the leche de tigre, while the interior retains a succulent, almost raw, tenderness. This approach, heavily influenced by Nikkei cuisine, prioritizes the natural texture and pristine flavor of the fish. Longer marination, while historically practiced, can lead to a tougher, rubbery texture as the acid penetrates deeper and over-denatures the proteins. However, some traditionalists still prefer a slightly longer soak (up to 10-15 minutes) for a more thoroughly "cooked" and firmer fish. The key is constant observation: once the fish turns opaque and its edges begin to curl slightly, it’s reached its peak. The Art of Assembly and Plating:Ensure Chill: All ingredients – the diced fish, the prepared leche de tigre, and the accompaniments – must be thoroughly chilled. The refreshing, invigorating quality of Ceviche is paramount, and temperature plays a vital role. Combine Fish and Leche de Tigre: In a non-reactive bowl (glass or ceramic is ideal), gently combine the perfectly diced, pristine fish with a generous pour of the icy-cold leche de tigre. Stir gently and briefly to ensure every piece of fish is evenly coated. Incorporate Aromatics: Immediately add a portion of the thinly sliced red onion and minced aji limo or rocoto to the mixture. Their flavors will begin to infuse the marinade and the fish instantly. Marinate with Precision: Allow the mixture to marinate for your desired duration, stirring once or twice to ensure even exposure. For a flash-cured style, this will be very quick. Taste and Refine: Take a small piece of fish and a spoonful of the leche de tigre to taste. Adjust seasoning with a pinch more salt if necessary. The balance of acidity, salt, and heat is crucial for the dish's vibrancy. Masterful Plating: Presentation is key to the Ceviche experience. Use a chilled, shallow bowl or a stylish plate. Begin by artfully arranging a few slices of boiled camote (sweet potato) at the bottom or to one side of the plate, providing a visual anchor and a sweet counterpoint. Carefully spoon the cured fish and its generous amount of leche de tigre over and around the sweet potato. The liquid is as important as the solids. Garnish with a scattering of choclo kernels, a sprinkle of crunchy cancha serrana, and a vibrant flourish of freshly chopped cilantro. A thin slice of aji limo or a small red onion ring can serve as a final, elegant touch.Serve Immediately: Ceviche is a dish that must be consumed without delay. Its ephemeral freshness, delicate texture, and vibrant flavors are at their peak moments after assembly. Lingering allows the acid to continue curing the fish, potentially leading to an undesirable, overly firm texture.Modern interpretations of Ceviche continue to push boundaries, exploring different citrus, exotic fruits, and innovative spice blends. Tiradito, a close relative of Ceviche, features fish sliced carpaccio-style and bathed in a single-serve leche de tigre, often infused with aji amarillo or rocoto, typically without the onions, showcasing the dynamic interplay of culinary traditions. Regardless of these exciting variations, the core principles of fresh, high-quality seafood, a powerful acidic cure, and perfectly balanced accompaniments remain the immutable heart of mastering the art of Peruvian Ceviche. Conclusion: A Culinary Legacy, Timeless and Enduring Our journey through the world of Peruvian Ceviche reveals a dish far more profound than its deceptively simple appearance suggests. It is a culinary legacy, steeped in millennia of history, where ancient traditions have gracefully fused with colonial influences and global innovations to create a truly unique gastronomic marvel. From the Moche civilization's early experiments with fermented juices to the refined, rapid-curing techniques perfected by Nikkei chefs, Ceviche stands as a living testament to Peru's rich cultural tapestry and its boundless culinary ingenuity. We've explored the fascinating science behind its "cooking" process, understanding how the humble lime orchestrates a remarkable biochemical transformation, denaturing proteins to achieve that signature firm yet tender texture and vibrant opacity. We’ve celebrated the leche de tigre, the very soul of the dish, a meticulously crafted elixir that infuses the seafood with an invigorating burst of flavor and life. And we’ve underscored the critical importance of sourcing only the freshest, most pristine seafood, complemented by a symphony of textures and flavors from camote, choclo, and cancha, each playing its vital role in the grand composition. Ceviche is more than just a meal; it's a sensory explosion, a refreshing paradox of raw and "cooked," a harmonious balance of acidity, heat, and sweetness that awakens the palate and invigorates the spirit. It's a dish that speaks of the ocean's bounty, the earth's generosity, and the human touch that transforms simple ingredients into an extraordinary experience. As a lean protein powerhouse packed with essential nutrients, it stands as a testament to healthy and flavorful eating. So, whether you're savoring it on a bustling street corner in Lima or meticulously crafting it in your own kitchen, remember that each spoonful of Peruvian Ceviche carries with it a rich narrative of tradition, science, and passion. It's an invitation to taste history, to experience culinary alchemy, and to celebrate a dish that truly embodies the art of curing seafood with citrus. I encourage you to embrace this timeless culinary adventure, to experiment, and to discover the endless joys that Peruvian Ceviche has to offer. Until our next culinary exploration, Isabella Rossi.#PeruvianCuisine #CevicheMastery #HealthySeafood #CitrusCuisine #FoodScience#Ceviche #PeruvianFood #HealthyEating #Seafood #CitrusMagic #FoodHistory Related InsightsHannah Weber's Guide to Delicious and Healthy Sprouted Grain Bread with Avocado and Radish (Vegan) Kung Pao: Die Alchemie des Feuers und die Kunst des perfekten Kontrasts L'Alchimie des Trottoirs : Voyage Sensoriel au Cœur de la Street Food de Mumbai{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse (Part 3)?", "acceptedAnswer": { "@type": "Answer", "text": "Dive deep into the rich history, scientific principles, and unparalleled flavors of authentic Peruvian Ceviche, a culinary masterpiece crafted by the magic of citrus." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Peruvian Ceviche Revealed: The Ancient Citrus Alchemy That Transforms Seafood into a Nutritional Powerhouse (Part 3)?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Isabella Rossi." } }, { "@type": "Question", "name": "Where can I find more related content about Food?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Food category page." } } ] }
-
 Lukas Richter
- 12 Jul, 2026 12:08
Unlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears
In an era increasingly defined by data, the promise of Artificial Intelligence often collides head-on with the paramount demand for privacy. As AI models grow more sophisticated, their insatiable hunger for vast, diverse datasets presents an ethical and regulatory tightrope walk. Companies and researchers alike grapple with a fundamental dilemma: how do we harness the collective intelligence locked away in silos of sensitive data—be it personal health records, financial transactions, or proprietary enterprise information—without exposing individuals or compromising competitive advantage? The traditional approach of centralizing data for training AI models is not merely fraught with privacy risks; it is often logistically impossible due to regulatory constraints like GDPR, HIPAA, and CCPA, not to mention the sheer scale of data generated at the edge. This tension between innovation and protection has catalyzed a paradigm shift, giving rise to one of the most transformative advancements in machine learning: Federated Learning (FL). Pioneered by Google in 2016 for their Gboard keyboard predictions, FL fundamentally redefines how AI models learn. Instead of bringing all the data to a central server, FL brings the model to the data. It’s a decentralized approach where clients—whether individual mobile devices, hospitals, financial institutions, or IoT sensors—locally train a shared global model using their own datasets. Only aggregated model updates, not raw data, are sent back to a central server, which then orchestrates the consolidation of these updates into an improved global model. This revolutionary methodology allows AI to thrive on the richness of distributed information while rigorously upholding privacy, securing a future where intelligent systems can flourish without sacrificing our most fundamental right to data sovereignty.The Core Mechanics of Federated Learning: Beyond Centralized Paradigms At its heart, Federated Learning (FL) is an iterative, collaborative process designed to build a robust global model from disparate, localized datasets. Unlike traditional machine learning, where data is typically pooled onto a central server for training, FL flips the script. The core philosophy is "data stays local, models travel." This seemingly simple reversal has profound implications for privacy, scalability, and regulatory compliance. The FL cycle generally unfolds in several distinct phases, orchestrated by a central server (or orchestrator) that coordinates numerous participating clients. This process typically begins with the server initializing a global model (or retrieving the current global model) and distributing it to a selected subset of clients. Each client then takes this global model and trains it locally on its own private dataset. Crucially, this local training step leverages the client’s unique, sensitive data without ever exposing it outside its secure environment. The client processes its data, computes local model updates (e.g., gradients or updated model weights), and then securely transmits only these aggregated updates back to the central server. The raw data itself never leaves the client device. Upon receiving updates from multiple clients, the central server aggregates these contributions to produce a new, improved version of the global model. One of the most common and foundational aggregation algorithms is Federated Averaging (FedAvg), introduced by Brendan McMahan et al. in 2017 (arXiv:1602.05629). FedAvg simply averages the weights of the models received from participating clients, often weighted by the amount of data each client trained on. This aggregated model then becomes the basis for the next round of training, distributed back to the clients, and the cycle continues until the global model converges or a predefined number of rounds are completed. Consider a practical example using a simplified Pythonic representation for a client's local training: # Conceptual Python class for a Federated Learning Client import torch import torch.nn as nn import torch.optim as optimclass FederatedClient: def __init__(self, client_id, model, local_dataset, learning_rate=0.01): self.client_id = client_id self.model = model self.local_dataset = local_dataset self.optimizer = optim.SGD(self.model.parameters(), lr=learning_rate) self.criterion = nn.CrossEntropyLoss() def receive_global_model(self, global_model_weights): # Update client's model with global weights self.model.load_state_dict(global_model_weights) def train_local_model(self, epochs=1): self.model.train() for epoch in range(epochs): for inputs, labels in self.local_dataset: # self.local_dataset is typically a DataLoader self.optimizer.zero_grad() outputs = self.model(inputs) loss = self.criterion(outputs, labels) loss.backward() self.optimizer.step() # Return the locally updated model weights return self.model.state_dict() def send_local_update(self, local_model_weights): # In a real system, this would involve a secure network transmission # to the central server. For demonstration, we just return them. print(f"Client {self.client_id} sending model update.") return local_model_weights# Example usage (simplified server-side interaction) # global_model = SomeNeuralNetwork() # Initial global model # global_model_weights = global_model.state_dict() # # client_data = [...] # Client-specific data loaders # client_a = FederatedClient(1, SomeNeuralNetwork(), client_data[0]) # client_b = FederatedClient(2, SomeNeuralNetwork(), client_data[1]) # # # Round 1 # client_a.receive_global_model(global_model_weights) # client_b.receive_global_model(global_model_weights) # # update_a = client_a.train_local_model() # update_b = client_b.train_local_model() # # # Server aggregates updates (e.g., simple averaging) # aggregated_weights = { # key: (update_a[key] + update_b[key]) / 2 # for key in update_a.keys() # } # global_model.load_state_dict(aggregated_weights) # print("Global model updated.")This fundamental cycle ensures that sensitive data never leaves its source, providing a baseline privacy guarantee that is crucial for building trust and enabling AI in highly regulated domains. Architectures and Communication Protocols: Orchestrating Decentralized Intelligence The practical implementation of Federated Learning requires robust architectures and sophisticated communication protocols to manage the distributed training environment effectively. Two primary architectural paradigms dominate the FL landscape: cross-device and cross-silo FL, each catering to different use cases and scales. Cross-device Federated Learning, often referred to as horizontal FL, typically involves a massive number of mobile devices (smartphones, IoT sensors, wearables) with relatively small, non-IID datasets. Think of millions of smartphones collaboratively training an autocorrect model without sending individual keyboard usage data. The communication is often intermittent, unreliable, and bandwidth-constrained. Frameworks like TensorFlow Federated (TFF) and Google's internal systems are designed to handle this scale, focusing on efficient communication and robustness against device dropouts. The server acts as an orchestrator, selecting a subset of active clients for each round, distributing models, and aggregating updates. Cross-silo Federated Learning, or vertical FL, involves a smaller number of organizations (e.g., hospitals, banks, research institutions) each possessing large, often complementary datasets that share common entities but different feature sets. For instance, two banks might want to collaboratively build a fraud detection model using their respective customer data without merging their sensitive customer records. In this scenario, clients are typically powerful servers or data centers with reliable network connections. Here, secure multi-party computation (SMPC) and homomorphic encryption (HE) play a more prominent role to ensure privacy during the intermediate computation steps where features might be aligned or combined. Regardless of the architecture, effective communication protocols are paramount. gRPC (Google Remote Procedure Call) is a popular choice for its efficiency, multi-language support, and bi-directional streaming capabilities, making it ideal for the client-server interactions of FL. Secure channels (TLS/SSL) are always a baseline requirement for encrypting data in transit. Frameworks like Flower (a general-purpose FL framework), PySyft (from OpenMined, focusing on privacy-preserving AI), and TensorFlow Federated (TFF) provide abstractions for building FL systems. They handle client selection, model distribution, secure aggregation, and fault tolerance. Here's a conceptual docker-compose.yaml to illustrate setting up a simple multi-client FL simulation environment with a central server and multiple clients, using a framework like Flower or TFF as the underlying orchestration layer. Each service would run a Python script for either the server or client logic. version: '3.8' services: # Federated Learning Server server: build: context: ./server dockerfile: Dockerfile ports: - "8080:8080" environment: # Optional: specify number of clients, rounds, etc. SERVER_PORT: 8080 networks: - fl_network command: python /app/server.py # Federated Learning Clients client_1: build: context: ./client dockerfile: Dockerfile environment: CLIENT_ID: "client_1" SERVER_ADDRESS: "server:8080" # Connect to the server service networks: - fl_network depends_on: - server command: python /app/client.py client_2: build: context: ./client dockerfile: Dockerfile environment: CLIENT_ID: "client_2" SERVER_ADDRESS: "server:8080" networks: - fl_network depends_on: - server command: python /app/client.py client_3: build: context: ./client dockerfile: Dockerfile environment: CLIENT_ID: "client_3" SERVER_ADDRESS: "server:8080" networks: - fl_network depends_on: - server command: python /app/client.pynetworks: fl_network: driver: bridgeThis docker-compose.yaml file defines a simple FL network where a server orchestrates three clients. Each server.py and client.py would contain the specific logic for model exchange and training, typically leveraging an FL framework's API. For example, a client.py using Flower might look like: # client/client.py (Flower client example) import flower as fl import tensorflow as tf # Or PyTorch from model import get_model, train, test # Assume these are defined elsewhereclass CifarClient(fl.client.NumPyClient): def __init__(self, model, x_train, y_train, x_test, y_test): self.model = model self.x_train, self.y_train = x_train, y_train self.x_test, self.y_test = x_test, y_test def get_parameters(self, config): return self.model.get_weights() def fit(self, parameters, config): self.model.set_weights(parameters) self.model, results = train(self.model, self.x_train, self.y_train, config) return self.model.get_weights(), len(self.x_train), results def evaluate(self, parameters, config): self.model.set_weights(parameters) loss, accuracy = test(self.model, self.x_test, self.y_test) return loss, len(self.x_test), {"accuracy": accuracy}if __name__ == "__main__": # Load data and create model (simplified) # (x_train, y_train), (x_test, y_test) = tf.keras.datasets.cifar10.load_data() # model = get_model() # A Keras model # client = CifarClient(model, x_train, y_train, x_test, y_test) # fl.client.start_numpy_client(server_address="server:8080", client=client) print("Flower client started, waiting for connection...") # Placeholder for actual client logicThis distributed setup demonstrates how FL leverages existing network technologies to enable collaborative AI without centralizing raw data.Enhancing Privacy Guarantees: Differential Privacy and Secure Aggregation While Federated Learning inherently protects privacy by keeping raw data local, sophisticated attacks can still infer sensitive information from the shared model updates. Researchers have shown that even aggregated model weights can, under certain conditions, reveal characteristics of individual training samples through techniques like membership inference attacks or model inversion. To counter these threats, FL integrates advanced privacy-enhancing technologies (PETs), notably Differential Privacy (DP) and Secure Multi-Party Computation (SMPC), often complemented by Homomorphic Encryption (HE). Differential Privacy (DP) provides a strong, mathematically quantifiable guarantee of privacy. Its core idea is to inject carefully calibrated noise into the model updates (or directly into the training process) such that the contribution of any single data point becomes indistinguishable to an adversary. This means that an attacker observing the global model or aggregated updates cannot confidently determine if a specific individual's data was included in the training dataset. DP is parameterized by epsilon (ε) and delta (δ), where a smaller ε indicates stronger privacy (but potentially lower model utility), and δ represents the probability of privacy leakage exceeding ε. Implementing DP in FL often involves adding noise to the local model updates before they are sent to the server (client-side DP) or adding noise to the aggregated model on the server before distributing it (server-side DP). Frameworks like Opacus (for PyTorch) or TensorFlow Privacy make it easier to integrate DP into deep learning models. Here's a conceptual Python example using Opacus to apply Differential Privacy to a PyTorch model during local training within an FL client: # Conceptual Python snippet for a DP-enabled FL client from opacus import PrivacyEngine import torch.nn as nn import torch.optim as optimclass DP_FederatedClient(FederatedClient): # Inherits from earlier FederatedClient def __init__(self, client_id, model, local_dataset, learning_rate=0.01, epsilon=1.0, delta=1e-5, max_grad_norm=1.0): super().__init__(client_id, model, local_dataset, learning_rate) self.privacy_engine = PrivacyEngine( self.model, batch_size=32, # Batch size for local training sample_size=len(local_dataset.dataset), # Total samples in client's local dataset alphas=[1 + x / 10.0 for x in range(1, 100)] + list(range(10, 60)), noise_multiplier=0, # Will be set by privacy_engine.make_private max_grad_norm=max_grad_norm, ) # Apply DP to the optimizer self.optimizer = optim.SGD(self.model.parameters(), lr=learning_rate) # The make_private method automatically wraps the optimizer and adds hooks for DP # This calculates the appropriate noise_multiplier for the given epsilon, delta self.optimizer, self.data_loader, self.privacy_engine = self.privacy_engine.make_private( module=self.model, optimizer=self.optimizer, data_loader=self.local_dataset, noise_multiplier_target=epsilon, # Opacus uses this as target epsilon target_delta=delta, epochs=1 # Number of local epochs ) print(f"Client {self.client_id}: Noise multiplier: {self.optimizer.noise_multiplier}") def train_local_model(self, epochs=1): self.model.train() for epoch in range(epochs): for inputs, labels in self.local_dataset: self.optimizer.zero_grad() outputs = self.model(inputs) loss = self.criterion(outputs, labels) loss.backward() self.optimizer.step() return self.model.state_dict()Secure Multi-Party Computation (SMPC) is another cornerstone. SMPC protocols allow multiple parties to collectively compute a function on their private inputs without revealing those inputs to each other. In FL, SMPC can be used during the aggregation phase: clients encrypt their model updates before sending them, and the server (or a set of aggregation servers) can compute the sum of these encrypted updates without decrypting individual contributions. Only the final aggregated sum is revealed. This protects against a malicious server or colluding clients from learning individual updates. Homomorphic Encryption (HE) takes SMPC a step further by allowing computations (like addition or multiplication) directly on encrypted data. A client could encrypt its model updates using an HE scheme, send the ciphertext to the server, and the server could perform aggregation (e.g., summation) on these ciphertexts. The result is an encrypted aggregate, which only the client (or an authorized party with the decryption key) can decrypt. HE offers strong privacy guarantees but comes with significant computational overhead, making it more suitable for scenarios with fewer, powerful clients and simpler models (e.g., cross-silo FL). The trade-off is clear: stronger privacy often comes at the cost of increased computational complexity, communication overhead, or a slight reduction in model utility. The choice of PETs depends on the specific privacy requirements, threat model, and available computational resources. By intelligently combining these techniques, Federated Learning moves beyond simply distributed training to truly privacy-preserving AI. Tackling Data Heterogeneity and System Challenges: The Real-World Gauntlet While Federated Learning offers compelling advantages, its deployment in real-world scenarios is far from trivial. Two major categories of challenges emerge: data heterogeneity and system-level complexities. Successfully navigating these requires sophisticated algorithmic and engineering solutions. Data Heterogeneity (Non-IID Data): This is arguably the most significant algorithmic hurdle in FL. In idealized centralized training, data is assumed to be Independent and Identically Distributed (IID) across mini-batches. However, in FL, clients typically possess data that is inherently non-IID. For instance, a mobile phone user's keyboard usage patterns (autocorrect data) will differ significantly from another user's, reflecting unique vocabulary, topics, and typing styles. Similarly, medical records from different hospitals might have varying patient demographics, prevalent diseases, or diagnostic procedures. Training on non-IID data can lead to several problems:Client Drift: Local models diverge significantly from the global model due to unique local data, making aggregation less effective. Slower Convergence: The global model may take many more rounds to converge, or even fail to converge, as aggregated updates conflict with each other. Performance Degradation: The final global model may perform poorly on individual clients, or generalize poorly to unseen data, particularly on clients with underrepresented data distributions.To mitigate non-IID issues, various research directions have emerged. Personalization techniques, like FedProx (Li et al., 2018, arXiv:1812.06127), add a proximal term to the client's local loss function, penalizing divergence from the global model and encouraging clients to stay closer to the aggregate. Other approaches involve model-agnostic meta-learning (MAML) or knowledge distillation, where clients learn a personalized model or distill knowledge from the global model. System Challenges: Beyond data distribution, the sheer distributed nature of FL introduces significant engineering complexities:Device Heterogeneity: Clients can range from powerful data centers to low-power IoT devices with varying computational capabilities, memory, and battery life. Communication Constraints: Bandwidth limitations, high latency, and intermittent connectivity are common, especially in cross-device FL. This necessitates efficient compression techniques for model updates and robust communication protocols. Client Availability and Reliability: Devices can drop out mid-training, go offline, or have corrupted data. The FL system must be resilient to these "stragglers" and failures, potentially by employing asynchronous aggregation or robust client selection strategies. Security and Trust: Malicious clients can attempt data poisoning (injecting bad data to corrupt the model) or model poisoning (submitting adversarial updates to sabotage the global model). Robust aggregation methods like Krum (Blanchard et al., 2017, arXiv:1703.02757) or Trimmed Mean are designed to identify and filter out outlier updates.Here's a conceptual Python snippet demonstrating how to simulate non-IID data partitioning for clients, a common setup for research and experimentation: # Conceptual Python snippet for non-IID data partitioning import numpy as np import torch from torchvision import datasets, transformsdef partition_data_by_label_skew(dataset, num_clients, num_shards_per_client, num_classes): """ Partitions data to simulate non-IID client datasets with label skew. Each client gets a specific number of shards (e.g., each shard contains data from only one class) to ensure non-IIDness. """ label_indices = [[] for _ in range(num_classes)] for i, (_, label) in enumerate(dataset): label_indices[label].append(i) # Shuffle indices for each label for i in range(num_classes): np.random.shuffle(label_indices[i]) # Assign shards to clients client_datasets = [[] for _ in range(num_clients)] current_label_shard_idx = [0] * num_classes for client_id in range(num_clients): # Determine which classes this client will primarily have # A simple strategy: each client gets data from a few specific classes chosen_classes = np.random.choice(num_classes, size=num_shards_per_client, replace=False) for class_idx in chosen_classes: start_idx = current_label_shard_idx[class_idx] end_idx = start_idx + (len(label_indices[class_idx]) // num_clients // num_shards_per_client) # Ensure we don't go out of bounds if start_idx >= len(label_indices[class_idx]): continue # No more data for this class shard_indices = label_indices[class_idx][start_idx:end_idx] client_datasets[client_id].extend(shard_indices) current_label_shard_idx[class_idx] = end_idx # Create Subset objects for each client client_subsets = [] for indices in client_datasets: client_subsets.append(torch.utils.data.Subset(dataset, indices)) return client_subsets# Example Usage: # transform = transforms.Compose([transforms.ToTensor(), transforms.Normalize((0.5,), (0.5,))]) # train_dataset = datasets.MNIST('./data', train=True, download=True, transform=transform) # # num_clients = 10 # num_shards_per_client = 2 # Each client gets data from 2 classes primarily # num_classes = 10 # MNIST has 10 classes # # client_data_subsets = partition_data_by_label_skew(train_dataset, num_clients, num_shards_per_client, num_classes) # # # Now client_data_subsets[i] can be used to create a DataLoader for client i # # For example: client_i_dataloader = torch.utils.data.DataLoader(client_data_subsets[i], batch_size=32) # print(f"Generated {len(client_data_subsets)} client datasets.") # for i, subset in enumerate(client_data_subsets): # labels_in_subset = [train_dataset[j][1] for j in subset.indices] # unique_labels, counts = np.unique(labels_in_subset, return_counts=True) # print(f"Client {i} dataset size: {len(subset)}, labels: {list(zip(unique_labels, counts))}")This function highlights the complexity of creating realistic non-IID scenarios for experimentation, a crucial step in developing robust FL algorithms that can handle the unpredictability of real-world data distributions. Overcoming these challenges is vital for FL's widespread adoption and for delivering its full promise of privacy-preserving AI. Real-World Applications and The Regulatory Landscape: FL's Impact and Future Federated Learning is rapidly transitioning from an academic curiosity to a critical enabler of AI solutions across diverse industries, particularly where data privacy and ownership are paramount. Its real-world impact is already evident and continues to expand. In the consumer tech space, Google's pioneering use of FL for its Gboard keyboard is a prime example. Gboard uses FL to train next-word prediction models and emoji suggestions directly on user devices without sending keystroke data to Google's servers. Apple similarly leverages FL for features like Face ID improvement and health data analysis within its HealthKit ecosystem, ensuring sensitive biometric and health information remains on the user's device. Healthcare stands to benefit immensely. NVIDIA's Clara Federated Learning framework, for instance, enables hospitals to collaboratively train AI models for medical image analysis (e.g., tumor detection, disease diagnosis) using their proprietary patient datasets. This allows for the creation of more robust and generalizable models that leverage diverse patient populations, circumventing the need to centralize highly sensitive Protected Health Information (PHI), which is heavily regulated by HIPAA. Y Combinator-backed startups in the health AI space are actively exploring FL to unlock insights from fragmented datasets, accelerating drug discovery and personalized medicine. Financial services are another frontier. Banks and credit card companies can use FL to develop more accurate fraud detection models or credit scoring systems by collaborating on transaction data without sharing raw customer details. This can lead to stronger models that identify novel fraud patterns more quickly across a wider base, while adhering to strict financial data regulations. Similarly, autonomous vehicle companies could collaboratively train perception models on driving data from different fleets without exchanging raw sensor readings, enhancing safety and accelerating development. The rapid rise of FL directly intersects with the evolving regulatory landscape governing data privacy. Regulations like Europe's General Data Protection Regulation (GDPR), California's Consumer Privacy Act (CCPA), and sector-specific rules like HIPAA and PCI DSS, impose stringent requirements on how personal data is collected, processed, and stored. By design, FL aligns exceptionally well with the core principles of these regulations, particularly data minimization and purpose limitation. Since only aggregated model updates (which are often differentially private) are shared, and raw data remains on the client device, FL significantly reduces the attack surface and simplifies compliance by avoiding the transfer of sensitive raw data across organizational or national boundaries. However, the regulatory landscape is not without its nuances. The concept of "personal data" in the context of model updates or gradients can still be debated, especially in cases where sophisticated inference attacks are possible. This drives the necessity for integrating advanced privacy-enhancing techniques like Differential Privacy and Secure Multi-Party Computation within FL, creating a layered defense. Ethical considerations also remain crucial, including preventing bias in federated models if client populations are not representative, and safeguarding against data poisoning or model inversion attacks. Open-source initiatives, such as the Linux Foundation AI & Data's "Open Federated Learning (OBLR)" project, are working to standardize and secure FL implementations, fostering wider adoption and trust. FL is not just a technical solution; it's a strategic imperative for organizations navigating a data-rich, privacy-conscious world. Its continued evolution promises a future where AI's immense potential can be realized responsibly and ethically. Federated Learning Frameworks Comparison To put the concepts into practice, several robust Federated Learning frameworks have emerged, each with its strengths and target audience. Understanding their differences is key to selecting the right tool for your project.Feature / Framework TensorFlow Federated (TFF) Flower PySyft (OpenMined) NVIDIA Clara Federated LearningOrigin / Focus Google. Designed for scalable cross-device FL. ETH Zurich. General-purpose, highly flexible, framework-agnostic. OpenMined. Strong emphasis on privacy-preserving ML (DP, SMPC, HE). NVIDIA. Specific focus on medical imaging and healthcare AI.ML Frameworks TensorFlow PyTorch, TensorFlow, JAX (via custom strategies) PyTorch, TensorFlow, Keras PyTorchPrivacy Features Built-in DP (TensorFlow Privacy), secure aggregation (via TFF) Pluggable DP, secure aggregation, custom strategies for PETs Deep integration of DP, SMPC, HE. Core mission is privacy. Integrates DP, secure aggregation, homomorphic encryption.Scalability Excellent for large-scale cross-device (millions of clients) Highly scalable for various FL architectures Good for cross-silo, cross-device. Can handle large client bases. Tailored for cross-silo in medical domain (fewer, powerful clients).Ease of Use / API Steep learning curve, functional API Pythonic, intuitive, flexible API More complex due to advanced privacy features, evolving API Relatively straightforward for PyTorch users, specific to domain.Community Support Large, active community (Google-backed) Growing, active community, excellent documentation Active research community, strong focus on privacy research Enterprise-focused, strong support for healthcare partners.Key Use Cases Mobile device applications (Gboard), large distributed ML Research, prototyping, custom FL deployments, diverse ML Highly sensitive data (healthcare, finance), privacy research Medical image analysis, drug discovery, clinical insights.Advantages Highly optimized, robust for scale, strong DP integration Flexible, framework-agnostic, good for research & production Strongest native support for advanced PETs, cutting-edge privacy Optimized for medical data, integrates with NVIDIA hardware.Considerations TensorFlow-centric, complex API for beginners Requires careful implementation of PETs, less out-of-the-box Higher complexity, overhead for advanced PETs Domain-specific, limited to PyTorch.This comparison highlights that while all frameworks aim to facilitate federated learning, they each offer unique strengths, making the choice dependent on the project's specific requirements regarding scale, privacy guarantees, ML framework preference, and industry domain. Conclusion Federated Learning stands as a pivotal advancement in the ongoing quest to reconcile the immense potential of Artificial Intelligence with the foundational right to privacy. We've journeyed through its core mechanics, understanding how models learn collaboratively without ever centralizing sensitive raw data. We've explored the sophisticated architectures and communication protocols that enable decentralized intelligence, from countless mobile devices to powerful institutional silos. Crucially, we've delved into the advanced privacy-enhancing technologies like Differential Privacy and Secure Multi-Party Computation, which act as formidable shields against inference attacks, mathematically quantifying and fortifying data sovereignty. Yet, we've also acknowledged the formidable real-world gauntlet FL faces, from the pervasive challenge of data heterogeneity (non-IID distributions) to system-level complexities like device dropouts and communication constraints. The continued innovation in algorithms and robust aggregation methods is a testament to the community's commitment to overcoming these hurdles. The impact of FL is not theoretical; it's already reshaping industries from consumer technology and healthcare to finance, aligning AI development with stringent global privacy regulations like GDPR and HIPAA. Federated Learning is more than just a technique; it is a philosophy that champions responsible AI development. It promises a future where intelligence is truly collective, derived from a wealth of diverse data sources, yet meticulously respectful of individual and organizational privacy. The path ahead involves continuous research into scalability, fairness, and the integration of even more advanced cryptographic methods. As we push the boundaries of AI, Federated Learning will undoubtedly be at the forefront, ensuring that our pursuit of innovation does not come at the cost of our most fundamental digital rights. The revolution is here, and it’s federated. Lukas Richter, Senior Software Engineer, AI Researcher, Elite Tech Blogger#FederatedLearning #AI #MachineLearning #Privacy #Cybersecurity #DistributedSystems Related InsightsUSB-C: The Silent Revolution Powering Your Digital Life from Phones to Supercomputers The Evolution and Impact of the Smartphone Camera: How a Pocket Device Revolutionized Photography The Future is Illuminating: A Deep Dive into OLED Technology{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Unlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears?", "acceptedAnswer": { "@type": "Answer", "text": "Explore Federated Learning's transformative power, enabling robust AI models while rigorously protecting sensitive user data across industries." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Unlocking AI's Full Potential: The Privacy Revolution of Federated Learning That Big Tech Fears?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Lukas Richter." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Claire Beaufort
- 12 Jul, 2026 11:38
Beyond the Veil: Unpacking AI's Black Box for Unprecedented Trust & Transparency with XAI
The pervasive integration of Artificial Intelligence into every facet of our lives, from personalized healthcare recommendations to autonomous vehicle navigation and critical financial decisions, has ushered in an era of unprecedented technological advancement. Yet, with this power comes a profound challenge: the "black box" problem. Many state-of-the-art AI models, particularly deep neural networks, operate with an opaque decision-making process, making it exceedingly difficult for humans to understand why a particular prediction or action was taken. This opacity breeds skepticism, hinders debugging, and poses significant ethical, legal, and safety risks. Enter Explainable AI (XAI) – a burgeoning field dedicated to making AI systems more transparent, interpretable, and understandable to humans. XAI is not merely an academic pursuit; it's a critical enabler for trust, accountability, and the responsible deployment of AI in regulated and high-stakes environments. As an AI researcher and senior software engineer, I've witnessed firsthand the paradigm shift XAI is bringing, transforming complex algorithms from mysterious oracles into collaborative decision-making partners. This article will delve deep into the technical intricacies of XAI, exploring its foundational principles, advanced methodologies, and the critical role it plays in securing our AI-driven future. We'll unpack the tools, techniques, and architectural considerations that empower us to demystify these powerful black boxes, offering practical insights and code examples to illuminate the path forward. Join me as we journey beyond mere prediction, towards profound understanding. The Imperative for Transparency: Why XAI is the Cornerstone of Trust in Modern AI The "black box" phenomenon in AI is no longer a fringe concern; it's a central debate shaping regulatory frameworks and industry best practices. While models like BERT, GPT-4, and advanced CNNs achieve astounding predictive accuracy, their internal mechanisms often remain inscrutable. This lack of transparency has tangible, often severe, consequences. Consider a diagnostic AI recommending a life-altering medical treatment without any justification, or an algorithmic trading system executing trades that cause significant market shifts without a clear rationale. In such scenarios, understanding "why" is not just desirable; it's absolutely essential for safety, ethical governance, and legal compliance. Regulations like the European Union's GDPR explicitly grant individuals a "right to explanation" for decisions made by algorithms that significantly affect them. The forthcoming EU AI Act and similar initiatives globally underscore the legal imperative for explainable systems, particularly in "high-risk" applications. From a debugging perspective, an inexplicable error in a complex deep learning model can be nearly impossible to trace and rectify without interpretable insights into its internal workings. Furthermore, without explainability, inherent biases hidden within training data can propagate and amplify, leading to discriminatory outcomes in areas like loan applications, hiring, or criminal justice. XAI provides the tools to audit models for fairness, uncover and mitigate biases, and ensure ethical decision-making. Researchers at institutions like IBM and Google have extensively documented the pitfalls of unexplainable AI, highlighting issues ranging from model drift to adversarial attacks that exploit latent vulnerabilities only detectable through robust explainability frameworks. The demand for XAI is driven by a confluence of regulatory pressure, ethical considerations, the practical needs of debugging and maintenance, and a fundamental human desire for understanding. Let's consider a simple conceptual example where an opaque model might pose issues. Imagine a credit scoring model. import pandas as pd from sklearn.ensemble import RandomForestClassifier# Sample data data = { 'income': [50000, 70000, 30000, 100000, 45000], 'credit_score_history': [700, 750, 550, 800, 600], 'loan_amount': [10000, 20000, 5000, 50000, 8000], 'employment_duration_years': [5, 10, 2, 15, 4], 'default': [0, 0, 1, 0, 1] # 0 = no default, 1 = default } df = pd.DataFrame(data)X = df[['income', 'credit_score_history', 'loan_amount', 'employment_duration_years']] y = df['default']# Train an opaque model (e.g., RandomForest) model = RandomForestClassifier(random_state=42) model.fit(X, y)# Predict for a new applicant new_applicant = pd.DataFrame([[60000, 680, 15000, 7]], columns=X.columns) prediction = model.predict(new_applicant) prediction_proba = model.predict_proba(new_applicant)print(f"Applicant prediction: {'Default' if prediction[0] == 1 else 'No Default'}") print(f"Default probability: {prediction_proba[0][1]:.2f}")# Without XAI, if this applicant is denied, we can't easily explain why. # Was it income? Credit history? Loan amount? A combination? # This is where XAI provides the 'why'.This simple RandomForest output gives a prediction, but no insight into why an applicant was deemed high-risk. This is the exact gap XAI aims to fill, making the decision-making process transparent and auditable.Dissecting the Black Box: Foundational Techniques for Local and Global Explainability XAI methodologies generally fall into two broad categories: local explanations, which clarify a single prediction, and global explanations, which provide an overarching understanding of the model's behavior across its entire dataset. Both are crucial for comprehensive model understanding and validation. Local Explainability focuses on understanding why a model made a specific prediction for a specific instance.LIME (Local Interpretable Model-agnostic Explanations): Pioneered by Ribeiro et al. (arXiv:1602.04938), LIME works by perturbing a single data instance and observing how the model's prediction changes. It then trains a simple, interpretable model (like a linear model or decision tree) locally around this perturbed instance. This surrogate model approximates the black box's behavior in that local region, providing feature importances for the specific prediction. LIME is "model-agnostic," meaning it can be applied to any black-box model. SHAP (SHapley Additive exPlanations): Based on cooperative game theory, SHAP values (Lundberg & Lee, arXiv:1704.03037) assign each feature an "importance value" for a particular prediction. These values represent the average marginal contribution of a feature value across all possible coalitions of features. SHAP offers a unified framework for interpreting any machine learning model, providing both local and global interpretability. Tools like shap on GitHub are widely adopted due to their theoretical soundness and flexibility.Global Explainability aims to understand the overall behavior of a model and how features generally influence predictions.Permutation Feature Importance (PFI): This method assesses the importance of a feature by calculating how much the model's performance decreases when the values of that feature are randomly shuffled (permuted). A significant drop in performance indicates a highly important feature. PFI is model-agnostic and gives a global view of feature impact. Partial Dependence Plots (PDPs) and Individual Conditional Expectation (ICE) plots: PDPs show the marginal effect of one or two features on the predicted outcome of a model. They average out the effects of all other features, providing a global understanding of the relationship between selected features and the prediction. ICE plots, a disaggregated version of PDPs, show the dependence for each instance individually, revealing heterogeneities that might be obscured by averaging.These techniques allow us to peer into the inner workings of complex models. Let's see how SHAP can be applied: import shap import pandas as pd from sklearn.ensemble import RandomForestClassifier from sklearn.model_selection import train_test_split# Load a classic dataset for demonstration from sklearn.datasets import load_iris iris = load_iris() X, y = iris.data, iris.target feature_names = iris.feature_names target_names = iris.target_names# Simplify to a binary classification problem for clarity: predict Versicolor vs. other y_binary = (y == 1).astype(int) # Split data X_train, X_test, y_train, y_test = train_test_split(X, y_binary, test_size=0.2, random_state=42)# Train a RandomForest model (our 'black box') model = RandomForestClassifier(random_state=42) model.fit(X_train, y_train)# Select a single instance from the test set for local explanation instance_to_explain = X_test[0] predicted_class = model.predict(instance_to_explain.reshape(1, -1))[0] print(f"Instance: {instance_to_explain}, Predicted Class (0=Not Versicolor, 1=Versicolor): {predicted_class}")# --- SHAP Explanation --- # 1. Create a SHAP Explainer object. For tree models, TreeExplainer is efficient. explainer = shap.TreeExplainer(model)# 2. Calculate SHAP values for the instance shap_values = explainer.shap_values(instance_to_explain)# shap_values will be a list of arrays for multi-output models; for binary it's [class0_values, class1_values] # We're interested in the values for the predicted class (class 1 in our binary case) shap_values_for_prediction = shap_values[predicted_class]print("\nSHAP values for the instance's prediction:") for i, feature in enumerate(feature_names): print(f" {feature}: {shap_values_for_prediction[i]:.4f}")# 3. Visualize the explanation (requires matplotlib) # shap.initjs() # For JS plots in notebooks # shap.force_plot(explainer.expected_value[predicted_class], shap_values_for_prediction, instance_to_explain, feature_names=feature_names) # For console/text-based output, we can interpret the values: # Positive SHAP value means the feature increases the prediction towards the positive class (Versicolor). # Negative SHAP value means the feature decreases the prediction towards the positive class.print("\nInterpretation:") print("The SHAP values indicate how much each feature contributed to pushing the model's output from the base value (average prediction) to the final prediction for this specific instance.") print(f"Features with higher absolute SHAP values had a stronger impact on the prediction of class '{predicted_class}'.")This SHAP example directly illustrates how features like petal length (cm) or sepal width (cm) specifically contributed to the model's classification of a single iris flower, allowing us to understand the individual prediction.Architecting for Clarity: Designing Inherently Interpretable AI Models While post-hoc explainability techniques like LIME and SHAP are powerful, an alternative strategy for achieving transparency is to design AI models that are inherently interpretable from the ground up. These models, by their very nature, allow direct insight into their decision-making logic without requiring additional tools or complex computations. This approach often trades some predictive power for superior transparency, a worthwhile compromise in many high-stakes applications where trust and audibility are paramount. Common Inherently Interpretable Models:Linear Regression and Logistic Regression: These foundational models express the relationship between features and the target variable through simple linear equations. The coefficients directly indicate the magnitude and direction of each feature's influence. For example, a positive coefficient in logistic regression means an increase in that feature increases the likelihood of the positive class. Decision Trees: These models mimic human decision-making with a series of if-then-else rules. The entire decision path for any prediction can be easily traced and visualized, making them highly transparent. While complex ensembles of trees (like Random Forests or Gradient Boosting) become less interpretable, individual decision trees are remarkably clear. Generalized Additive Models (GAMs): GAMs extend linear models by allowing for non-linear relationships between individual features and the target variable through smooth functions, while still maintaining additivity. This means the effect of each feature can be visualized independently, providing both flexibility and interpretability. Tools like interpret-ml on GitHub (from Microsoft Research) provide excellent implementations for GAMs and other interpretable models. Rule-Based Systems: These systems operate on a set of predefined rules (e.g., "IF age > 65 AND medical_condition = 'heart_disease' THEN recommended_treatment = 'cardiology_consult'"). Their logic is explicitly coded and therefore inherently transparent. Attention Mechanisms in Transformers: In natural language processing, Transformer models use attention mechanisms to weigh the importance of different words in a sequence when generating an output. These attention weights can be visualized, providing insight into which parts of the input the model focused on for a particular decision. While the overall Transformer is still complex, the attention map offers a critical window into its reasoning for specific outputs.The choice between an inherently interpretable model and a powerful black box with post-hoc XAI depends heavily on the specific use case, regulatory environment, and the acceptable trade-off between performance and transparency. For applications demanding absolute clarity, such as regulatory compliance in finance or safety-critical systems, an inherently interpretable architecture might be the preferred choice. Here’s a Python example demonstrating the inherent interpretability of a simple Decision Tree: from sklearn.tree import DecisionTreeClassifier, export_graphviz from sklearn.datasets import load_iris import graphviz import pandas as pd# Load Iris dataset iris = load_iris() X = pd.DataFrame(iris.data, columns=iris.feature_names) y = iris.target# Train a Decision Tree Classifier dt_model = DecisionTreeClassifier(max_depth=3, random_state=42) # Limit depth for visual clarity dt_model.fit(X, y)# Export the decision tree to a DOT format file dot_data = export_graphviz(dt_model, out_file=None, feature_names=iris.feature_names, class_names=iris.target_names, filled=True, rounded=True, special_characters=True) # Render the DOT file into a visual graph (requires graphviz to be installed) graph = graphviz.Source(dot_data) # graph.render("iris_decision_tree", view=True) # Uncomment to save and view the tree imageprint("Decision Tree Structure (truncated for console, full view requires graphviz rendering):") print("Root node condition:", dt_model.tree_.feature[0], " <= ", dt_model.tree_.threshold[0]) print("This output demonstrates the direct, rule-based nature of decision trees.") print("Each node represents a clear decision based on a feature value, making its logic inherently transparent.")The export_graphviz function directly provides the rules that the model uses to make decisions, which is a prime example of inherent interpretability.XAI in Action: Operationalizing Explanations within MLOps Pipelines Integrating XAI into research is one thing; operationalizing it within robust MLOps pipelines is quite another. For XAI to deliver its promise of trust and transparency in production systems, it must be seamlessly woven into the entire machine learning lifecycle, from data ingestion and model training to deployment, monitoring, and governance. This shift requires specific tools, architectural considerations, and a cultural commitment to responsible AI. Key Integration Points in MLOps:Model Development & Experimentation: During this phase, XAI tools like LIME, SHAP, and permutation importance are invaluable for model debugging, feature selection, and understanding potential biases before deployment. Data scientists use these explanations to refine models, ensure fairness, and build confidence in their design choices. Many MLOps platforms, such as MLflow, now integrate artifacts specifically for storing explanations alongside models. Pre-deployment Validation & Auditing: Before a model goes live, its explanations are critical for validation. Compliance teams can use XAI outputs to verify regulatory adherence, while domain experts can cross-check if the model’s reasoning aligns with human intuition or established domain knowledge. This can involve generating comprehensive explanation reports and storing them with model versions. Deployment as a Service: XAI capabilities can be deployed as dedicated microservices alongside the predictive model. When a prediction request comes in, the XAI service can generate an explanation on demand, either in real-time or asynchronously. This is crucial for applications requiring immediate justification (e.g., fraud detection, medical diagnosis). Continuous Monitoring & Retraining: Post-deployment, XAI plays a vital role in detecting model drift or unexpected behavior. If explanations start to change significantly or indicate reliance on irrelevant features, it signals a potential problem, triggering alerts for investigation or retraining. Platforms like IBM AI Explainability 360 (AIX360) and Microsoft Azure Machine Learning's Responsible AI dashboard offer integrated capabilities for monitoring explanations over time. Feedback Loops & Human-in-the-Loop Systems: Explanations facilitate better human-AI collaboration. Users can understand why a recommendation was made, provide informed feedback, and potentially correct the system. This feedback loop is essential for continuous improvement and building long-term trust.Consider a microservice architecture where an XAI component provides explanations for a deployed model. This might involve a Docker Compose setup for local development or a Kubernetes deployment in production. # docker-compose.yml for a local MLOps setup with XAI version: '3.8' services: model_service: build: context: ./model_api dockerfile: Dockerfile ports: - "8000:8000" environment: - MODEL_PATH=/app/model.pkl # Path to the pre-trained model volumes: - ./model_api:/app networks: - ai_network xai_service: build: context: ./xai_api dockerfile: Dockerfile ports: - "8001:8001" environment: - MODEL_SERVICE_URL=http://model_service:8000/predict volumes: - ./xai_api:/app networks: - ai_network depends_on: - model_servicenetworks: ai_network: driver: bridgeIn this docker-compose.yml, model_service hosts the main AI model, while xai_service provides explanations by querying the model service and applying XAI techniques (e.g., LIME or SHAP). This modular approach ensures that the explanation logic is decoupled, maintainable, and scalable, fitting perfectly within modern MLOps paradigms. The xai_api directory would contain a Python Flask/FastAPI app that takes input, sends it to model_service for a prediction, then generates and returns an explanation based on that input and prediction.The Horizon of Trust: Advanced Concepts and Future Challenges in Explainable AI The field of XAI is rapidly evolving, driven by ongoing research and the increasing complexity of AI systems. Beyond current techniques, several advanced concepts are emerging that promise to push the boundaries of interpretability, addressing both the technical nuances and the human factors involved in understanding AI. Emerging Trends:Causal XAI: Most current XAI methods identify correlations – which features are important for a prediction. Causal XAI (e.g., Pearl's causality framework applied to ML) aims to uncover why a feature causes a certain outcome. This moves beyond mere importance to a deeper understanding of the underlying causal mechanisms, which is critical for interventions and counterfactual explanations ("what if" scenarios). Recent arXiv papers delve into this, proposing frameworks that integrate causal inference models with traditional ML. Human-Centered XAI (HCAI): The ultimate goal of XAI is to help humans understand AI. HCAI focuses on tailoring explanations to the specific needs, expertise, and cognitive biases of different stakeholders – be it a data scientist, a domain expert, a regulator, or a lay user. This involves user studies, cognitive science, and human-computer interaction principles to design effective, actionable, and trustworthy explanations. Multimodal XAI: As AI models increasingly process and integrate data from multiple modalities (e.g., text, images, audio, tabular data), XAI must evolve to provide coherent, integrated explanations across these diverse inputs. For instance, explaining why a medical AI diagnosed a condition based on both a patient's textual history and an MRI scan. Adversarial Robustness and XAI: Explanations themselves can be manipulated or misleading. Research is exploring how to make XAI methods robust against adversarial attacks, ensuring that explanations are genuine and reliable. Conversely, explanations can help identify vulnerabilities in models, making them more robust. Concept-Based Explanations: Instead of just feature importance, some XAI approaches focus on identifying and explaining which human-understandable "concepts" (e.g., "stripes" in an image classifier for zebras) influence a model's decision, making explanations more intuitive.Lingering Challenges:Quantifying Explanation Quality: How do we objectively measure if one explanation is "better" than another? Metrics for fidelity (how accurately the explanation reflects the black box) and comprehensibility (how well humans understand it) are still under active development. Scalability: Generating explanations for massive, high-dimensional datasets or extremely complex models can be computationally expensive and time-consuming, hindering real-time applications. The "Trade-off" Conundrum: The inherent tension between model accuracy and interpretability often persists. While XAI aims to mitigate this, achieving both simultaneously at peak levels remains a significant challenge. Misleading Explanations: A poorly designed or maliciously crafted explanation can be more dangerous than no explanation at all, providing a false sense of security or justification. Ensuring the trustworthiness of explanations is paramount.The future of XAI lies in developing methods that are not only technically sound but also practically deployable, scalable, and genuinely useful to a diverse range of human users. It's a journey from simply knowing what an AI predicts to truly understanding why, ushering in an era of more responsible, transparent, and trustworthy artificial intelligence. This is not just about building better algorithms; it's about building better human-AI partnerships. # Conceptual Python snippet for a Causal XAI setup (simplified for illustration) # This code aims to demonstrate the concept of causal reasoning in a simple scenario. # Real causal inference requires careful design, domain knowledge, and specific libraries (e.g., DoWhy, CausalPy).import numpy as np import pandas as pd from sklearn.linear_model import LogisticRegression# Simulate data with a known causal structure # Assume 'feature_A' causally influences 'feature_B', which then influences 'target'. # And 'feature_C' directly influences 'target'.np.random.seed(42) num_samples = 1000feature_A = np.random.normal(loc=10, scale=2, size=num_samples) # e.g., Education level feature_B = feature_A * 0.5 + np.random.normal(loc=0, scale=1, size=num_samples) # e.g., Income, causally linked to Education feature_C = np.random.normal(loc=5, scale=1.5, size=num_samples) # e.g., Skill level, independent of A/B# Target: Probability of getting a job offer # Assume: Higher income (B) and higher skill (C) increase job offer probability. # A also indirectly affects target via B. prob_target = 1 / (1 + np.exp(-(0.2 * feature_B + 0.5 * feature_C - 5))) target = (np.random.rand(num_samples) < prob_target).astype(int)df_causal = pd.DataFrame({ 'feature_A': feature_A, 'feature_B': feature_B, 'feature_C': feature_C, 'target': target })# Train a simple model to predict 'target' X_causal = df_causal[['feature_A', 'feature_B', 'feature_C']] y_causal = df_causal['target']model_causal = LogisticRegression(solver='liblinear', random_state=42) model_causal.fit(X_causal, y_causal)print("Logistic Regression Coefficients:") for i, feature in enumerate(X_causal.columns): print(f" {feature}: {model_causal.coef_[0][i]:.4f}")print("\nCausal XAI Insight (Conceptual):") print("Traditional XAI (like feature coefficients here) shows feature_A has a positive correlation with target.") print("However, Causal XAI would aim to show that feature_A's *direct causal effect* on target is negligible,") print("and its influence is primarily *mediated* through feature_B.") print("This distinction is crucial for understanding true drivers and for policy interventions.") print("For instance, increasing 'feature_A' might only benefit 'target' if it successfully boosts 'feature_B'.")This conceptual example highlights that a simple coefficient (correlation) doesn't always reveal the underlying causal chain. Causal XAI aims to unravel these deeper relationships for more robust and trustworthy explanations. XAI Methodologies: A Comparative Overview Understanding the strengths and weaknesses of different XAI approaches is crucial for selecting the right tool for a specific task. Here's a brief comparative table summarizing key methodologies discussed:Methodology Type of Explanation Model-Agnostic/Specific Pros Cons Best Use CasesLIME Local Model-Agnostic Provides intuitive, local explanations; easy to understand for diverse audiences. May not be stable (small perturbations can lead to different explanations); can be computationally intensive for complex models; local fidelity doesn't guarantee global understanding. Explaining individual predictions for non-technical users; debugging specific errors.SHAP Local & Global Model-Agnostic Theoretically sound (game theory based); unified framework for various models; provides both local and global insights. Computationally expensive for many instances or features (especially exact SHAP); can be difficult to interpret the exact meaning of a SHAP value without context. Auditing model fairness and bias; comprehensive understanding of feature contributions; regulatory compliance.Permutation Feature Importance (PFI) Global Model-Agnostic Simple to implement and understand; highlights the most impactful features globally. Only provides global insights; doesn't explain individual predictions; can be misleading if features are highly correlated; computationally expensive if many permutations are run. Feature selection; model debugging at a global level; understanding overall model behavior.Partial Dependence Plots (PDP) Global Model-Agnostic Visualizes marginal effect of one or two features on prediction; intuitive for understanding trends. Assumes feature independence (can be misleading if strong correlations exist); only shows average effect (hides individual variations). Understanding general trends and relationships between features and predictions.Individual Conditional Expectation (ICE) Local (aggregated) Model-Agnostic Disaggregates PDPs, revealing individual instance variations and heterogeneity. Can become cluttered with too many instances; still assumes feature independence for its interpretation; can be noisy. Identifying heterogeneous effects not visible in PDPs; deeper individual trend analysis.Decision Trees Inherently Interpretable Model-Specific Directly human-readable rules; easy to visualize decision paths; no post-hoc explanation needed. Can be prone to overfitting; performance often lower than complex black-box models; complex trees become difficult to interpret. Simple, auditable decisions in low-stakes or regulatory environments; baseline interpretability.Generalized Additive Models (GAMs) Inherently Interpretable Model-Specific Provides interpretable non-linear relationships for each feature independently; better predictive power than linear models. Interpretation of smooth functions can be slightly less intuitive than linear coefficients; computational complexity increases with number of features and basis functions. Predictive tasks requiring non-linear relationships with high interpretability; medical applications.This table provides a concise reference for navigating the XAI landscape, emphasizing that the "best" method often depends on the specific requirements of the AI application and the audience for the explanation. Conclusion & The Path Forward to Trustworthy AI The journey into Explainable AI is not merely a technical endeavor; it is a fundamental shift towards building trustworthy, accountable, and ethical AI systems. We've explored the profound imperative for transparency, delved into the powerful techniques like LIME and SHAP that demystify individual predictions, examined the architectural elegance of inherently interpretable models, and discussed how to operationalize XAI within robust MLOps pipelines. From the regulatory demands of GDPR to the critical need for bias detection and model debugging, XAI stands as the indispensable bridge between complex algorithms and human understanding. As an AI researcher, I'm particularly excited by the emerging frontiers of XAI – causal inference, human-centered design, and multimodal explanations – which promise to unlock even deeper levels of understanding and collaboration between humans and AI. While challenges remain, notably in quantifying explanation quality, ensuring scalability, and guarding against misleading interpretations, the trajectory is clear: XAI will become an increasingly integral part of every responsible AI development lifecycle. The future of AI is not just about intelligence; it's about intelligent systems we can trust. By embracing Explainable AI, we empower developers to build better, fairer models; we equip regulators to ensure compliance; and most importantly, we enable end-users to understand, question, and ultimately, confide in the AI that shapes their world. This commitment to transparency is how we truly unlock the full, benevolent potential of artificial intelligence.#ExplainableAI #XAI #AIEthics #MachineLearning #TrustworthyAI #MLOps #AIResearch Related InsightsLow-Code/No-Code Platforms: Empowering Citizen Developers and Accelerating Innovation Energy-Harvesting IoT: Powering Sensors Without Batteries Using Ambient Intelligence and Self-Sustaining Circuits Beyond the Horizon of 5G: Unlocking the Secrets of 6G Wireless Standards{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Beyond the Veil: Unpacking AI's Black Box for Unprecedented Trust & Transparency with XAI?", "acceptedAnswer": { "@type": "Answer", "text": "Explore Explainable AI (XAI) with Claire Beaufort. Dive deep into methods, tools, and real-world applications demystifying complex AI for trust, compliance, and innovation." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Beyond the Veil: Unpacking AI's Black Box for Unprecedented Trust & Transparency with XAI?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Claire Beaufort." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
In the grand tapestry of human indulgence, few threads gleam with the profound richness and complex history of chocolate. It is a substance that transcends mere sustenance, weaving itself into the fabric of ritual, luxury, and daily comfort across continents and millennia. From the verdant embrace of the cacao tree, born of ancient earth and sun, emerges a foodstuff capable of myriad forms – a liquid, a solid, a paste – each a testament to its singular versatility and unparalleled allure. This journey, from a bitter, ceremonial brew in the heart of Mesoamerica to the ubiquitous bars and confections savored worldwide, is a narrative steeped in innovation, cultural exchange, and a relentless pursuit of culinary perfection. The Elixir of Ages: Cacao's Ancient Whispers and Contentious Names The story of chocolate begins not with the sweet, familiar squares of today, but with the venerable Theobroma cacao tree, whose processed seeds, known as cocoa beans, hold the very essence of this global phenomenon. Its genesis as a food source stretches back an astonishing 5,300 years, taking root in what is now southeastern Ecuador, cultivated by the Mayo-Chinchipe culture long before its introduction to the more widely recognized Mesoamerican civilizations. While the precise moment chocolate, as distinct from other cacao-based libations, first tantalized human palates remains shrouded in the mists of antiquity, evidence suggests the Olmecs, foundational figures of Mesoamerican civilization, engaged with cacao in a fascinating way: fermenting the sweet pulp surrounding the beans into an alcoholic beverage. For the vibrant societies of Mesoamerica – the Mayans, the Aztecs, and others – cacao was far more than a simple crop; it was a sacred gift from the gods, imbued with profound spiritual and practical significance. The precious cocoa bean served as a form of currency, a testament to its intrinsic value, facilitating commerce across diverse civilizations. It played an integral role in solemn ceremonies, offered as a revered tribute to leaders and deities, and even revered for its medicinal properties. The chocolate of this era, however, was a stark contrast to its modern descendant. It manifested as a bitter drink, meticulously flavored with indigenous additives such as vanilla, the subtle pungency of earflower, and the fiery kick of chili. A distinctive characteristic was the dark brown foam that crowned the beverage, meticulously created by pouring the liquid from a height, often between ornate containers, a performance of both craft and reverence. The very word "chocolate" carries with it a history as intricate and layered as the flavors of its namesake. First recorded in Spanish in 1579 and subsequently borrowed into English by 1604, its etymological roots remain a subject of scholarly contention. A popular, yet likely inaccurate, belief attributes its origin to the Nahuatl word chocolatl. However, early texts that genuinely document the Nahuatl term for a chocolate drink consistently employ a different word: cacahuatl, meaning "cacao water." This linguistic divergence compels a deeper exploration into its true etymology. Several alternative theories have been posited to unravel this linguistic enigma. One suggests a derivation from the hypothetical Nahuatl word xocoatl, meaning "bitter drink," a plausible description of the early Mesoamerican concoction. Yet, scholars Michael and Sophie Coe express skepticism, questioning the phonetic shifts required for the 'sh' sound of 'x' to transform into 'ch', and the unexplained addition of an 'l'. Another theory proposes a Mayan language origin, specifically chocolatl meaning "hot water." However, a critical lack of evidence for the form 'chocol' ever independently signifying 'hot' casts doubt upon this hypothesis. Despite the persistent uncertainty surrounding a direct Nahuatl origin, a degree of scholarly consensus points towards the Nawat word chikola:tl as the more probable source. The precise meaning of chikola:tl itself remains debated; some propose it means "cacao-beater," referencing the traditional act of whisking cocoa to create its signature foam, though the meaning of 'chico' within this context is unknown. Anthropologist Kathryn Sampeck offers an intriguing perspective, suggesting that "chocolate" originally denoted a specific cacao beverage among many, notably one that included annatto and was produced in what is now Guatemala. According to Sampeck's research, this particular term evolved to become the generic word for all cacao beverages around 1580, coinciding with the period when the Izalcos people of that region were the most prominent producers of cacao, thereby solidifying its linguistic footprint.From Sacred Brew to European Craze: The Transatlantic Leap The first documented European encounter with chocolate is often attributed to the formidable Spanish conquistador Hernán Cortés, who, in 1520, observed the enigmatic beverage being consumed in the court of Moctezuma II. For European palates accustomed to different flavors, this bitter, spiced drink proved to be an acquired taste, requiring time and adaptation to gain favor. It was not until 1585 that the first official record of a shipment of cocoa beans to Europe marked the beginning of chocolate's transatlantic journey. Initially, chocolate arrived veiled in an aura of exoticism and perceived potency. It quickly garnered a reputation as an aphrodisiac and a potent medicine, beliefs that undoubtedly fueled its dissemination across the continent. By the 17th century, chocolate had firmly established itself in European society, albeit in a markedly transformed state. To appeal to European tastes, it was sweetened, served warm, and infused with familiar spices, a far cry from the unadulterated bitter brew of its Mesoamerican origins. Religious orders, particularly those with extensive networks, played a significant, albeit often understated, role in its spread, contributing to its distribution and adaptation across various monastic and aristocratic circles. For centuries, chocolate remained largely the purview of the elite. The prohibitive cost of cocoa, sourced from colonial plantations established across the Americas, ensured its status as a luxury commodity. Throughout the 18th century, chocolate solidified its identity as a quintessentially southern European, aristocratic, and often Catholic indulgence, its production methods largely mirroring those employed by the Aztecs centuries prior, reflecting a blend of ancient tradition and nascent European refinement. The Industrial Revolution: Forging a Solid Future The 18th century heralded a new era for chocolate, as production methods began to see incremental improvements. However, it was the seismic shifts of the 19th century, driven by the fervor of the Industrial Revolution, that truly revolutionized chocolate's trajectory, transforming it from a niche, hand-crafted delicacy into a mass-consumed staple. The advent of engine-powered milling significantly streamlined the initial stages of processing, paving the way for greater efficiency. A pivotal moment arrived in 1828 with Coenraad Johannes van Houten's groundbreaking patent for a hydraulic press. This ingenious invention allowed for the revolutionary separation of cocoa butter from the chocolate liquor, giving rise to defatted cocoa powder. This innovation was nothing short of foundational, creating the very bedrock upon which the modern solid chocolate industry would be built. The ability to control fat content opened up entirely new possibilities for texture, shelf-life, and form. The 19th century was a crucible of innovation for chocolate production. The development of the melanger, a sophisticated mixing machine, further refined the texture and consistency of chocolate. The creation of modern milk chocolate introduced a new category of sweetness and creaminess, broadening its appeal immeasurably. Perhaps most crucially, the invention of the conching process – a prolonged kneading and aerating of chocolate paste – meticulously smoothed its texture and subtly altered its flavor profile, enhancing its melt-in-the-mouth quality and complexity. These technological advancements collectively magnified productivity to an astonishing degree: by 1890, a single worker could produce fifty times more chocolate using the same amount of labor than before the Industrial Revolution. This surge in efficiency fundamentally altered chocolate's identity, firmly transitioning it from a cherished beverage to a solid food, readily eaten and enjoyed. Concurrently, the global supply chain for cocoa beans began to shift dramatically. As mass markets for chocolate exploded across Western nations, production of the raw material increasingly migrated from the Americas to the burgeoning cocoa-growing regions of Asia and, most significantly, Africa. Today, West African countries, particularly Ivory Coast and Ghana, stand as the titans of global cocoa supply, collectively contributing approximately 60% of the world's cocoa, a testament to this profound historical shift.Modern Mosaics: Varieties, Ethics, and Innovation The 20th century, while marked by continued innovation, also brought ethical complexities to the forefront of the chocolate industry. Early in the century, British chocolate producers like Cadbury and Fry's faced significant controversy regarding the deplorable labor conditions prevalent in the Portuguese cacao industry in Africa. A searing 1908 report by a Cadbury agent starkly described these conditions as "de facto slavery." While a subsequent boycott by chocolate makers led to some improvements, the pervasive issue of slave labor among African cacao growers tragically resurfaced in the public consciousness in the early 21st century, reminding the industry of its enduring ethical responsibilities. Despite these grave concerns, technological progress continued apace, further refining the art and science of chocolate making. The development of the tempering technique became essential, carefully controlling temperature to ensure that chocolate achieved the desired crystalline structure, resulting in its characteristic satisfying "snap" and lustrous gloss. The addition of lecithin, an emulsifier, further improved chocolate's texture and consistency, making it smoother and more stable. The 20th century also witnessed the development of specific chocolate types such as white chocolate – made solely from cocoa butter, milk, and sugar, conspicuously lacking the non-fat cocoa solids found in other varieties – and couverture chocolate, renowned for its high cocoa butter content, ideal for professional coating and tempering. Furthermore, the emergence of the "bean-to-bar" trade model began to emphasize greater transparency and direct relationships between growers and producers, marking a significant evolution in how chocolate is sourced and crafted. At its core, chocolate is born from roasted and ground cocoa beans. It is a chameleon, taking liquid, solid, or paste forms, eaten on its own, or serving as an exquisite flavor enhancer for countless other foods. The process, an alchemical dance of fermentation, drying, cleaning, roasting, and grinding nibs into chocolate liquor, forms the basis of all chocolate. This liquor can be further processed into cocoa butter and cocoa powder, or shaped and sold as pure, unsweetened baking chocolate. The introduction of sugar transforms it into sweetened chocolates, which, when sold without milk, become the sophisticated dark chocolate. With the addition of milk, it blossoms into the beloved milk chocolate. White chocolate, a distinct category, contains only cocoa butter and milk, eschewing cocoa solids entirely. Today, chocolate reigns supreme as one of the most popular food types and flavors globally, an omnipresent delight in desserts ranging from ice creams and cakes to mousses and cookies. Candies are frequently filled with or coated in its sweetened embrace, and solid chocolate bars or those encasing other ingredients are cherished as convenient snacks. Its symbolic power is undeniable, with chocolate molded into festive shapes like eggs, hearts, and coins, becoming cherished traditional gifts for holidays such as Christmas, Easter, Valentine's Day, Hanukkah, and Eid al-Fitr. Beyond solid forms, chocolate endures in cold and hot beverages, from the comforting simplicity of chocolate milk and hot chocolate to the indulgent complexity of chocolate liqueur. The journey of chocolate is a saga of transformation – from a sacred, bitter brew cradled in ancient civilizations to a global phenomenon shaped by industrial prowess and ethical considerations. It remains a profound testament to human ingenuity and our enduring quest for both sustenance and sublime pleasure, a dark heart beating at the very core of culinary history.#ChocolateHistory #CacaoCulture #DemirŞef #FoodScience #GourmetChocolate Related InsightsL'Alchimie du Levant : Quand l'Histoire se Déguste en Mezze The Wild Yeast Revolution: Beyond the Loaf into the World of Fermented Alchemy Dan Dan Noodles: The Ultimate Szechuan Street Bowl{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of The Obscure Origins and Transcendent Transformation of Cacao's Dark Heart?", "acceptedAnswer": { "@type": "Answer", "text": "Embark on a profound journey through chocolate's ancient roots, its Mesoamerican reverence, European transformation, and the industrial innovations that shaped this beloved global delicacy." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on The Obscure Origins and Transcendent Transformation of Cacao's Dark Heart?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Demir Şef." } }, { "@type": "Question", "name": "Where can I find more related content about Food?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Food category page." } } ] }
Language, in its essence, is a tapestry woven from sound, symbol, and soul – a unique lens through which humanity perceives and articulates its existence. But what happens when these intricate tapestries, each rich with the dyes of a specific culture and history, must be re-woven into a foreign fabric? This is the profound, often invisible, alchemy of literary translation: not merely a transfer of words, but a transmigration of spirit, intent, and artistic resonance from one linguistic cosmos to another. It is an endeavor that demands not only linguistic mastery but also a profound empathy, a critical ear, and the soul of a poet. The act of translation, particularly within the realm of literature, transcends a simplistic word-for-word conversion. It is an interpretive art, a delicate balance struck between fidelity to the source and resonance with the target. The literary translator is neither a stenographer nor a usurper, but a bridge-builder, a cultural cartographer, and ultimately, a co-creator. They embark on a perilous yet exhilarating journey, navigating the treacherous waters of syntax, metaphor, and cultural nuance, striving to deliver not just the narrative, but the very heartbeat of the original work to a new readership. Without these tireless architects of understanding, the vast, shimmering wealth of global literature would remain confined within its birthplace, inaccessible and unheard. The Translator as Alchemist: Beyond Mere Words To understand literary translation, one must first dismantle the common misconception that it is a mechanical process. Imagine attempting to render a complex musical score into a new key, not just note-for-note, but preserving its emotional arc, its thematic development, its subtle modulations of tempo and timbre. This analogy barely scratches the surface of the translator's task. Each word in a literary text is not an isolated unit but a node in a vast, interconnected network of meaning, association, and cultural baggage. It carries echoes of its etymology, whispers of its common usage, and often, specific connotations unique to its linguistic environment. The translator, therefore, must possess a formidable arsenal of skills. Foremost is an impeccable command of both the source and target languages, extending far beyond dictionary definitions to embrace idiom, colloquialism, dialect, and register. Yet, linguistic prowess is merely the foundation. What truly elevates a literary translator is their deep literary sensibility: an acute awareness of style, rhythm, cadence, imagery, and the author's unique voice. They must be able to discern the subtle irony hidden in a phrase, the poetic echo of an alliteration, the deliberate ambiguity of a chosen word, and then, crucially, find an equivalent expression that evokes a similar effect in the new language. Consider the challenge of translating humor, which is often deeply rooted in linguistic play, cultural references, or social conventions. A pun that sparkles brilliantly in French might fall utterly flat in English, requiring the translator to invent a new pun that captures the spirit and comedic timing, even if it deviates structurally from the original. Similarly, cultural allusions, historical context, or specific social hierarchies depicted in the source text must be subtly conveyed to a target audience that may lack the same shared knowledge. This requires not just linguistic transfer, but cultural mediation and, at times, judicious explanation or adaptation.The Fidelity Paradox: An Impossible Perfection One of the central dilemmas in literary translation is the concept of "fidelity." To what or whom should the translator be faithful? To the literal meaning of the words? To the author's original intent? To the cultural context? To the aesthetic effect? Or to the sensibilities and expectations of the new reader? The truth is, perfect fidelity across all these dimensions is often an impossible dream, a tantalizing paradox. Every translation is, by its very nature, an interpretation, a new creation born from the original. The translator walks a tightrope between domestication and foreignization. Domestication seeks to make the foreign text familiar and accessible to the target reader, potentially smoothing out cultural rough edges or adapting references to suit local understanding. Foreignization, conversely, aims to preserve the "foreignness" of the original, challenging the reader to cross cultural boundaries and experience the text on its own terms, even if it means confronting unfamiliar concepts or linguistic structures. Both approaches have their merits and their critics, and the choice often depends on the specific text, the translator's philosophy, and the intended audience. For poetry, the challenge intensifies exponentially. Here, meaning is often inseparable from form – from meter, rhyme, alliteration, assonance, and the very sound of the words. To translate a poem is to attempt to rebuild a sonic and semantic edifice with entirely different materials. A literal translation might capture the prose meaning but utterly destroy the poem's musicality and emotional impact. Conversely, a translator might prioritize rhythm and rhyme, potentially sacrificing some literal meaning. The translator of poetry must be a poet in their own right, capable of recreating not just the poem's content but its very essence, its unique aesthetic force. This is where the translator’s creativity truly shines, transforming words into echoes that resonate with similar power. The Invisible Labor: Shaping World Literature Despite the immense skill and artistry required, the literary translator often remains an unsung hero. Their name, if present, is usually relegated to a small print on the title page, while the author's name takes center stage. This "invisibility" belies their profound impact. Each translated work opens a window to a different world, a different way of thinking, feeling, and articulating. It enriches the target language, introducing new ideas, literary forms, and narrative techniques. Without translation, our literary landscape would be barren, devoid of the vibrant colors contributed by Kafka, García Márquez, Tolstoy, or Murasaki Shikibu. Literary translation is not merely an act of linguistic conversion; it is an act of cultural diplomacy. It fosters understanding, breaks down barriers, and allows different cultures to converse, debate, and empathize with one another. It introduces readers to narratives that challenge their perspectives, expand their empathy, and reveal the shared human experience that transcends geographical and linguistic divides. In an increasingly interconnected yet often fragmented world, the role of the literary translator becomes not just important, but imperative. They are the conduits through which global consciousness is shaped and enriched. The process itself is rigorous, often involving multiple drafts, extensive research into historical periods, cultural contexts, and authorial biographies. A translator might spend months, even years, immersed in a single work, grappling with its complexities, consulting experts, and refining every phrase until it feels just right. This iterative process of reading, interpreting, writing, and revising is the crucible in which a compelling translation is forged. It demands patience, meticulous attention to detail, and an unwavering commitment to both the source author and the target reader.The Future of Translation: Beyond the Algorithm In an era increasingly dominated by artificial intelligence, questions inevitably arise about the future of human literary translation. While machine translation tools have made astounding progress in processing vast amounts of text and providing rudimentary translations, they are fundamentally limited in their capacity to grasp the nuanced subtleties of literary art. AI can process syntax and lexicon; it struggles profoundly with irony, metaphor, cultural connotation, aesthetic effect, and the author's unique voice – elements that are the very lifeblood of literature. A machine can translate the words of a poem, but it cannot translate its music, its emotional resonance, or the complex interplay of sound and meaning that makes it art. It lacks the human capacity for empathy, cultural intuition, and the creative leap required to find an equivalent that works artistically in another language. Literary translation remains a deeply human endeavor, requiring a consciousness that understands not just what is said, but what is implied, what is felt, and what is intended to be evoked. The future of literary translation, therefore, will likely see human translators leveraging AI tools for initial drafts or research, but the ultimate act of crafting a truly resonant and faithful literary work will remain firmly in the hands of skilled human artists. These translators will continue to be the essential guides who lead us across linguistic chasms, allowing us to walk in the footsteps of characters from distant lands and times, to grapple with ideas born in foreign minds, and to revel in the universal beauty of human expression, regardless of its original tongue. Their work is a testament to literature's boundless power and humanity's unceasing quest for connection. The enduring magic of a beautifully translated book lies in its ability to transcend its foreign origins and resonate as profoundly as if it were conceived in one's native tongue. It is a testament to the translator's profound artistry and the enduring human spirit's desire to share, to understand, and to be understood across all barriers. Each translated word is a thread, painstakingly re-spun, adding to the rich, interconnected tapestry of global human storytelling, ensuring that no voice, no story, is ever truly lost to the winds of time or the boundaries of language.#LiteraryTranslation #BookTranslation #CulturalExchange #Literature #ArtOfTranslation Related InsightsThe Long Walk Book Review and Summary The Isle of Lonely Monsters Book Review and Summary The Chinese Lady Book Review and Summary{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Echoes Across Chasms: The Art and Imperative of Literary Translation?", "acceptedAnswer": { "@type": "Answer", "text": "Delve into the profound artistry and critical importance of literary translation, exploring its challenges, triumphs, and the invisible labor that reshapes worlds across languages." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Echoes Across Chasms: The Art and Imperative of Literary Translation?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Aylin Okur." } }, { "@type": "Question", "name": "Where can I find more related content about Books?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Books category page." } } ] }
Imagine a smart home that anticipates your needs, understands complex voice commands, and recognizes your face at the door—all without sending a single byte of your personal data to a corporate server. Until recently, this level of intelligence required the massive computing power of cloud data centers. But the rapid miniaturization of neural processing units (NPUs) and the optimization of open-source models have ushered in a new era: The Edge AI Smart Home. As a robotics engineer with a background in autonomous systems, I view the home as the ultimate localized robotic environment. Relying on cloud infrastructure for critical home operations is not just a privacy risk; it's an architectural flaw. #Robotics #AutonomousVehicles In this comprehensive, step-by-step guide, we will explore how to architect, hardware-provision, and deploy a privacy-first smart home using Edge AI hubs. We will cut the cord to the cloud and bring the brain of the operation directly into your living room. #EdgeAI #IoT What is Edge AI in the Context of a Smart Home? "Edge computing" means processing data at or near the source of data generation, rather than sending it across the internet to a centralized cloud. When we add "AI" to the mix, we are talking about running machine learning models—such as computer vision for security cameras or Large Language Models (LLMs) for voice assistants—locally on hardware physically located inside your home. The Three Pillars of Edge AI Privacy:Zero Data Exfiltration: Your audio recordings, video feeds, and daily routines never leave your local area network (LAN). Infinite Uptime: Because processing is local, your voice commands and automations work flawlessly even during internet outages. Instant Latency: Processing an image or a voice command locally takes milliseconds, compared to the round-trip latency of cloud APIs.Step 1: Choosing the Right Hardware for the Hub You cannot run advanced AI models on a standard $30 smart hub. You need compute power, specifically hardware optimized for AI inference. The Entry Level: Raspberry Pi 5 with an AI Accelerator The Raspberry Pi 5 is incredibly capable, but for Edge AI, you need to pair it with an accelerator like the Google Coral USB Accelerator or a Hailo-8 M.2 module. These specialized chips (TPUs/NPUs) can perform trillions of operations per second (TOPS), making them perfect for local object detection on camera feeds. The Power User: The N100 Mini PC or Mac Mini M-Series For running local LLMs (like Llama 3 8B or Mistral) to process natural language voice commands locally, you need significant RAM and a powerful CPU/GPU. A refurbished Mac Mini M1/M2 (due to its unified memory architecture) or an Intel N100-based Mini PC running Proxmox is the sweet spot for budget-conscious edge computing in 2026. Step 2: The Operating System - Proxmox and Home Assistant OS To maximize efficiency, we will use a hypervisor. Proxmox Virtual Environment (VE) allows you to split your Mini PC into multiple isolated virtual machines (VMs). Install Proxmox on your Mini PC via a bootable USB. Deploy Home Assistant OS (HAOS) as a primary Virtual Machine. HAOS will act as the central nervous system connecting all your IoT devices.Terminal Command: HAOS Proxmox Installation Script The community has created brilliant automation scripts for this. Log into your Proxmox web shell and execute: bash -c "$(wget -qLO - https://github.com/tteck/Proxmox/raw/main/vm/haos.sh)"Follow the prompts to allocate RAM (minimum 4GB) and storage (minimum 32GB). Within minutes, your local Home Assistant instance will be running. Step 3: Local Computer Vision with Frigate NVR Cloud cameras like Ring or Nest upload your continuous video feeds to external servers, analyze them for human movement, and send you a notification. We will replace this with Frigate, an open-source Network Video Recorder (NVR) built specifically for real-time local object detection. Frigate integrates directly into Home Assistant and utilizes the Google Coral TPU (which you plugged into your Mini PC) to analyze RTSP video streams from local, offline IP cameras (like Reolink or Amcrest). Sample Frigate Configuration (frigate.yml): mqtt: host: 192.168.1.100 detectors: coral: type: edgetpu device: usb cameras: front_door: ffmpeg: inputs: - path: rtsp://admin:password@192.168.1.50:554/h264Preview_01_main roles: - detect - rtmp detect: width: 1920 height: 1080 objects: track: - person - dog - carBecause the Coral TPU runs the inference locally, the moment a person steps onto your porch, the AI detects it in milliseconds, triggers a Home Assistant automation to turn on the porch light, and sends a snapshot to your phone via an encrypted local push notification—zero cloud required. #DataSecurityStep 4: Local Voice Processing (The Holy Grail) Voice assistants are the biggest privacy offenders. To replace them, we use the Home Assistant Assist pipeline, powered by local Whisper (for Speech-to-Text) and Piper (for Text-to-Speech). If you have a powerful enough Edge Hub (like an M2 Mac Mini or a machine with an Nvidia RTX GPU), you can route the transcribed text through a local LLM using Ollama. Running Ollama locally: # Install Ollama on your Linux VM curl -fsSL https://ollama.com/install.sh | sh# Pull a lightweight, highly capable model ollama run llama3:8bBy connecting Home Assistant to your local Ollama instance via the "Extended OpenAI Conversation" integration (pointing the API URL to http://localhost:11434/v1), your home becomes truly intelligent. You don't have to say rigid commands like "Turn on living room light." You can say, "It's getting a bit dark in here, and I want to read a book." Your local Edge AI processes the intent, understands you are in the living room, realizes reading requires light, and autonomously turns on the reading lamp. Step 5: Network Isolation (VLANs) The final, and most crucial, step in a privacy-first smart home is network isolation. Even if you don't use cloud services, many cheap IoT devices (like smart plugs or Wi-Fi bulbs) have hardcoded telemetry that constantly tries to "phone home" to servers in foreign countries. You must configure your router (using pfSense, OPNsense, or Unifi) to create an IoT VLAN.Move all IoT hardware to this separate Wi-Fi network. Create a firewall rule that Blocks all traffic from the IoT VLAN to the WAN (Internet). Create a rule that allows your Home Assistant server to initiate communication with the IoT VLAN.Now, your devices are trapped. They cannot spy on you, they cannot update their firmware without your permission, and they cannot be compromised by external botnets. They exist purely to serve your local Edge AI hub. The Future is Local Building an Edge AI smart home requires more upfront effort than simply plugging in a Google Nest Hub. It requires tinkering with Docker containers, writing YAML, and managing subnets. However, the reward is absolute digital sovereignty. Your home becomes a fortress of privacy. Your automations execute with lightning speed. And you are utilizing cutting-edge neural processing technology exactly where it belongs: at the edge, serving you, and only you. Welcome to the true definition of a "Smart" Home.Have questions about hardware requirements or Proxmox setups? Let me know in the comments, and I'll help you architect your local edge server! Related InsightsAlgorithmic Sovereignty: Deconstructing the DAO Paradox in On-Chain Governance Revolutionizing Autonomous Task Execution: The Evolution of Large Action Models (LAMs) Holographic Displays: The Silent Revolution Reshaping AR/VR, 3D Visualization, and Human-Computer Interaction{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of How to Set Up a Privacy-First Smart Home Using Edge AI Hubs?", "acceptedAnswer": { "@type": "Answer", "text": "Learn how to build a 100% private smart home utilizing Edge AI hubs, local LLMs, and secure hardware without relying on external cloud servers." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on How to Set Up a Privacy-First Smart Home Using Edge AI Hubs?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Kaan Demir." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Alexander Vance
- 12 Jul, 2026 10:05
Top 10 Agentic AI SaaS Tools Transforming Developer Workflows in 2026
The software development lifecycle has undergone a seismic shift. If 2023 was the year of "Generative AI" acting as a smart autocomplete, 2026 is undoubtedly the era of Agentic AI. We have moved past prompting chat interfaces to write isolated functions; today, developers manage autonomous AI agents that proactively debug, refactor entire codebases, manage pull requests, and orchestrate complex deployments across multiple SaaS platforms. As an AI architect who has watched this evolution closely from within the walls of Silicon Valley, I can confirm that "Agentic AI" is not just a buzzword—it is a fundamental restructuring of how engineering teams operate. According to recent papers published on arXiv, development teams utilizing autonomous agents report a 40% reduction in time-to-merge for complex pull requests. #ArtificialIntelligence #SoftwareEngineering In this comprehensive guide, we will explore the top 10 Agentic AI SaaS tools that are fundamentally transforming developer workflows, complete with case studies and implementation examples. What makes an AI "Agentic"? Before diving into the tools, we must define the term. A standard Large Language Model (LLM) is reactive: you ask a question, it provides an answer. An Agentic AI is proactive and goal-oriented. It possesses the following capabilities:Tool Use: It can interact with external APIs, run terminal commands, and query databases. Reasoning & Planning: It breaks down complex, ambiguous goals into step-by-step execution plans. Memory: It remembers context across long sessions, maintaining an understanding of the entire repository architecture. Autonomy: It can execute loops, correct its own errors when a script fails, and continue working without human intervention until the primary goal is achieved.Let's look at the SaaS platforms leading this revolution.1. Devin by Cognition (Enterprise Tier) Devin remains the gold standard for autonomous software engineering. Unlike IDE plugins, Devin operates in its own secure cloud environment equipped with a terminal, browser, and code editor. Case Study: Legacy Migration A startup recently used Devin to migrate a monolithic Node.js backend to a serverless Cloudflare Workers architecture. Instead of writing code line-by-line, the lead engineer provided Devin with the GitHub repository URL and a prompt: "Migrate the /api/users endpoints to Cloudflare Workers using Hono.js. Ensure all PostgreSQL queries are compatible with Prisma Accelerate." Devin autonomously cloned the repo, read the documentation for Hono.js, rewrote the routes, installed the necessary dependencies via npm, ran the local test suite, observed a failing test due to a missing environment variable, fixed it, and submitted a pristine Pull Request. #TechStartups 2. GitHub Copilot Workspace GitHub has evolved Copilot from an IDE autocomplete tool into a full-fledged agentic workspace. Copilot Workspace allows developers to start a project from a GitHub Issue. The AI reads the issue, proposes a specification, generates a step-by-step plan, and executes the code changes across multiple files simultaneously. Terminal Integration Example: You can now ask the GitHub CLI to execute agentic tasks. gh copilot execute "Find all instances of the deprecated moment.js library in the frontend directory and replace them with date-fns, then run the linter and fix any formatting issues."The agent handles the regex searching, the AST parsing, the dependency replacement, and the execution of npm run lint --fix. 3. AutoGPT Pro (SaaS Edition) Originally an open-source experiment, AutoGPT has matured into a robust SaaS platform for developers. It excels at workflow automation that spans outside the codebase. For instance, AutoGPT Pro can be wired to your Jira and Slack. When a critical bug is reported in Jira, the agent reads the stack trace, pulls the relevant logs from Datadog via API, identifies the offending commit in GitLab, writes a patch, and posts a summary of the fix in the engineering Slack channel, awaiting human approval to merge. #AIAutomation 4. Cursor IDE (Agent Mode) While technically an editor (a fork of VS Code), Cursor's new "Agent Mode" functions as a SaaS backend that deeply understands your local workspace. It doesn't just suggest code; it navigates your file tree, reads your terminal output, and understands your project's specific conventions. If you run a build command and it fails with a cryptic Webpack error, you don't need to copy-paste the error. You simply press Cmd+K and type "Fix the build." The Cursor Agent reads the terminal output, identifies the conflicting dependency, updates your package.json, runs npm install, and restarts the dev server. 5. Sweep AI Sweep AI focuses exclusively on eliminating technical debt and handling minor feature requests. You install it as a GitHub application. When you create an issue with the label sweep, the AI agent wakes up, reads the issue, branches the code, writes the feature, and opens a PR. Implementation Step: To integrate Sweep into your CI/CD pipeline, you simply configure a sweep.yaml in your repository root defining the rules it must follow (e.g., "Always use TypeScript strict mode," "Never modify the core database schema without adding a migration file").6. Vercel v0 (Agentic Iteration) Vercel's v0 started as a UI generator, but its 2026 iteration acts as an agentic frontend developer. You provide it with a Figma link or a textual description, and it generates production-ready React/Next.js code using Tailwind CSS and Shadcn UI components. What makes it agentic is its ability to iterate. You can tell it, "The login form looks good, but wire it up to our Supabase authentication backend and handle the error states." The agent writes the API routes, manages the client-side state, and integrates the authentication tokens autonomously. #WebDevelopment 7. Superblocks AI Agent Superblocks is a platform for building internal tools. Their embedded AI agent allows non-technical founders or operations teams to build complex admin panels simply by describing the data flow. You can instruct the agent: "Create a dashboard that pulls user data from PostgreSQL, shows their subscription status from Stripe, and adds a button to issue a refund." The agent generates the SQL queries, configures the REST API calls to Stripe, and wires the UI components together, drastically reducing the burden on the core engineering team. 8. CodeQL Agent (by GitHub) Security testing has moved from passive scanning to active remediation. The CodeQL Agent doesn't just flag a SQL injection vulnerability; it autonomously generates the patch to fix it. Using Static Application Security Testing (SAST) principles, when a vulnerability is detected during a CI run, the agent opens a PR containing the exact code changes needed to sanitize the inputs, accompanied by an explanation of the exploit it prevented. #CyberSecurity 9. Supabase Studio AI Database administration is inherently risky, but Supabase has integrated an agentic assistant that acts as a senior DBA. If a specific query is slowing down your application, the agent analyzes the query execution plan via PostgreSQL's EXPLAIN ANALYZE and automatically suggests (or safely applies) the optimal composite indices to resolve the bottleneck. -- The agent autonomously identifies missing indices based on production telemetry CREATE INDEX CONCURRENTLY idx_users_email_status ON users (email, status);10. LangSmith by LangChain If you are building AI agents, LangSmith is the essential SaaS tool for debugging them. It provides unprecedented visibility into the thought process of your LLMs. You can trace exactly which external tools your agent decided to use, what data it retrieved, and why it made specific decisions. It is the ultimate observability platform for the new era of agentic software. The Future of the "10x Developer" The concept of the "10x Developer" has always been somewhat mythical. However, Agentic AI is turning this myth into a measurable reality. A single developer, armed with tools like Devin, Cursor, and Sweep AI, can now architect, execute, and maintain systems that previously required an entire pod of engineers. We are transitioning from being code writers to being code reviewers and system architects. The value of an engineer in 2026 is no longer defined by how fast they can type boilerplate React code, but by how effectively they can orchestrate an army of autonomous AI agents to build scalable, secure, and robust software architectures. The companies that embrace this paradigm shift will ship faster and dominate their markets. Those that insist on manual, legacy workflows will simply be left behind. Welcome to the future of development.Which Agentic AI tool has had the biggest impact on your workflow? Drop your experiences and recommendations in the comments below! Related InsightsBeyond the Horizon of 5G: Unlocking the Secrets of 6G Wireless Standards Data Mesh Architecture: Decentralizing Data Ownership for Scalability Data Governance in the Age of AI: Ensuring Ethical and Compliant Data Use{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Top 10 Agentic AI SaaS Tools Transforming Developer Workflows in 2026?", "acceptedAnswer": { "@type": "Answer", "text": "Discover how autonomous Agentic AI SaaS platforms are revolutionizing software development, automating GitHub workflows, and rewriting the rules of coding." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Top 10 Agentic AI SaaS Tools Transforming Developer Workflows in 2026?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Alexander Vance." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
- Lukas Richter
- 12 Jul, 2026 10:00
Home Assistant vs. Google Home in 2026: Why Local Control Wins for Privacy
In an era where every lightbulb, thermostat, and refrigerator demands a Wi-Fi connection and a cloud account, the smart home dream has slowly morphed into a privacy nightmare for many. We've reached 2026, and the landscape of home automation is fractured. On one side, we have tech behemoths like Google and Amazon pushing seamless, cloud-dependent ecosystems. On the other, a rapidly growing coalition of "Geeks," DIY enthusiasts, and privacy advocates championing absolute local control. This isn't just a debate about which voice assistant understands your accent better; it’s a fundamental battle over data sovereignty, latency, and the longevity of the hardware you own. If you've ever experienced the frustration of your smart lights failing because your internet went down, or felt a chill down your spine reading the privacy policy of a $15 smart plug, this deep dive is for you. Today, we are putting Home Assistant, the open-source titan of local control, head-to-head with Google Home, the ubiquitous cloud-based giant. We will explore why local control is winning the privacy war, how to transition your setup, and why relying on the cloud in 2026 is a significant security risk. #SmartHome #CyberSecurity #LocalControl The Fundamental Flaw of the Cloud-Dependent Smart Home To understand why a mass exodus toward local control is happening, we first need to dissect how ecosystems like Google Home, Alexa, and SmartThings (historically) operate. When you ask Google Assistant to turn on the living room lights, here is the typical journey of that command:Your voice is recorded by the smart speaker. The audio file is encrypted and sent to Google's cloud servers. Natural Language Processing (NLP) models in the cloud transcribe and understand the command. Google's server sends a command to the cloud server of your smart light manufacturer (e.g., Tuya, Philips Hue cloud, or TP-Link). The manufacturer's server sends a command back down to your router. Your router tells the lightbulb to turn on.This entire process usually takes less than a second, which is a marvel of modern engineering. However, it introduces three massive points of failure and concern: Latency, Reliability, and Privacy. Latency and Reliability: The "Internet Down" Scenario If your internet Service Provider (ISP) has an outage, your Google Home becomes a very expensive, albeit aesthetically pleasing, paperweight. The lights won't turn on via voice, routines will fail to execute, and your smart home effectively devolves into a "dumb" home. Furthermore, even with a fast connection, round-trip cloud communication introduces micro-latencies that make the smart home feel sluggish compared to a traditional physical switch. The Privacy Paradigm: Who Owns Your Habits? Every time a cloud API is invoked, data is logged. Google, Amazon, and third-party device manufacturers know when you wake up (because you turned on the bathroom light), when you leave for work (because the smart lock engaged), and when you go to bed. In a recent case study analyzing IoT traffic, researchers found that the average cloud-connected smart home pings external servers over 3,000 times a day, often sending telemetry data that the user never explicitly consented to sharing. In a world increasingly wary of data harvesting, handing over the intimate details of your daily routine to advertising companies is a tough pill to swallow. #DataPrivacy Enter Home Assistant: The Local Control Revolution Home Assistant (HA) flips the script entirely. It is an open-source home automation platform designed to run locally on your hardware—usually a Raspberry Pi, an Intel NUC, or a repurposed thin client. With Home Assistant, the brain of your smart home lives inside your house, not in a data center in California. How Local Control Works When you use a local Zigbee switch to trigger a smart light via Home Assistant:The switch sends a local Zigbee radio signal to your Home Assistant hub. Home Assistant processes the automation rule internally. Home Assistant sends a local network command (or another Zigbee signal) to the lightbulb.Result: Near-zero latency, absolute privacy, and it works perfectly even if your fiber optic cable is accidentally severed by a backhoe down the street. Step-by-Step: Deploying Home Assistant via Docker For tech enthusiasts, running Home Assistant via Docker on a local Linux server (like Ubuntu or Debian) offers the ultimate flexibility. Here is a quick case study on how to deploy it using docker-compose. Prerequisites: A machine running Linux with Docker and Docker Compose installed.Create the configuration directory: mkdir -p /opt/homeassistant/config cd /opt/homeassistantCreate the docker-compose.yml file: Using your favorite text editor (like nano or vim), create the following configuration: version: '3' services: homeassistant: container_name: homeassistant image: "ghcr.io/home-assistant/home-assistant:stable" volumes: - /opt/homeassistant/config:/config - /etc/localtime:/etc/localtime:ro - /run/dbus:/run/dbus:ro restart: unless-stopped privileged: true network_mode: hostDeploy the stack: docker-compose up -dWithin seconds, Home Assistant will boot up locally. You can access the interface by navigating to http://<YOUR_SERVER_IP>:8123 in your web browser. No cloud accounts, no forced updates, no data harvesting. Just you and your hardware. Matter and Thread: The Great Equalizer of 2026 We cannot discuss smart homes in 2026 without addressing the Matter protocol. Matter was supposed to be the "one ring to rule them all," allowing Apple, Google, Amazon, and SmartThings ecosystems to play nicely together over the local network using IPv6 and Thread (a low-power mesh networking technology). While Google Home has adopted Matter, it still uses it primarily to bridge devices into its cloud ecosystem for advanced automation and voice processing. Home Assistant, however, leverages Matter and Thread to their absolute fullest potential: pure, unadulterated local control. By plugging a SkyConnect USB dongle into your Home Assistant server, you can pair Matter-over-Thread devices completely offline. If a company goes bankrupt tomorrow and shuts down its servers, your Matter devices connected to Home Assistant will not care. They will continue to function flawlessly. This concept, known as "Future-Proofing," is a massive driving force behind the adoption of open-source automation.Advanced Automation: YAML vs. Google Routines Google Home's automation interface is designed for the masses. It is incredibly user-friendly but severely limited. You can create routines like "If it's 8:00 AM, turn on the coffee maker," but complex conditional logic is difficult or impossible. Home Assistant caters to developers and power users. You can write automations in the UI, or drop into YAML configuration for infinite possibilities. Case Study: The "Movie Time" Automation Let's say you want an automation that does the following: When I start playing a movie on Plex, IF the sun has set, dim the living room lights to 20%, turn off the kitchen lights, and lower the smart blinds. In Google Home, this is a nightmare to configure reliably. In Home Assistant, it's a beautifully simple YAML block: alias: "Cinema Mode: Plex Started" description: "Dim lights when a movie starts, only at night." trigger: - platform: state entity_id: media_player.living_room_plex to: "playing" condition: - condition: state entity_id: sun.sun state: "below_horizon" action: - service: light.turn_on target: entity_id: light.living_room_hue data: brightness_pct: 20 transition: 3 - service: light.turn_off target: entity_id: light.kitchen_main - service: cover.close_cover target: entity_id: cover.living_room_blinds mode: singleThis level of granular control is why developers and tech professionals are abandoning restricted ecosystems. Home Assistant allows you to integrate APIs from your Tesla, your solar inverter, your router's bandwidth monitor, and your weather station, combining them into unified, highly complex logic engines. The Security Audit: Why Local Hubs Win From a cybersecurity perspective, exposing every light switch to the public internet is a massive attack surface. Botnets like Mirai historically targeted cheap IoT devices with hardcoded cloud credentials. By utilizing a local hub like Home Assistant, you can implement a "VLAN (Virtual Local Area Network) Quarantine" strategy. Step-by-Step: Securing IoT DevicesCreate an IoT VLAN on your router (e.g., Unifi, pfSense, or Mikrotik). Connect all your Wi-Fi smart devices (cameras, vacuums, plugs) to this specific VLAN. Set Firewall Rules: Block the IoT VLAN from accessing the WAN (Internet) completely. Allow your Home Assistant server (which sits on a trusted management VLAN) to establish one-way communication into the IoT VLAN to send commands.By doing this, your cheap smart plugs cannot "phome home" to servers in foreign countries, nor can they be compromised remotely from the internet. They are completely isolated, yet fully functional through your local Home Assistant instance. Google Home simply cannot facilitate this level of enterprise-grade network security because it requires those devices to have WAN access to function. #NetworkSecurity #IoT Conclusion: Taking Back Your Home Google Home and Alexa still have their place. They are excellent, cheap voice interfaces. In fact, many power users integrate Google Assistant into Home Assistant purely for voice recognition, while keeping the actual logic and execution entirely local. However, as we move deeper into 2026, the sentiment is clear: Your home is your most private sanctuary. Relying on cloud servers to turn on your bedroom lights is an unnecessary surrender of data and reliability. By investing the time to set up an open-source, local-first system like Home Assistant, you are not just building a smarter house; you are reclaiming your digital sovereignty. You are ensuring that your routines, your data, and your hardware belong exclusively to you. And in the modern tech landscape, that level of control is priceless.Want to learn more about securing your local network or setting up Edge AI hubs? Let me know in the comments below, and don't forget to share this guide with your fellow DIY enthusiasts! Related InsightsThe Convergence of Quantum Entropy and Native Multimodal Architectures: A New Frontier in Information Processing Soulbound Tokens (SBTs): The Web3 Identity Revolution That Will Rewrite Trust and Reputation Silicon Beyond the Stratosphere: Architecting Autonomous Intelligence for Deep Space Exploration{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Home Assistant vs. Google Home in 2026: Why Local Control Wins for Privacy?", "acceptedAnswer": { "@type": "Answer", "text": "A deep dive into why local control with Home Assistant is replacing cloud-based ecosystems like Google Home for privacy-conscious smart home enthusiasts." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Home Assistant vs. Google Home in 2026: Why Local Control Wins for Privacy?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Lukas Richter." } }, { "@type": "Question", "name": "Where can I find more related content about Technology?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Technology category page." } } ] }
-
 Giovanni Luigi
- 11 Jul, 2026 20:01
Il Respiro Antico del Mare Nostrum: La Dieta Mediterranea tra Scienza, Storia e Armonia del Vivere
Dalle sponde baciate dal sole dove il tempo sembra rallentare, dove l'ulivo millenario affonda le sue radici nella terra fertile e il profumo del rosmarino si mescola alla brezza marina, emerge un patrimonio inestimabile: non solo un modo di nutrirsi, ma una filosofia di vita, una sinfonia di sapori e tradizioni che risuona attraverso i secoli. Parliamo della Dieta Mediterranea, un concetto che trascende la semplice alimentazione per abbracciare un'intera esistenza, fatta di convivialità, movimento e rispetto per la natura. È un invito a riscoprire l'essenza della buona tavola, un rituale quotidiano che celebra la salute e la gioia di vivere. Fu nel lontano 1975 che la curiosità intellettuale di due menti brillanti, il biologo americano Ancel Keys e la chimica Margaret Keys, disvelò al mondo questo modello alimentare. La loro meticolosa osservazione si concentrò sulle abitudini e sui cibi tradizionali delle popolazioni che abitavano le coste mediterranee tra la fine degli anni '50 e l'inizio degli anni '60: la Grecia, l'Italia, le riviere di Francia e Spagna, e persino le terre del Levante. Non si trattava di delineare una singola cucina, poiché le tradizioni culinarie di questi paesi sono tanto variegate quanto le loro genti, bensì di identificare un modello dietetico comune, distinto sia dalla ricca e diversificata "cucina mediterranea" intesa in senso ampio, sia dalla "dieta atlantica" dell'Europa nord-occidentale, pur con qualche punto di contatto. Da quella prima intuizione, la Dieta Mediterranea si è affermata come il regime alimentare più studiato e riconosciuto a livello globale, un faro nella ricerca scientifica sulla nutrizione. I Pilastri del Gusto e del Benessere: Cosa Definisce la Dieta Mediterranea Sebbene radicata in un tempo e in un luogo specifici, l'espressione "Dieta Mediterranea" oggi descrive un modello alimentare che è stato via via raffinato e validato dai risultati di innumerevoli studi scientifici. Al suo cuore pulsa un'enfasi inequivocabile sui cibi di origine vegetale, autentici doni della terra. Cereali integrali non processati, legumi robusti, verdure fresche e croccanti, e una profusione di frutta succosa costituiscono la base piramidale di questa alimentazione. A questi si affianca un consumo moderato di pesce, prezioso per i suoi nutrienti, e di prodotti lattiero-caseari, prevalentemente formaggi e yogurt, che conferiscono sapidità e cremosità. La carne rossa, i cereali raffinati e gli zuccheri sono invece relegati a un ruolo marginale, consumati con parsimonia. Un capitolo a parte merita il consumo di alcol, limitato principalmente al vino, in particolare quello rosso, assunto in quantità basse o moderate e, quasi sempre, durante i pasti. Questa consuetudine, profondamente radicata nella cultura mediterranea, è parte di un equilibrio che non ricerca l'eccesso ma il piacere misurato. Il vero protagonista, tuttavia, l'oro liquido che lega ogni elemento e conferisce sapore e salute, è l'olio d'oliva. È la fonte principale di grassi in questo regime alimentare e, non a caso, è stato oggetto di vastissima ricerca scientifica per il suo potenziale di ridurre la mortalità per tutte le cause e il rischio di malattie croniche. L'olio d'oliva non è solo un condimento; è un ingrediente fondamentale, un veicolo di benessere che racchiude in sé l'anima stessa del Mediterraneo.L'Eco della Salute: Evidenze Scientifiche e Riconoscimenti Mondiali La risonanza scientifica della Dieta Mediterranea è straordinaria. Studi osservazionali hanno costantemente associato la sua adozione a una riduzione significativa della mortalità per tutte le cause. Una revisione sistematica del 2017 ha fornito prove robuste che questo modello dietetico diminuisce il rischio di malattie cardiache e di morte prematura, suggerendo altresì un potenziale aiuto nella gestione del peso per gli individui obesi. La sua efficacia e sicurezza sono tali che le "Linee Guida Dietetiche per gli Americani 2015-2020" l'hanno inclusa tra le tre diete sane raccomandate, al fianco della dieta DASH e della dieta vegetariana. Anche l'Organizzazione Mondiale della Sanità (OMS) la riconosce universalmente come un modello alimentare salutare. Ma l'impatto della Dieta Mediterranea va oltre il mero aspetto nutrizionale. Nel 2010, l'UNESCO, consapevole della sua profondità culturale, l'ha riconosciuta come Patrimonio Culturale Immateriale dell'Umanità, non solo per i cibi, ma per l'insieme delle tradizioni e delle pratiche ad essa associate. Questo riconoscimento ne sottolinea la natura olistica. La Dieta Mediterranea, infatti, si estende talvolta a includere abitudini di vita specifiche, comportamenti sociali e valori culturali strettamente legati ai paesi mediterranei: metodi di cottura semplici ma vari, pasti comunitari che rafforzano i legami sociali, le immancabili sieste post-pranzo e una regolare attività fisica, spesso integrata nella quotidianità. È un mosaico di pratiche che insieme contribuiscono a un'esistenza più equilibrata e appagante. Gli Effetti Benefici sulla Salute: Un Approfondimento Scientifico L'interesse della comunità scientifica per la Dieta Mediterranea non accenna a diminuire, e le ricerche continuano a svelarne le molteplici virtù. Ricerca Alimentare e il Ruolo dell'Olio d'Oliva Una delle caratteristiche distintive della Dieta Mediterranea è il suo basso contenuto di grassi saturi, bilanciato da elevate quantità di grassi monoinsaturi e fibre alimentari. Il potenziale salutistico dell'olio d'oliva è un fattore chiave in questo equilibrio. L'olio d'oliva è ricco di grassi monoinsaturi, in particolare acido oleico, oggetto di continue ricerche cliniche per i suoi benefici. L'Autorità Europea per la Sicurezza Alimentare (EFSA), tramite il suo Panel sui Prodotti Dietetici, Nutrizione e Allergie, ha approvato dichiarazioni sulla salute riguardanti l'olio d'oliva, riconoscendone la capacità dei polifenoli di proteggere i lipidi ematici dall'ossidazione e il contributo dell'acido oleico al mantenimento di normali livelli di colesterolo LDL nel sangue, quando sostituisce i grassi saturi nella dieta (Regolamento (UE) 432/2012 della Commissione del 16 maggio 2012). Una meta-analisi del 2014 ha concluso che un consumo elevato di olio d'oliva è associato a un rischio ridotto di mortalità per tutte le cause, eventi cardiovascolari e ictus. Questo contrasta con i grassi monoinsaturi di origine mista animale e vegetale, che non hanno mostrato effetti significativi. Le linee guida nazionali degli Stati Uniti 2015-2020 hanno persino elaborato un "Modello Alimentare Sano di Stile Mediterraneo" basato su questi schemi e sui loro esiti positivi per la salute, raccomandando più frutta e frutti di mare e meno latticini rispetto al modello alimentare statunitense tradizionale. Una revisione del 2020 sulla Dieta Mediterranea ha ulteriormente indicato la sua capacità di ottimizzare la salute cardiovascolare. Salute Generale e Riduzione del Rischio di Malattie L'ampiezza dei benefici della Dieta Mediterranea è sorprendente. Una revisione del 2017 ha rilevato prove che la sua adozione può portare a una riduzione del rischio di malattie cardiovascolari, dell'incidenza complessiva di cancro, di malattie neurodegenerative, di diabete e di morte prematura. Un'altra revisione del 2018 ha mostrato che la pratica della Dieta Mediterranea può migliorare lo stato di salute generale, come la riduzione del rischio di malattie non infettive, e può persino contribuire a ridurre i costi totali della vita e quelli per l'assistenza sanitaria nazionale. Sebbene una revisione del 2016 abbia riscontrato una perdita di peso simile a quella di altre diete, i benefici vanno chiaramente ben oltre la sola bilancia. La Salute Cardiovascolare: Un Percorso di Ricerca La Dieta Mediterranea è annoverata tra i modelli alimentari che possono ridurre il rischio di malattie cardiovascolari. Una revisione Cochrane del 2013 ha trovato prove limitate che una Dieta Mediterranea influisca favorevolmente sui fattori di rischio cardiovascolare. Tuttavia, una meta-analisi dello stesso anno, confrontando diverse diete (Mediterranea, vegana, vegetariana, a basso indice glicemico, a basso contenuto di carboidrati, ricca di fibre e ad alto contenuto proteico), ha concluso che la Dieta Mediterranea, insieme alle diete a basso contenuto di carboidrati, a basso indice glicemico e ad alto contenuto proteico, è efficace nel migliorare i marcatori di rischio per malattie cardiovascolari e diabete. Nel 2016, la Dieta Mediterranea è stata raccomandata come mezzo per abbassare l'apolipoproteina B, un indicatore chiave. Anche l'American Heart Association, nel 2016, l'ha discussa come un modello alimentare sano in grado di ridurre il rischio di malattie cardiovascolari. È interessante notare come la scienza progredisca attraverso il dibattito. Verso il 2016, sono emerse revisioni più caute, sollevando preoccupazioni sulla qualità delle precedenti revisioni sistematiche che esaminavano l'impatto della Dieta Mediterranea sui fattori di rischio cardiovascolare. Queste revisioni hanno sottolineato la necessità di ulteriori ricerche standardizzate, con una meta-analisi che concludeva che la quantità e la qualità delle prove disponibili erano altamente variabili, mettendo in guardia sui limiti nella certezza degli esiti clinici possibili dal consumo di una Dieta Mediterranea. Nonostante ciò, altre revisioni nel 2016-2017 hanno raggiunto ulteriori conclusioni sulla capacità di una Dieta Mediterranea di migliorare i fattori di rischio cardiovascolare, come la riduzione del rischio di ipertensione e altre malattie cardiovascolari.Recenti Scoperte sulla Salute Cardiovascolare (dal 2019) Il dibattito scientifico continua ad evolvere. Una revisione Cochrane del 2019 ha rilevato che esiste incertezza circa gli effetti di una dieta in stile mediterraneo sull'incidenza di malattie cardiovascolari e sui fattori di rischio in persone con o senza malattie cardiovascolari esistenti. La revisione ha inoltre discusso che la ricerca sulla dieta ha fornito prove solo per benefici modesti contro i fattori di rischio cardiovascolare, con una qualità della ricerca da bassa a moderata. Questo sottolinea la complessità della ricerca nutrizionale e la necessità di studi a lungo termine e di alta qualità. Tuttavia, le ricerche più recenti continuano a rinforzare il quadro generale positivo. Una revisione del 2023 ha fornito prove per una riduzione della mortalità e del rischio di malattie cardiovascolari nelle donne che seguono una dieta di tipo mediterraneo. Ancora più recentemente, una meta-analisi del 2024 ha riscontrato che l'aderenza al consumo di questi alimenti è associata a una riduzione del rischio di malattie cardiovascolari. Questo continuo flusso di studi, pur con le sfumature e le cautele necessarie, consolida l'immagine della Dieta Mediterranea come un alleato prezioso per il cuore. L'Impatto sul Diabete Anche per quanto riguarda il diabete, i dati sono promettenti. Nel 2014, due meta-analisi hanno rilevato che la Dieta Mediterranea era associata a una diminuzione del rischio di diabete di tipo 2, risultati simili a quelli di una revisione del 2017. L'American Diabetes Association e una revisione del 2019 hanno indicato che la Dieta Mediterranea è un modello alimentare raccomandato per la prevenzione e la gestione di questa malattia sempre più diffusa. L'enfasi sui cereali integrali, sui legumi e sulle verdure, con un basso apporto di zuccheri raffinati, contribuisce a un migliore controllo glicemico e a una maggiore sensibilità all'insulina. Un Patrimonio da Custodire La Dieta Mediterranea è molto più di un elenco di alimenti da consumare. È un'eredità culturale profonda, un simbolo di una connessione intrinseca tra l'uomo, la terra e il mare. È una celebrazione della semplicità, della freschezza e del sapore autentico. In un'epoca in cui le mode alimentari si susseguono freneticamente, la Dieta Mediterranea rimane un baluardo di saggezza, una via maestra verso la salute e il benessere duraturi. I suoi principi, validati dalla scienza e consacrati dalla storia, ci invitano a rallentare, a gustare, a condividere e, in definitiva, a vivere meglio, abbracciando il respiro antico e vitale del Mare Nostrum.#DietaMediterranea #SaluteEBenessere #CucinaItaliana #UNESCOHeritage #OlioDiva Related InsightsThe Wild Yeast Revolution: Beyond the Loaf into the World of Fermented Alchemy Portuguese Pastéis de Nata: The Custard Tart's Sweet History The Bitter Revolution: How Chicory, Radicchio, and Dandelion Are Redefining Modern Menus{ "@context": "https://schema.org", "@type": "FAQPage", "mainEntity": [ { "@type": "Question", "name": "What is the main focus of Il Respiro Antico del Mare Nostrum: La Dieta Mediterranea tra Scienza, Storia e Armonia del Vivere?", "acceptedAnswer": { "@type": "Answer", "text": "Un'esplorazione profonda della Dieta Mediterranea, dall'intuizione dei coniugi Keys alle moderne evidenze scientifiche, svelando il segreto di longevità e benessere radicato nel cuore del Mare Nostrum." } }, { "@type": "Question", "name": "Who authored the comprehensive guide on Il Respiro Antico del Mare Nostrum: La Dieta Mediterranea tra Scienza, Storia e Armonia del Vivere?", "acceptedAnswer": { "@type": "Answer", "text": "This detailed article and its insights were carefully researched and authored by Giovanni Luigi." } }, { "@type": "Question", "name": "Where can I find more related content about Food?", "acceptedAnswer": { "@type": "Answer", "text": "You can explore more articles, detailed reviews, and similar insights by browsing the Related Insights section at the bottom of this article or visiting our dedicated Food category page." } } ] }